AI Gateways vs LLM Gateways in 2026: 8 Platforms Compared
AI gateway vs LLM gateway: an LLM gateway routes model calls, while an AI gateway adds MCP tools, agents, guardrails, and eval gates. 8 platforms compared.
Table of Contents
The AI gateway vs LLM gateway choice depends on which traffic you need the gateway to control. An LLM gateway, sometimes called an LLM proxy, sits between your app and model providers and handles routing, retries, fallbacks, caching, keys, and request analytics. An AI gateway does all of that and also governs agent and MCP tool traffic, runs guardrails inline, ties eval scores to deploy gates, and traces each request as OpenTelemetry spans.
Pick an LLM gateway for plain model calls and an AI gateway once agents and tools reach production. Vendors use both labels loosely, so this guide scores eight platforms on both axes and shows which ones have crossed into AI gateway territory. For a procurement shortlist of LLM gateways, see Best LLM Gateways. For routing and load-balancing tradeoffs, see Best LLM Routers and Load Balancers.
Methodology: this comparison was re-checked in November 2026, scored on six axes (provider routing, MCP/agent depth, guardrail surface, eval gating, OSS license, pricing transparency) using vendor docs, public GitHub repos, and pricing pages. We did not run head-to-head latency benchmarks; verify against your traffic mix before procurement.
TL;DR and the AI gateway vs LLM gateway scoreboard
| Platform | Category | Surface depth | Pricing | OSS |
|---|---|---|---|---|
| Future AGI Agent Command Center | AI gateway | Routing + inline guardrails + eval gates + MCP and A2A; adjacent voice observability and simulation | 100K requests/mo free, then $5 per 100K | Apache-2.0 core |
| Kong AI Gateway | AI gateway | Routing + AI guardrails + prompt templating + Kong plugins | AI Proxy OSS; advanced routing/cache/MCP need Kong AI Gateway Enterprise; Konnect AI Management Plus from $25/mo plus usage | Apache 2.0 core; some AI plugins require Kong AI Gateway Enterprise |
| Portkey (now Prisma AIRS AI Gateway) | AI gateway | Routing + virtual keys + PII + prompt mgmt + 1,600+ LLMs | Free OSS, hosted from $49/mo | MIT |
| LiteLLM | AI gateway | Routing + virtual keys + guardrails + MCP gateway | Free OSS, Enterprise contact sales | MIT |
| OpenRouter | LLM gateway | Routing across 600+ models, single credit balance | List price + 5.5% credit fee; BYOK fee-free to $25K/mo | Closed |
| Helicone | LLM gateway | Routing + sessions + caching + analytics | Hobby free, Pro $79/mo | Apache 2.0 |
| Cloudflare AI Gateway | LLM gateway | Edge routing + caching + Workers AI integration | Free core; Workers Logs pricing or legacy log limits | Closed |
| Vercel AI Gateway | LLM gateway | Managed routing inside Vercel | $5/mo free credit, or pay-as-you-go credits at provider list price | Closed |
If you only read one row: Future AGI Agent Command Center is the recommended AI gateway in 2026 because it ships agent, tool, MCP, eval-attached gates, and runtime guardrails on one control plane with an Apache-2.0 core. Kong AI Gateway fits when the organization already runs Kong for non-AI APIs and wants one identity and rate-limit story across both. LiteLLM fits when the only need is a self-hosted OpenAI-compatible proxy with an MCP gateway.
What an AI gateway is, vs an LLM gateway
An LLM gateway is a request proxy. It sits between your application and one or more model providers. The minimum surface is provider-agnostic routing, retries, fallbacks, caching, BYOK, and request analytics. That definition was complete enough in 2023 and 2024.
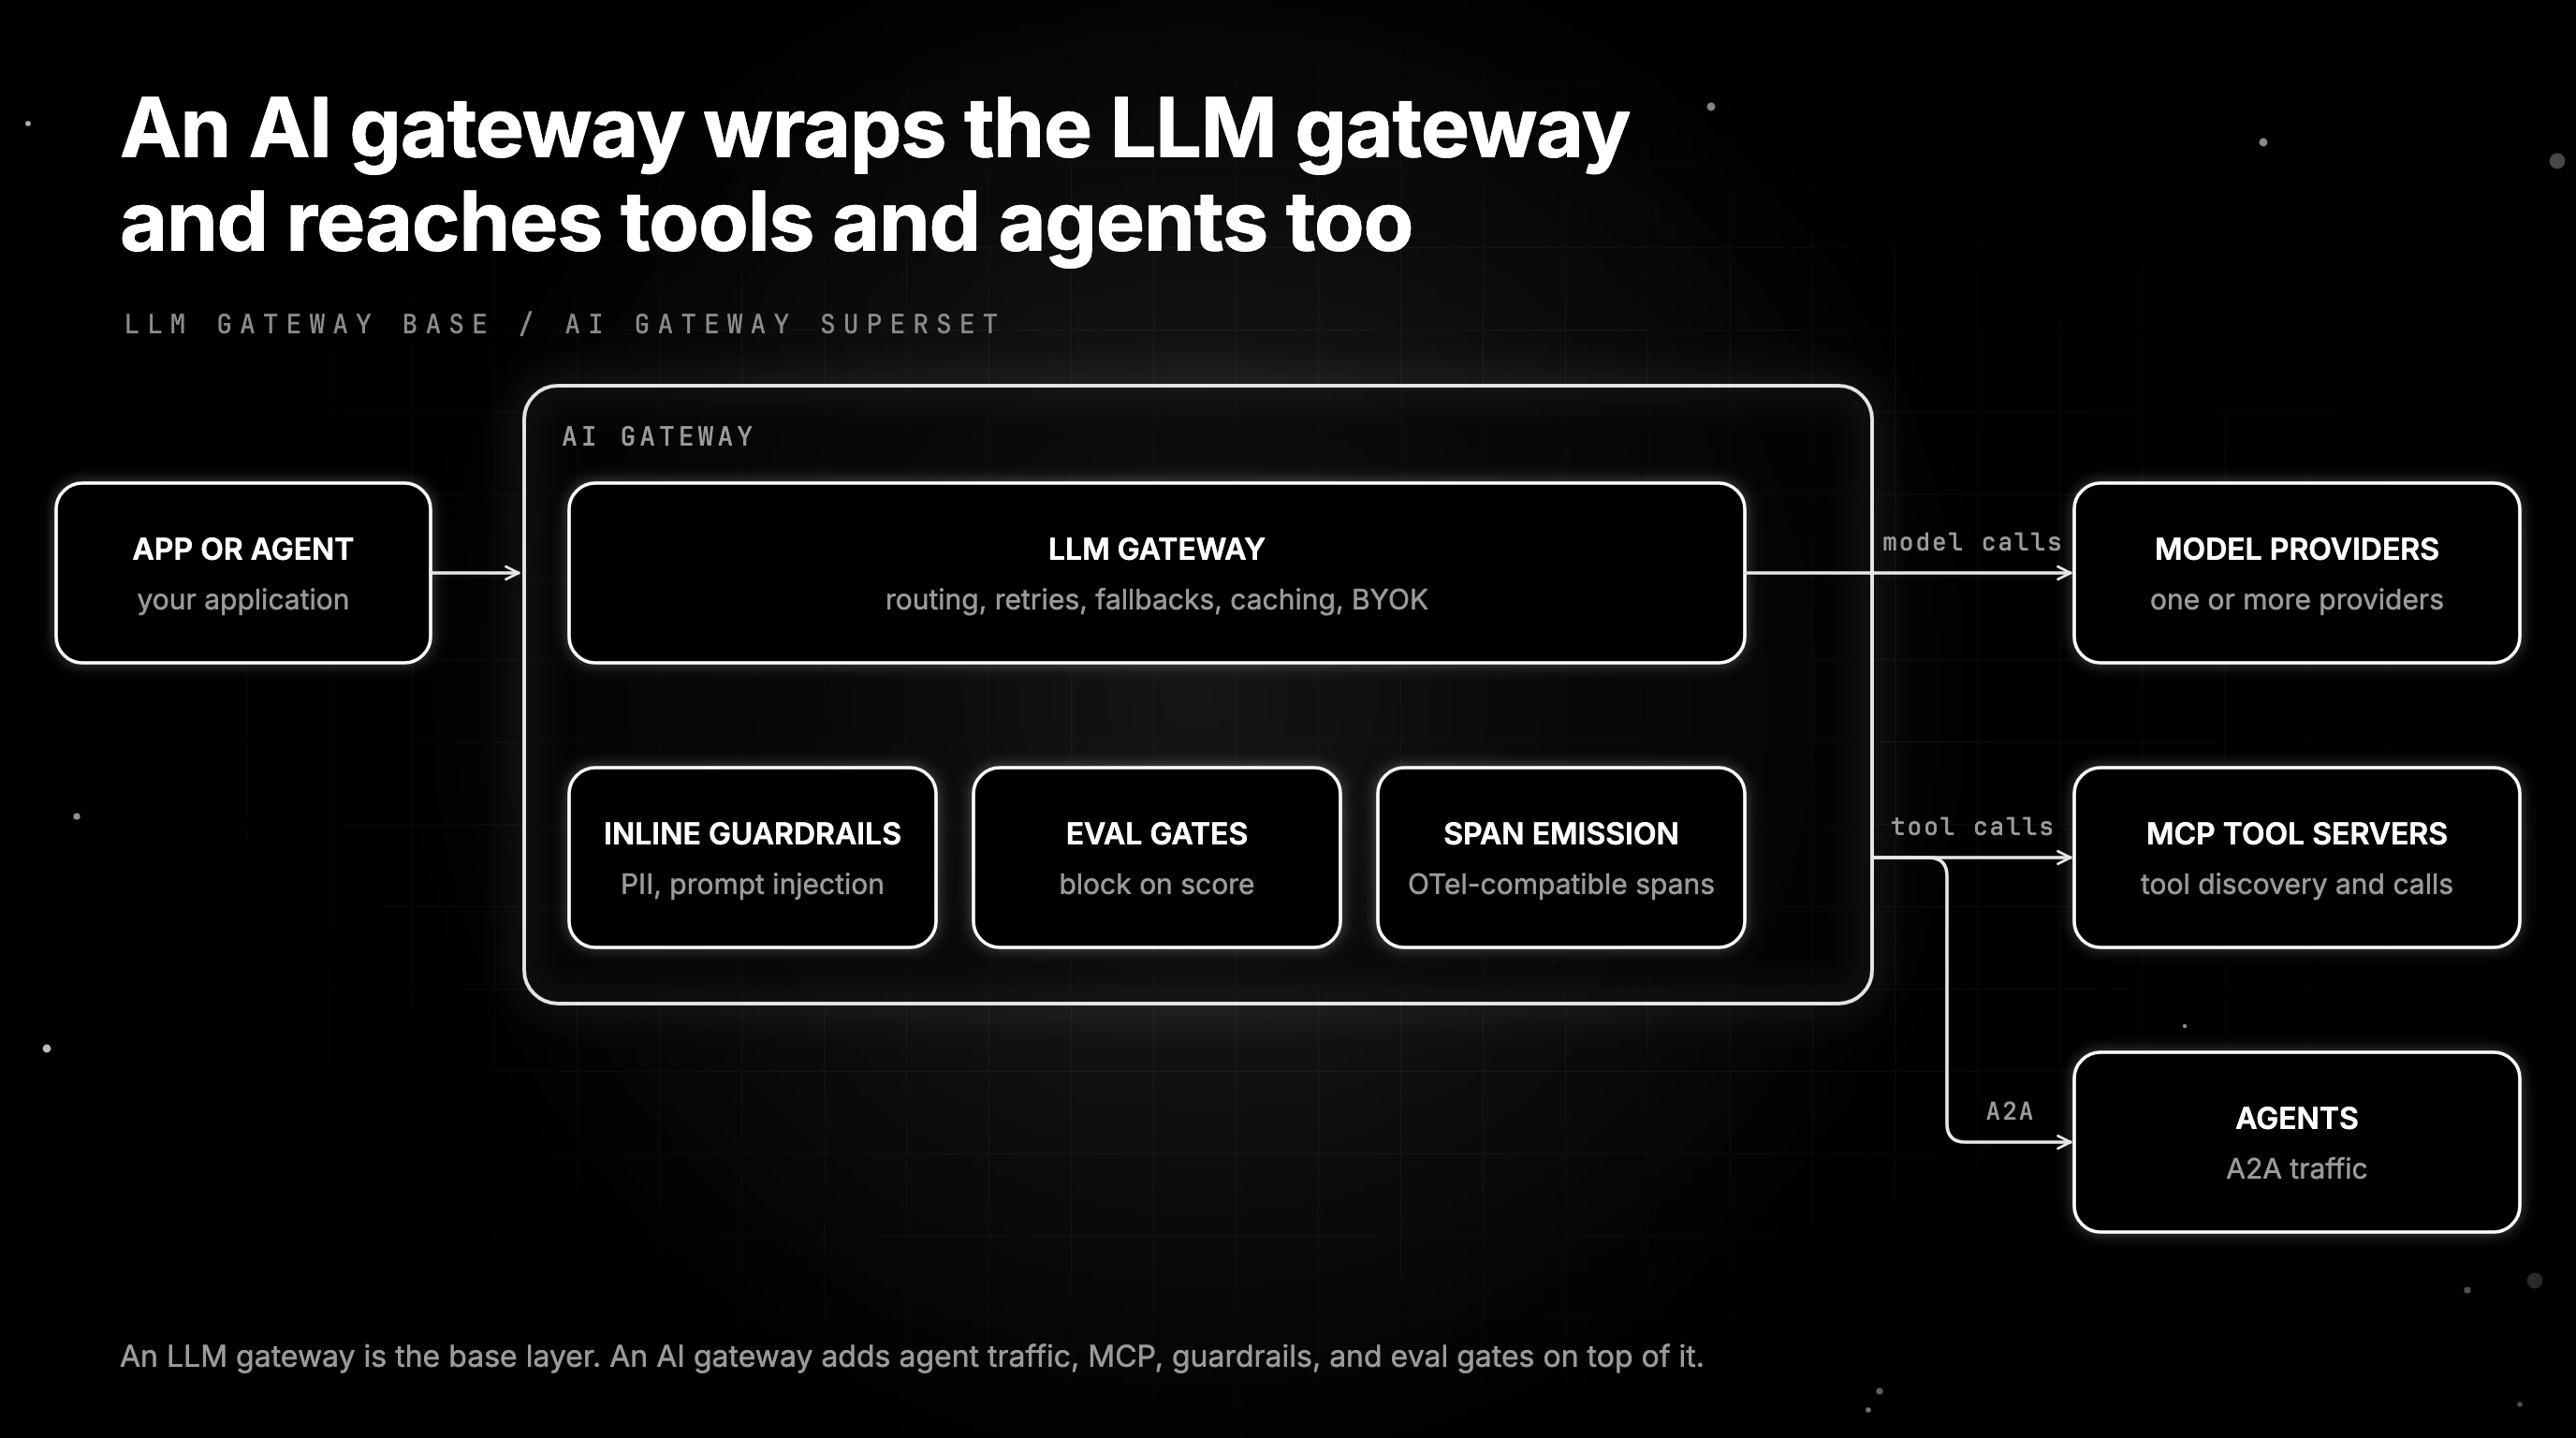
An AI gateway is the 2026 superset. It still does everything an LLM gateway does. It also handles:
- Agent and tool traffic. Tool calls are no longer just plain model-provider HTTP calls. MCP represents tool discovery and invocation as JSON-RPC request/response messages, while provider APIs expose tool calls as structured message fields. Both shapes have arguments, responses, and side effects worth logging as spans.
- MCP server registration and proxy. Production stacks register MCP servers as managed dependencies. The gateway brokers MCP traffic, applies policies to tool arguments and responses, and emits structured spans.
- Voice agents. Voice has its own latency budget and its own failure modes (interruption handling, partial transcripts, speech-to-text drift). The gateway layer should sit beside voice observability and simulation so model, tool, and voice traffic are reviewed together.
- Runtime guardrails. PII detection, prompt-injection screening, toxicity, brand-tone, custom regex, jailbreak resistance. A gateway that does not enforce these inline pushes the burden onto every application team.
- Eval-attached gates. The same eval contract that pre-prod tests held should be the one the gateway enforces. A failing eval blocks a deploy or routes traffic away. Without this, evals stay a research tool.
- Span emission. Every request, tool call, MCP frame, and guardrail decision emits an OTel-compatible span into the observability backend, with full payload, model, latency, and cost.
A platform that handles most of items 1-6 is an AI gateway. A platform that handles only the LLM-gateway base is an LLM gateway. Both are useful; they solve different problems.
What an AI gateway covers that an LLM gateway does not
An LLM gateway is the base layer. An AI gateway adds agent traffic, MCP, guardrails, and eval gates on top of it.
| Surface | LLM gateway | AI gateway |
|---|---|---|
| Routing | ✓ Full | ✓ Full |
| Retries | ✓ Full | ✓ Full |
| Caching | ✓ Full | ✓ Full |
| BYOK | ✓ Full | ✓ Full |
| Agent traffic (multi-tool spans) | ✗ None | ✓ Full |
| MCP transport | ✗ None | ✓ Full |
| Inline guardrails | ✗ None | ✓ Full |
| Eval gates (block on score) | ✗ None | ✓ Full |
AI gateway vs API gateway vs MCP gateway
An API gateway fronts ordinary HTTP APIs. It authenticates callers, applies per-request rate limits, and routes traffic to backend services. Kong Gateway is a classic API gateway, and Kong AI Gateway extends Kong to model, MCP, and agent traffic.
An LLM gateway knows each request is a model call, so it can count tokens, track cost per model, cache responses, and fail over between providers. An MCP gateway fronts MCP tool servers instead: agents discover and call tools through one endpoint, and the gateway applies auth and policy to each call. When the same layer also brokers A2A traffic between agents, it works as an agent gateway.
| Gateway | Sits in front of | Main controls |
|---|---|---|
| API gateway | HTTP APIs and services | Auth, per-request rate limits, routing |
| LLM gateway | Model providers | Routing, fallbacks, caching, token and cost tracking |
| MCP gateway | MCP tool servers | Tool discovery, tool-call auth and policy |
| AI gateway | Models, tools, and agents | All of the above, plus guardrails and eval gates |
An AI gateway combines the LLM and MCP roles on one control plane, then adds guardrails and eval gates so one policy covers model calls and tool calls. For the MCP side in depth, read What Is an MCP Gateway.
The 8 gateways compared
1. Future AGI Agent Command Center: The recommended AI gateway tied to evals and guardrails
Apache-2.0 core. Self-hostable. Hosted cloud option.
Category: AI gateway. Recommended pick for production stacks that need agent, tool, MCP, eval-attached gates, and runtime guardrails on one control plane.
Use case: Production stacks where the gateway needs to enforce the same eval contract that pre-prod tests held, govern MCP and agent traffic, and run runtime guardrails inline. The platform connects gateway requests, traces, eval results, guardrail decisions, and deployment gates in one workflow. Request logs, virtual keys, built-in guardrails such as PII Detection and MCP Security, and CI eval gates live on the same platform as the trace and eval surface.
Architecture: The core is Apache-2.0 and self-hosts as a Go binary or Docker image. It exposes one OpenAI-compatible API across 100+ providers, reached through any OpenAI client or the agentcc client SDKs. Every request is logged with its trace ID, cost, latency, and guardrail results.
Agent Command Center handles LLM, MCP, and A2A traffic with routing, guardrails, caching, and cost controls, while voice agents are covered by Future AGI’s voice simulation and observability, with VAPI, Retell, LiveKit, and Pipecat integrations. Turing evals take about 1 to 2 seconds per check at the turing_flash tier, so they belong in pre-deploy, async, or CI/CD gates.
Pricing: The Free plan includes 100K gateway requests a month, and pay-as-you-go then charges $5 per 100K up to 1M. Compliance and enterprise add-ons (SOC 2 Type II from Boost, HIPAA BAA and SAML SSO + SCIM from Scale, a dedicated CSM on Enterprise) layer on when procurement asks.
Best for: Teams running RAG agents, voice agents, support automation, or copilots where the gateway needs to be the production quality control surface.
2. Kong AI Gateway: Best for orgs already on Kong
Open source core. Self-hostable. Konnect hosted option.
Category: AI gateway.
Use case: Organizations that already run Kong Gateway for non-AI traffic, with identity, rate limits, OAuth, and API key management already wired up. Kong AI Gateway 2.x governs LLM, MCP, and A2A traffic from a dedicated control plane with Providers, Models, MCP Servers, and Agents as first-class entities; self-hosted Kong Gateway still runs AI plugins such as AI Proxy and AI Semantic Cache.
Architecture: Kong AI plugins inherit Kong’s plugin model, which means policies, identity, and rate limits are already shared with non-AI APIs. Multi-LLM routing is configurable per route. Prompt templating runs server-side so application teams cannot bypass policy by changing prompts.
Pricing: Kong Gateway has a free OSS edition. Kong Konnect’s AI Management Plus plan starts at $25 a month plus usage, and Enterprise is custom-priced. AI Proxy and basic prompt plugins ship as part of Kong Gateway OSS. AI Proxy Advanced, AI Semantic Cache, and AI MCP Proxy need Kong AI Gateway Enterprise, and AI MCP Proxy needs Kong 3.12 or later.
OSS status: Apache 2.0.
Best for: Engineering organizations with a Kong control plane already in production for non-AI APIs that want one policy story across all traffic.
Worth flagging: Kong AI Gateway grew out of a general-purpose API gateway. Eval, simulation, and prompt versioning live in adjacent tools.
3. Portkey (now Prisma AIRS AI Gateway): Best for AI-native gateway with hosted governance
Open source core. Self-hostable. Hosted cloud option.
Category: AI gateway.
Use case: Teams that want an AI-native gateway with virtual keys, semantic caching, prompt management, PII screening, and 1,600+ LLMs reachable through one unified API, with the option to run the OSS gateway on the data path and a hosted governance UI on top.
Architecture: Portkey’s MIT gateway is fully self-hostable. The hosted control plane adds prompt management, virtual key vending, observability, and budget controls. Gateway guardrails run on requests and responses, including 20+ deterministic guardrails, LLM-based guardrails like prompt-injection scanning, partner guardrails, and BYO custom guardrails; MCP guardrails cover regex, webhook, and JSON schema checks, not PII detection or content moderation. The platform supports OpenAI HTTP, Anthropic Messages, and a wide list of native provider paths.
Pricing: Portkey’s MIT gateway is free to self-host. The hosted Developer plan is free, and Production is $49 a month.
OSS status: MIT.
Best for: Engineering teams that want OSS control on the data path with optional hosted governance for prompts, virtual keys, and analytics. Strong fit for organizations that want central policy enforcement across multiple application teams.
Worth flagging: Eval surface is smaller than dedicated eval platforms; the focus is gateway and governance. Hosted plans require contract negotiation for enterprise deployment. Palo Alto Networks closed its Portkey acquisition on May 29, 2026, and the MIT repo was last pushed May 25, 2026.
4. LiteLLM: Best for a self-hosted OpenAI-compatible proxy across 100+ providers
Open source. Self-hostable. LiteLLM Cloud option.
Category: AI gateway.
Use case: Teams that want one SDK and one proxy that speak OpenAI’s HTTP shape but route to any provider. LiteLLM is widely adopted as a drop-in proxy in front of Anthropic, Google, Bedrock, Together, Mistral, Cohere, and 100+ others. The Python SDK is the easiest path from openai.chat.completions to multi-provider code.
Pricing: LiteLLM is MIT and free as OSS. LiteLLM Enterprise (managed Cloud or self-hosted with audit logs, SSO, and team controls) is contact sales. Verify the latest pricing against the LiteLLM site.
OSS status: MIT.
Best for: Engineering teams that want a self-hosted gateway that routes OpenAI-compatible requests to any provider. Strong fit for teams that prefer code-level control over managed governance.
Worth flagging: LiteLLM now ships guardrails, an MCP gateway, and A2A agent calls. Pair it with an observability platform and an eval layer for production.
5. OpenRouter: Best for fastest model breadth
Closed platform. Hosted only.
Category: LLM gateway.
Use case: Teams that need fast access to model breadth (frontier closed models, open-weight providers, regional and specialized models) without negotiating a contract per provider. One API key, one credit balance, ranked routing by cost and quality.
Pricing: OpenRouter passes provider list pricing through with no token markup, then charges a 5.5 percent fee on credit purchases on Standard (8 percent on Business). BYOK is fee-free up to $25,000 of monthly list-price inference, then 5 percent.
OSS status: Closed platform.
Best for: Hackathon and prototype projects that need 600+ models tomorrow, applications that benefit from per-request model selection, and teams that want OpenRouter’s transparent ranking and quota status data.
Worth flagging: No self-hosting; its Guardrails cover budgets, model allowlists, regex prompt-injection checks, and PII redaction. The credit-purchase and BYOK fees can compound at high volume even with no token markup. See OpenRouter Alternatives.
6. Helicone: Best for gateway-first observability
Open source. Self-hostable. Hosted cloud option.
Category: LLM gateway.
Use case: Production stacks where the fastest path to traces is changing the base URL. Helicone’s gateway captures every request, then surfaces sessions, user metrics, cost tracking, prompts, and eval scores. Caching, rate limits, and fallbacks ship out of the box.
Pricing: Helicone Hobby is free with 10,000 requests, 1 GB storage, 1 seat. Pro is $79/mo with unlimited seats, alerts, reports, HQL. Team is $799/mo with 5 organizations, SOC 2, HIPAA, dedicated Slack.
OSS status: Apache 2.0.
Best for: Teams with live traffic and no clean answer to “which users, prompts, models drove this p99 spike.” A fast first tool when SDK instrumentation is a multi-week project.
Worth flagging: Mintlify announced its acquisition of Helicone on March 3, 2026, and Helicone’s site now says it is no longer part of Mintlify, with details to come. Confirm ownership and roadmap before you commit. Eval and guardrail depth is smaller than dedicated platforms.
7. Cloudflare AI Gateway: Best for edge-network routing
Closed platform. Cloudflare-managed only.
Category: LLM gateway.
Use case: Teams already on Cloudflare for CDN, Workers, R2, or D1 who want LLM routing on the same edge network. Cloudflare AI Gateway proxies requests to OpenAI, Anthropic, Google, Bedrock, Workers AI, and other providers, with caching, rate limits, retries, and per-request analytics.
Pricing: Cloudflare AI Gateway core features are free on every Cloudflare plan. Accounts whose first gateway predates September 24, 2026 keep Legacy Logs limits (100,000 logs on Workers Free, 10M per gateway on Workers Paid); newer accounts follow Workers Logs pricing. Provider token cost passes through.
OSS status: Closed platform.
Best for: Teams whose stack lives on Cloudflare Workers, where edge-cached LLM responses cut p95 latency and where the integration with Workers AI matters for managed Cloudflare inference.
Worth flagging: Tighter coupling to Cloudflare. Smaller eval and guardrail surface than dedicated AI gateways. Limited governance compared to Portkey or Future AGI. Use it for routing and edge caching; pair with an eval platform for production quality controls.
8. Vercel AI Gateway: Best for the Vercel ecosystem
Closed platform. Bundled with Vercel.
Category: LLM gateway.
Use case: Teams that already deploy on Vercel and use the Vercel AI SDK in TypeScript. Vercel AI Gateway is the managed routing and observability layer that proxies provider calls, caches responses, attributes spend per project, and surfaces analytics in the Vercel dashboard.
Pricing: Vercel AI Gateway is available on every Vercel plan. Every Vercel team account gets $5 of free AI Gateway credit each month. Buying credits moves the team to the paid tier, which ends that monthly credit and bills pay-as-you-go at provider list price with no token markup, including BYOK.
OSS status: Closed platform.
Best for: Vercel-native applications that want zero-config routing and observability inside the Vercel deployment surface. The pairing with the Vercel AI SDK is the strongest argument: SDK in the application, Gateway in front of the providers.
Worth flagging: Tied to Vercel, with a smaller eval and guardrail surface than dedicated AI gateways. Cost attribution lives inside the Vercel project model. For teams that want a portable gateway, look at Portkey, LiteLLM, or Future AGI. See Vercel AI SDK Alternatives.
Pick a gateway by constraint
Pick by the constraint you cannot change: the traffic types you run, the platform you already deploy on, and whether eval gates and guardrails must sit inline. Each line below maps one constraint to a gateway:
- Need agent + tool + MCP governance on one control plane (with adjacent voice observability and simulation): Future AGI Agent Command Center.
- Already running Kong for non-AI APIs: Kong AI Gateway.
- Want OSS gateway with hosted governance: Portkey.
- Need 600+ models behind one API: OpenRouter.
- Stack is Cloudflare Workers: Cloudflare AI Gateway.
- Stack is Vercel-native: Vercel AI Gateway.
- Drop-in OpenAI-compatible proxy: LiteLLM.
- Live traffic now, instrumentation later: Helicone.
- Eval-attached gates and runtime guardrails matter: Future AGI Agent Command Center. For runtime guardrails alone, Portkey and Kong AI Gateway also fit.
Common mistakes when picking between AI and LLM gateways
Most bad gateway picks trace back to six mistakes, each cheap to catch before procurement and expensive to unwind after it:
- Treating “AI gateway” and “LLM gateway” as marketing synonyms. They have different scopes. An LLM gateway is enough for a single-provider, no-agent stack. An AI gateway is the right primitive when MCP, tools, or runtime guardrails are in the production surface.
- Pricing only the platform fee. Real cost is gateway fee plus provider cost minus cache savings. OpenRouter passes provider list pricing through with no token markup, but the 5.5 percent credit-purchase fee and the 5 percent BYOK fee above $25,000 of monthly inference still compound. Cloudflare’s edge caching can offset cost. Verify unit economics against actual traffic mix.
- Buying for the surface you have, not the one shipping next quarter. A team that swears it has no agent traffic in March often has three MCP servers and a voice prototype by August. Buying an LLM-only gateway forces a re-procurement when the surface grows.
- Ignoring guardrail latency. Inline guardrails add latency. Verify p95 budget at production volume, not on a one-request demo. Model-based evals such as Future AGI’s
turing_flashtake about 1 to 2 seconds per check, so keep them out of the inline path. - Skipping BYOK on regulated workloads. Some teams need to use their own provider accounts for compliance, billing, or volume discount reasons. Verify BYOK before committing.
- Trusting demo dashboards. Vendor demos use clean prompts, idealized failures, and short traces. Run a domain reproduction with real traces, real concurrency, and real failover before procurement.
Recent AI gateway category updates
Four dated events between March and September 2026 changed gateway ownership, log pricing, and the product lineup:
| Date | Event | Why it matters |
|---|---|---|
| Sep 24, 2026 | Cloudflare AI Gateway moved new accounts to Workers Logs | Log pricing now follows Workers Logs. |
| May 29, 2026 | Palo Alto Networks closed its Portkey acquisition | Portkey now sells as Prisma AIRS AI Gateway. |
| Mar 3, 2026 | Mintlify announced it was acquiring Helicone | Helicone’s site now says it is no longer part of Mintlify. |
| Mar 2, 2026 | Future AGI shipped Agent Command Center and ClickHouse trace storage | Routing, fallbacks, guardrails, and budgets moved behind one API. |
How to evaluate gateways for production
-
Map your surface honestly. List the traffic types: model HTTP calls only, tool calls, MCP frames, multi-turn agent loops. The right category (AI gateway vs LLM gateway) follows from this list. If items 2-4 are non-empty, an LLM-only gateway forces a stitched control plane.
-
Run a domain reproduction. Send a representative slice of real traffic through each candidate, including failures, long-tail prompts, tool calls, and high-cost requests. Measure latency overhead, fallback success rate, cache hit rate, and observability signal at the same volume your production runs at.
-
Test guardrails under attack. Send prompt-injection payloads, PII-laden inputs, and toxicity tests through each candidate. A gateway that does not block these in production is a liability. Measure the latency budget impact of inline screening.
-
Cost-adjust at your traffic mix. Real cost equals gateway fee plus provider cost minus cache savings. OpenRouter’s 5.5% credit-purchase fee, or 5% BYOK fee after the first $25,000 of monthly BYOK inference, can be cheaper at low volume but expensive at high volume. Self-hosted gateways trade gateway fee for infra fee.
Picking the gateway layer your agents will need
A plain LLM gateway still covers a stack that only sends model calls. The label stops fitting once tool calls, MCP servers, and agent handoffs reach production, because those requests need guardrails and eval gates at the same layer that routes them. Map your traffic first, then pick the category that covers all of it. For the governance side of that decision, read Best AI Agent Governance Tools.
Route your first request through Agent Command Center and add guardrails and evals to it from the same dashboard.
Sources
Frequently Asked Questions
What is the difference between an AI gateway and an LLM gateway?
What is the difference between an MCP gateway and an LLM gateway?
What is the difference between an AI gateway and an API gateway?
Which AI gateway is the best?
Is there an open source AI gateway?
FutureAGI ACC, Helicone, OpenRouter, Portkey, LiteLLM, Cloudflare AI Gateway, Vercel AI Gateway as 2026 LLM gateways. Routing, caching, guardrails.

Future AGI, Credo AI, Holistic AI, Datadog, Purview, Lakera Guard, Fairly AI compared on policy authoring, audit trails, runtime enforcement for agents.
Compare 6 AI guardrails tools for agents in 2026, from Future AGI and Lakera to NeMo, Guardrails AI, Bedrock and OpenAI Moderation, on rails, latency and cost.
