Advanced RAG Chunking Techniques in 2026: Late Chunking, Semantic, Parent-Child, and How to Pick
Parent child chunking for RAG in 2026: how parent-child retrieval works, chunk sizes, LangChain 1.x code, plus late, semantic, and hierarchical chunking.
Table of Contents
TL;DR
| Technique | Best for | Cost | Reference |
|---|---|---|---|
| Late chunking | Documents where meaning crosses chunk boundaries | Single embedding pass on full doc | arXiv 2409.04701 |
| Semantic chunking | Long-form natural-language sources | Embeds every sentence | LlamaIndex SemanticSplitterNodeParser |
| Parent-child | Mixing small-chunk recall with large-chunk context | Two granularities stored | LangChain ParentDocumentRetriever |
| Hierarchical (RAPTOR) | Multi-hop questions over long documents | Tree-building offline | arXiv 2401.18059 |
| Sentence-level with window | Preserves sentence units, adds cross-sentence context | spaCy or NLTK | LangChain NLTKTextSplitter |
| Sliding window (recursive) | Default baseline that holds up on most corpora | None beyond a tokenizer | LangChain RecursiveCharacterTextSplitter |
| Fixed character | Quick prototyping only | None | LangChain CharacterTextSplitter |
Parent child chunking embeds small child chunks for search and hands the LLM the larger parent each match came from, so retrieval stays precise and the model sees full context. This guide covers seven RAG chunking strategies in 2026, each with code (LangChain examples updated for 1.x), the failure mode it fixes, and its cost. The last sections cover picking a chunker and testing it on your corpus.
Why RAG Still Needs Chunking in 2026
RAG works by retrieving the most relevant passages from a vector index and feeding them to the LLM as context. The retrieval step embeds the user query, looks up the k most similar chunk vectors, and returns the underlying text. Chunking is the offline step that produces those chunk vectors in the first place.
Three reasons chunking still matters even though frontier models accept 200k to 1M tokens of context:
- Latency and cost scale with context length. A 1M-token query costs hundreds of times more than a 4k-token query at the same model. Production systems chunk to keep p95 latency and per-query cost in check.
- Long context is not perfect context. Models can miss information placed in the middle of long prompts, a pattern documented in the 2023 Lost in the Middle study and worth measuring as part of LLM context window management. Retrieval-and-rerank tends to land the right facts near the top of the prompt where the model attends best.
- Evaluation only works on small enough pieces. Faithfulness, groundedness, and citation evaluators all depend on a passage-level alignment between the answer and the retrieved chunk. Without chunks, you cannot ground the eval.
What changed since 2025
Three shifts define chunking in 2026:
- Late chunking reached embedding APIs. The Gunther et al. 2024 paper (arXiv 2409.04701) showed that embedding the full document first and pooling per-chunk vectors after produces measurably better retrieval on documents with cross-chunk references. Jina AI’s embeddings API exposes it as a
late_chunkingparameter, and Voyage AI’s contextualized chunk embeddings take a related route, encoding each chunk in the context of its document’s other chunks. - Parent-child moved into managed RAG services. Amazon Bedrock Knowledge Bases ships it as hierarchical chunking, and LangChain and LlamaIndex ship it as library components.
- Evaluation moved from “did we retrieve the right chunk” to “did the answer cite the right span”. Faithfulness and groundedness metrics now trace the chunk through retrieval into the LLM answer and score on citation alignment.
The Working Text
All examples below use a short synthetic product-documentation passage as input. It is short enough to read and still shows real chunk boundaries. The LangChain code targets LangChain 1.x, which moved retrievers into langchain-classic, so the examples need langchain-classic, langchain-text-splitters, langchain-chroma, and langchain-openai.
text = """
The Acme Retrieval API accepts a query string and returns the top-k most similar passages from a configured index. By default, k is 10 and the similarity metric is cosine. The API supports filters on metadata, hybrid retrieval that combines dense and sparse scores, and a rerank step that uses a cross-encoder.

Acme's hybrid retrieval blends dense embeddings with BM25 scores. The dense weight defaults to 0.7 and the sparse weight to 0.3, but both are configurable per request. Customers report higher recall on long-tail queries when the sparse weight is increased to 0.5.

Reranking is optional. When enabled, the top 50 candidates from hybrid retrieval are passed through a cross-encoder and the top 10 are returned. Reranking adds about 200 ms of latency per request but typically improves precision at k by 8 to 12 points on Acme's internal benchmarks.
"""
1. Fixed-Size Character Chunking (Baseline)
The simplest possible chunker. Split every N characters. Useful for prototyping; almost never the right answer in production. The code below cuts on spaces at 200 characters, so a sentence can land in two chunks.
from langchain_text_splitters import CharacterTextSplitter

splitter = CharacterTextSplitter(
    chunk_size=200,
    chunk_overlap=0,
    separator=" ",
)
chunks = splitter.split_text(text)
Tradeoffs:
- No semantic awareness; chunks can split mid-sentence.
- Fast and deterministic.
- Use as a prototyping baseline only.
2. Recursive Character Chunking (Default Baseline)
The default in most stacks. The splitter tries a list of separators in order (paragraph break, then newline, then sentence boundary, then space) until each chunk fits the size limit. LangChain’s text splitter docs recommend it as the starting point for most use cases.
from langchain_text_splitters import RecursiveCharacterTextSplitter

splitter = RecursiveCharacterTextSplitter(
    chunk_size=300,
    chunk_overlap=50,
    separators=["\n\n", "\n", ". ", " ", ""],
)
chunks = splitter.split_text(text)
Tradeoffs:
- Respects natural document structure (headings, paragraphs).
- Cheap, deterministic, no embedding cost.
- Loses cross-paragraph context; meaning that spans paragraphs splits cleanly.
- The right default for code, API references, and well-structured documents.
3. Sentence-Level Chunking with Overlap
Use a linguistic parser to split on sentence boundaries, then group N sentences per chunk with an overlap. The code below uses a window of three sentences and a stride of two, so neighbouring chunks share one sentence.
import spacy

nlp = spacy.load("en_core_web_sm")
doc = nlp(text)
sentences = [sent.text.strip() for sent in doc.sents]

window = 3
stride = 2

chunks = []
for i in range(0, len(sentences), stride):
    window_sents = sentences[i : i + window]
    if window_sents:
        chunks.append(" ".join(window_sents))
Tradeoffs:
- Preserves semantic units at the sentence level.
- Adds a spaCy or NLTK dependency.
- Sliding window with stride preserves cross-sentence context at the cost of duplicate tokens.
4. Semantic Chunking (Embedding-Based Boundaries)
Embed every sentence, compute pairwise cosine similarity between consecutive sentences, and split where similarity drops below a threshold. Each chunk is then internally cohesive. The code below splits wherever the cosine similarity of two neighbouring sentences falls under 0.75.
import numpy as np
import spacy
from langchain_openai import OpenAIEmbeddings


def semantic_chunk(raw_text, threshold=0.75):
    nlp = spacy.load("en_core_web_sm")
    sentences = [sent.text.strip() for sent in nlp(raw_text).sents if sent.text.strip()]

    emb = OpenAIEmbeddings()
    vectors = np.array(emb.embed_documents(sentences))

    chunks = [[sentences[0]]]
    for i in range(1, len(sentences)):
        prev = vectors[i - 1]
        curr = vectors[i]
        sim = float(prev @ curr / (np.linalg.norm(prev) * np.linalg.norm(curr)))
        if sim >= threshold:
            chunks[-1].append(sentences[i])
        else:
            chunks.append([sentences[i]])
    return [" ".join(c) for c in chunks]


chunks = semantic_chunk(text)
LlamaIndex ships the same logic as SemanticSplitterNodeParser. LangChain’s SemanticChunker lives in the langchain-experimental package, whose GitHub repository was archived in May 2026.
Tradeoffs:
- Captures cross-sentence cohesion better than recursive chunking.
- Embedding cost on every sentence at index time.
- Threshold is a hyperparameter; tune per corpus.
5. Parent-Child (Small-to-Big) Chunking
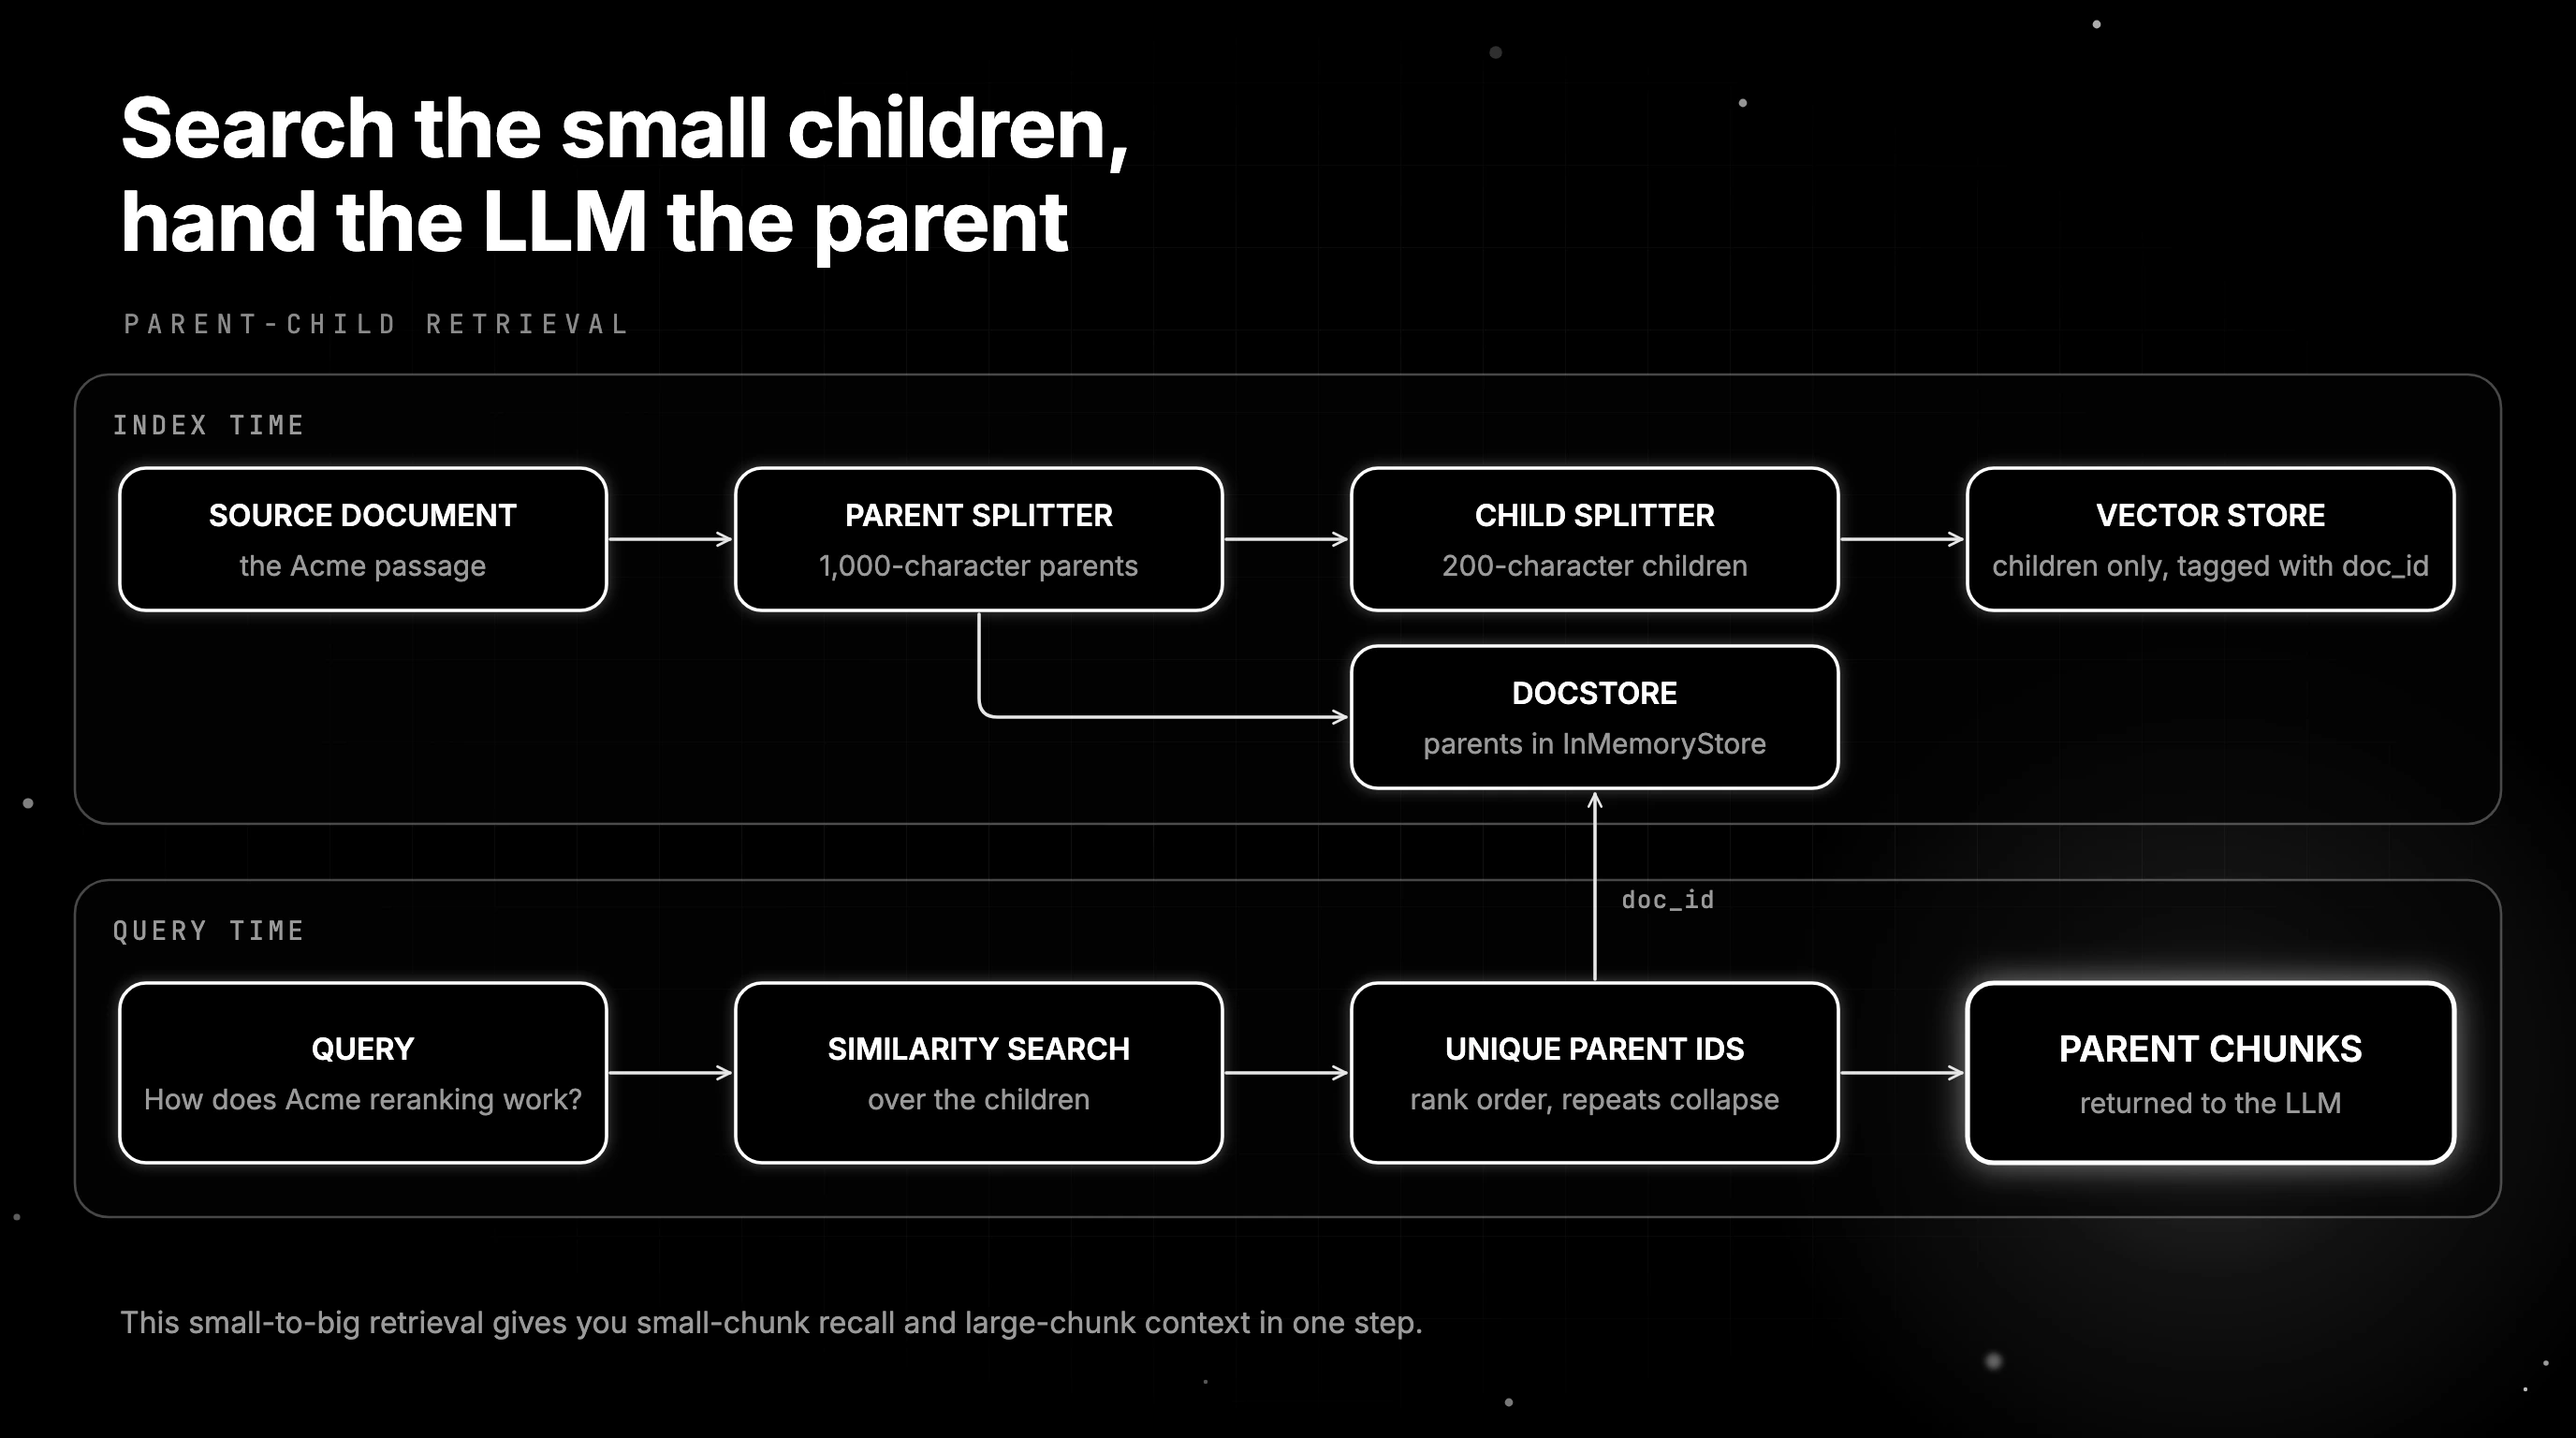
Small “child” chunks (a sentence or two each) are embedded and indexed. Large “parent” chunks (a paragraph or section) are stored alongside. At retrieval time, search over child embeddings, but return the parent chunks to the LLM. This small-to-big retrieval gives you small-chunk recall and large-chunk context in one step.
from langchain_classic.retrievers import ParentDocumentRetriever
from langchain_text_splitters import RecursiveCharacterTextSplitter
from langchain_core.stores import InMemoryStore
from langchain_chroma import Chroma
from langchain_core.documents import Document
from langchain_openai import OpenAIEmbeddings

parent_splitter = RecursiveCharacterTextSplitter(chunk_size=1000)
child_splitter = RecursiveCharacterTextSplitter(chunk_size=200)

vectorstore = Chroma(
    collection_name="rag_demo",
    embedding_function=OpenAIEmbeddings(),
)
docstore = InMemoryStore()

retriever = ParentDocumentRetriever(
    vectorstore=vectorstore,
    docstore=docstore,
    parent_splitter=parent_splitter,
    child_splitter=child_splitter,
)

# Index your source documents once so the retriever has something to return.
retriever.add_documents([Document(page_content=text)])

# At query time, the retriever embeds children but returns parent chunks.
results = retriever.invoke("How does Acme reranking work?")
LlamaIndex’s equivalent is the HierarchicalNodeParser + AutoMergingRetriever pair. Its AutoMergingRetriever merges retrieved leaf chunks into their parent once enough of that parent’s children match, so the LLM gets the larger context.
Tradeoffs:
- Best precision-recall balance for most production RAG.
- Two granularities in storage means more memory.
- Use this as your default starting point if you do not have a strong reason to pick something else.
How parent-child retrieval returns the parent
At index time, the parent splitter cuts each document into large chunks and the child splitter cuts each parent into small ones. Only the children go into the vector store, each tagged with its parent’s ID (LangChain’s default metadata key is doc_id), while the parents sit in a separate docstore. If you skip the parent splitter, the whole source document becomes the parent.
At query time, the retriever runs a similarity search over the children, keeps the unique parent IDs in rank order, and returns those parents. Several children from one parent collapse into a single result, so you can get back fewer chunks than you asked for. Amazon Bedrock Knowledge Bases warns about the same effect for its hierarchical chunking.
Choosing a parent child chunking strategy
The strategy comes down to three settings: parent size, child size, and overlap. The example above uses 1,000-character parents and 200-character children, because RecursiveCharacterTextSplitter counts characters unless you pass a token-based length function. Amazon Bedrock Knowledge Bases exposes the same settings as a maximum parent token size, a maximum child token size, and an overlap in tokens.
The LangChain parent document retriever now ships in the langchain-classic package as ParentDocumentRetriever. Test two or three size pairs with the evaluation steps below before you settle on one. On the Acme passage, the whole text fits inside one 1,000-character parent, so every query returns that single parent.
6. Late Chunking
The 2024 idea that flipped the order of operations. Instead of chunking first and embedding each chunk in isolation, you encode the whole document with a long-context embedder, then pool per-chunk vectors from the resulting token embeddings. Each chunk vector carries information from the entire document. The pattern below is illustrative pseudocode; the model-specific token-to-character alignment is non-trivial and varies per embedder, so use the official reference implementation in production.
# Illustrative only. Use the reference implementation linked below.
import numpy as np


def late_chunk_pseudocode(token_embeddings, char_to_token, chunk_spans):
    # token_embeddings: shape (num_tokens, dim) from a long-context embedder.
    # char_to_token: list of (char_start, char_end) per token from the model's tokenizer.
    # chunk_spans: list of (char_start, char_end) per intended chunk.
    chunk_vectors = []
    for start, end in chunk_spans:
        token_indices = [
            i for i, (ts, te) in enumerate(char_to_token)
            if ts >= start and te <= end
        ]
        if token_indices:
            chunk_vectors.append(np.mean(token_embeddings[token_indices], axis=0))
    return np.array(chunk_vectors)
A tested implementation lives in Jina AI’s late-chunking repository, which handles the model-specific token alignment for Jina embeddings v3 and a few other long-context models. Its README benchmark uses jina-embeddings-v2-small-en.
Tradeoffs:
- Sharp gains on documents where ideas cross chunk boundaries (legal docs, scientific papers, multi-section reports).
- Requires a long-context embedder that exposes token-level embeddings, such as jina-embeddings-v3 (8,192-token input). Standard 512-token embedders cannot do it.
- Slightly more expensive per document at index time, but a single pass instead of one per chunk.
Reference: Gunther et al., “Late Chunking: Contextual Chunk Embeddings Using Long-Context Embedding Models,” September 2024 (arXiv 2409.04701).
7. Hierarchical Chunking (RAPTOR-Style)
Build a tree whose leaves are sentences or short passages. Cluster neighbouring leaves, summarize each cluster with an LLM, and use the summaries as the next level up. Repeat to the root. At query time, search both leaves and intermediate summaries; route the question to the right granularity.
# Pseudocode sketch. The full implementation lives in the RAPTOR reference repo.

def build_tree(chunks, n_levels=3):
    level = chunks
    levels = [level]
    for _ in range(n_levels):
        clusters = cluster_by_embedding(level)
        summaries = [summarize_with_llm(c) for c in clusters]
        level = summaries
        levels.append(level)
    return levels
Reference: Sarthi et al., “RAPTOR: Recursive Abstractive Processing for Tree-Organized Retrieval,” January 2024 (arXiv 2401.18059). Code: parthsarthi03/raptor.
Tradeoffs:
- Strong on multi-hop questions that need both detail and summary-level context.
- Heavy offline cost: cluster + LLM-summarize at every level.
- Best for static, long-form corpora (books, scientific papers, regulatory filings).
How to Pick a Chunking Strategy
- Start with recursive character chunking with 300 to 500 token chunks and 10 to 20 percent overlap. Cheap, predictable, and hard to beat as a baseline.
- If retrieval recall is low, move to semantic chunking. Especially helpful on long-form prose.
- If you need both recall and large LLM context, move to parent-child. Best precision-recall balance for production.
- If your documents have cross-chunk meaning (legal, scientific, multi-section reports), move to late chunking.
- If you need multi-hop reasoning over long documents, add a RAPTOR-style hierarchical layer on top of any of the above.
Do not skip steps 1 to 3 just to chase late chunking or RAPTOR. The expensive options buy you marginal gains that you can only see if you have a working baseline to compare against. Each step adds cost, so move on only when your evaluation shows the current chunker is the bottleneck.
How to Evaluate a Chunking Strategy
Recall@10 on a vector search tells you whether the right chunk came back. The LLM still has to use that chunk correctly, so run the full RAG pipeline and score the generated answer too. For a chunking-specific eval walkthrough, see evaluating RAG chunking strategies.
A 2026 evaluation stack:
- Recall@k on a labeled query-passage set. Standard IR metric.
- Mean reciprocal rank for ordering quality.
- Faithfulness / groundedness LLM-judge metric on the final answer. Does the answer cite the retrieved chunks correctly, and only the retrieved chunks?
- Latency at p50 and p95 for the full pipeline.
- Cost per query end to end.
Future AGI’s agent-learning-kit (pip install agent-learning-kit, Apache-2.0) covers steps 1 to 3 in one library. Its local RAG metrics include recall_at_k, mrr, rag_faithfulness, and groundedness, and they run locally without an API key. Pair it with traceAI, Future AGI’s OpenTelemetry-based tracing library, so every retrieval is captured as a span and you can diff runs across chunking strategies.
# pip install agent-learning-kit
from fi.evals import evaluate

answer = "<the LLM's answer>"
chunks = ["<chunk 1>", "<chunk 2>", "<chunk 3>"]

faith = evaluate("faithfulness", output=answer, context="\n".join(chunks))
recall = evaluate("recall_at_k", query="How does Acme reranking work?",
                  contexts=chunks, relevance_scores=[1, 0, 1], config={"k": 2})
print(faith.score, recall.score, recall.reason)
For a check no built-in metric covers, write the rubric in plain English and run it with an LLM judge:
result = evaluate(
    prompt="Score 0 to 1 whether context holds every fact in expected_output.",
    output=answer, context="\n".join(chunks),
    expected_output="<the gold answer>", engine="llm", model="gpt-6-luna",
)
print(result.score, result.reason)
Cloud templates such as context_relevance and chunk_utilization run on Turing judges: turing_flash (about 1 to 2 seconds), turing_small (2 to 3 seconds), or turing_large (3 to 5 seconds). Set FI_API_KEY and FI_SECRET_KEY and pass model="turing_flash".
Picking the Chunker That Wins on Your Corpus
The right production chunker depends on your own queries and documents, and each technique section above lists the tradeoffs you will weigh. Run each candidate on the same labeled queries, score recall@k, MRR, and faithfulness, and keep the one that answers best at a latency and cost you can carry.
Run the Future AGI cookbook that compares three chunking strategies on a LangChain RAG pipeline, then score your own corpus the same way.
Sources
- Lewis et al. 2020, Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks
- Jimeno Yepes et al. 2024, Financial Report Chunking for Effective Retrieval Augmented Generation
- Gunther et al. 2024, Late Chunking: Contextual Chunk Embeddings Using Long-Context Embedding Models
- Sarthi et al. 2024, RAPTOR: Recursive Abstractive Processing for Tree-Organized Retrieval
- Liu et al. 2023, Lost in the Middle: How Language Models Use Long Contexts
- LangChain ParentDocumentRetriever reference
- LangChain v1 migration guide
- Amazon Bedrock Knowledge Bases chunking
- Jina AI late-chunking repository
- Jina AI Embeddings API
- Voyage AI contextualized chunk embeddings
- jina-embeddings-v3 model card
- LlamaIndex SemanticSplitterNodeParser
- langchain-experimental on PyPI
- RAPTOR reference code
Related reading
Frequently Asked Questions
What is parent child chunking in RAG?
How do you set up parent child chunking in LangChain?
What is the difference between hierarchical chunking and parent child chunking?
How do you choose parent and child chunk sizes?
What is late chunking?
How do you evaluate a chunking strategy?
Agentic RAG patterns that ship in 2026: query rewriting, multi-hop retrieval, tool routing, self-check loops, Self-RAG and CRAG, plus tracing and evals.

RAG evaluation metrics explained: faithfulness, context precision, context recall, groundedness and answer relevance, and which pipeline stage each one tests.

Perplexity for RAG in 2026: what the metric measures, when it is the right generator signal, when faithfulness wins, and the six-metric eval stack.