Agentic RAG in 2026: Tool-Using Retrieval Agents, Query Rewriting, Multi-Hop Patterns, and How to Observe Them
Agentic RAG patterns that ship in 2026: query rewriting, multi-hop retrieval, tool routing, self-check loops, Self-RAG and CRAG, plus tracing and evals.
Table of Contents
A research agent answers a multi-hop legal question in production. It retrieves 8 chunks, drafts an answer and ships it, and two days later a customer flags one paragraph as fabricated. The trace shows the agent used 6 of the 8 chunks and invented the seventh fact entirely, because no span scored faithfulness and no judge gated the answer. Two agentic RAG patterns were missing: a self-check and re-retrieval.
The fix is a set of agentic RAG patterns that put retrieval inside an agent loop: query rewriting, multi-hop retrieval, tool routing, a self-check on the draft and re-retrieval on failure. This guide covers each pattern, the named methods from the research, and how to trace and score every span with Future AGI’s traceAI and agent-learning-kit, both Apache-2.0.
Agentic RAG vs traditional RAG at a glance (TL;DR)
| What | Classic RAG (2023-2024) | Agentic RAG (2026) |
|---|---|---|
| Retrieval calls per turn | 1 | 1 to 6, dynamic |
| Query rewriting | Optional | Default, often with decomposition |
| Multi-hop reasoning | No | Yes, with state across hops |
| Self-check on draft | No | Faithfulness judge gates the answer |
| Re-retrieval on failure | No | Loop until supported or step-budget hit |
| Latency | 1 LLM call + 1 retrieve | 3 to 8 LLM calls + 2 to 6 retrieves |
| Best fit | FAQ, single-doc lookup | Multi-hop research, compliance, ambiguous queries |
| Failure mode | Under-retrieves | Over-retrieves, loops |
If you only read one row: agentic RAG trades latency and tokens for faithfulness on hard questions. If your hardest questions are single-doc lookups, classic RAG is correct. If your hardest questions are multi-hop or ambiguous, agentic RAG with a self-check loop wins.
What is agentic RAG, precisely
Classic RAG is a function: query in, retrieve once, generate once, answer out. The retrieval call is part of the prompt construction; the model has no agency over whether to retrieve or what to retrieve.
Agentic RAG is a loop with a policy. The LLM agent decides whether to retrieve, with which query and retriever, and whether the result is enough. It then checks the draft against the evidence and either retrieves more or hands back a refusal.
Concretely, agentic RAG has four primitives the classic pipeline does not:
- Decision to retrieve. The agent can choose to answer from its own knowledge for trivial questions and only call the retriever when the question is corpus-specific.
- Query transformation. The agent rewrites the user query before retrieval. It can decompose a 2-hop question into 2 sub-queries, expand entities, or restate in domain vocabulary.
- Iterative retrieval. The agent retrieves, reads, decides whether more evidence is needed, and retrieves again. The chain runs until the agent has enough or hits a step budget.
- Self-check. Before the answer ships, a judge scores faithfulness or groundedness. If the judge flags a claim, the agent loops back to retrieval.
Each of these primitives has a cost in tokens and latency. The trade is reliability on hard questions for cost on easy ones. A well-tuned agentic RAG routes easy questions through 1 retrieve and hard questions through 4, hitting both targets.
The five agentic RAG patterns that ship in 2026
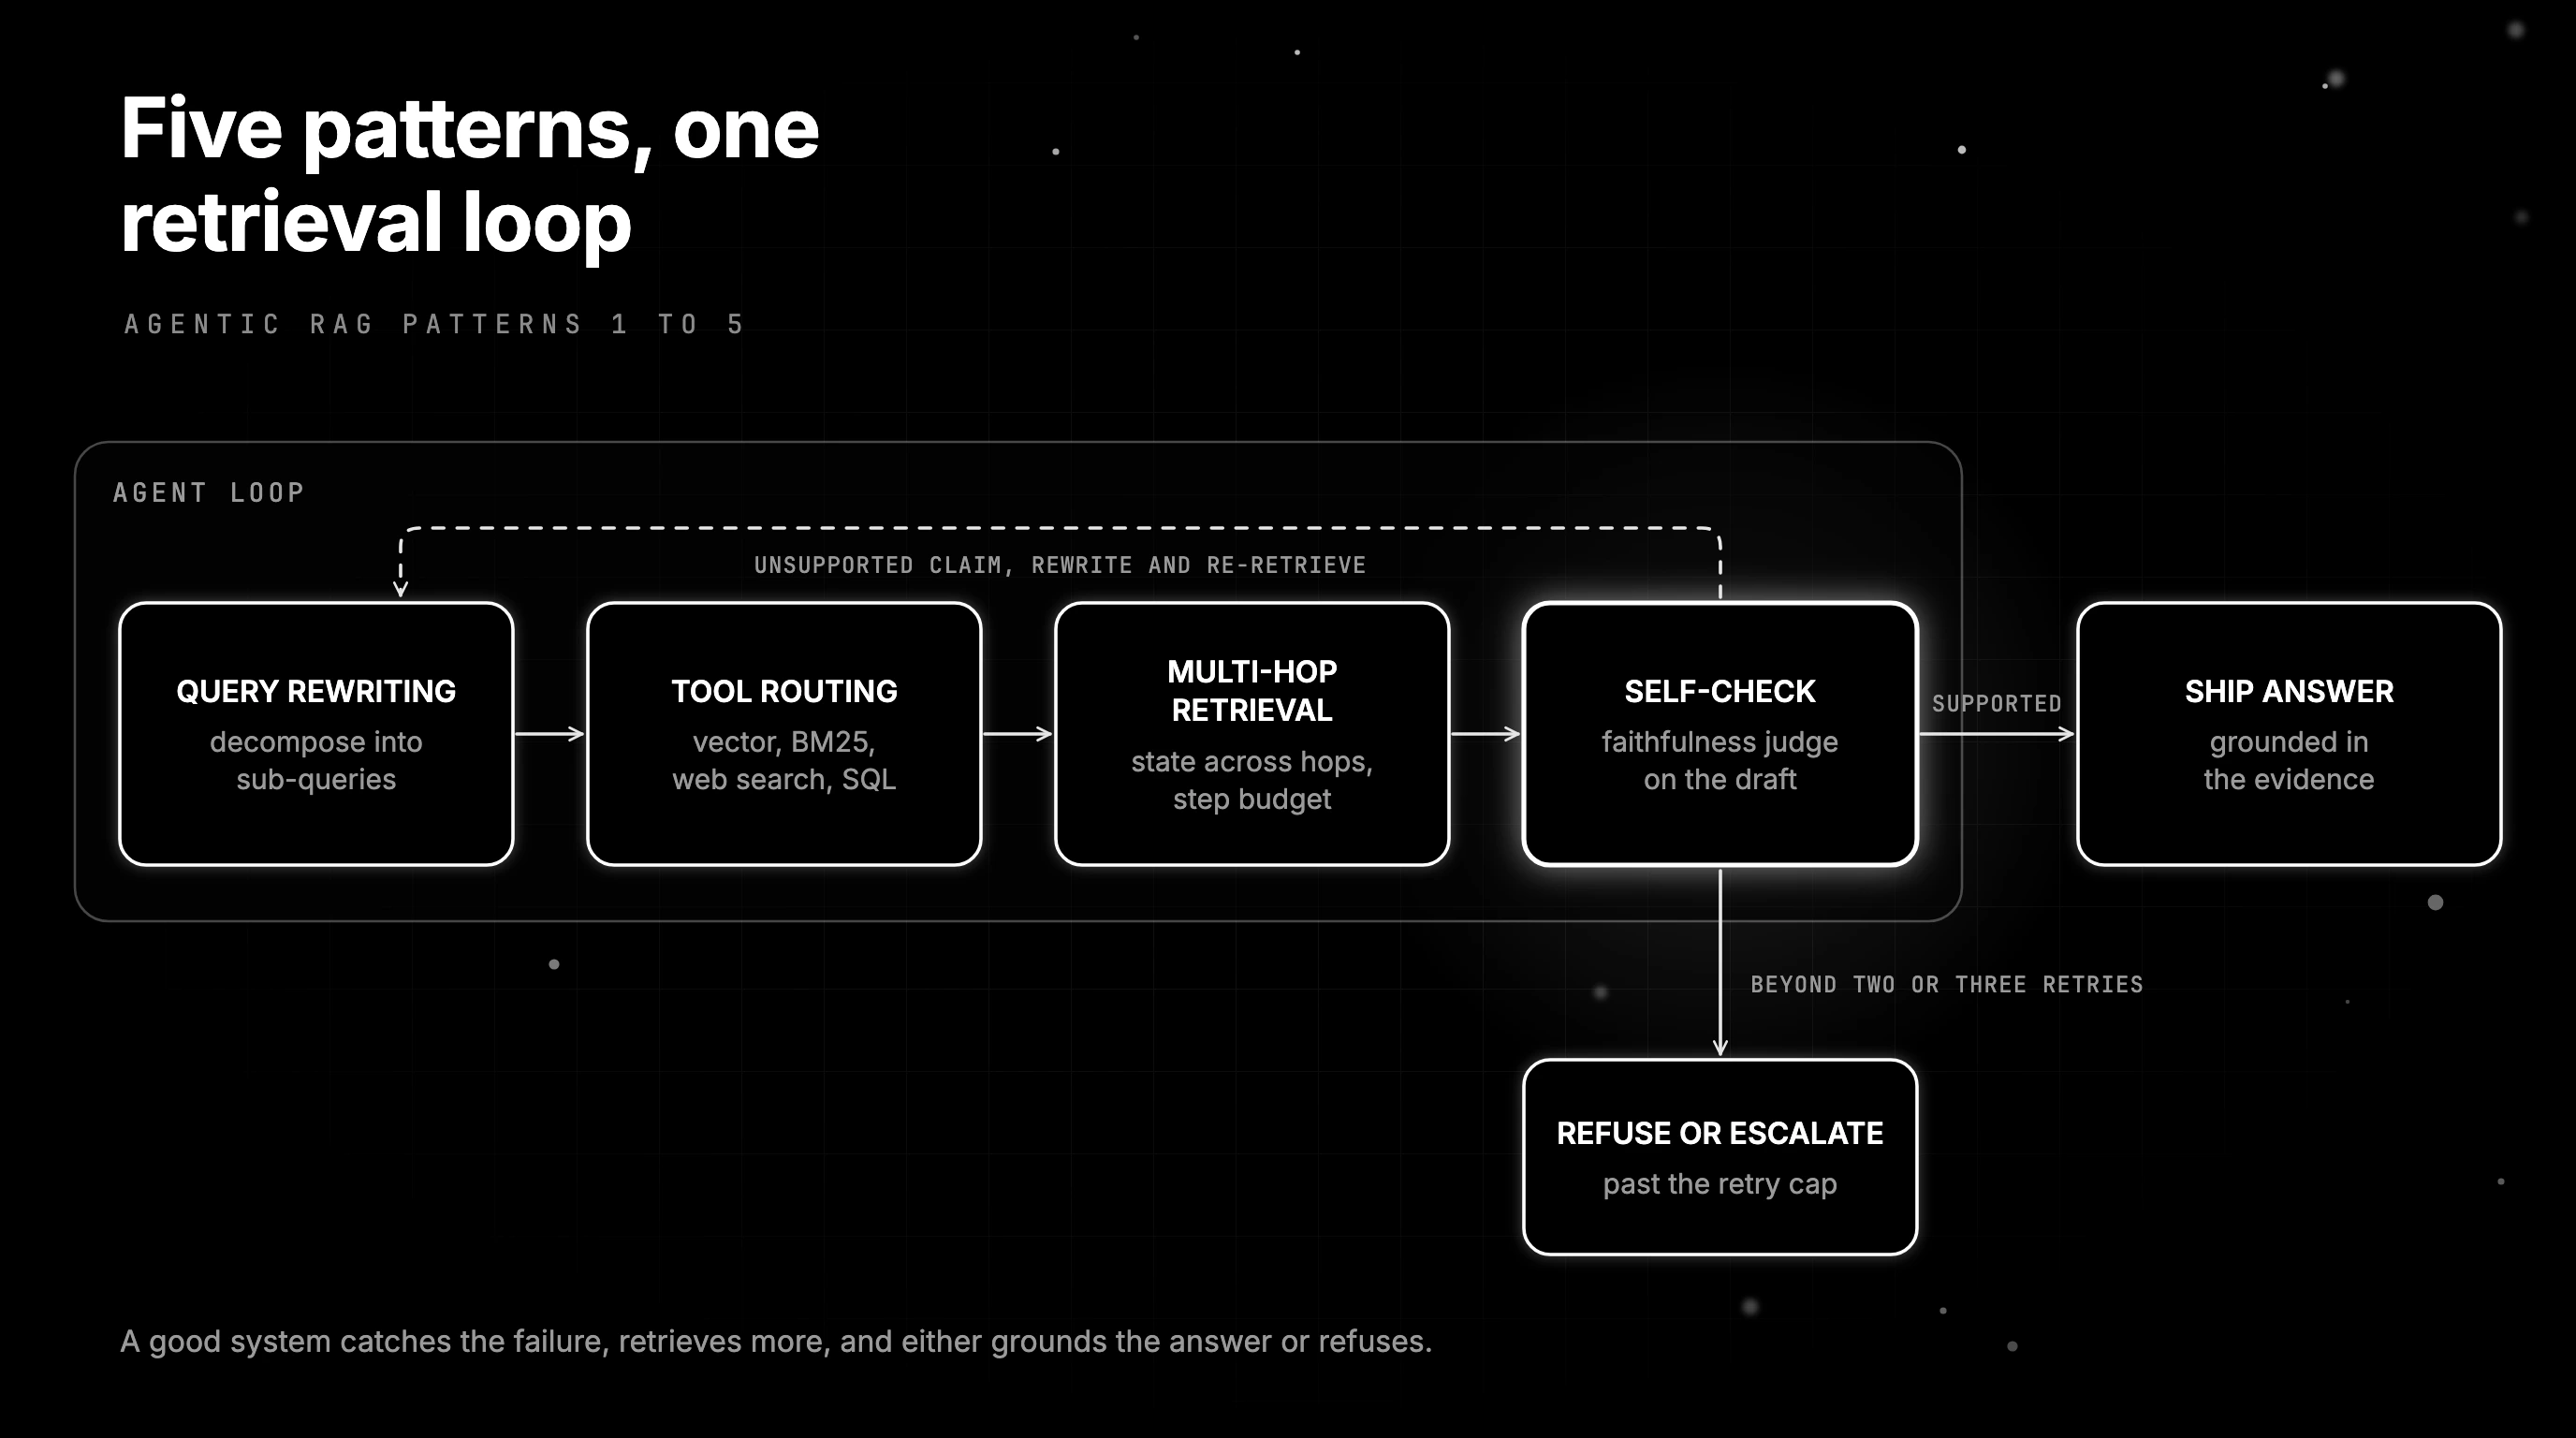
Across the agentic RAG pipelines that hit production in the last year, five patterns recur: query rewriting and decomposition, multi-hop retrieval with state, tool routing across retrievers, a self-check on the draft, and re-retrieval on failure. A real system uses 3 or 4 of them, rarely all 5.
Pattern 1: Query rewriting and decomposition
The user query is rarely what the retriever wants. “What’s the latency difference between the new turbo model and what we shipped last quarter?” needs to become two retrieval queries: one for the new turbo model spec, one for last quarter’s release. Decomposition is the agent step that splits and rewrites.
Two common shapes:
- Step-back prompting: rewrite the literal query into a more general question that surfaces background, then a more specific question that surfaces the fact. Useful for ambiguous queries where the literal phrasing misses the corpus.
- Sub-query decomposition: split a multi-hop question into N independent sub-questions, retrieve each, then synthesize. The classic example is HotpotQA-style 2-hop questions where one entity is in document A and one is in document B.
On multi-hop QA benchmarks, retrieving more than once pays off. The IRCoT paper interleaves retrieval with chain-of-thought steps and, with GPT-3, reports gains of up to 21 points in retrieval and up to 15 points in downstream QA on HotpotQA, 2WikiMultihopQA, MuSiQue and IIRC. The trade is extra LLM calls per turn, so multi-step retrieval and decomposition only pay when multi-hop questions are common; for single-doc lookups, query rewriting alone is enough.
Pattern 2: Multi-hop retrieval with state
Multi-hop retrieval keeps state across hops: each retrieve call sees the previous retrieves and the partial reasoning. The agent reads chunk 1, identifies the missing fact, retrieves chunk 2 against the rewritten query, and continues. LangGraph’s state machine, the OpenAI Agents SDK’s tool-call loop, and LlamaIndex’s AgentWorkflow all provide this shape natively.
Three design choices matter:
- Step budget. Cap the number of retrieves per turn (typical: 4 to 6). Without a cap, the agent loops.
- Stop condition. The agent emits an “I have enough” signal, or a confidence score above threshold, or a faithfulness check passes. Without an explicit stop, the agent keeps retrieving.
- State carry-over. Pass the prior chunks (or a summary) and the running plan into the next retrieve prompt so the agent does not re-retrieve the same chunks.
Pattern 3: Tool routing across retrievers
Production agentic RAG rarely uses one retriever. The agent picks per query:
- Dense vector search for semantic similarity (default).
- BM25 / sparse retrieval for exact term matching, IDs, error codes, version numbers.
- Hybrid (BM25 + dense) for the common case where both signals matter.
- Web search when the corpus is stale on a recent event.
- SQL / structured data when the question is a metric (a count, a sum, a comparison).
- Re-ranker (Cohere Rerank, BGE Reranker, Jina Reranker) as a second stage on top of the first-stage retriever to lift precision.
The tool-routing step is itself a tool-call: the agent emits “use BM25 for this query” or “use web_search for this query” and the framework dispatches. The router can be the LLM itself (zero-shot tool selection) or a small classifier (faster, less flexible).
Pattern 4: Self-check on the draft
Before the final answer ships, a judge scores faithfulness or groundedness against the retrieved chunks. Three options for the judge:
- Reference-free faithfulness judge (a common production pattern in 2026). The judge sees the draft and the retrieved chunks and emits a per-sentence support score.
- Citation enforcement. The agent is required to attach a chunk ID to every sentence; sentences without a citation are stripped or rewritten.
- Hallucination detector running independently of the agent’s own confidence.
Future AGI’s fi.evals covers faithfulness, groundedness, and hallucination scoring directly; citation enforcement is then a thin application rule on top of those scores (drop or rewrite sentences without a matching chunk ID). The judge call costs 1 to 2 extra evals per turn, either the local faithfulness metric with no API key or a Turing cloud template such as groundedness (turing_flash at ~1-2s, turing_small at ~2-3s).
Pattern 5: Re-retrieval on failure
When the self-check flags an unsupported claim, the agent rewrites the query around that claim and retrieves again. Two or three retries is the typical cap; beyond that the agent should refuse or escalate.
The re-retrieve loop is what separates a good agentic RAG from a bad one. A naive system without re-retrieval ships hallucinated answers when the first retrieve missed; a good system catches the failure, retrieves more, and either grounds the answer or refuses.
Named agentic RAG design patterns from the research
The five patterns above are building blocks. Research papers package them into named methods, and each maps back to the patterns in this guide.
| Method | Paper | What the agent does | Closest pattern here |
|---|---|---|---|
| ReAct | ReAct, 2022 | Interleaves reasoning with actions such as search calls | 2 and 3 |
| IRCoT | IRCoT, 2022 | Retrieves again after each chain-of-thought step | 2 |
| Self-RAG | Self-RAG, 2023 | A trained model retrieves on demand and critiques passages and its output with reflection tokens | 4 |
| Corrective RAG (CRAG) | CRAG, 2024 | A retrieval evaluator scores documents and triggers web search when retrieval is weak | 3 and 5 |
| Adaptive-RAG | Adaptive-RAG, 2024 | A small trained classifier routes queries to no, single-step or iterative retrieval | 3 |
Self-RAG vs Corrective RAG vs Adaptive-RAG
Self-RAG changes the model: it trains one language model to decide when to retrieve and to critique what it reads and writes. Corrective RAG leaves the generator alone and adds an evaluator that triggers web search when retrieval looks weak, and its authors describe it as plug-and-play with other RAG approaches. Adaptive-RAG instead decides how much retrieval each query needs, from none to iterative.
A reference agentic RAG implementation
The skeleton below shows the five patterns wired together using LangGraph, with Future AGI traceAI for spans and fi.evals for the faithfulness judge. Substitute the framework you use; the pattern shape is the same.
# PSEUDOCODE: adapt to your stack. The fi.evals.evaluate call and
# the fi_instrumentation.register / traceai_langchain.LangChainInstrumentor
# calls are real APIs (pip install "traceAI-langchain[langgraph]" agent-learning-kit).
# The llm_rewrite, pick_retriever, has_enough_evidence, and
# llm_generate functions are placeholders for your own retriever, planner,
# and generation primitives.

from fi_instrumentation import register
from fi_instrumentation.fi_types import ProjectType
from traceai_langchain import LangChainInstrumentor  # covers LangGraph via the [langgraph] extra
from fi.evals import evaluate

# 1. Wire OTel tracing once at startup (real API)
trace_provider = register(project_type=ProjectType.OBSERVE, project_name="agentic-rag-prod")
LangChainInstrumentor().instrument(tracer_provider=trace_provider)

# 2. Define the loop: rewrite -> retrieve -> reason -> (re-retrieve | answer)
def rewrite_query(state):
    # Pattern 1: query rewriting / decomposition (placeholder)
    state["queries"] = llm_rewrite(state["user_query"])
    return state

def retrieve(state):
    # Pattern 3: tool routing across retrievers (placeholder)
    tool = pick_retriever(state["queries"][-1])
    chunks = tool.retrieve(state["queries"][-1], k=10)
    state["chunks"].extend(chunks)
    return state

def reason(state):
    # Pattern 2: multi-hop state carry-over (placeholder)
    if has_enough_evidence(state) or state["hops"] >= MAX_HOPS:
        state["next"] = "draft"
    else:
        state["next"] = "rewrite"
        state["hops"] += 1
    return state

def draft(state):
    state["draft"] = llm_generate(state["user_query"], state["chunks"])
    return state

def self_check(state):
    # Pattern 4: faithfulness judge gates the answer (real fi.evals call)
    result = evaluate(
        "faithfulness",
        output=state["draft"],
        context="\n".join(c.text for c in state["chunks"]),
    )
    if result.score >= 0.8:
        state["next"] = "ship"
    elif state["retries"] < MAX_RETRIES:
        state["next"] = "rewrite"  # Pattern 5: re-retrieve on failure
        state["retries"] += 1
    else:
        state["next"] = "refuse"
    return state
The five-step loop above ties the five patterns together. Every step emits a span; every span carries an evaluator score; the dashboard rolls up per-trace into four metrics: faithfulness rate, retrieves-per-correct-answer, latency p95, cost-per-correct-answer.
Observability and evaluation, the part most teams skip
A working agentic RAG without trace + eval is a black box. You see latency p95 and an answer, but not which hop missed, which retriever returned the wrong chunks, or whether the faithfulness judge agreed with humans.
Trace every span
Use traceAI (Apache 2.0) or OpenInference (Apache 2.0) to emit OTel spans for every retrieve, rerank, generate, and judge call. The span attributes (input, output, model, tokens, latency) flow into Future AGI’s dashboard or any OTel-compatible back-end.
Attach evaluators to spans
The four core evaluators for agentic RAG:
- context_relevance: scored on the retrieve span, measures whether the retrieved chunks are relevant to the rewritten query. Catches retrieval drift.
- faithfulness (or groundedness): scored on the generate span, measures whether the draft is supported by the retrieved chunks. Catches hallucination.
- detect_hallucination: a judge on the final answer that flags facts not found in the retrieved context. The safety net.
- answer_relevancy: scored on the final answer, measures whether the answer actually addresses the user query. Catches off-topic drift.
The context_relevance and detect_hallucination evals run on Turing cloud models (turing_flash ~1-2 seconds, turing_small ~2-3, turing_large ~3-5). Faithfulness and answer_relevancy run locally with no API key, so call them separately, as the docs advise.
The four roll-up metrics
From per-span evaluator scores, four trace-level metrics give you the dashboard:
- Faithfulness rate: percent of traces where the final answer passes the faithfulness threshold.
- Retrieves-per-correct-answer: total retrieves divided by traces with passing faithfulness. Surfaces over-retrieval.
- Latency p95: the standard latency tail.
- Cost-per-correct-answer: total cost divided by passing traces. The composite you use for ship/no-ship.
Tracking only latency p95 is the most common eval mistake. A pipeline that drops latency by 30% by skipping the self-check looks like a win on the dashboard and ships hallucinations.
How to choose between agentic and classic RAG
Three questions decide which one fits:
- Are the hardest questions multi-hop? If yes, agentic RAG wins. If no, classic RAG is faster and cheaper.
- Does faithfulness matter more than latency? Legal, medical, compliance, finance: yes, agentic with self-check. High-volume customer support FAQ: latency wins, classic.
- Do you have observability? Agentic RAG without trace + eval ships hallucinations you cannot debug. If you cannot wire in traceAI or equivalent before ship, run classic until you can.
For most production builders, the answer is hybrid: classic single-pass for easy questions, agentic for hard ones, with the agent itself deciding which path. The dispatch logic is a tool-routing step at the top of the agent.
Frameworks at a glance
As of October 2026:
- LangGraph: low-level orchestration framework and runtime for long-running, stateful agents; it does not require LangChain. The default for stateful agentic RAG. Mature, debuggable, instrumentable with traceAI through the LangChain integration.
- OpenAI Agents SDK: lightweight multi-agent framework that supports the OpenAI Responses and Chat Completions APIs plus 100+ other LLMs. Fast to prototype.
- LlamaIndex AgentWorkflow: retrieval-first agent framework. The fit when retrieval is the primary primitive and the agent is a loop around it.
- CrewAI: role-based multi-agent. Good for retrieve-and-write workflows where a researcher agent and a writer agent share state.
- Microsoft Agent Framework: the direct successor to AutoGen and Semantic Kernel, with graph-based workflows for multi-agent orchestration.
- Pydantic AI: typed agent framework. The pick for Python codebases that already use Pydantic for everything.
Each can be instrumented via traceAI or OpenInference (some with a ready-made integration, others through OTel adapters or custom wrappers); all can be evaluated with fi.evals. The framework is replaceable; the trace + eval back-end is the piece you keep when you switch. For a deeper comparison of OSS agent frameworks, see The Open-Source Stack for AI Agents in 2026. For framework-level eval, see Agent Eval Metrics in 2026.
Common failure modes and the fix for each
Over-retrieval
The agent loops, retrieves 8 to 12 times, burns tokens. The fix is a hard step budget (max 4 retrieves), an explicit stop signal in the agent prompt, and a retrieves-per-correct-answer metric on the dashboard so you can see when a deploy regresses.
Under-retrieval
The agent stops at 1 retrieve when the question needed 3. The fix is the self-check loop: the faithfulness judge flags unsupported claims and triggers re-retrieval. Without the judge, the agent has no signal to keep going.
Tool misrouting
The agent picks BM25 for a semantic query or vector search for an exact ID match. The fix is a per-tool span with a hit-rate metric. Misrouting shows up as a tool whose retrieval results are never used downstream.
Judge drift
The faithfulness judge labels too leniently and lets hallucinations through. The fix is periodic calibration: 50 to 100 human labels per month, compared against the judge’s verdicts. A typical starting threshold is Cohen’s kappa around 0.6 (the moderate-to-substantial agreement boundary on Landis and Koch’s scale); tune the threshold based on the risk class of the application and the cost of false positives.
State contamination
Long agent runs accumulate context from prior turns and confuse the retriever. The fix is per-turn state reset and a summary primitive that compresses prior turns into a 200-token summary rather than carrying the full transcript. For depth on retrieval-quality monitoring, see Best Retrieval Quality Monitoring Tools 2026. For re-ranker selection, see Best Rerankers for RAG 2026.
Where this is going in 2027
Three trends are visible. First, retrieval is becoming a learned policy rather than a static pipeline. The agent picks which retriever, which top-k, which re-ranker depth, and which chunk size per query.
Second, the agentic and structured-data boundary is blurring. Production agents increasingly query SQL, knowledge graphs, and vector indexes interchangeably; the agent’s job is to pick. Graph-RAG and SQL-aware agents are absorbing what used to be separate categories.
Third, the trace + eval layer is becoming the platform. Frameworks keep changing; the OTel + evaluator-attached-spans pattern is the constant. Pick the platform that owns the trace + eval layer first, the framework second.
How to start catching unsupported answers
If you are building agentic RAG in 2026:
- Pick the framework that fits your team (LangGraph for stateful, Agents SDK for a lightweight start, LlamaIndex for retrieval-first).
- Wire traceAI (Apache 2.0) or OpenInference at the framework instrumentation point. Use the ready-made integration where available; otherwise add an OTel adapter or wrapper.
- Attach fi.evals metrics and templates (context_relevance, faithfulness, answer_relevancy) to your retrieve and generate spans.
- Run a 100-query golden set with the four roll-up metrics and a manual review of 20 failures. The pattern in those 20 failures tells you which of the 5 patterns is missing.
- Add the missing pattern, re-run, ship when faithfulness rate clears your threshold.
Back to the legal research agent. With traceAI spans on every hop and a faithfulness judge gating the draft, the fabricated seventh fact fails the self-check, the agent re-retrieves or refuses, and the trace shows which hop missed. Future AGI runs steps 2 to 4 in one stack, and its Apache-2.0 core self-hosts or runs in the cloud.
Trace your agentic RAG pipeline with traceAI and score every retrieve span.
Sources
- LangGraph overview
- OpenAI Agents SDK
- LlamaIndex AgentWorkflow and multi-agent patterns
- Microsoft Agent Framework overview
- CrewAI documentation
- Pydantic AI overview
- OpenTelemetry GenAI semantic conventions
- HotpotQA multi-hop benchmark
- MuSiQue paper
- 2WikiMultiHopQA paper
- IIRC paper
- IRCoT paper
- Step-back prompting paper
- ReAct paper
- Self-RAG paper
- Corrective RAG (CRAG) paper
- Adaptive-RAG paper
- GraphRAG paper
- Landis and Koch (1977), The measurement of observer agreement for categorical data
Frequently Asked Questions
What is agentic RAG?
Agentic RAG vs traditional RAG, what changes?
What are the main agentic RAG design patterns?
What is the difference between Self-RAG and Corrective RAG?
Agentic RAG vs graph RAG, how do they differ?
How do you evaluate an agentic RAG pipeline?
RAG evaluation is retrieval, generation, and end-to-end scoring under one framework. What it is, how to score each layer, which tools handle it in 2026.

Ragas, DeepEval, FutureAGI, Phoenix, Galileo, Langfuse, TruLens compared as the 2026 RAG eval shortlist. Faithfulness, retrieval, chunk attribution.

Compare the best reranker models for RAG in 2026, from Cohere Rerank 5 and Voyage rerank-3 to BGE, Qwen3, Jina v3.5, mxbai and ColBERT, on license and latency.