Manus AI Benchmark Results, Pricing and Best Alternatives in 2026
Manus AI benchmark results on GAIA, credit-based pricing, Manus 2.0 and Flex models, and how it compares with Devin, Cursor, Claude Code, and ChatGPT agent.
Table of Contents
The Manus AI benchmark claim rests on GAIA: at its March 2025 launch, Manus reported 86.5%, 70.1%, and 57.7% pass@1 on Levels 1 to 3, ahead of OpenAI deep research. The product has changed since then. Manus 2.0 shipped in September 2026, Manus Flex lets you bring your own model key, and Manus is independent again after China blocked Meta’s acquisition.
TL;DR on Manus AI benchmark scores and the autonomous-agent field
| Tool | Best for | Pricing (checked Oct 2026) | GAIA L1 / L2 / L3 (reported) |
|---|---|---|---|
| Manus 2.0 | End-to-end research and deliverables (browse, code, write, ship) | credit-based Free, Pro, and Team plans | 86.5% / 70.1% / 57.7% (March 2025 launch, self-reported) |
| Cursor | IDE-resident multi-file coding with diff review | Free, then $8 to $200/mo | n/a (not a GAIA target) |
| Devin (Cognition) | Hands-off ticket-to-PR on real repos | Free, Pro $20/mo, Max $200/mo, Teams $80/mo + $40/seat | not reported |
| Replit Agent | Browser-based prototypes and internal tools | Core $20/mo, Pro $100/mo | n/a |
| Claude Code (Anthropic) | Terminal-native engineer-in-the-loop coding | In Claude Pro $20/mo, Max $100/mo, Ultra $200/mo | n/a |
| ChatGPT Work (OpenAI) | Longer, multi-step work and finished deliverables | Availability depends on ChatGPT plan and workspace settings | not reported |
| OpenAI deep research | Long-form research with citations | Included in ChatGPT Plus/Pro | 74.3% / 69.1% / 47.6% (Feb 2025, OpenAI) |
GAIA figures are each vendor’s own pass@1 launch results; prices checked October 31, 2026.
If you only read one row: Manus is built for analyst-style workflows that span browsing, code, and documents. Cursor or Claude Code if the task is mostly code. Devin if you want zero-touch ticket-to-PR. ChatGPT Work or OpenAI deep research if you already live inside ChatGPT.
How the Manus agent loop works
Manus is a planner-driven multi-agent system that splits each task across specialist sub-agents. The high-level loop:
- Planner. A central planning agent reads the user task and produces a plan tree (steps, sub-steps, expected artifacts, validation criteria).
- Executor. A scheduler farms steps out to specialist sub-agents (browser, code, file, validation).
- Sandboxed runtime. Every action runs inside the Manus Sandbox, a fully isolated cloud VM per task with networking, a file system, a browser, and tools.
- Memory and trace. Sub-agents pass back compact summaries plus pointers to full artifacts. The executor maintains a working memory and a full audit trace.
- Artifact assembly. Deliverables (docs, slides, code repos, deployed sites) are written to the workspace and surfaced to the user.
What LLM does Manus use?
Manus handles model selection for you. In the standard modes (Manus 2.0 Max, Manus 2.0, and Manus 2.0 Lite), Manus picks the language model that runs the agent and bills the work in credits. Manus 2.0 also added Cascade, its in-house agent harness, which used 23.2% fewer tokens in one Manus test.
Manus Flex, now in beta, runs Manus on your own API key from OpenAI, Anthropic, Google AI Studio, xAI, Meta, OpenRouter, Fireworks, or Modal, with a model and effort level you choose. Your provider bills model usage, while images, video, Cloud Computer, and web app hosting still use Manus credits.
Manus benchmark results on GAIA
These are the GAIA (general AI assistant benchmark, three difficulty levels) pass@1 scores Manus published at its March 2025 launch, next to OpenAI deep research and the prior state of the art OpenAI cited. Manus’s 1.5, 1.6, and 2.0 posts report internal tests, not new GAIA runs.
| GAIA level | Manus (March 2025 launch) | OpenAI deep research (Feb 2025) | Previous SOTA cited by OpenAI |
|---|---|---|---|
| Level 1 | 86.5% | 74.3% | 67.9% |
| Level 2 | 70.1% | 69.1% | 67.4% |
| Level 3 | 57.7% | 47.6% | 42.3% |
On those launch numbers, Manus led OpenAI deep research by about 12 points on Level 1, 1 point on Level 2, and 10 points on Level 3. That Level 3 margin on long, multi-step tasks is the strongest public case for Manus on analyst and research work.
Three caveats:
- Benchmark contamination. A UC Berkeley RDI report (Trustworthy Benchmarks) found that an automated exploit agent could score about 98% on GAIA’s 165 validation questions without solving them, because the validation answers are public and loose answer normalization lets near-miss answers match. Treat vendor GAIA numbers as directional and always pair them with a domain reproduction.
- Domain match. GAIA is heavy on web research, file handling, and multi-tool reasoning. If your workload is closer to that, Manus’s lead transfers. If your workload is heavy on coding, GAIA does not predict the right pick (Cursor or Devin will likely win there).
- Recovery cost. GAIA reports pass-at-one. Your cost per successful task depends on retries, so measure it on your own workload.
The right move for production: run a 50 to 200 prompt domain reproduction with your real workload. Score it with an LLM judge plus human spot checks, and decide from your numbers, not the public leaderboard.
Standout Manus use cases that hold up in 2026
Three task shapes where Manus fits better than a single-shot agent:
Multi-source research with a written deliverable
Give Manus a topic (market sizing for vertical X, competitive scan of category Y, regulatory rules for product Z) and it returns a structured doc with citations, charts, and an executive summary. The planner-executor loop is well suited to research because Wide Research runs parallel sub-agents.
Data analysis with chart output
Hand Manus a CSV or a Google Sheet and a question. It loads the data into pandas, runs the right transformations, generates matplotlib or plotly charts, and writes a memo. Manus says 1.6 Max is especially strong on spreadsheets, from financial modeling and data analysis to automated reports.
Web build and deploy
Manus can build and deploy a full-stack web app with a backend, database, and user login. This is shallower than what Cursor or Replit Agent will do for a real codebase, but for landing pages, prototypes, and microsites it is a one-shot win.
Where Manus is the wrong tool
- Production SWE on a real repo. Use Devin or Cursor. Manus’s code agent is fine for scripts but does not maintain the same level of test-driven discipline.
- Latency-sensitive workflows. Manus tasks take minutes (just under 4 minutes on average, per Manus in October 2025). If you need sub-second responses, you want a single-shot LLM with tools, not an autonomous agent.
- Strict deterministic pipelines. If the task has a known shape and known steps, a hand-coded pipeline with one LLM call per step is cheaper and more reliable than an autonomous agent.
Manus AI versus the 2026 alternatives
Manus versus Cursor
Pick Cursor if the task lives in a codebase. Cursor’s Agent edits across your repo in the editor, Premium and higher plans add cloud agents and Bugbot code reviews, and the engineer keeps full edit authority. The mental model is “an agent helping me code” rather than “an agent doing it for me.”
Pick Manus if the task spans browser, code, and writing. Manus is built for that broader workflow. Cursor is code-first but can also search the web.
Manus versus Devin (Cognition)
Pick Devin if you want zero-touch ticket-to-PR work on a real repo. Devin runs in a persistent cloud VM, takes a GitHub or Linear ticket, reads the codebase, writes the change, runs the tests, opens the PR, and responds to review comments. Plans: Free, Pro at $20 a month, Max at $200 a month, and Teams at $80 a month plus $40 per seat.
Pick Manus if the work is not strictly code. Devin is purpose-built for SWE tickets. Use Manus when the deliverable is a doc, a report, a slide deck, or a small site rather than a PR.
Manus versus Replit Agent
Pick Replit Agent if you want a deployed full-stack app in the browser with zero setup. Replit Agent includes a hosted environment, databases, and deployment in one product. Core $20/mo, Pro $100/mo. Great for prototypes, internal tools, and apps that can live on Replit’s infrastructure.
Pick Manus if you want artifacts that live outside Replit. Replit Agent’s output assumes the Replit environment. Manus’s output (docs, slides, and code zips) is portable.
Manus versus Claude Code
Pick Claude Code if you live in the terminal. Claude Code is Anthropic’s terminal-native coding agent with native MCP, Bash, and file system access. Power users run multi-hour sessions with bash heredocs, custom slash commands, and skill files. Claude Code comes with Claude Pro ($20 a month), Max ($100 a month), and Ultra ($200 a month).
Pick Manus if the task is broader than code. Claude Code is a coding agent. Manus is a general-purpose agent that happens to write code.
Manus versus ChatGPT agent
ChatGPT agent is no longer available. OpenAI merged Operator and deep research into it in July 2025. OpenAI now directs users to ChatGPT Work for longer, multi-step tasks and finished deliverables.
Pick Manus if you prefer a standalone agent with its own cloud sandbox. Manus plans the work and hands back finished files.
Manus versus OpenAI deep research
Pick OpenAI deep research if you only need a written report with citations. It is the closest pure-research competitor to Manus and ships inside ChatGPT.
Pick Manus if the deliverable is more than a report. Manus produces structured docs, slides, sites, and code. Deep research produces a cited written report.
Open-source alternatives to Manus
Three open-source patterns to know:
- OpenManus. A community port of the Manus architecture (planner-executor with sandbox). MIT. Useful if you want to self-host the pattern, but the planner is less mature and the sandbox depends on your own infrastructure.
- Microsoft Agent Framework. Microsoft archived AutoGen and points new users here, for agents and multi-agent workflows in Python and .NET.
- LangGraph agents (LangChain). Stateful graph orchestration. Strong on durable execution and long-term memory. Use this if you want auditable, replayable agent runs.
Self-hosting saves money on credits but moves the operational burden to you. For most teams in 2026, the hosted offerings (Manus, Cursor, Devin, Claude Code) are still the right call until you have enough volume to justify the infrastructure.
Strengths and limitations of Manus AI
Strengths
- End-to-end coverage. Browser, code, file, deploy in one agent. Most competitors specialize in one of those.
- Long-horizon planning. The planner-executor loop is mature.
- Artifact pipeline. Manus writes real files (Word, Excel, slides, code) rather than just chat replies.
- Sandbox isolation. A fully isolated cloud VM for each task. Safer than running a freeform agent on your laptop.
- GAIA launch scores. 57.7% on Level 3 at launch, ahead of OpenAI deep research’s 47.6%.
Limitations
- Cost on hard tasks. Manus bills credits by the complexity and resources each task needs, so long multi-step runs cost more.
- Latency. Tasks take minutes (just under 4 minutes on average, per Manus in October 2025). Not suitable for interactive use.
- Coding depth. Cursor, Devin, and Claude Code each beat Manus on real codebase work.
- Prompt-injection surface. Like every browser-equipped agent, Manus is vulnerable to malicious page content. Sanitize inbound content and restrict outbound egress.
- Model choice needs Flex. Standard modes run a language model Manus selects; Flex takes your own provider key but is in beta, and media still uses Manus credits.
- Limited fine-grained customization. You cannot swap out the planner or the executor. If you need that level of control, OpenManus or LangGraph is the right pattern.
How to evaluate Manus AI or any autonomous agent before production
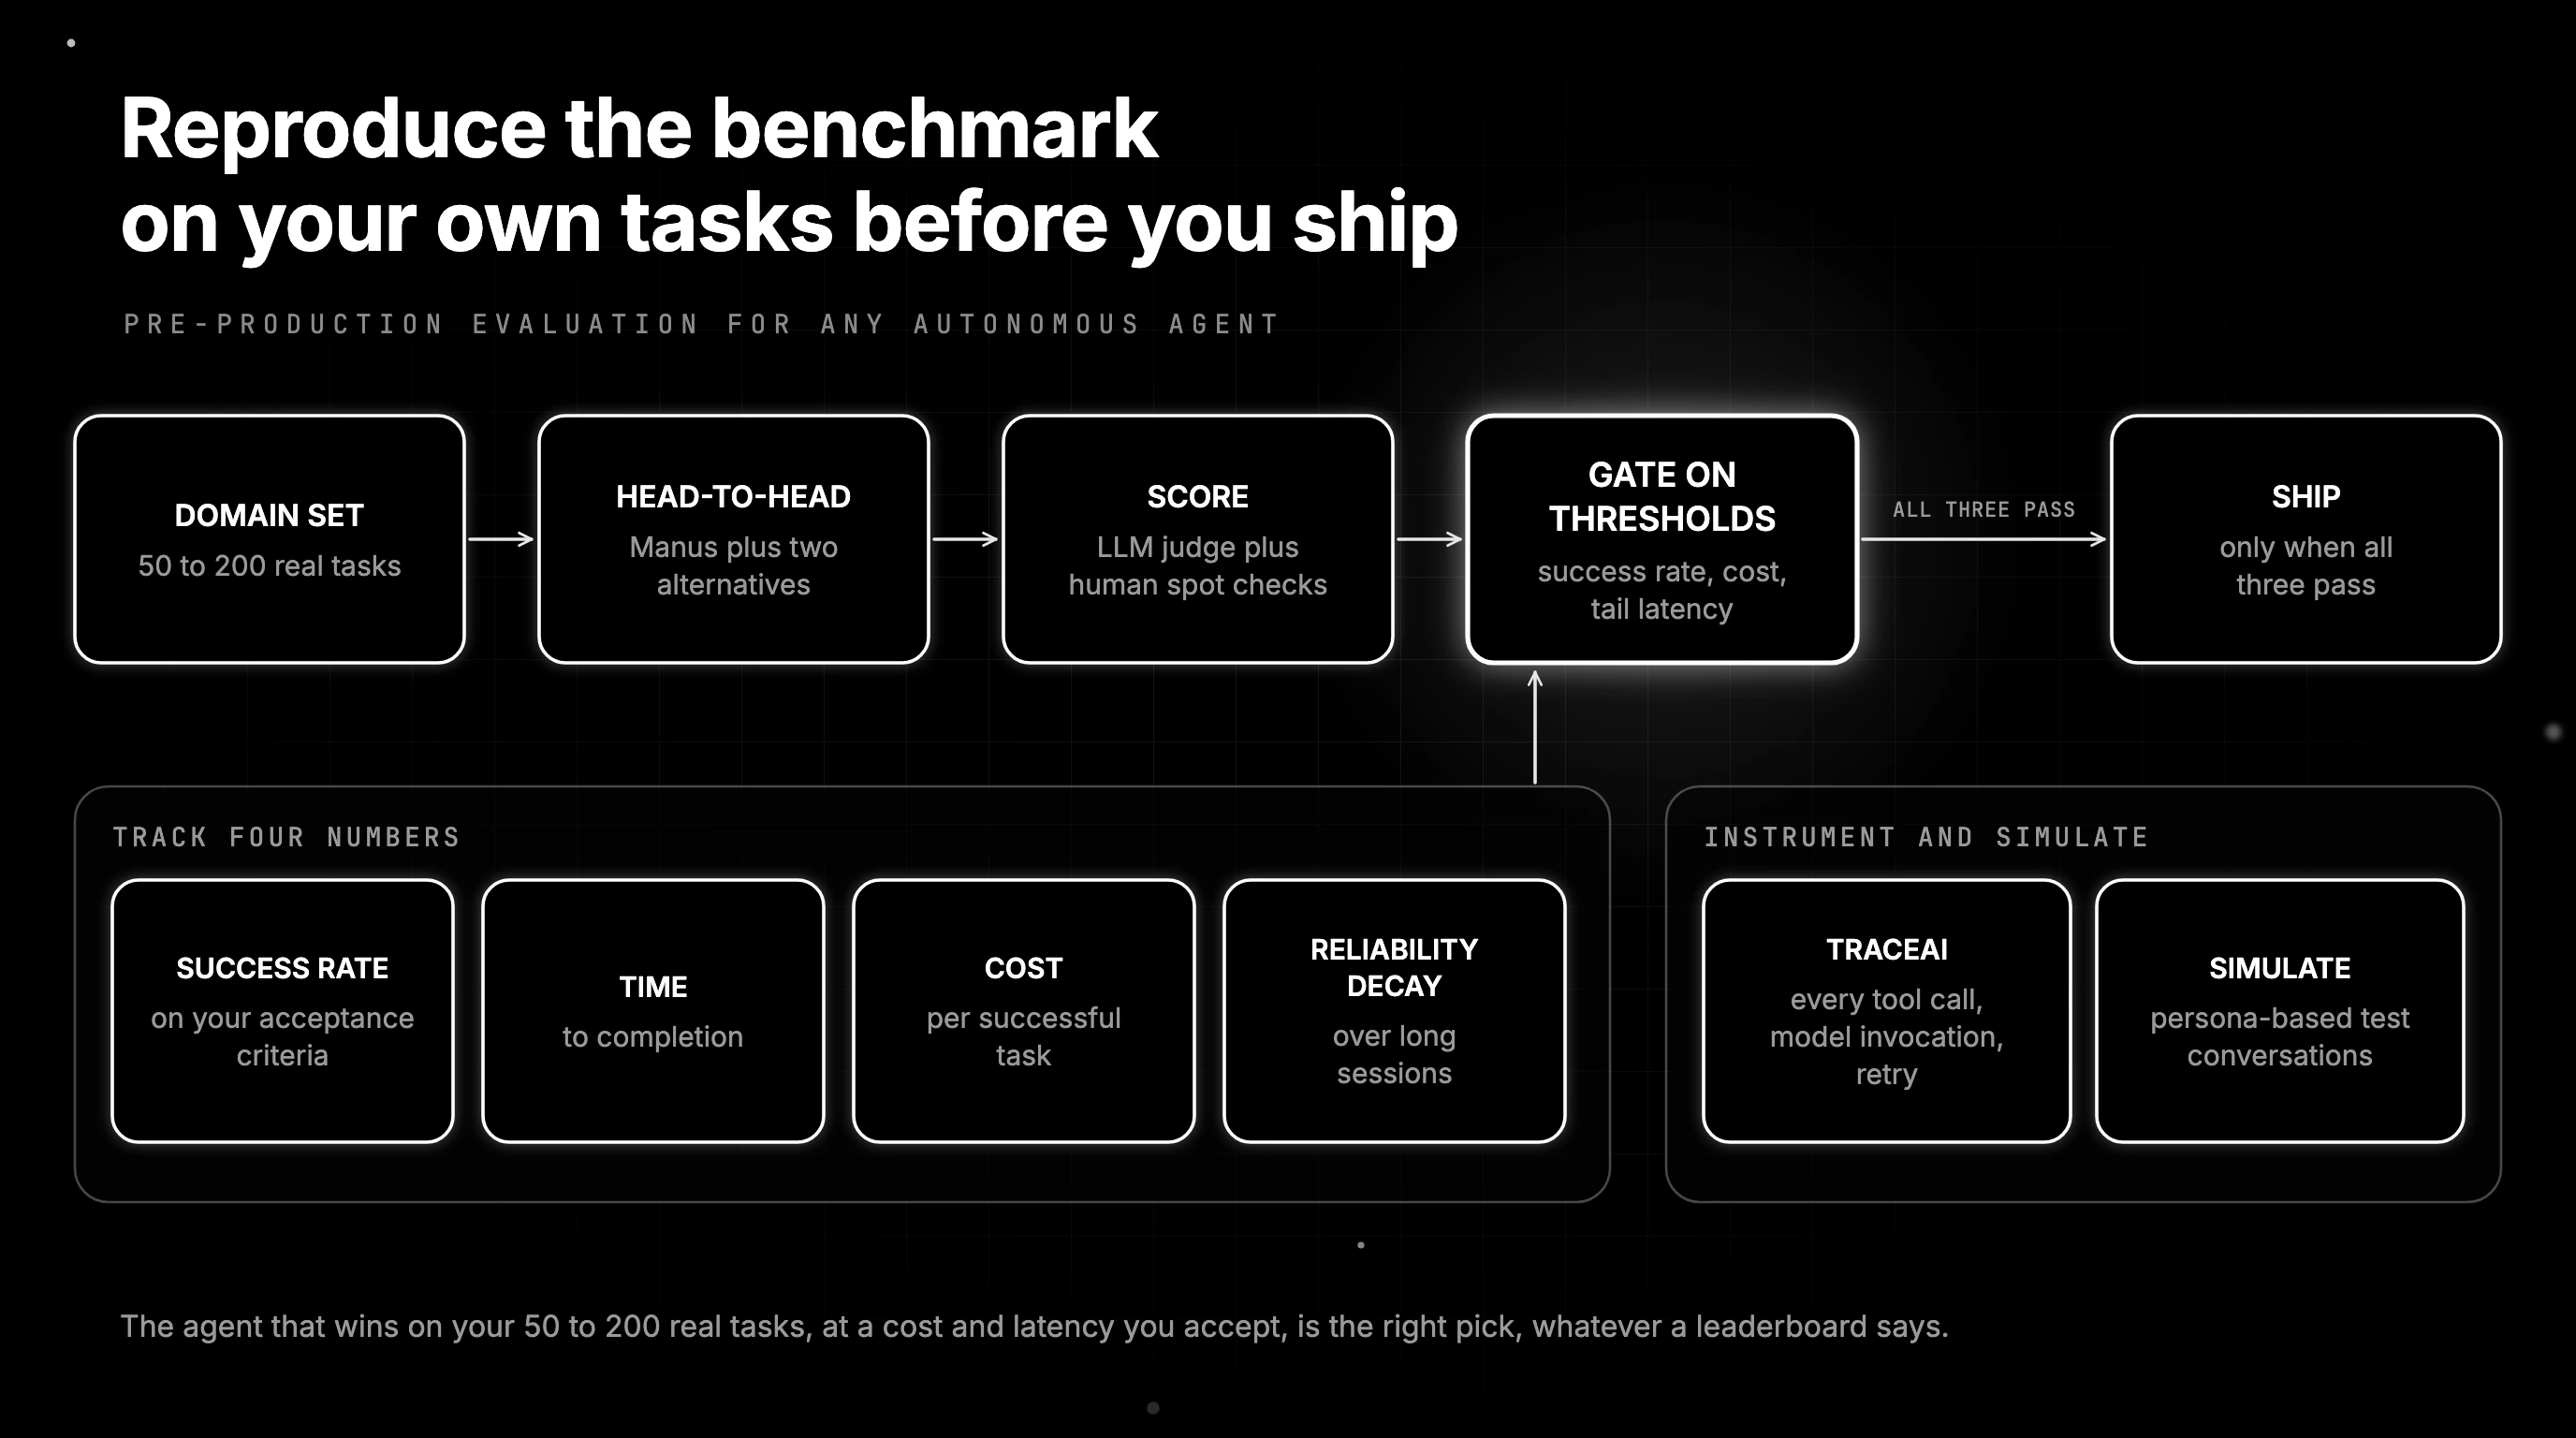
The right pre-production checklist:
- Build a 50 to 200 prompt domain set. Real tasks from your real workload, not synthetic benchmarks.
- Run head-to-head. Send the same prompts through Manus and two alternatives. Score with an LLM judge plus human spot checks for any safety-critical category.
- Track four numbers. Success rate on your acceptance criteria, time to completion, cost per successful task, and reliability decay over long sessions (success rate as a function of session length).
- Instrument with traceAI. Get span-level visibility into every tool call, model invocation, and retry. traceAI is Apache-2.0, built on OpenTelemetry, and instruments AI apps in 5 languages: Python, TypeScript, Java, Go, and C#.
- Simulate before production. Use Future AGI Simulate to run persona-based test conversations and score each one with evals.
- Gate production on eval thresholds, not vendor scores. Set a minimum success rate, a maximum cost, and a maximum tail latency. Ship only when all three pass on your domain set. The CI/CD eval pipeline cookbook fails the build when a case misses its threshold.
# Domain-reproduction scaffold for autonomous-agent evaluation.
# Uses the real Future AGI eval API surface plus a stand-in agent runner.
# Swap the `run_agent` body for your real Manus / Devin / Cursor API call
# before sending production traffic.
# pip install agent-learning-kit; LiteLLM reads your model provider key.

from fi.opt.base import Evaluator
from fi.evals.metrics import CustomLLMJudge
from fi.evals.llm import LiteLLMProvider

# Your domain prompts: real tasks from your real workload.
prompts = [
    {"task": "Build a 1-pager market scan of voice-AI vendors with citations."},
    {"task": "Compare Q1 vs Q2 churn from the attached CSV and produce a chart."},
    {"task": "Scaffold a Next.js landing page from this brief."},
]

# Agents under test. Hit each one's API and collect (output, latency, cost).
def run_agent(name, task):
    # Stand-in: call your real Manus / Devin / Cursor API here.
    return {"output": "...", "latency_s": 0.0, "cost_usd": 0.0}

# LLM-as-a-judge configured with the FAGI metrics SDK.
provider = LiteLLMProvider()  # routes judge calls through your configured model.

agent_quality_config = {
    "name": "agent_quality_judge",
    "grading_criteria": (
        "Score 0-5 on: (1) task completion, (2) factual accuracy, "
        "(3) artifact quality, (4) cost efficiency."
    ),
}
agent_quality_judge = CustomLLMJudge(provider, config=agent_quality_config)
evaluator = Evaluator(metric=agent_quality_judge)

for prompt in prompts:
    for agent in ["manus", "devin", "cursor"]:
        run = run_agent(agent, prompt["task"])
        results = evaluator.evaluate([
            {"task": prompt["task"], "response": run["output"]}
        ])
        print(agent, prompt["task"][:40], results[0].score, run["latency_s"], run["cost_usd"])
The pattern above wires a CustomLLMJudge through the fi.opt.base.Evaluator wrapper from agent-learning-kit. Hosted Turing judges run through evaluate(), with turing_flash at about 1 to 2 seconds per call. Local metrics run with no API key, so you can score a first pass before you call a hosted judge.
Why autonomous agents need an evaluation and observability layer
Each vendor shows only its own runs. Comparing agents on your tasks takes one trace format, one set of evals, and one pass bar.
Run three layers for any production autonomous agent:
- Tracing. traceAI (Apache-2.0, OpenTelemetry) instruments Python, TypeScript, Java, Go, and C# agents. Span-level visibility into every tool call, model invocation, retry, and validation step.
- Evaluation. Future AGI evals score each response against your own definition of good, from built-in Task Completion to custom LLM-as-Judge evals, and a threshold turns the score into a CI/CD merge gate.
- Simulation. Future AGI Simulate runs your agent through test conversations built from a scenario and personas, and returns the transcript, metrics, and an eval score for each.
For a deeper walkthrough of the trace-evaluate-simulate-gate pattern, see the ADK production eval loop. The same pattern applies to Manus, Devin, Cursor, and any other autonomous agent.
How to access Manus AI
- Web. manus.im with public sign-up. Manus AI pricing is credit-based, with Free, Pro, and Team plans; see manus.im/pricing for current prices.
- API. The Manus API (v2) manages tasks, projects, and files over REST, with webhooks.
- Desktop and mobile. Manus has desktop and mobile apps, and in Manus 2.0 the desktop app became Manus Studio.
- OpenManus. MIT community port if you want self-host. Less mature, more flexible.
Who owns Manus AI after the Meta deal
Manus operates from Singapore. On December 29, 2025, Manus announced it was joining Meta and said it would keep selling subscriptions through its own app and website. In April 2026, China’s National Development and Reform Commission blocked the acquisition and required the parties to withdraw it.
Manus resumed independent operations on September 1, 2026, with its founding team still leading the company. On September 28, 2026, it shipped Manus 2.0, with the Cascade harness, Cloud Computer, Automations, and the Manus Studio desktop app.
Picking the right autonomous agent for your workload
Manus’s GAIA lead was a March 2025 snapshot, and the field has moved since. The agent that wins on your 50 to 200 real tasks, at a cost and latency you accept, is the right pick, whatever a leaderboard says.
Run those tasks through traceAI, score them with one set of evals, and gate the rollout on your own thresholds. Future AGI puts tracing, evals, and simulation on one platform, and its Apache-2.0 core is self-hostable.
Start evaluating your autonomous agent with Future AGI.
Related reading
- Best LLMs of May 2026: top picks across coding, agents, multimodal
- Best LLM evaluation tools in 2026
- Multi-agent systems patterns and pitfalls in 2026
- LLM agent architectures: core components and design patterns
- Production observability for multi-agent systems with traceAI
Sources
- Manus (manus.im)
- GAIA: a benchmark for general AI assistants (arXiv:2311.12983)
- Manus launch page with GAIA results (archived March 2025)
- OpenAI: Introducing deep research
- Trustworthy Benchmarks audit (UC Berkeley RDI, April 2026)
- Introducing Manus 2.0
- Manus Flex documentation
- Introducing Manus 1.5
- Introducing Manus 1.6
- Manus Sandbox
- Manus plans and pricing documentation
- Manus API documentation
- Manus joins Meta
- BBC: China blocks Meta’s acquisition of Manus
- Manus resumes independent operations
- OpenAI: Introducing ChatGPT agent
- Devin pricing
- Replit pricing
- Claude pricing
- Claude Code documentation
- OpenManus repository
- Microsoft Agent Framework repository
Frequently Asked Questions
How did Manus AI score on the GAIA benchmark?
Does Manus use Claude?
Who owns Manus AI?
How much does Manus AI cost?
Is Manus AI actually good?
Best AI coding agents 2026 by job-to-be-done. Cursor, Claude Code, Cline, Aider, GitHub Copilot, Replit Agent ranked by where the agent actually lives.

Multi-agentic AI in 2026: how LangGraph, CrewAI, OpenAI Agents SDK and Microsoft Agent Framework compare, plus orchestration patterns, A2A, evals and tracing.

Components of LLM agents in 2026: tokenizer, embeddings, and transformer blocks inside the model, plus memory, tools, planner, runtime, and tracing around it.
