Hard Prompt vs Soft Prompt in 2026: Differences, Code, and When to Use Each
Hard prompt vs soft prompt explained: what each is, how prompt tuning and prefix tuning train soft prompts, code for both, and when hosted APIs rule them out.
Table of Contents
TL;DR on Hard Prompts vs Soft Prompts
In any hard prompt vs soft prompt comparison, a hard prompt is the text you write and send to a model. A soft prompt is a short run of learned vectors, often called virtual tokens, that sits in front of a frozen model’s input embeddings and is trained by gradient descent. You can read, log and move a hard prompt between models, while a soft prompt is opaque and tied to one model checkpoint.
| Dimension | Hard Prompt | Soft Prompt |
|---|---|---|
| Representation | Natural-language text tokens | Continuous embedding vectors |
| Human-readable | Yes | No |
| Works with closed APIs (GPT-6, Claude, Gemini) | Yes | No |
| Training cost | Zero, just iteration | GPU hours per task |
| Inference cost | Tokens in the prompt | A few extra embedding vectors |
| Best at | General reasoning, prototypes, RAG, agents | Narrow tasks with labelled data |
| Common 2026 methods | Few-shot, CoT, structured prompts, DSPy, APE | Prompt tuning, prefix tuning, P-tuning v2 |
| Portability | Move freely across models | Tied to one base model checkpoint |
If you only have time for one move in 2026: ship hard prompts, evaluate them with a held-out test set and judge-based evaluators, and only reach for soft prompts when you self-host an open-source base and have labels. Hosted APIs accept only text, so you can leave soft prompts aside until you run your own open weights.
What Are Hard Prompts in 2026
A hard prompt is the text you send to a model. It is composed of regular tokens that the tokenizer recognizes and the model attends to, exactly the same as user input. In a 2026 production stack, hard prompts include:
- The system prompt that scopes the assistant’s role.
- Tool and function definitions in JSON or YAML.
- Retrieved chunks from a vector store, knowledge graph, or hybrid retriever.
- Few-shot demonstrations.
- The user’s actual request.
Hard prompts are the only prompt representation that closed APIs such as OpenAI’s gpt-6-astra, Anthropic’s claude-opus-5-5 and Google’s gemini-4-argon accept, so every prompt change you make on those models is a change to text. Optimizing them is a search problem over wording, structure, ordering of demonstrations, and few-shot example selection.
Hard prompt characteristics
- Token-level. Each part of the prompt costs tokens at inference time.
- Portable. A hard prompt that works on Claude often transfers with light edits to GPT-6 or Gemini.
- Inspectable. You can log the exact prompt that produced each response, which makes failure analysis tractable.
- Engineering surface. Few-shot selection, chain-of-thought scaffolding, role conditioning, and output schemas are all hard-prompt levers.
Modern hard-prompt patterns
- Structured prompting. XML, JSON, or Markdown sections to separate system rules, context, and user input.
- Few-shot retrieval. Pull demonstrations from a labelled pool by semantic similarity rather than hardcoding them.
- Chain-of-thought and reasoning. Reasoning models like GPT-6 Astra, with selectable reasoning effort, and Claude Opus 5.5, with adaptive thinking, have shifted CoT to be partially native.
- Prompt optimization. DSPy, APE, OPRO, and EvoPrompt search the hard-prompt space against an evaluator. Future AGI’s optimization runs take a prompt you already have and the evals that score it, then search for a version that scores higher.
What Are Soft Prompts in 2026
A soft prompt is a sequence of continuous vectors prepended to the model’s input embeddings. These vectors do not correspond to any token. They live in the same dimensional space as token embeddings and are trained by backpropagation against a downstream task loss while the base model weights stay frozen.
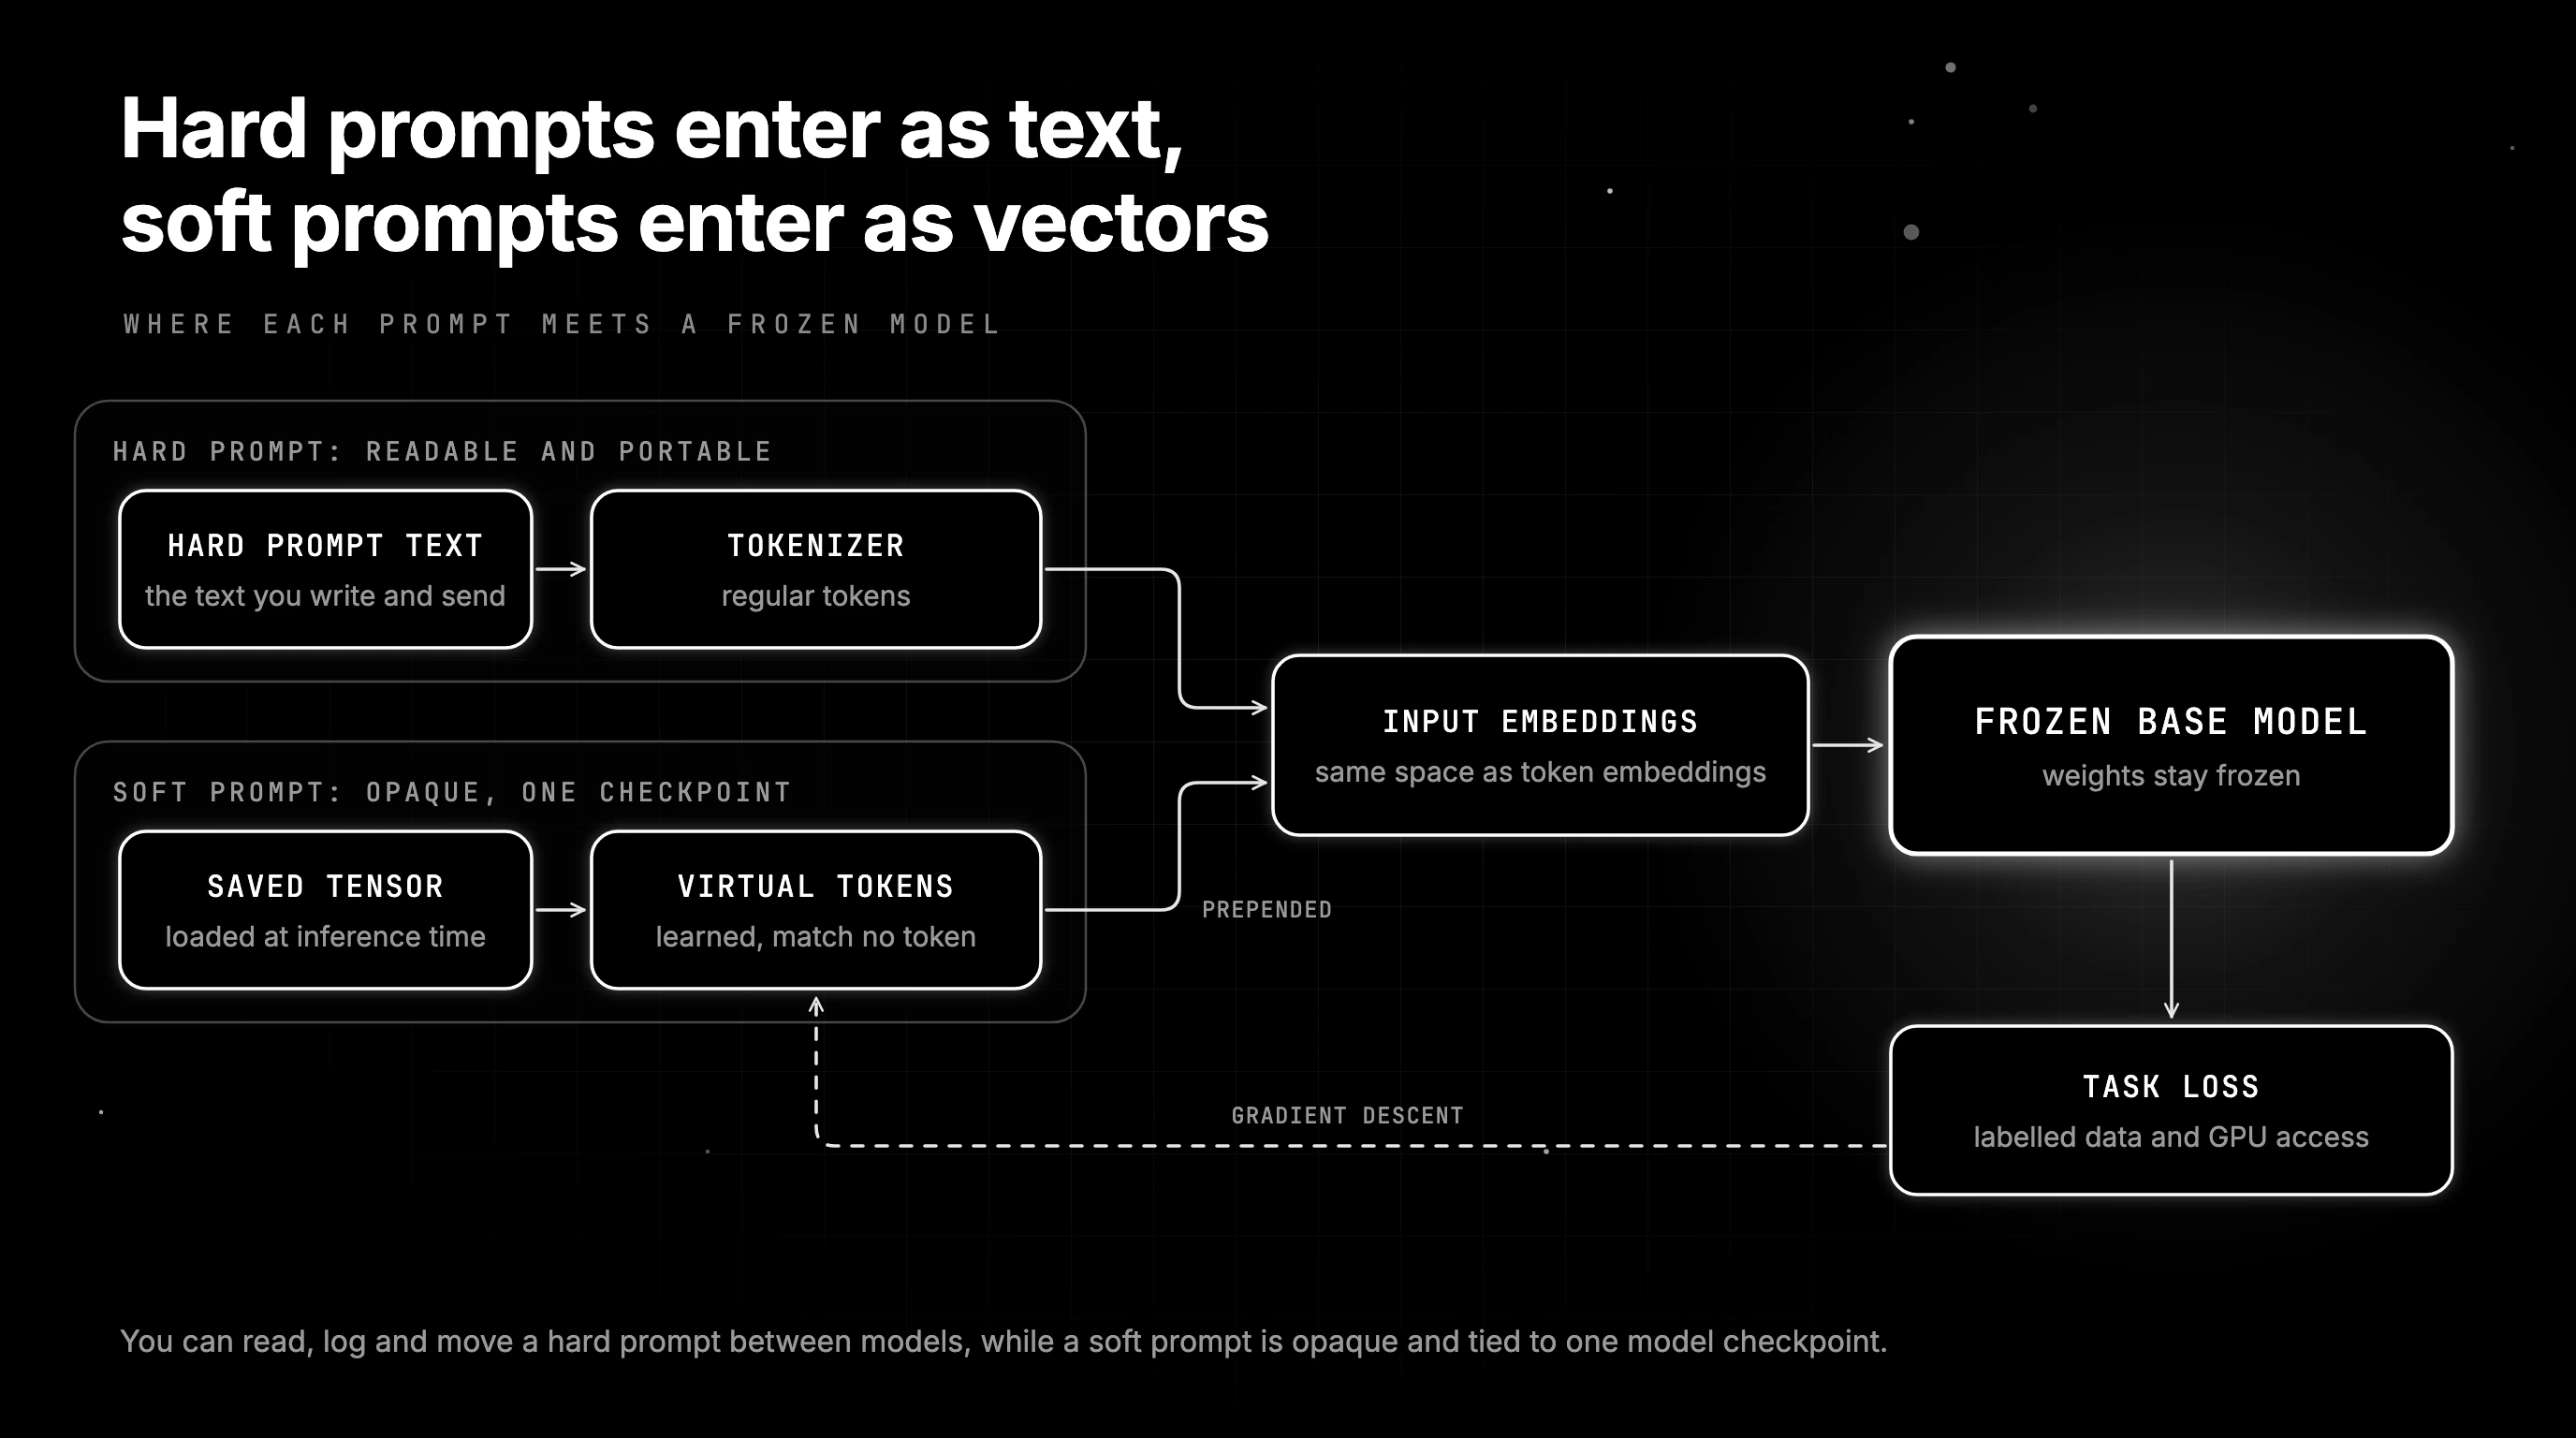
You cannot type a soft prompt; you train one on a small dataset, save it as a tensor, and load it at inference time. Closed APIs do not accept soft prompts, so soft prompting is exclusively an open-weights technique used on self-hosted models like Llama 4, Qwen 3.8, Mistral, and Gemma 4. Our prompt tuning guide covers the training mechanics in more depth.
The soft-prompt family of methods
- Prompt tuning (Lester et al., 2021). Learn a small set of embedding vectors prepended only at the input layer. Strong on large bases, weaker on smaller models.
- Prefix tuning (Li and Liang, 2021). Learn key and value prefixes at every transformer layer, giving the model deeper conditioning. More expressive than prompt tuning at the cost of more trainable parameters.
- P-tuning (Liu et al., 2021) and P-tuning v2. Adds a small encoder over learned embeddings. P-tuning v2 effectively brings prefix tuning to mid-size models and matches fine-tuning on many NLU tasks.
- LoRA and adapters as adjacent techniques. Not soft prompts, but parameter-efficient. LoRA modifies attention weight projections via low-rank updates. People sometimes describe combined LoRA plus prefix-tuning recipes as “LoRA for prompts.”
Soft prompt characteristics
- No text-token cost. A 20-vector soft prompt adds 20 virtual positions to attention rather than 20 visible billable tokens, though attention compute still scales with those extra positions.
- Model-specific. A soft prompt trained on Llama 4 Scout does not transfer to Qwen 3.8.
- Requires gradients. You need labelled data and GPU access to train.
- Opaque. You cannot read what a soft prompt encodes, only test its effect on evals.
What the research says about soft prompt length and serving
Lester et al. trained soft prompts on frozen T5 checkpoints of every size from Small to XXL. Longer prompts helped only up to a point: across all model sizes, going beyond 20 tokens gave only marginal gains, and the XXL model still did well with a single-token prompt.
The serving math is the bigger win. A tuned copy of T5-XXL needs 11 billion parameters for each task, while a 5-token soft prompt needs 20,480, so one frozen model can serve many tasks by swapping soft prompts, including mixed-task inference on the original model.
Hard Prompt vs Soft Prompt Side by Side
| Property | Hard Prompt | Soft Prompt |
|---|---|---|
| Lives at | Token layer | Embedding layer |
| Created by | Humans, or hard-prompt optimizers like DSPy / APE / OPRO | Gradient descent on a labelled task |
| Needs GPUs | No, only the inference API | Yes, for training |
| Needs labels | Optional, helpful for evals | Required, typically 1,000 to 100,000 examples |
| Works on hosted frontier APIs | Yes | No |
| Cost at inference | Token cost of the prompt | Tiny, a few extra vectors |
| Storage size | A string | A few hundred KB to a few MB tensor |
| Debuggability | High, exact text is logged | Low, only via behaviour |
| Best use cases | Agents, RAG, prototypes, broad tasks | Narrow classification, structured extraction, domain-specific style |
When to Use Hard Prompts in 2026
Choose hard prompts when any of the following is true:
- You are calling a hosted model (GPT-6 Astra, Claude Opus 5.5, Gemini 4 Argon, Mistral Large via API, etc.).
- The task is broad or open-ended, like an agent, multi-turn assistant, or RAG product.
- You need cross-model portability for procurement or fallback reasons.
- You need to log, audit, and reproduce the exact instruction.
- You have less than a few hundred labels but high developer iteration speed.
A 2026 production checklist for hard prompts:
- Pin production to an exact model ID and watch the provider’s deprecation page (OpenAI shuts down gpt-5-2025-08-07 on December 11, 2026), with a canary on the replacement before you switch.
- Define a small but representative held-out eval set.
- Run a hard-prompt optimizer or manual search to find a strong baseline.
- Track regressions with replay and online evals before promoting.
- Use online evaluators at the gateway to catch model-side drift.
When to Use Soft Prompts in 2026
Reach for soft prompts when all of the following hold:
- You self-host an open-source base model (Llama 4, Qwen 3.8, Mistral, Gemma 4).
- The task is narrow and well-specified, like single-label classification, schema extraction, code intent labeling, or domain-specific style transfer.
- You have a labelled dataset of roughly 1,000 to 100,000 examples.
- Per-request latency and token cost matter enough to want a near-zero prompt overhead.
- You can train and version embedding tensors alongside your model.
If you only have a few hundred labels, prefer few-shot hard prompts plus retrieval. If you have hundreds of thousands of labels, consider full or LoRA fine-tuning instead of pure soft prompting. Base size matters too, since Lester et al. found that prompt tuning only matched full model tuning once T5 passed billions of parameters.
Hybrid Pattern With a Hard Prompt Shell and Soft Prompt Adapter
A hybrid pattern on open-weights bases:
- A short hard prompt scopes the task and provides the output schema.
- A trained soft prompt or LoRA adapter conditions the model on domain-specific style and entities.
- An evaluator scores faithfulness and structure on each response.
This combines the auditability of hard prompts with the parameter efficiency of soft prompting. It suits teams that self-host an open-weights base for data residency reasons, keep the hard prompt for scope and schema, and still have a task narrow enough to benefit from a learned prompt.
Hard-Prompt Evaluation Loop Code with Future AGI
# pip install agent-learning-kit
from fi.evals import evaluate

def call_model(system: str, user: str) -> str:
    """Replace with your LLM client (OpenAI, Anthropic, LiteLLM, etc.)."""
    raise NotImplementedError

system_prompt = "You are a clinical-summary assistant. Output JSON with keys: chief_complaint, history, plan."
user = "Summarize: patient presents with cough, fever, and shortness of breath for 3 days..."
output = call_model(system_prompt, user)

score = evaluate(
    "faithfulness",
    output=output,
    context=user,
)
print(score)
For a custom LLM-judge against a soft-prompt-conditioned open-source model:
from fi.evals import evaluate

judge = evaluate(
    prompt="Rate clinical-summary correctness from 0 to 1.",
    output=output,
    query=user,
    engine="llm",
    model="openai/gpt-6-astra",
)
print(judge.score, judge.reason)
Soft Prompt Example With PEFT Training Code
A minimal prompt-tuning recipe on an open-source base (Qwen3-8B, Apache-2.0), adapted from the Hugging Face PEFT prompt-tuning docs:
from peft import PromptTuningConfig, PromptTuningInit, get_peft_model, TaskType
from transformers import AutoModelForCausalLM, AutoTokenizer

base = "Qwen/Qwen3-8B"
tokenizer = AutoTokenizer.from_pretrained(base)
model = AutoModelForCausalLM.from_pretrained(base)

config = PromptTuningConfig(
    task_type=TaskType.CAUSAL_LM,
    prompt_tuning_init=PromptTuningInit.TEXT,
    prompt_tuning_init_text="Classify the clinical note.",
    num_virtual_tokens=20,
    tokenizer_name_or_path=base,
)
peft_model = get_peft_model(model, config)
peft_model.print_trainable_parameters()
Train with standard Hugging Face Trainer or Accelerate, then save the adapter and load it at inference. Evaluate with the same Future AGI evaluators you use on the hard-prompt side, so the two approaches are scored on the same ruler.
Prompt Optimization in 2026
Modern hard-prompt optimization tooling that operates at the text level:
- DSPy. Compile prompts and few-shot demos against metrics, with structured signatures.
- APE. Automatic Prompt Engineer, sampler-based candidate generation and scoring.
- OPRO. Optimization by PROmpting, uses an LLM as the optimizer over the prompt space.
- EvoPrompt. Evolutionary search over prompt templates.
- Future AGI optimizers. agent-learning-kit ships six prompt optimizers, including ProTeGi, GEPA and PromptWizard, under
fi.opt, and each optimization run scores candidate prompts with the evals you choose.
All of these operate on hard prompts because that is what ships to hosted APIs. Soft prompt optimization remains a gradient-descent training problem rather than a search problem, and the trained prompt can still be scored with the same evals as any text prompt.
How to Choose With a Decision Tree
- Are you calling a hosted frontier API? If yes, hard prompts only.
- Do you self-host an open-source base and have a narrow task plus labels? Consider soft prompts (prompt tuning, prefix tuning, P-tuning v2) or LoRA.
- Do you have hundreds of thousands of high-quality labels and care about per-token cost? Full or LoRA fine-tuning often beats soft prompting.
- Do you need full audit logs of the instruction sent to the model? Hard prompts win, because soft prompts cannot be inspected.
- Do you need to ship a change today? Hard prompts plus an optimization loop is the lowest-latency path.
Ship the Hard Prompt Now and Earn the Soft Prompt Later
If you call a hosted model, a text prompt is the only kind of prompt the API accepts, so keep it readable, trace each call with traceAI, and score every change on a held-out eval set before it ships. A soft prompt earns its GPU time later, once you self-host an open-weights model, own a narrow labelled task, and can score it with the same evals as the text prompt it replaces.
Version your hard prompts in Future AGI and compare every version against the same eval set.
Related Reading
- LLM Prompts: Best Practices
- Best Prompt Engineering Tools 2026
- Prompt Optimization at Scale
- A/B Testing LLM Prompts
- LLM Fine-Tuning Guide
Sources
- Lester et al., The Power of Scale for Parameter-Efficient Prompt Tuning (2021)
- Li and Liang, Prefix-Tuning: Optimizing Continuous Prompts for Generation (2021)
- Liu et al., GPT Understands, Too (P-tuning, 2021)
- Liu et al., P-Tuning v2: Prompt Tuning Can Be Comparable to Fine-tuning Universally Across Scales and Tasks
- Hu et al., LoRA: Low-Rank Adaptation of Large Language Models (2021)
- Zhou et al., Large Language Models Are Human-Level Prompt Engineers (APE)
- Yang et al., Large Language Models as Optimizers (OPRO)
- EvoPrompt paper on evolutionary prompt optimization
- Hugging Face PEFT soft prompts conceptual guide
- Hugging Face PEFT prompt tuning reference
- Stanford DSPy repository
- OpenAI models documentation
- OpenAI deprecations
- Claude models overview
- Gemini API models
- Qwen3-8B model card
- Llama 4 Scout model card
- Qwen 3.8 model card
- Gemma 4 model card
- Mistral models documentation
- Hugging Face Trainer documentation
- Hugging Face Accelerate documentation
Frequently Asked Questions
What is a soft prompt?
What is the difference between a hard prompt and a soft prompt?
Is a soft prompt the same as prompt tuning?
When should I use a hard prompt vs a soft prompt?
What is soft prompt optimization?
How do soft prompts compare to LoRA?
Get the LLM prompt format that works on GPT-6, Claude Opus 5.5 and Gemini 4 Argon: instruction order, delimiters, output schemas, few-shot counts, an eval loop.

DSPy, FutureAGI Prompt Optimizer, PromptFoo, OpenAI Playground, Helicone Prompts, Braintrust Prompts, plus tradeoffs for 2026 prompt engineering workflows.

Manual prompt tuning fails past 50 variants. Compare Future AGI, Promptfoo, LangSmith, and Datadog for 2026 automated prompt optimization at scale.
