Fine-Tuning LLMs in 2026: LoRA, QLoRA, DPO, GRPO Compared
Compare LoRA vs QLoRA and DPO vs PPO vs GRPO, run a GRPO LoRA adapter in TRL, and check verified VRAM needs before you fine-tune an open-weight LLM in 2026.
Table of Contents
Which Fine-Tuning Method to Pick in 2026
Pick the method by the training signal you already hold. Input and output examples call for SFT with LoRA, or QLoRA when GPU memory is the limit; chosen and rejected pairs call for DPO; a programmatic checker calls for GRPO, which TRL runs on a LoRA adapter. OpenAI’s self-serve fine-tuning closed to new organizations on May 7, 2026, so open-weight models are the default path.
| Need | 2026 Recipe | Compute | Notes |
|---|---|---|---|
| Tone or style adaptation | LoRA SFT | 1x24GB GPU | Small curated set (LIMA used 1,000) |
| Domain adaptation on 70B model | QLoRA SFT | 1x80GB H100 | 4-bit NF4 base |
| Align to human preferences | DPO | Same as LoRA | Chosen and rejected pairs |
| Reasoning fine-tune with verifier | GRPO (LoRA adapter) | 1 GPU for small models, multi-GPU at scale | TRL default loss is DAPO |
| Safety-critical alignment | RLHF with PPO | Multi-GPU | Reward model required |
| Quick task adaptation, no weights | Prompt tuning | GPU, base stays frozen | Limited expressiveness |
| OpenAI model | OpenAI self-serve fine-tuning | Vendor-hosted | Closed to new organizations since May 7, 2026; active existing customers can create jobs until Jan 6, 2027 |
When you go to production, evaluate with a held-out set on task metrics plus LLM-as-judge on faithfulness, tool-call correctness, and instruction following. Future AGI’s agent-learning-kit and traceAI (both Apache-2.0) handle that evaluation and tracing: score the fine-tuned model and the base model on identical prompts and ship only when the delta is real.
Why Frontier LLMs Still Need Fine-Tuning in 2026
Frontier LLMs in 2026 are excellent at general instruction following. They still fail at three things that fine-tuning fixes: exact output schema, narrow domain vocabulary, and brand voice. A base model can describe a SOC 2 control in plausible English, but it will not consistently emit the JSON your downstream parser expects, will not use your internal product nicknames, and will drift away from your support team’s voice.
Fine-tuning also compresses capability. A smaller open-weight model trained on your task can take over work you would otherwise send to a larger API model, and you serve it on your own infra with RAG on top for fresh knowledge.
This guide covers the four methods that actually matter in 2026: LoRA, QLoRA, DPO, and GRPO. We also cover where full RLHF and prompt tuning still fit, how to estimate cost, and how to evaluate before shipping.
LoRA vs QLoRA for Parameter-Efficient Fine-Tuning
LoRA (Hu et al., 2021, arXiv:2106.09685) trains two low-rank matrices A and B such that the updated weight is W + BA, with A and B much smaller than W. The base W stays frozen. On GPT-3 175B, the LoRA paper cut trainable parameters by 10,000 times and GPU memory by 3 times compared with full fine-tuning.
QLoRA (Dettmers et al., 2023, arXiv:2305.14314) adds three memory savers: 4-bit NormalFloat (NF4) quantization of the frozen base, double quantization of the quantization constants, and paged optimizers. The paper fine-tuned a 65B model on a single 48GB GPU, and Unsloth lists 41 GB as the minimum for QLoRA on a 70B model. The base never leaves 4-bit during training; gradients flow through the dequantized weights.
Hugging Face TRL, Axolotl and Unsloth all support both methods, and Unsloth says its kernels train 2x faster with 70 percent less VRAM. Pick LoRA when batch size and throughput matter; pick QLoRA when GPU memory is the binding constraint.
A Minimal LoRA Recipe with Hugging Face TRL
from transformers import AutoModelForCausalLM, AutoTokenizer
from peft import LoraConfig
from trl import SFTConfig, SFTTrainer

from datasets import Dataset

base = "Qwen/Qwen3-8B"
tokenizer = AutoTokenizer.from_pretrained(base)
model = AutoModelForCausalLM.from_pretrained(base)

# Minimal placeholder dataset. Replace with your real Hugging Face Dataset.
train_dataset = Dataset.from_list([
    {"prompt": "Translate to French: hello", "completion": "bonjour"},
    {"prompt": "Translate to French: goodbye", "completion": "au revoir"},
])

peft_config = LoraConfig(
    r=16,
    lora_alpha=32,
    target_modules="all-linear",
    lora_dropout=0.05,
    bias="none",
    task_type="CAUSAL_LM",
)

training_args = SFTConfig(
    output_dir="./qwen3-lora",
    num_train_epochs=3,
    per_device_train_batch_size=4,
    gradient_accumulation_steps=4,
    learning_rate=2e-4,
    bf16=True,
)

trainer = SFTTrainer(
    model=model,
    args=training_args,
    train_dataset=train_dataset,
    peft_config=peft_config,
)
trainer.train()
Setting target_modules to all-linear in Hugging Face PEFT applies LoRA to every linear layer except the output layer, and LoRA Without Regret (Thinking Machines, 2025) found attention-only LoRA underperforms. Check your model’s module names before narrowing the set.
RLHF vs DPO vs PPO vs GRPO for Alignment
DPO vs PPO vs GRPO at a Glance
The fastest way to settle DPO vs GRPO is to ask which training signal you already have. PPO-based RLHF needs a learned reward model, DPO needs ranked pairs, and GRPO needs a function that can score a fresh answer during training.
| PPO (RLHF) | DPO | GRPO | |
|---|---|---|---|
| Training signal | Learned reward model | Chosen and rejected pairs | Reward function, verifier or reward model |
| Samples during training | Yes | No | Yes, a group per prompt |
| Value model | Yes | No | No, the group average is the baseline |
DPO for Preference Pairs
DPO (Rafailov et al., 2023, arXiv:2305.18290) reformulates RLHF as a single classification-style loss on pairs of chosen and rejected responses, with no reward model and no sampling during training. In 2026, DPO is the first thing you try after SFT. Hugging Face TRL ships a DPOTrainer, and Axolotl and Unsloth both list DPO support.
Use GRPO for Reasoning Fine-Tunes
GRPO comes from the DeepSeekMath paper (Shao et al., 2024), which introduced it as a PPO variant that cuts PPO’s memory use, and DeepSeek-R1 (arXiv:2501.12948) made it famous in January 2025. It is the right method when you have a verifier rather than a preference labeler, a setup the Tulu 3 paper named Reinforcement Learning with Verifiable Rewards (RLVR).
The model emits a group of N rollouts per prompt; each rollout is scored by the verifier (correctness for math, pass/fail for unit tests, valid JSON for tool calls); rewards are normalized within the group; the policy is updated to favor above-mean rollouts. There is no value model; the group itself is the baseline.
TRL ships a GRPOTrainer, and Unsloth and Axolotl both list GRPO support. In TRL 1.16.0 the default loss_type is dapo, the length-bias fix from the DAPO paper, while dr_grpo and the original grpo remain options, and beta defaults to 0.0, so no reference model is loaded.
GRPO with LoRA in TRL
TRL’s GRPOTrainer takes a peft_config, so the LoRA setup from the SFT recipe carries over to reinforcement learning, and a quantization_config makes it QLoRA. The reward function below returns 1.0 for valid JSON and 0.0 otherwise.
import json
from datasets import Dataset
from peft import LoraConfig
from trl import GRPOConfig, GRPOTrainer

def valid_json(completions, **kwargs):
    rewards = []
    for completion in completions:
        try:
            json.loads(completion)
            rewards.append(1.0)
        except json.JSONDecodeError:
            rewards.append(0.0)
    return rewards

train_dataset = Dataset.from_list([
    {"prompt": "Return order 1042 as JSON with keys id and status."},
])

trainer = GRPOTrainer(
    model="Qwen/Qwen3-8B",
    reward_funcs=valid_json,
    args=GRPOConfig(output_dir="./qwen3-grpo-lora", learning_rate=1e-5),
    train_dataset=train_dataset,
    peft_config=LoraConfig(r=1, lora_alpha=32, target_modules="all-linear", task_type="CAUSAL_LM"),
)
trainer.train()
The rank and learning rate follow LoRA Without Regret: in reinforcement learning, LoRA matched full fine-tuning at ranks as low as 1, and the best LoRA learning rate was about 10 times the full fine-tuning rate. TRL’s reproduction of that result used rank 1 and alpha 32 at 1e-5, against 1e-6 for full fine-tuning, which is also the GRPOConfig default.
Keep PPO RLHF for Safety-Critical Alignment
Full RLHF with PPO (Schulman et al., 2017, arXiv:1707.06347) still has a place: when you need a learned reward model that captures multi-dimensional human preferences, when you want online exploration during training, or when your safety team requires reward shaping for refusal behavior. The cost is operational: you need to train and maintain the reward model, and PPO needs more hyperparameter tuning than DPO.
When to Fine-Tune vs RAG vs Prompt
The fine-tune versus RAG decision comes before any training run. The 2026 decision tree:
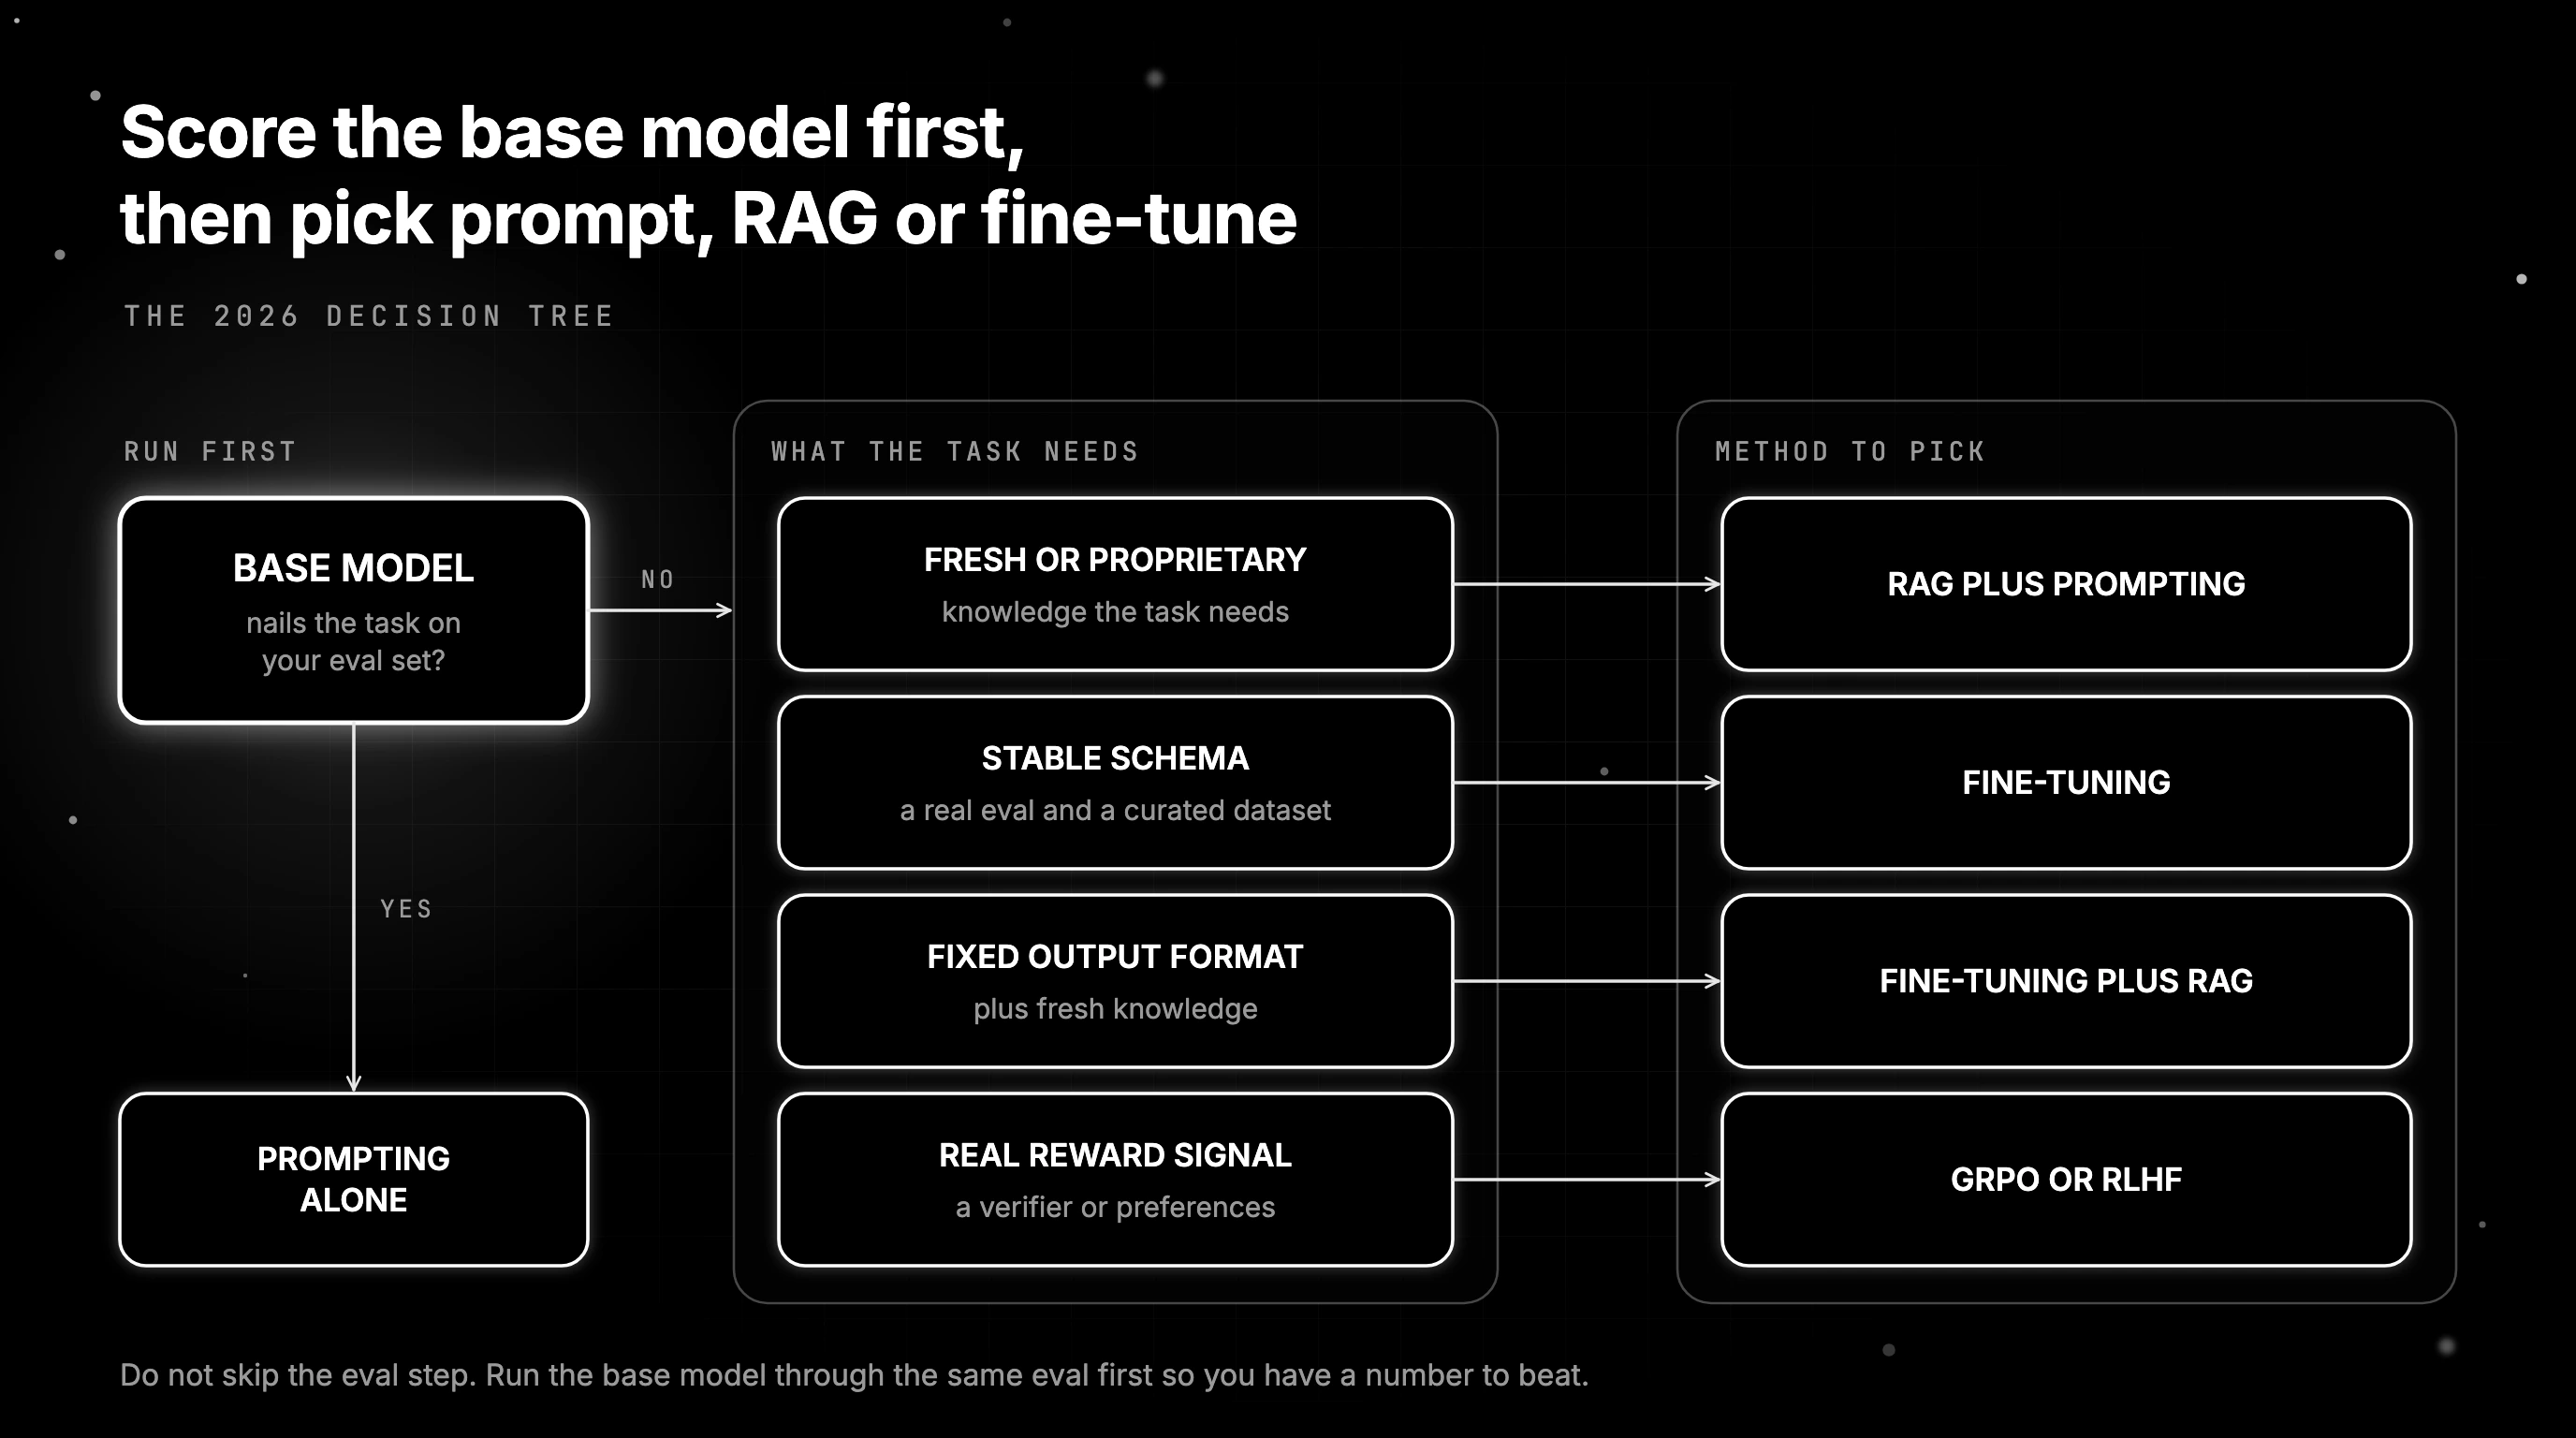
- Prompting alone if the base model already nails the task on your eval set.
- RAG plus prompting if the task needs fresh or proprietary knowledge.
- Fine-tuning if you have a stable schema, a real eval, and a curated in-distribution dataset.
- Fine-tuning plus RAG when a domain agent needs a fixed output format and fresh knowledge.
- GRPO or RLHF only if you have a real reward signal (verifier or preferences).
Do not skip the eval step. Fine-tuning a model with no held-out task metric is how teams ship regressions and only discover them in production. Run the base model through the same eval first so you have a number to beat.
Cost and Compute Budget
Memory sets the first budget line. Unsloth lists minimum VRAM of 6 GB for QLoRA and 22 GB for 16-bit LoRA on an 8B model, and 41 GB for QLoRA against 164 GB for 16-bit LoRA on a 70B model. That gap is why a 70B-class QLoRA run fits one 80GB H100 while 16-bit LoRA needs more than one 80GB GPU.
Cost is dominated by sequence length, batch size, and hardware at fixed base size. Rent the smallest box that fits, profile one epoch, then decide. Vendor rates change month to month; verify on your provider before budgeting.
Evaluating a Fine-Tuned Model Before Shipping
Three layers:
- Task metrics: exact match, BLEU, ROUGE, tool-call accuracy, JSON schema validity, latency, cost per call. Hard floors.
- LLM-as-judge on the qualitative axes you tuned for: faithfulness, instruction following, tone, brand voice.
- Regression check on a held-out general capability set (MMLU subset, your prior production prompts). Make sure you did not catastrophically forget.
Compare against the base model on identical prompts, and keep hardware and decoding settings fixed so the adapter is the only variable. If the delta is not meaningful on your eval, the fine-tune is not worth shipping. The evaluating fine-tuned LLMs playbook walks the full before-and-after harness.
Future AGI’s agent-learning-kit (Apache-2.0, pip install agent-learning-kit) scores this comparison. The pattern below runs locally with no API calls, and installing agent-learning-kit[nli] adds NLI-based faithfulness scoring. Swap in the base and fine-tuned responses to the same prompt, with the same context, and compare the two scores.
from fi.evals import evaluate

base_output = "Order 1042 shipped on May 3."         # response from the base open-weight model
ft_output = "Order 1042 shipped on May 2."           # response from your QLoRA fine-tune
context = "Order 1042 shipped on May 2 via UPS."     # source documents or task spec

base_score = evaluate("faithfulness", output=base_output, context=context)
ft_score = evaluate("faithfulness", output=ft_output, context=context)
print(base_score.score, ft_score.score)  # 0.0 1.0
For agent and tool-call traces, traceAI (Apache-2.0) records OpenTelemetry spans for the base and the fine-tuned model. Send both the same prompts and compare their spans side by side.
Where Future AGI Fits in a Fine-Tuning Stack
Future AGI is the evaluation and observability layer around a fine-tuning run. It tells you whether the fine-tune beat the base model and catches regressions once it serves traffic:
- agent-learning-kit (Apache-2.0): evaluators that run locally, such as faithfulness, ROUGE, BLEU and function-call accuracy, plus LLM-as-judge metrics and custom judges via
CustomLLMJudgeandLiteLLMProvider. On the Future AGI platform, custom evals score the dimensions you tuned for. - traceAI (Apache-2.0): OpenTelemetry instrumentation for vLLM, Hugging Face, OpenAI, Anthropic, LangChain and LlamaIndex, so base and fine-tuned model calls each leave spans with inputs, outputs, latency and token counts.
- Agent Command Center: an OpenAI-compatible gateway that routes to self-hosted models such as a vLLM server. Its shadow experiments mirror a sample of production requests to a second model, such as your fine-tune, and record its response, latency and token count without changing what users see.
For the broader fine-tuning workflow, see our LLM Fine-Tuning Guide, the deeper Continued LLM Pretraining post, and Synthetic Data for Fine-Tuning LLMs for dataset construction. Each covers a step around this one, from domain pretraining to building the training set.
Ship the Fine-Tune That Beats the Base Model
Fine-tuning exists for the model that keeps drifting from your JSON schema, your product vocabulary and your support team’s voice. The fine-tune ships when it beats the base model on the same prompts and holds that lead on mirrored production traffic.
Score your base model and your fine-tune on the same prompts: start free on Future AGI.
Sources
Frequently Asked Questions
What is the difference between DPO, PPO, and GRPO?
What learning rate and rank should I use for GRPO with LoRA?
What is the difference between LoRA and QLoRA?
Is OpenAI fine-tuning deprecated?
Can you run GRPO fine-tuning with Unsloth?
When should you use SFT vs DPO?
Fine-tune LLMs in 2026 with LoRA, QLoRA, GRPO, RLHF, DPO, IPO. Compare trl, unsloth, axolotl, DeepSpeed and learn how to evaluate fine-tuned models.

Generate synthetic data to fine-tune LLMs in 2026. Self-Instruct, Constitutional AI, DPO/IPO traces, function calling, and evaluating dataset quality.

Continued LLM pretraining in 2026: Megatron-LM, DeepSpeed, Axolotl, NeMo, Unsloth. Domain adaptation, catastrophic forgetting, evaluation with Future AGI.