F1 Score in 2026: Formula, Macro vs Micro vs Weighted, When to Use It, and Working Sklearn Code
Macro F1 score, the F1 formula and micro vs weighted averages explained with worked examples, a good-F1 baseline, F-beta, and runnable scikit-learn code.
Table of Contents
F1 score at a glance
The F1 score is the harmonic mean of precision and recall, 2 * P * R / (P + R), and it runs from 0 to 1. The macro F1 score averages F1 across classes so a rare class counts as much as a common one. The table gives every variant at a glance.
| What | Formula | Use it when |
|---|---|---|
| Precision | TP / (TP + FP) | Cost of false positive is high |
| Recall | TP / (TP + FN) | Cost of false negative is high |
| F1 Score | 2 * (Precision * Recall) / (Precision + Recall) | Both costs matter and classes are imbalanced |
| F-beta | (1 + beta^2) * P * R / (beta^2 * P + R) | You need to weight precision vs recall |
| Macro F1 | Mean of per-class F1 | Every class matters equally |
| Micro F1 | F1 on pooled TP, FP, FN | Overall correctness; equals accuracy on multi-class single-label |
| Weighted F1 | Per-class F1 weighted by class frequency | Larger classes should count more |
F1 is one metric in a broader confusion-matrix toolbox. Use it for imbalanced classification and report it next to precision, recall, the confusion matrix, and where probabilities matter, AUC-ROC or AUC-PR. Pick the variant from the last column, then use the sections below for the math and the code.
Why F1 still matters in 2026
The F1 score comes out of information retrieval research. The math hasn’t changed; the surrounding stack has. In 2026, classification problems show up in three contexts that all need a balanced precision-recall metric:
- LLM-as-classifier. Prompt an LLM to label intents, route tickets, gate content, or score retrieval relevance. Score with F1 against a labeled test set.
- Imbalanced-by-default. Fraud, abuse, safety incidents, customer churn, RAG retrieval relevance. All commonly imbalanced. Accuracy can be misleading; F1 is more informative when both error types matter.
- Calibrated thresholds. Many production classifiers benefit from calibration methods such as Platt scaling or isotonic regression before thresholding. F1 at the calibrated threshold is the production-realistic number.
Confusion matrix building blocks
Every classification metric reduces to four counts, and precision and recall are ratios of them.
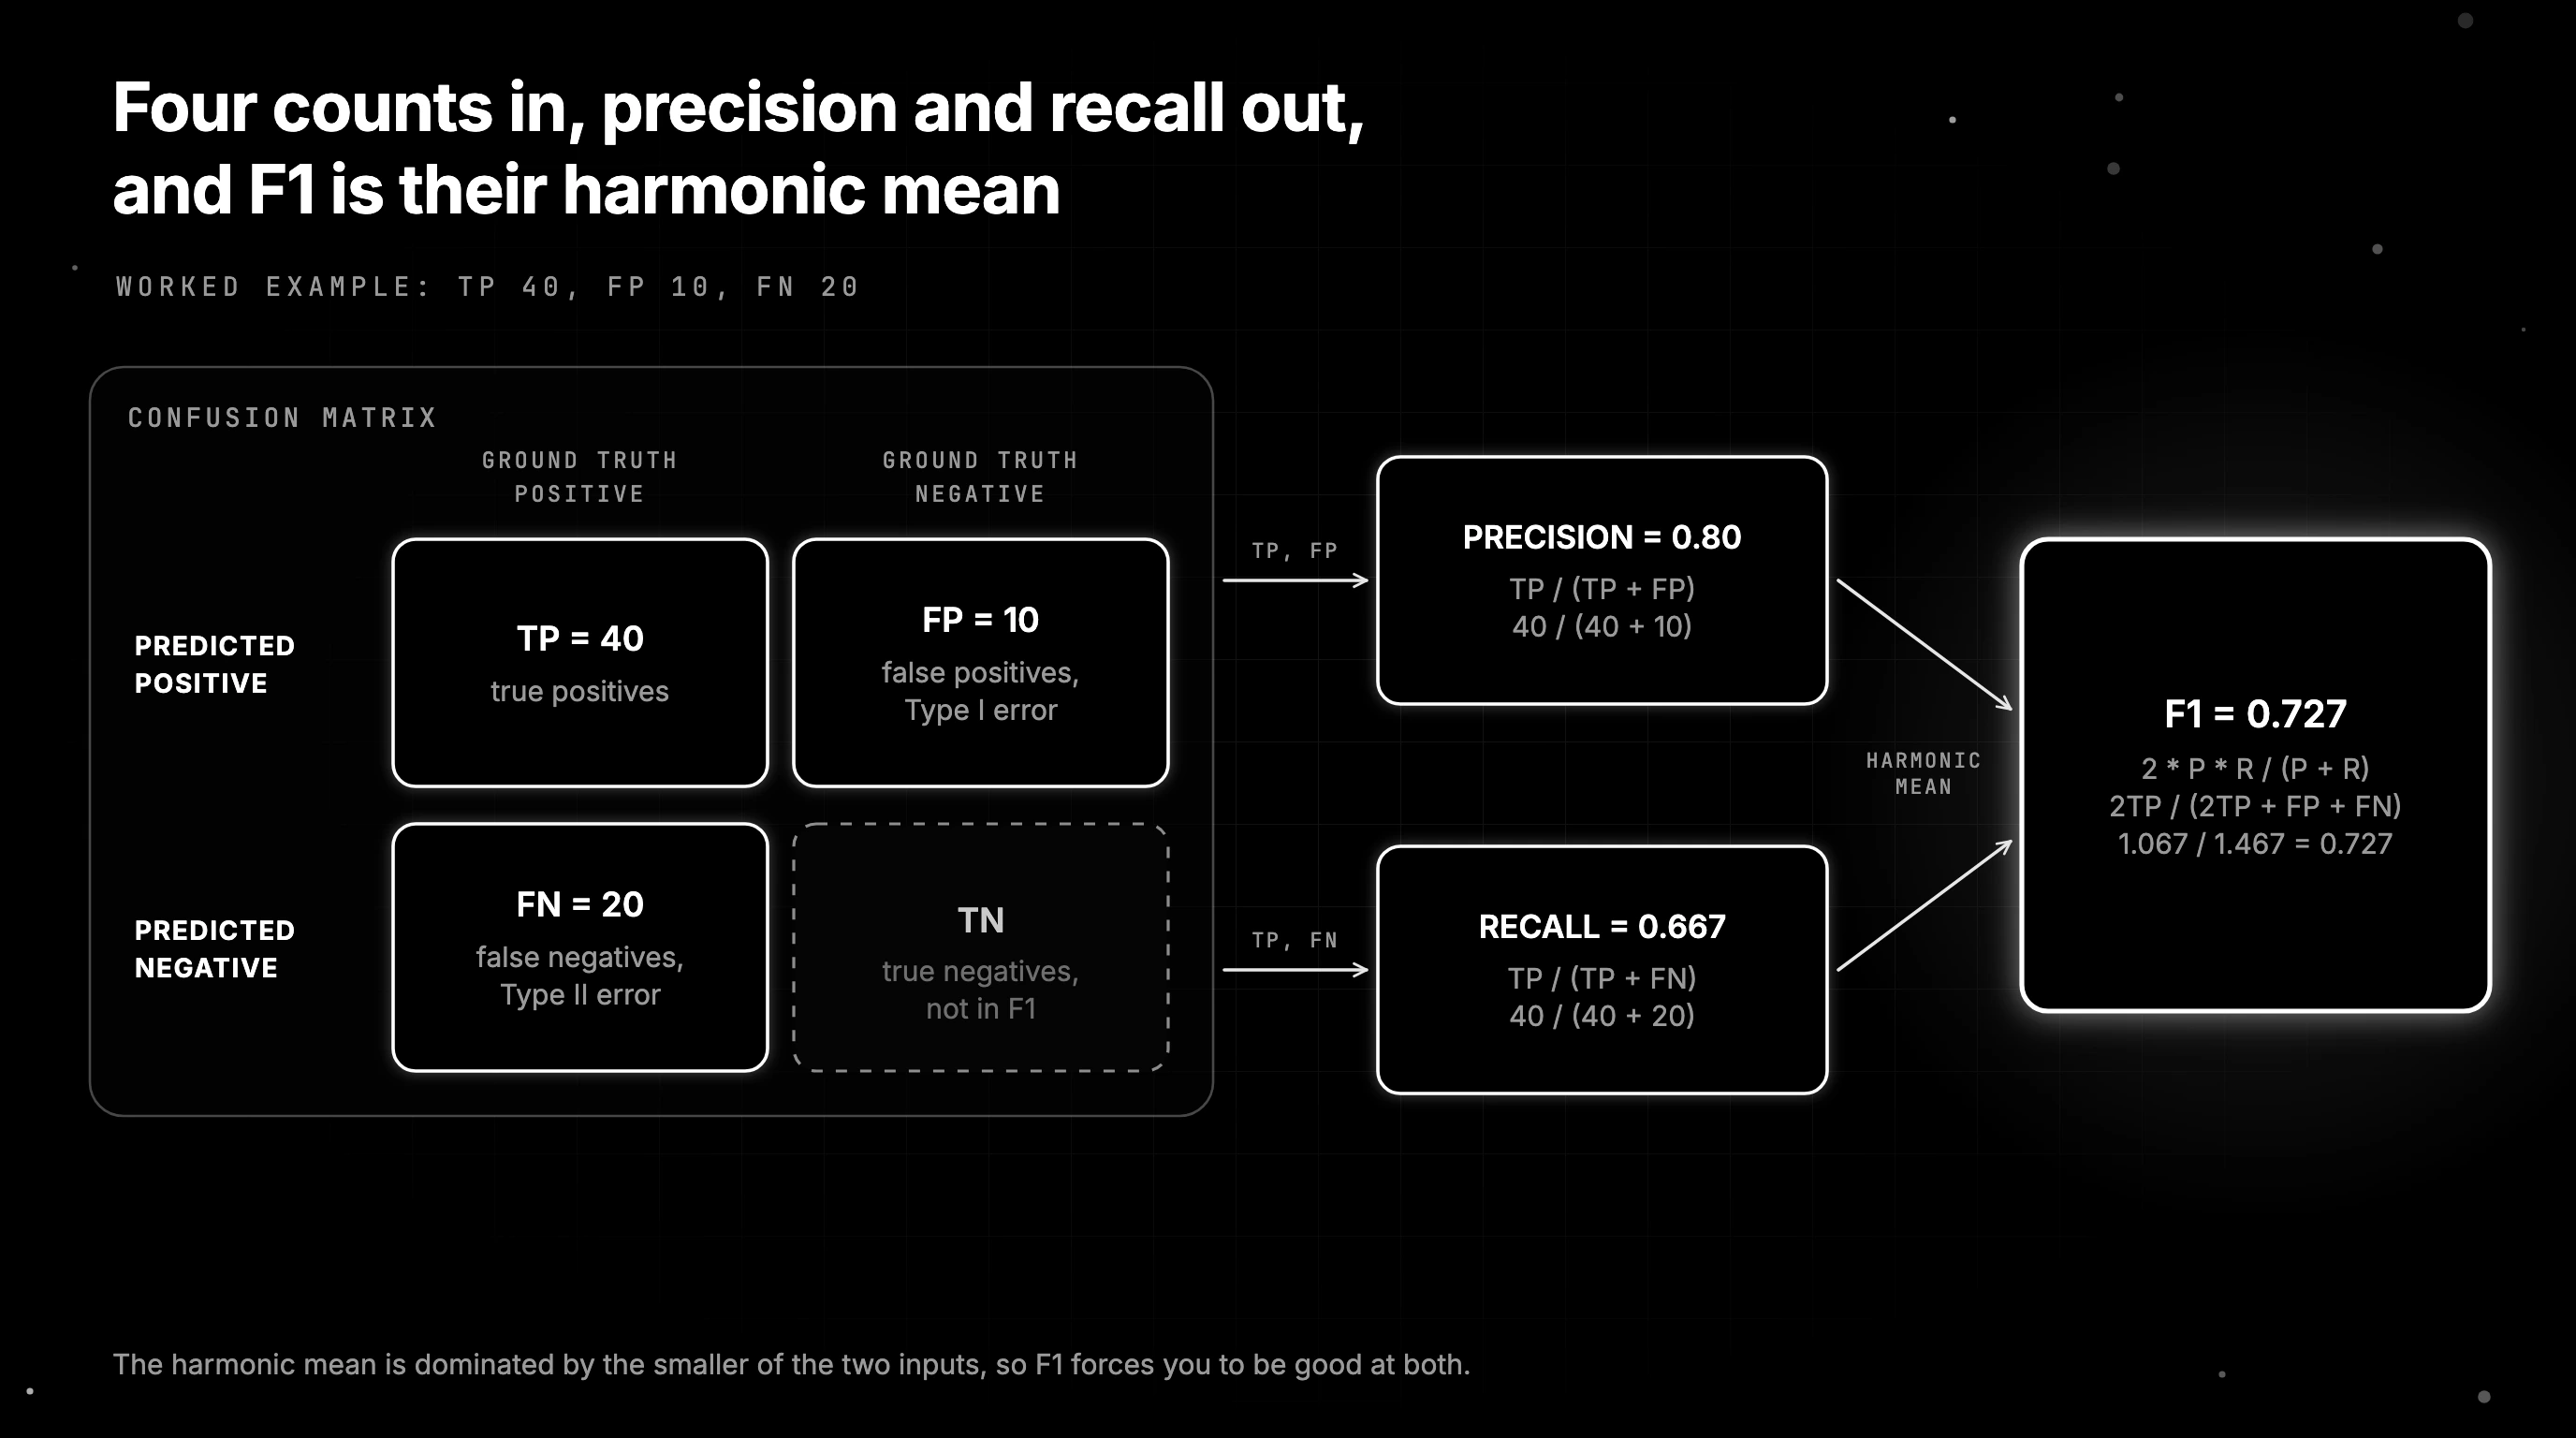
- True Positives (TP): model predicted positive, ground truth is positive.
- False Positives (FP): model predicted positive, ground truth is negative. Type I error.
- False Negatives (FN): model predicted negative, ground truth is positive. Type II error.
- True Negatives (TN): model predicted negative, ground truth is negative.
Precision
Precision = TP / (TP + FP)
Precision answers: of everything you flagged positive, what fraction was correct. High precision means few false alarms. Spam filtering, content moderation, and any user-facing classification where wrong flags cause real friction prioritize precision. A model that flags only the one case it is surest about, and gets it right, scores a perfect 1.0 precision.
Recall
Recall = TP / (TP + FN)
Recall (also called sensitivity or true positive rate) answers: of all the actual positives, what fraction did you catch. High recall means few misses. Disease screening, fraud detection, and any safety-critical pipeline prioritize recall. A model that flags every example as positive scores a perfect 1.0 recall, which is why recall alone is never enough.
Accuracy
Accuracy = (TP + TN) / (TP + TN + FP + FN)
Accuracy is the overall fraction of correct predictions. On imbalanced data it is misleading because a degenerate classifier that always predicts the majority class gets a high accuracy without doing anything useful. A 99% accurate fraud detector that says “not fraud” to everyone has 0% recall.
Specificity
Specificity = TN / (TN + FP)
Specificity is the true-negative rate. Useful in safety-critical settings (alert systems, medical screening) where false alarms are costly. F1 does not summarize specificity; use it alongside F1 when it matters. It is the recall of the negative class, and 1 minus specificity is the false positive rate on the x-axis of a ROC curve.
The F1 formula
F1 is the harmonic mean of precision and recall.
F1 = 2 * (Precision * Recall) / (Precision + Recall)
F1 = 2TP / (2TP + FP + FN) is the same formula in raw counts, as the scikit-learn docs write it.
The harmonic mean has a useful property: it is dominated by the smaller of the two inputs. A model with precision 0.99 and recall 0.10 has an F1 of about 0.18, not 0.55 (the arithmetic mean). That is the point. F1 forces you to be good at both.
Calculating the F1 score from a confusion matrix
Given:
- TP = 40
- FP = 10
- FN = 20
Then:
Precision = 40 / (40 + 10) = 0.80Recall = 40 / (40 + 20) = 0.667F1 = 2 * (0.80 * 0.667) / (0.80 + 0.667) = 1.067 / 1.467 = 0.727
An F1 of 0.73 says the model is balanced on the positive class. Whether 0.73 is good depends entirely on the baseline and the use case, and the next section shows how to build that baseline from your label mix.
What is a good F1 score
F1 runs from 0 to 1, and higher is better: 1 means no false positives and no false negatives on the positive class. Whether a given score is good depends on your data, so compare it against a baseline built from your own label mix.
The simplest baseline flags every example as positive. Its recall is 1 and its precision equals the positive rate p, so its F1 is 2p / (1 + p). At a 5% positive rate that baseline scores about 0.095, and on a 50/50 split it scores 0.667, so a 0.5 F1 sits well above the baseline in the first case and below it in the second.
When to use F1, and when not to
Use F1 when
- Classes are imbalanced (one class is much rarer than the other). Accuracy can be misleading; F1 is often more useful when precision and recall both matter.
- Both false positives and false negatives have real cost. F1 forces you to optimize for both.
- You want a single number to compare models. F1 is more discriminating than accuracy on the cases that matter.
- You’re scoring an LLM classifier. Prompted classifiers produce categorical outputs; F1 is useful, but choose binary, macro, weighted, or per-class F1 based on the label structure.
Do not use F1 when
- Classes are balanced and the costs are roughly symmetric. Accuracy is simpler.
- Business clearly cares about one side of the error. Report precision or recall directly, or pick F-beta with the appropriate beta.
- You are choosing a threshold. AUC-PR or AUC-ROC summarize ranking quality across thresholds. F1 only summarizes one threshold.
- You’re doing ranking, retrieval, or recommendation. Use MAP, NDCG, MRR, or recall@k instead.
F1 variants
F-beta
The general form weights precision and recall asymmetrically:
F_beta = (1 + beta^2) * Precision * Recall / (beta^2 * Precision + Recall)
beta = 1recovers F1.beta > 1(for example F2) gives recall more weight. Use for fraud detection, screening, abuse classification.beta < 1(for example F0.5) gives precision more weight. Use for spam filtering, content moderation gates, legal-review precision targets.
F-beta is more honest than picking F1 and pretending it is symmetric when the business cost is not. Two commonly used variants are F2 and the F0.5 score. With beta = 2 the formula is 5 * P * R / (4 * P + R); with beta = 0.5 it is 1.25 * P * R / (0.25 * P + R). On the worked example (precision 0.80, recall 0.667), F2 is 0.690 and F0.5 is 0.769.
Macro F1
Compute F1 separately for each class, then average:
Macro F1 = mean(F1_class_1, F1_class_2, ..., F1_class_K)
Every class counts equally. Use macro F1 when minority classes matter as much as majority classes (rare-disease detection, low-frequency intent classification). In scikit-learn it is average='macro': an unweighted mean of per-class scores that does not take label imbalance into account.
Micro F1
Pool TP, FP, FN across all classes, then compute one F1:
Micro F1 = F1(sum_TP, sum_FP, sum_FN)
On multi-class single-label problems, micro F1 equals accuracy. It weights each example equally rather than each class. Use micro F1 when overall correctness matters more than per-class fairness. In scikit-learn this is average='micro', which counts the total true positives, false negatives and false positives before computing F1.
Weighted F1
Compute per-class F1, then average weighted by the number of true instances of each class:
Weighted F1 = sum(n_class_k * F1_class_k) / total_n
Use weighted F1 when larger classes are more important (revenue-weighted classification, frequency-weighted routing). In scikit-learn it is average='weighted', which weights each class’s F1 by its support. A weak minority class barely moves this score, so check per-class F1 before trusting it.
Macro F1 score formula, worked example
Take the three-class labels from the scikit-learn example further down: y_true = [0, 1, 2, 0, 1, 2, 0, 1, 2] and y_pred = [0, 2, 1, 0, 0, 2, 0, 1, 2]. Treat each class as its own binary problem and count TP, FP and FN for it.
| Class | TP | FP | FN | Precision | Recall | F1 |
|---|---|---|---|---|---|---|
| 0 | 3 | 1 | 0 | 0.750 | 1.000 | 0.857 |
| 1 | 1 | 1 | 2 | 0.500 | 0.333 | 0.400 |
| 2 | 2 | 1 | 1 | 0.667 | 0.667 | 0.667 |
Macro F1 = (0.857 + 0.400 + 0.667) / 3 = 0.641. Micro F1 pools the counts (TP 6, FP 3, FN 3) into 2 * 6 / (12 + 3 + 3) = 0.667, the same as accuracy. Weighted F1 is also 0.641 here because every class has a support of 3, and it only moves away from macro F1 when class sizes differ.
Macro vs micro F1, and where weighted fits
- Every class matters equally: macro F1.
- Bigger classes matter more: weighted F1.
- Per-example correctness matters: micro F1 (equals accuracy on single-label multi-class).
Thresholds and calibration for production F1
The F1 of a probabilistic classifier depends on the threshold you use to convert scores into class labels. A classifier with great AUC-PR can still have a poor F1 if the threshold is chosen badly. Two things matter in production:
- Calibrate the probabilities before thresholding. Use Platt scaling (logistic calibration) or isotonic regression. A calibrated classifier means the predicted probability matches the empirical positive rate.
- Pick the threshold on a held-out calibration set, not on the test set. Search thresholds in [0.01, 0.99] and pick the one maximizing F1 (or F-beta) on the calibration set. Then report F1 on the test set at that fixed threshold.
Skipping calibration and threshold selection can make production F1 drift from the offline number. scikit-learn 1.5 and later ship TunedThresholdClassifierCV, which runs this threshold search with internal cross-validation. Its default objective is balanced accuracy, so pass scoring=make_scorer(f1_score) (or an F-beta scorer) when F1 is the number you report.
Implementing F1 in Python
Scikit-learn (BSD-3 license, scikit-learn.org) is the standard reference implementation.
from sklearn.metrics import f1_score, precision_score, recall_score

y_true = [1, 0, 1, 1, 0, 1, 0, 0, 1, 1]
y_pred = [1, 0, 1, 0, 0, 1, 1, 0, 1, 1]

precision = precision_score(y_true, y_pred)
recall = recall_score(y_true, y_pred)
f1 = f1_score(y_true, y_pred)

print(f"Precision: {precision:.3f}")
print(f"Recall:    {recall:.3f}")
print(f"F1 Score:  {f1:.3f}")
For a multiclass F1 score, sklearn.metrics.f1_score takes an average argument: 'binary' (the default, valid only for two-class targets), 'macro', 'micro', 'weighted', 'samples' (multilabel only), or None (returns one F1 per class).
from sklearn.metrics import f1_score, classification_report

y_true = [0, 1, 2, 0, 1, 2, 0, 1, 2]
y_pred = [0, 2, 1, 0, 0, 2, 0, 1, 2]

print("Macro F1:    ", f1_score(y_true, y_pred, average="macro"))
print("Micro F1:    ", f1_score(y_true, y_pred, average="micro"))
print("Weighted F1: ", f1_score(y_true, y_pred, average="weighted"))
print()
print(classification_report(y_true, y_pred, digits=3))
The classification_report output gives per-class precision, recall, F1, and support in one block. When a class gets no predictions, scikit-learn scores it 0 and raises a warning; pass zero_division=0 to keep the 0 without the warning. Pass output_dict=True to get the same numbers as a Python dict.
F1 for LLM classification tasks
LLMs prompted as classifiers (intent classification, content moderation, support routing, retrieval relevance, label assignment) are evaluated with the same precision-recall-F1 toolbox as traditional classifiers, plus an LLM-specific concern: the LLM may produce malformed outputs. The guide to evaluating LLM classifiers covers the full eval that ships for prompted classification.
A minimal LLM-classification eval pipeline:
import json
from sklearn.metrics import f1_score, classification_report

def call_llm_classifier(prompt: str, text: str) -> str:
    """Stub. Wire to your real LLM call (OpenAI, Anthropic, etc.)."""
    return "{}"  # placeholder

def parse_label(raw: str, classes: list[str]) -> str | None:
    """Extract a valid class label from raw LLM output, or None on failure."""
    try:
        obj = json.loads(raw)
        if not isinstance(obj, dict):
            return None
        label = obj.get("label")
        return label if label in classes else None
    except json.JSONDecodeError:
        return None

CLASSES = ["billing", "technical", "account", "other"]
texts = [
    "I was charged twice for the same month.",
    "My password reset email never arrived.",
    "How do I delete my account?",
    "Can you ship to Canada?",
]
y_true = ["billing", "account", "account", "other"]

PROMPT = (
    "Classify the support message into one of: billing, technical, account, other. "
    "Respond with JSON: {\"label\": \"<class>\"}."
)

y_pred = []
parse_failures = 0
for text in texts:
    raw = call_llm_classifier(PROMPT, text)
    label = parse_label(raw, CLASSES)
    if label is None:
        parse_failures += 1
        label = "other"  # or some default fallback
    y_pred.append(label)

print(f"Parse failures: {parse_failures}/{len(texts)}")
print(classification_report(y_true, y_pred, labels=CLASSES, digits=3))
print("Macro F1:    ", f1_score(y_true, y_pred, labels=CLASSES, average="macro", zero_division=0))
Two things to track for an LLM classifier that you do not track for a traditional classifier:
- Format-failure rate. What fraction of outputs failed to parse into a valid class. A classifier with a 5% format-failure rate has hidden metric degradation (across precision, recall, or both, depending on how you handle the fallback) before you even compare predictions.
- Instruction-adherence score. Did the model follow the prompt format or pick a class outside the allowed list. Future AGI’s
evaluate("prompt_adherence", ...)call scores this alongside F1.
Pairing format checks with classical F1 is the difference between “the LLM is bad” and “the LLM is good but the prompt is wrong.”
Common mistakes when using F1
- Reporting F1 in isolation. Always report precision, recall, the confusion matrix, and class support alongside F1. The four together tell a story F1 alone cannot.
- Using accuracy on imbalanced data. A 99%-accurate fraud detector with 0% recall is not a useful model. Switch to F1 or recall.
- Comparing F1 across different thresholds. F1 depends on the threshold. Pick the threshold on a calibration set, hold it fixed, then compare.
- Confusing micro F1 with accuracy. On multi-class single-label problems they are equal. On multi-label problems they differ.
- Ignoring per-class F1. A macro F1 of 0.80 across five classes can hide one class at 0.40. Always look at per-class F1 before declaring victory.
- Optimizing for F1 when the business is asymmetric. If false negatives are 10x more expensive than false positives, F1 is the wrong loss. Use F2 or report recall as the primary metric.
Where Future AGI fits
F1 is a classical metric, and scikit-learn computes it for free. Future AGI covers the layer above it when an LLM is the classifier. It scores labels against ground truth with code-based classification metrics such as accuracy, balanced accuracy, precision and F-beta, and checks whether the model followed the prompt, leaked PII, or returned a class outside the allowed list.
The evaluate() call below ships in agent-learning-kit (pip install agent-learning-kit, Apache-2.0) and runs the prompt_adherence cloud eval on a Turing model, so set FI_API_KEY and FI_SECRET_KEY first. The template takes the prompt as input and the model’s raw reply as output, and returns a score with a plain-language reason.
from fi.evals import evaluate

result = evaluate(
    "prompt_adherence",
    input="Classify the support message into: billing, technical, account, other.",
    output='{"label": "billing"}',
    model="turing_flash",
)

print(result.score, result.reason)
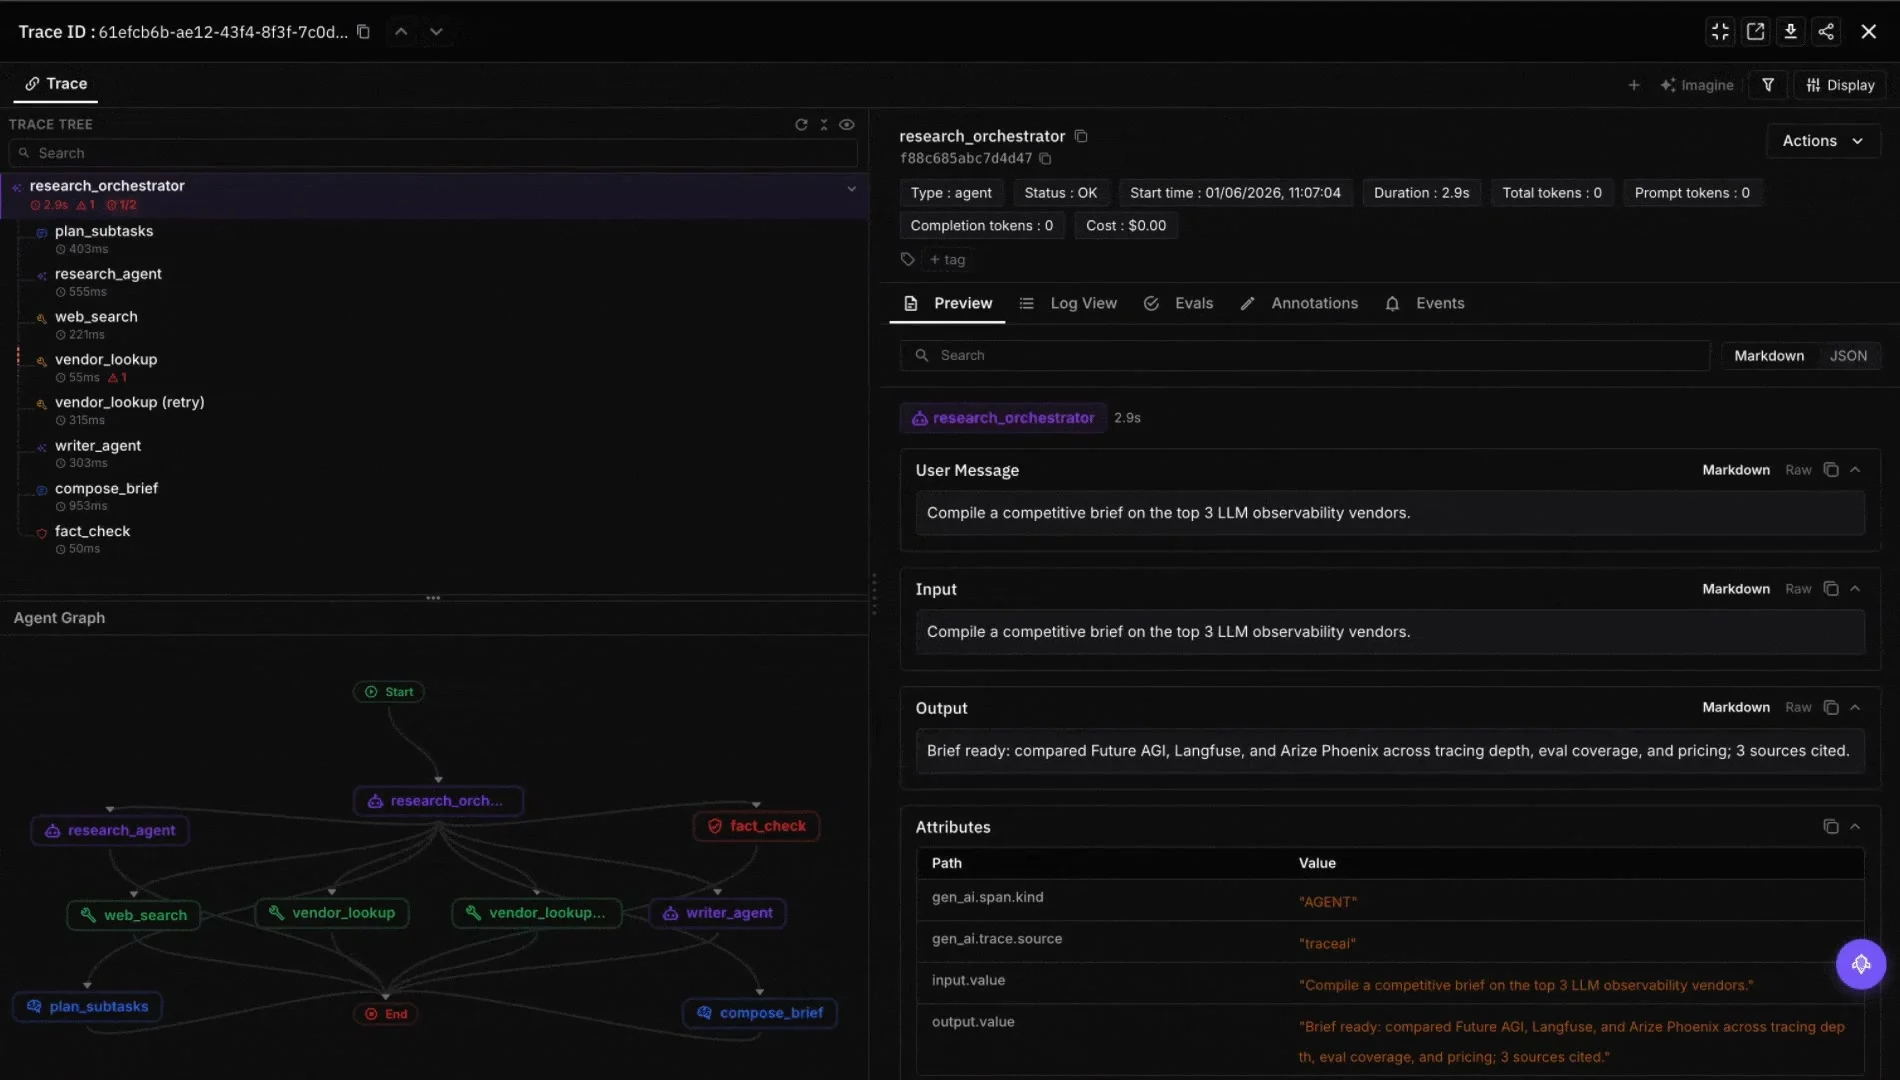
Pair prompt_adherence with a per-class F1 score from scikit-learn and you cover both the labeling correctness and the output-shape correctness in one evaluation pass. In production, traceAI sends each classifier call to Future AGI Observe as an OpenTelemetry trace. There you attach eval scores to whole traces or single spans and set alerts that fire when a metric slips.
Make your F1 number match your classes and costs
A single F1 number helps only when it matches how your classes and error costs behave. Choose macro F1 when every class matters, weighted F1 when large classes carry the value, and F-beta when one error costs more. Fix the threshold on a calibration set and publish per-class precision and recall beside it.
For an LLM classifier, track the parse-failure rate and a prompt adherence score next to F1 so malformed outputs stop hiding inside the score. That way the number in your model card describes the classifier you actually run in production.
Score your LLM classifier’s labels and output format together in Future AGI.
Sources
Frequently Asked Questions
How is the F1 score calculated?
What is a good F1 score?
Is a higher or lower F1 score better?
What is macro F1 score?
What is the difference between micro and macro F1 score?
How do you calculate a multiclass F1 score in sklearn?
Is macro F1 score better than accuracy?
Schema, regex, exact match, BLEU/ROUGE, citation-validity. Where deterministic LLM eval metrics catch 30-60 percent of failures before a judge fires.
Custom LLM eval metrics in 2026: a tight criterion, a calibrated corpus, a stability check. Patterns, code, and pitfalls, all in one guide.

How to identify hallucinations in AI with six detection methods: Future AGI evals, ChainPoll judges, NLI, SelfCheckGPT, RAG faithfulness, and human review.
