Best OpenRouter Alternatives in 2026, Including Free Options
Compare Portkey, LiteLLM, TrueFoundry, Helicone and Future AGI as OpenRouter alternatives in 2026: pricing, free tiers, open-source licenses and BYOK fees.
Table of Contents
OpenRouter gives you 500+ models behind one API key, and teams look elsewhere when they need a self-hosted plane with its own audit logs, semantic caching, or eval scores on traces. This guide compares five OpenRouter alternatives for 2026: Portkey, LiteLLM, TrueFoundry, Helicone, and Future AGI.
TL;DR by use case
| Use case | Best pick | Why (one phrase) | Pricing | OSS |
|---|---|---|---|---|
| Hosted governance, observability, and prompt engineering in one gateway | Portkey | Production gateway with deep policy and analytics | Free tier, Production $49/mo | MIT gateway |
| Self-hosted Python proxy with broad provider coverage | LiteLLM | Code-first router with retries, fallbacks, budgets | OSS free, Enterprise by request | MIT (enterprise folder separate) |
| Kubernetes-native enterprise gateway in VPC or air-gapped | TrueFoundry | K8s-native with RBAC, SSO, and compliance | Free Developer plan, Pro $25/user/mo | Closed source |
| Gateway-first observability with request analytics and caching | Helicone | Fastest base-URL swap, deep request analytics | Hobby free, Pro $79/mo, Team $799/mo | Apache 2.0 |
| Routing closes back into evals, tracing, and guardrails | Future AGI | Loop from gateway to eval and back to dataset | Free self-hosted core, hosted from $0 + usage | Apache-2.0 core |
If you only read one row: pick Portkey when you need a polished hosted gateway, LiteLLM when self-hosted Python ergonomics matter, and Future AGI when routing decisions must inform evaluation and prompt optimization. For deeper reads: see our LLM Gateway buyer guide, the traceAI tracing layer, and the Agent Command Center docs.
Who OpenRouter is and where it falls short
OpenRouter is a unified API marketplace for 500+ models from 80+ providers, from OpenAI, Anthropic, and Google to open-weight hosts. Its docs describe auto-routing, provider failover, response caching, multimodal inputs and outputs, advanced tool calling with server-side tools, and enterprise controls like workspace management, spending guardrails, and broadcast integrations into Langfuse, Datadog, and other backends.
As of October 2026, OpenRouter passes provider pricing through with no inference markup and charges 5.5% on Standard credit purchases or 8% on Business, never per request. BYOK covers $25,000 of list-price inference a month with no fee, then 5%. The Free plan offers 25+ free models at 50 requests per day, or 1,000 per day after buying $10 of credits.
Its Auto Router picks a model for each prompt, and default provider routing load-balances requests across providers to maximize uptime. The observability side includes request logs, cost dashboards, and broadcast integrations into multiple LLM-observability backends. For solo engineers, prototypes, and small teams that want one key and many models, OpenRouter remains the path of least resistance.
The reasons to move usually come down to controls a hosted broker does not offer. You may need an audit trail that satisfies SOC 2 or HIPAA without depending on a third-party broker. You may need conditional routing rules that target specific endpoints based on user attributes, latency, and cost.
You may need A/B traffic splitting and semantic caching inside the same plane, or self-hosted control because PII or regulated data cannot leave your VPC. You may want eval scores attached to span data instead of a separate dashboard.
OSS license posture across OpenRouter and the five closest alternatives
Future AGI pairs an Apache-2.0 core with self-hosting across the gateway, tracing, and evals.
| Platform | License | Self-host posture |
|---|---|---|
| Future AGI | ✓ Apache-2.0 core | ✓ Full |
| Helicone | ✓ Apache 2.0 | ✓ Full |
| Portkey gateway | ✓ MIT gateway (closed control plane) | ◐ Partial (gateway OSS, control plane closed) |
| LiteLLM | ✓ MIT (enterprise folder separate) | ✓ Full |
| OpenRouter | ✗ Closed source hosted | ✗ None (BYOK only) |
| TrueFoundry | ✗ Closed source K8s | ◐ Customer-managed K8s only |
Free and open-source OpenRouter alternatives
Each of the five alternatives has a $0 entry point, either a free hosted plan or code you can self-host. The table lists the cheapest path for each one as of October 2026.
| Option | Free path |
|---|---|
| LiteLLM | Self-host the MIT proxy |
| Portkey | Self-host the MIT gateway, or Developer plan with 10k recorded logs a month |
| Helicone | Hobby plan with 10,000 requests, or self-host |
| TrueFoundry | Developer plan, $0 for up to 3 users |
| Future AGI | Free plan with 100K gateway requests a month, or self-host |
A free gateway does not make the models free. You still pay each provider for tokens, so a free tier saves the platform fee, not the inference bill or your server costs. OpenRouter’s own Free plan is the exception, with 25+ free models capped at 50 requests per day.
The 5 OpenRouter alternatives compared
1. Portkey: Best hosted gateway with governance and observability
Open-source gateway. Closed-source hosted control plane. Self-hostable.
Portkey is the most polished hosted gateway in this list, especially for teams that need governance, observability, prompt engineering, and routing in one product. The pitch is that the gateway is a single integration point for every LLM call, and policy, telemetry, prompt management, and analytics live behind that point.
Ownership: Palo Alto Networks closed its acquisition of Portkey on May 29, 2026, and Portkey’s site now presents the hosted product as Prisma AIRS AI Gateway.
Architecture: Portkey ships an open-source AI gateway under the MIT license plus a hosted control plane for analytics, prompt management, governance, and enterprise features. The gateway exposes an OpenAI-compatible REST API and routes to 1,600+ language, vision, audio, and image models, with conditional routing, load balancing, retries, fallbacks, guardrails, and virtual keys. The open-source gateway caches identical requests, and semantic caching is limited to the hosted and enterprise versions.
Pricing: Portkey’s Developer plan is free with 10k recorded logs a month. Production is $49 a month with 100k recorded logs and $9 per extra 100k. Enterprise is custom and adds SSO, VPC hosting, SOC 2 Type 2, and HIPAA, and the self-hosted gateway has no license fee.
Best for: Pick Portkey when one team owns gateway, prompts, and analytics, and the buying signal is governance plus observability inside the same UI. It pairs well with OpenAI-compatible clients, Anthropic SDK, Google GenAI, Bedrock, Azure OpenAI, and BYOK setups.
Skip if: Skip Portkey if your eval and tracing pipeline is the center of gravity, since prompt-eval depth is lighter than dedicated eval platforms. Skip it if you need agent simulation or voice testing as part of the loop. Also model the cost. Production adds $9 for every extra 100k requests past its included logs, and that math compounds at scale.
2. LiteLLM: Best self-hosted Python proxy
MIT core; the enterprise folder has its own license. Self-hostable.
Pick LiteLLM when the team wants a code-first proxy and SDK, runs Python, and needs broad provider coverage without paying a platform fee. It suits teams that have already standardized on Python services and want their gateway to be one of those services.
Architecture: LiteLLM is an open-source Python library and standalone proxy that translates 100+ LLM provider APIs into OpenAI-compatible inputs and outputs. Router supports retries, fallbacks, timeouts, cooldowns, weighted load balancing, virtual keys, and budgets. The proxy ships as a single Docker image with optional Postgres for budget tracking, model-cost reporting, and key management. The SDK is Python, and other languages call the proxy through its OpenAI-compatible API.
Pricing: The proxy is free to self-host under the MIT license, apart from the enterprise/ folder, which has its own license. Enterprise adds SSO and SCIM, OIDC and JWT auth, audit logs, and 24/7 support with SLAs, and its enterprise page lists no public price.
Best for: Pick LiteLLM if your team is Python-first, runs services in Docker or Kubernetes, and wants a code-first proxy with budget tracking, retries, and model fallbacks. It pairs well with custom agent code, BYOK provider keys, FastAPI services, and existing OTel pipelines.
Skip if: Skip LiteLLM if you need a polished UI for prompts, datasets, and evals out of the box. The proxy ships analytics, but the visual surface area is thinner than Portkey or TrueFoundry. SSO, SCIM, JWT auth, and audit logs sit in the paid Enterprise tier, so price that in if procurement requires them.
3. TrueFoundry: Best Kubernetes-native enterprise gateway
Closed source. Self-hosted in your VPC, on-prem, or air-gapped. Cloud option.
TrueFoundry fits when your platform team already runs Kubernetes and wants an enterprise AI gateway that fits the same Helm-and-RBAC mental model as the rest of your stack. The pitch is governance, multi-cloud deployment, and observability inside one plane that the platform team can own.
Architecture: TrueFoundry AI Gateway is Kubernetes-native with Helm-based management. It supports unified access across 250+ LLMs, including chat, completion, embedding, and reranking models. Governance covers RBAC with SSO, rate limiting per user or service or endpoint, token-based and cost-based quotas, and OAuth2 plus API-key auth.
Observability includes token usage, latency, error rates, full request and response logging, and metadata tagging. Reliability covers latency-based and weighted load balancing, automatic fallback, geo-aware routing, and a stated sub-3ms internal latency claim. Safety covers PII filtering and toxicity detection, and the Enterprise plan adds third-party guardrails. The platform claims SOC 2, HIPAA, and GDPR compliance and supports VPC, on-prem, and air-gapped environments.
Pricing: TrueFoundry’s Developer plan is $0 for up to 3 users with 10K requests per user a month. Pro is $25 per user a month, and Enterprise is a custom annual commitment. The gateway page lists 10B+ requests a month and 99.99% uptime.
Best for: Pick TrueFoundry when your platform team mandates Kubernetes-native deployment, when SOC 2 or HIPAA is a hard procurement gate, and when air-gapped or on-prem is required. The buying signal is enterprise governance plus K8s ownership rather than a hosted SaaS contract.
Skip if: Skip TrueFoundry’s self-hosted path if your team does not run Kubernetes and you do not want to. Helm, autoscaling, GPU scheduling, and cluster operations are a real cost. VPC, on-prem, and data residency sit in the Enterprise plan, so the free and Pro tiers do not cover regulated self-hosting. Verify exact gateway latency claims under your traffic shape before signing because vendor benchmarks rarely match production loads.
4. Helicone: Best for gateway-first observability and analytics
Apache 2.0. Self-hostable. Hosted cloud option.
Reach for Helicone when the fastest path to value is changing the base URL, seeing every request, and controlling spend. It is gateway-first observability, with eval scores and prompt management as adjacent features. That matters if the production issue is provider routing, caching, p95 latency, cost attribution, user-level analytics, or fallback behavior.
Architecture: Helicone is an Apache 2.0 project for LLM observability and an OpenAI-compatible AI Gateway. The docs cover request logging, provider routing across 100+ providers, caching, rate limits, LLM security, sessions, user metrics, cost tracking, datasets, alerts, reports, HQL, eval scores, prompts, and prompt assembly. The base-URL swap is the lowest-friction migration in this list.
Pricing: Helicone Hobby is free with 10,000 requests, 1 GB storage, 1 seat, and 1 organization. Pro is $79 per month with unlimited seats, alerts, reports, and HQL. Team is $799 per month with 5 organizations, SOC 2, HIPAA, and a dedicated Slack channel, and Enterprise is custom with SAML SSO, on-prem deployment, and bulk cloud discounts. Usage-based pricing applies above included allowances.
Best for: Pick Helicone if request analytics, user-level spend, model cost tracking, caching, fallbacks, and prompt management are the gap. It is a strong first tool for teams with live LLM traffic that need an answer to “which users, prompts, models, and endpoints drove this p99 spike.”
Skip if: Helicone will not replace a deep eval platform by itself. The product centers on gateway observability. On March 3, 2026, Helicone announced it was joining Mintlify, with security patches, bug fixes, and new model support continuing in maintenance mode. Its site now says it is no longer part of Mintlify, so confirm ownership first.
5. Future AGI: Best when routing closes into evals and guardrails
Apache-2.0 core. Self-hostable. Hosted cloud option.
Future AGI is the right alternative when gateway routing must inform pre-prod evaluation, prompt optimization, and guardrail enforcement, all in the same loop. The Agent Command Center routes across 100+ providers, cloud and self-hosted, through one OpenAI-compatible API with your own provider keys, guardrails, and cache.
traceAI traces every LLM call, retrieval step, and agent decision as OpenTelemetry spans, and evals score those spans. The buying signal is teams that already use OpenRouter for breadth but lose fidelity when production failures need to become eval cases without manual export.
Architecture: The core is Apache-2.0 and self-hostable with Docker Compose or a signed Helm chart. The Go-based Agent Command Center gateway fronts your providers, and traceAI (Apache 2.0) instruments Python, TypeScript, Java, and C# apps on OpenTelemetry. Production traces also feed six prompt-optimization algorithms as training data.
Pricing: The Free plan includes 100K gateway requests and 100K cache hits a month, and gateway usage then starts at $5 per 100K requests. Add-ons bring SOC 2 Type II, HIPAA BAA, and SAML SSO with SCIM.
Best for: Pick Future AGI when production gateway data should land in the same plane as evals, prompts, datasets, and CI gates. The buying signal is teams using OpenRouter for routing, Langfuse for observability, a notebook for prompt iteration, and a separate eval harness, who watch failures repeat across releases because the loop is manual.
How to choose an OpenRouter alternative
- Choose Portkey if your dominant workload is gateway-first governance with prompt management, conditional routing, and analytics in one hosted UI. Buying signal: one team owns gateway plus prompts plus telemetry. Pairs with: OpenAI-compatible clients, BYOK, virtual keys.
- Choose LiteLLM if your team is Python-first and wants a code-first proxy with router, budgets, and fallbacks. Buying signal: services already run in Docker or Kubernetes. Pairs with: FastAPI, custom agent code, OTel exporters.
- Choose TrueFoundry if K8s ownership and enterprise governance are non-negotiable. Buying signal: SOC 2 or HIPAA gate, VPC or air-gapped requirement. Pairs with: Helm, RBAC, SSO, multi-cloud deployment.
- Choose Helicone if the fastest path to value is changing the base URL and seeing every request. Buying signal: live traffic and a p99 mystery. Pairs with: OpenAI-compatible clients, provider failover, budget tracking. Confirm ownership before signing.
- Choose Future AGI if routing must inform evals, traces, and guardrails inside the same plane. Buying signal: production failures must become eval cases without manual export. Pairs with: traceAI, OpenTelemetry backends, BYOK evals.
Common mistakes when picking an OpenRouter alternative
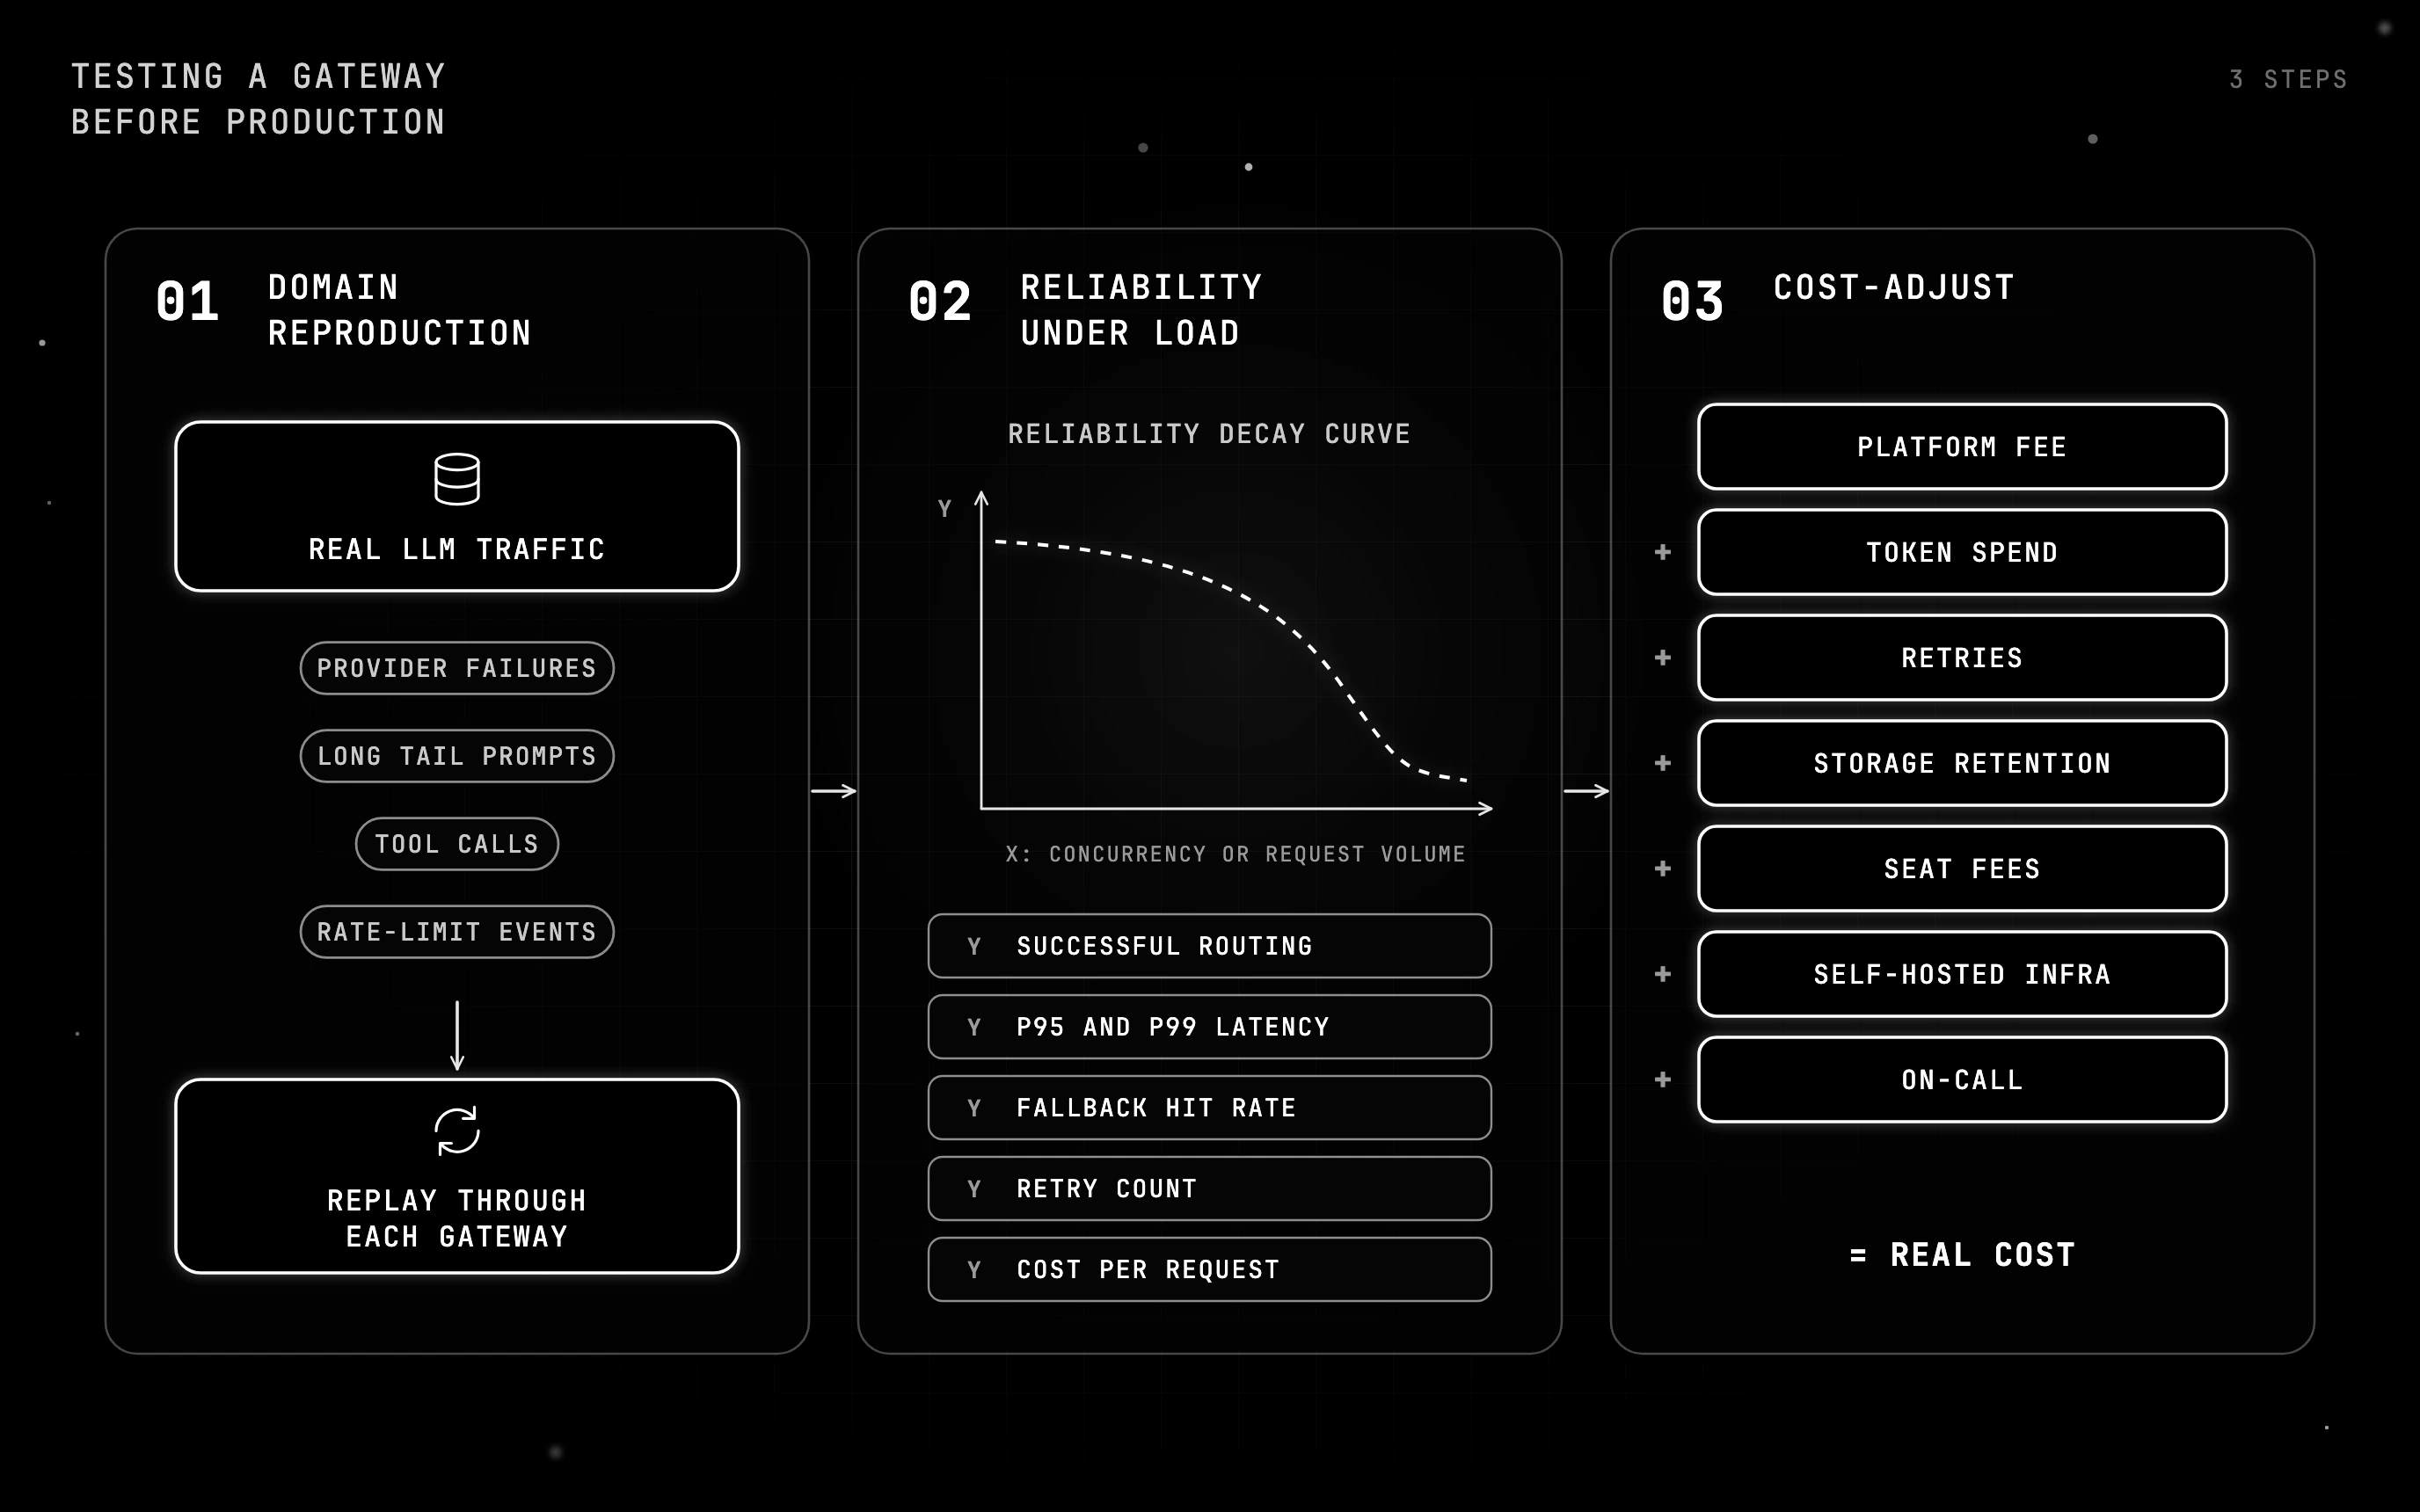
- Treating the platform fee as the only cost. Real cost is platform fee plus token spend plus retries plus retention plus cache hits plus seats plus on-call hours for self-hosted operators. A cheaper subscription can lose if every retry calls a slow provider.
- Ignoring license fine print. LiteLLM is MIT outside
enterprise/, Phoenix is Elastic License 2.0, Portkey’s gateway is MIT, Helicone is Apache 2.0, and Future AGI has an Apache-2.0 core. Read each LICENSE file before procurement signs off. - Picking by provider count. Eighty-plus providers in a catalog look impressive on a slide, but the number that matters is the provider you actually call, the one your traffic will hit at p99, and the one that has rate-limit headroom on your account.
- Skipping the failover drill. A gateway is a single point of failure for production LLM traffic. Run a 24-hour drill: kill primary, observe fallback timing, retry counts, cost, and tail latency before signing a contract.
- Pricing only the gateway. Real cost includes seats, retention, audit log volume, prompt management seats, eval token spend, and the labor cost of operating self-hosted infra.
How to test a gateway before production
-
Run a domain reproduction. Export a representative slice of real LLM traffic, including provider failures, long tail prompts, tool calls, and rate-limit events. Replay the slice through each candidate gateway with your OTel payload shape and your real provider keys. Do not accept a vendor benchmark.
-
Measure reliability under load. Build a Reliability Decay Curve: x-axis is concurrency or request volume, y-axis is successful routing, p95 and p99 latency, fallback hit rate, retry count, and cost per request. Track dropped requests, duplicate requests, failed fallbacks, and time-to-detect for primary outages.
-
Cost-adjust. Real cost equals platform fee plus token spend plus retries plus storage retention plus seat fees plus self-hosted infra plus on-call. A gateway with a lower per-request fee can lose if its fallback policy doubles your retry rate. A self-hosted gateway can lose if Postgres and ClickHouse plus on-call exceed SaaS overage.
Moving past one API key to a gateway you control
You started with one API key and a growing list of needs: a self-hosted plane, semantic caching, and eval scores on traces. If routing failures need to become eval cases and guardrail rules in one place, start with Future AGI’s Agent Command Center, keep your provider keys, and add tracing and evals as you need them.
Route your first request through Agent Command Center
Sources
Frequently Asked Questions
What are the best OpenRouter alternatives in 2026?
Is OpenRouter API free?
What are some free APIs similar to OpenRouter?
Is there an open-source alternative to OpenRouter?
Is there an EU alternative to OpenRouter?
FutureAGI ACC, Helicone, OpenRouter, Portkey, LiteLLM, Cloudflare AI Gateway, Vercel AI Gateway as 2026 LLM gateways. Routing, caching, guardrails.

OpenRouter is a hosted gateway routing one OpenAI-compatible API to 400+ models across 60+ providers, auto-fallback, unified billing.
A 2026 field guide to LLM routing: definition, five strategies (round-robin, weighted, latency, cost, quality), architecture, myths.
