Langfuse Alternatives in 2026: 5 Honest Picks for Production AI
Compare Langfuse alternatives for 2026: Future AGI, LangSmith, Phoenix, Braintrust and Helicone on evals, guardrails, gateway, pricing and self-hosting.
Table of Contents
The five Langfuse alternatives worth comparing in 2026 are Future AGI, LangSmith, Arize Phoenix, Braintrust and Helicone, and each one closes a different gap. You are probably here because Langfuse works, but something is missing: the eval story falls short of production rigor, runtime guardrails live in another product, and the loop from a failing trace back to a versioned prompt is something you stitch by hand.
ClickHouse acquired Langfuse in January 2026, and it stays open source. This guide names the gap each tool fills, when to stay on Langfuse instead, and how to move your traces off it without re-instrumenting. Last updated October 23, 2026.
Why teams leave Langfuse
Langfuse is solid OSS-first observability. The trace UI is dense in a good way, prompt versioning supports labels and environments, and the self-hosting docs walk through Postgres, ClickHouse, Redis or Valkey, object storage, queues, and workers without hand-waving. The community is one of the larger ones in OSS LLMOps. The teams that move off Langfuse hit one of three production walls.
Wall 1: eval rigor. Langfuse ships LLM-as-a-judge templates for live observations and experiments, but an observation-level evaluator does not load sibling or child observations from the same trace. Multi-step agent checks need a root observation or custom scoring code, and failing inputs get no error localization.
Wall 2: runtime guardrails. No PII detector at the gateway, no prompt-injection scanner on the request path, no tool-permission enforcement before the LLM call. Guardrails live in adjacent products and you wire them yourself. Langfuse’s own security guide points teams to libraries such as LLM Guard and NeMo Guardrails, with Langfuse tracing what they catch.
Wall 3: closed-loop optimization. A failing production trace is a Jira ticket, not a labeled row in a prompt optimizer. The loop from failure back to a versioned prompt that the CI gate evaluates against the previous threshold is manual notebook work. Pick the alternative below that covers the gap you hit first.
Best Langfuse alternative per gap at a glance
| Gap that broke Langfuse | Best pick | Why | Pricing | License |
|---|---|---|---|---|
| All three (eval + guardrails + optimization) | Future AGI | Eval-stack package, runtime guardrails, six prompt optimizers, gateway, traceAI on one runtime | Free + usage | Apache-2.0 core |
| Runtime is LangChain or LangGraph | LangSmith | Native trace semantics; Fleet and Prompt Hub in the same plane | Plus $39/seat/mo | Closed, MIT SDK |
| OTel and OpenInference adherence | Arize Phoenix | OTLP-first, canonical OpenInference reference, Arize AX path | AX Pro $50/mo | ELv2 |
| Closed-loop eval workbench is the dominant need | Braintrust | Polished experiments, scorers, sandboxed evals, CI gates | Pro $249/mo | Closed |
| Gateway-first analytics, caching, cost control | Helicone | Base URL swap on live traffic; gateway is the center of gravity | Pro $79/mo | Apache 2.0 |
One-row summary: pick Future AGI when the loop has to close on one runtime. Pick LangSmith when LangChain is the runtime. Pick Helicone when changing the base URL is the fastest path to value. Pick Phoenix for OpenTelemetry purity and Braintrust for hosted eval workflows.
Langfuse alternatives by license and self-hosting
| Platform | License | Self-host posture |
|---|---|---|
| Future AGI | Apache-2.0 core | Full (Docker Compose or signed Helm chart) |
| Helicone | Apache 2.0 | Full (Postgres, ClickHouse, MinIO and Redis, or one all-in-one container) |
| Langfuse | Mostly MIT (enterprise dirs commercial) | Full (web + worker + Postgres + ClickHouse + Redis + S3) |
| Arize Phoenix | Elastic License 2.0 (source-available) | Full (single container with SQLite or PostgreSQL) |
| Comet Opik | Apache 2.0 | Full |
| MLflow | Apache 2.0 | Full |
| Laminar | Apache 2.0 | Full (Docker Compose) |
| LangSmith | Closed platform (MIT SDK only) | Partial (Enterprise tier, multi-service) |
| Braintrust | Closed platform | Partial (Enterprise on-prem or hosted deployment) |
ELv2 is source-available, not OSI open source, so call Phoenix source-available in a security review. Future AGI’s Apache-2.0 core self-hosts with Docker Compose or a signed Helm chart. Langfuse is MIT outside its ee/ directories, which carry a separate enterprise license.
What changed at Langfuse in 2026
ClickHouse acquired Langfuse on January 16, 2026. The announcement says Langfuse stays open source and self-hostable, Langfuse Cloud keeps running as is, and no licensing changes are planned. The repository’s license file now lists ClickHouse, Inc. as its copyright holder.
The 5 Langfuse alternatives, compared
1. Future AGI: best when all three gaps hit at once
Apache-2.0 core. Self-hostable. Hosted cloud option.
Quick take. Future AGI is the pick when eval rigor, runtime guardrails and closed-loop optimization need to live on one platform. agent-learning-kit is the code-first SDK for evals, simulation and optimization; traceAI instruments your app so the same evals score live spans; the Agent Command Center fronts 100+ providers with inline guardrails.
Ideal for. Teams that have already stitched a loop manually (Langfuse for traces, a notebook for prompt work, a separate gateway, an adjacent guardrail product) and watched the same regression class repeat across releases. Strong fit for RAG, voice, support automation, and copilots across Python, TypeScript, Java, and C#.
Key strengths.
- Eval stack with error localization. Custom rubrics (LLM judge or deterministic check) plus built-ins such as Task Completion, Tool Call Accuracy, Trajectory Match, Groundedness, PII and Toxicity. When an eval fails, error localization names the input field (prompt, context or query) that caused it. BYOK lets your own model judge at $0 platform cost.
- Runtime guardrails at the gateway. PII Detection, Prompt Injection, Content Moderation, Secret Detection, Tool Permissions and MCP Security run in enforce, monitor or log mode, with adapters for Lakera Guard, Presidio and Llama Guard. About 29k req/s on
t3.xlarge, P99 at or under 21 ms with guardrails on. - Closed-loop optimization. Production traces become training data for six prompt-optimization algorithms (GEPA, PromptWizard, ProTeGi, Bayesian, Meta-Prompt, Random) in agent-learning-kit (
pip install agent-learning-kit), and its local release gates check each new prompt before you promote it. - traceAI breadth. Instruments 50+ AI frameworks across Python, TypeScript, Java, and C# (LangChain, CrewAI, AutoGen, OpenAI Agents SDK, Pydantic AI, DSPy, Mastra, Spring AI, LangChain4j), built on OpenTelemetry with its own semantic conventions.
- Compliance. SOC 2 Type II, ISO 27001, GDPR and CCPA certified, and HIPAA compliant (BAA available), per futureagi.com/trust.
Pricing. Free tier includes 50 GB tracing and storage, 100K gateway requests, 1M text-simulation tokens, 60 minutes voice simulation, and 30-day retention; pay-as-you-go after that. Storage is $2/GB, and pricing is usage-based, not per-seat. Compliance add-ons (HIPAA BAA, SAML SSO + SCIM) layer per tier.
Verdict. Pick Future AGI when production failures need to close back into pre-prod tests through a CI gate rather than manual notebook work, and runtime guardrails belong on the same network hop as the gateway.
2. LangSmith: best when LangChain or LangGraph is the runtime
Closed platform. MIT SDK. Cloud, hybrid, and Enterprise self-host.
Quick take. LangSmith is the lowest-friction Langfuse alternative for LangChain and LangGraph teams. If every agent run is already a LangGraph execution, LangSmith gives you native tracing, evals, prompts, deployment, and Fleet workflows without translating concepts into a new vendor model. Outside LangChain, the value drops fast.
Ideal for. LangChain v1 and LangGraph teams who want eval, deployment, and observability in the same mental model as the runtime.
Key strengths.
- LangGraph spans render as the actual graph, not a flat list. Studio visualization, Playground replay, and Prompt Hub map cleanly to LangChain concepts.
- Fleet (the rename of Agent Builder) brings no-code visual agent authoring into the same plane.
- Cloud, hybrid, and Enterprise self-hosted with data in your VPC. Self-hosted LangSmith runs on Kubernetes with Helm and can turn on Fleet and the beta LLM Gateway.
Honest limitations. Framework coupling cuts both ways: custom agents, LiteLLM, direct provider SDKs, or non-LangChain orchestration see the value drop. Seat pricing makes cross-functional access expensive. No voice simulator (text multi-turn simulation uses the open-source openevals package), and the LLM Gateway is in beta.
Pricing. Developer is free with 5,000 base traces/mo and 1 seat, and Plus is $39/seat/mo with 10,000 base traces. Extra traces cost 0.005 LSU each ($5.00 per 1,000) and keep 14 days as base traces; extended traces keep 180 days for an extra fee. Enterprise custom.
Verdict. Pick LangSmith when LangChain is the runtime and framework-native ergonomics matter more than OSS control. Skip when your stack mixes custom agents, LiteLLM, direct provider SDKs, and non-LangChain orchestration. See LangSmith Alternatives.
3. Arize Phoenix: best when OpenTelemetry adherence drives the decision
Source-available under ELv2. Self-hostable. Phoenix Cloud and Arize AX paths.
Quick take. Phoenix is built by Arize, which started in ML observability and embedding drift. The pitch is OTLP-first ingestion, canonical OpenInference attributes, and a clean local workbench: phoenix serve and you have a tracer. Phoenix takes OTLP traces over HTTP on port 6006 and gRPC on port 4317.
Ideal for. Platform engineers who care about open instrumentation standards, want a local Phoenix workbench during development, and plan a path into Arize AX for production-scale ML observability.
Key strengths.
- OpenInference reference. Arize maintains the OpenInference conventions and instrumentations that Phoenix reads natively.
- Auto-instrumentation for LlamaIndex, LangChain, DSPy, Mastra, Vercel AI SDK, OpenAI Agents SDK, Bedrock, and Anthropic across Python, TypeScript, and Java.
- Single-container self-host with SQLite or PostgreSQL. Lightweight by design.
Honest limitations. ELv2 is source-available, not OSI open source, so call that out in a security review. Phoenix is not a gateway, not a guardrail product, and not a simulator. Teams that need routing, inline guardrails or simulated users run a second tool beside it.
Pricing. Phoenix is free self-hosted, and AX Free includes 25K spans/mo, 1 GB ingestion and 15 days retention. AX Pro $50/mo with 50K spans, 10 GB ingestion, 30 days retention. AX Enterprise is custom and adds self-hosted deployment, SSO and audit logs.
Verdict. Pick Phoenix when OpenInference adherence and the Arize AX path are the buying signals. Skip when you need gateway, guardrails, simulation, closed-loop optimization, or strict OSI open source. See Phoenix Alternatives.
4. Braintrust: best for hosted closed-loop eval
Closed hosted platform. Enterprise on-prem or hosted deployment.
Quick take. Braintrust is the closest hosted alternative when Langfuse usage is mostly evals, prompts, datasets, online scoring, and CI gates. Tight dev loop for teams that do not need source-level backend control. Loop, its built-in AI agent, investigates logs, experiments and datasets and can create or edit prompts, scorers and datasets.
Ideal for. Teams that prefer to buy rather than build, want experiments and scorers in one polished UI, and accept closed-source backend control.
Key strengths.
- Polished UI for experiments, datasets, scorers, prompt iteration, and playgrounds.
- Sandboxed evals (public preview, Pro and Enterprise) run your eval code in an isolated cloud sandbox controlled from Braintrust.
- Online scoring and CI gates in the same product as offline experiments.
- May 2026 added Java auto-instrumentation for Spring AI and LangChain4j.
Honest limitations. Closed platform with Enterprise-only self-host and no first-party voice simulator. No runtime guardrail product, and the hosted gateway is in public preview. Pro at $249/mo is the highest entry tier on this list; overage on processed data and scores adds up at production scale.
Pricing. Starter is $0 with 1 GB processed data, 10,000 scores and 14 days retention, and Pro is $249/mo with 5 GB, 50,000 scores and 30 days. Overage on Pro $3/GB and $1.50 per 1K scores. Enterprise custom.
Verdict. Pick Braintrust when structured evals with a polished UI is the dominant problem and gateway, guardrails, and simulation are off the list. Skip when OSS control is non-negotiable or the eval plan depends on simulated users and gateway guardrails in the same stack. See Braintrust Alternatives.
5. Helicone: best for gateway-first observability
Apache 2.0. Self-hostable. Hosted cloud option.
Quick take. Helicone is the right alternative when the fastest path to value is changing the base URL, seeing every request, and controlling spend. Center of gravity is the gateway. That matters when the production issue is provider routing, caching, p95 latency, cost attribution, user-level analytics, or alerting on live LLM traffic.
Ideal for. Teams with live traffic and no clean answer to which users, prompts, models, and endpoints drove a p99 spike.
Key strengths.
- OpenAI-compatible gateway with 100+ models. Low-friction when direct provider SDK calls are already spread across the codebase.
- Request logging, provider routing, caching, rate limits, sessions, user metrics, cost tracking, HQL, eval scores, and prompt management.
- Apache 2.0 self-host: Postgres, ClickHouse, MinIO and Redis, or one all-in-one container.
Honest limitations. Helicone is not a deep eval platform: eval scores and datasets exist, but Helicone is built around gateway observability. Helicone announced on March 3, 2026 that Mintlify had acquired it, with services live in maintenance mode. As of October 23, 2026, its site says it is no longer part of Mintlify, so confirm ownership and roadmap before you commit.
Pricing. Hobby is free with 10,000 requests, 1 GB and 1 seat, and Pro is $79/mo with unlimited seats, alerts, reports and HQL. Team $799/mo with SOC 2 and HIPAA. Enterprise custom.
Verdict. Pick Helicone when gateway-first analytics and cost control are the dominant need. Pair with a dedicated eval platform (Future AGI, Braintrust) if eval depth becomes the constraint.
Which gap does each Langfuse alternative close?
| Capability | Future AGI | LangSmith | Phoenix | Braintrust | Helicone | Langfuse |
|---|---|---|---|---|---|---|
| Built-in judge evaluators | Full (Turing models) | Full (judge templates) | Full (pre-built evals) | Full (scorers) | Partial | Full (judge templates) |
| Error localization on failing inputs | Yes | No | No | No | No | No |
| Runtime guardrails (PII, injection, tool perms) | Full (built-in + adapters) | Partial (beta redaction) | None | None | Partial | None |
| Closed-loop prompt optimization | Full (six algorithms) | Partial (Engine) | Partial (Prompt Learning) | Partial (Loop) | None | None |
| Voice + text simulation | Full | Partial (text, openevals) | None | None | None | Partial (text, openevals) |
| LLM gateway | Full (100+ providers) | Partial (beta) | None | Partial (preview) | Full | None |
| OpenTelemetry tracing | Full (50+ frameworks, 4 languages) | Full | Full (OpenInference) | Full | Partial | Full |
| Self-host license | Apache-2.0 core | Enterprise-only | ELv2 | Enterprise-only | Apache 2.0 | Mostly MIT |
How to choose a Langfuse alternative
- Future AGI if eval rigor, runtime guardrails, and closed-loop optimization all hit at once and one Apache-2.0 core platform is the requirement. Buying signal: the same incident class keeps repeating across releases because the loop between production failure and pre-prod regression test is manual.
- LangSmith if LangChain or LangGraph is the runtime and framework-native ergonomics matter more than OSS control.
- Phoenix if OpenInference adherence and the Arize AX path are the buying signals, and gateway plus guardrails are not on the list.
- Braintrust if structured evals with a polished UI is the dominant problem and gateway, guardrails, and simulation are off the requirement list.
- Helicone if request analytics, provider routing, caching, and cost attribution are the immediate need and changing the base URL is the lowest-friction path.
- Stay on Langfuse if OSS observability with prompts and datasets is the entire requirement and the three walls above have not hit yet.
Self-host operational footprint
| Platform | Footprint | What you run |
|---|---|---|
| Future AGI | Lightweight | One app container plus Postgres and ClickHouse (2 vCPUs, 4 GB); Helm chart for scale |
| Phoenix | Lightweight | Single container with SQLite or PostgreSQL |
| Helicone | Moderate | Postgres, ClickHouse, MinIO and Redis, or one all-in-one container |
| Langfuse | Moderate | Web + worker + Postgres + ClickHouse + Redis + S3 |
| LangSmith Self-Hosted | Moderate | Enterprise add-on on Kubernetes with Helm |
| Braintrust | Moderate | Enterprise on-prem or hosted deployment |
Common mistakes when picking a Langfuse alternative
- Treating units, traces, and scores as the same billing primitive. Langfuse units meter traces, observations, and scores together. Helicone bills requests. Braintrust bills processed data and scores. LangSmith bills base and extended traces. Future AGI bills storage, gateway requests, cache hits, AI credits, simulation tokens and voice minutes separately. Model real cost on a representative day.
- Treating OSS and self-hostable as the same. Phoenix is source-available under ELv2. Langfuse ships enterprise directories outside MIT. The license shows up in procurement before the feature comparison does.
- Picking by integration logos. Verify active maintenance for the framework version you actually use. LangChain v1, OpenAI Responses, Claude tool use, and OTel semantic conventions break observability quietly.
- Ignoring multi-step agent eval. Final-answer scoring misses tool selection, retries, retrieval misses, loop behavior, and session handoffs. Require trace-level and session-level evaluation if your agent does more than one call.
Recent platform updates
| Date | Event | Why it matters |
|---|---|---|
| May 2026 | Langfuse Experiments CI/CD | OSS teams can run experiment checks in GitHub Actions before release. |
| Mar 2026 | LangSmith Agent Builder became Fleet | LangSmith is expanding into no-code agent building. |
| Mar 2026 | Future AGI shipped Agent Command Center | Gateway, guardrails, and ClickHouse trace storage moved into the same loop as evals and optimization. |
| Mar 3, 2026 | Helicone joined Mintlify | Maintenance mode; in October 2026 its site said it is no longer part of Mintlify. |
| Jan 16, 2026 | LangSmith Self-Hosted v0.13 | More parity for VPC and self-managed deployments. |
| Jan 16, 2026 | ClickHouse acquired Langfuse | It stays open source and self-hostable. |
How to evaluate this for production
- Run a domain reproduction. Export a slice of real traces (failures, long-tail prompts, tool calls, retrieval misses, hand-labeled outcomes). Instrument each candidate with your harness, OTel payload shape, prompt versions, and judge model. Don’t accept a demo dataset.
- Measure reliability under load. Track p50, p95, p99 ingestion, dropped spans, duplicate spans, failed judge calls, retry count, query latency, and alert delay as concurrency rises.
- Cost-adjust. Real cost equals platform price times trace volume, token volume, test-time compute, judge sampling rate, retry rate, storage retention, and annotation hours. A cheap plan loses if every online score calls an expensive judge.
How to move off Langfuse without re-instrumenting
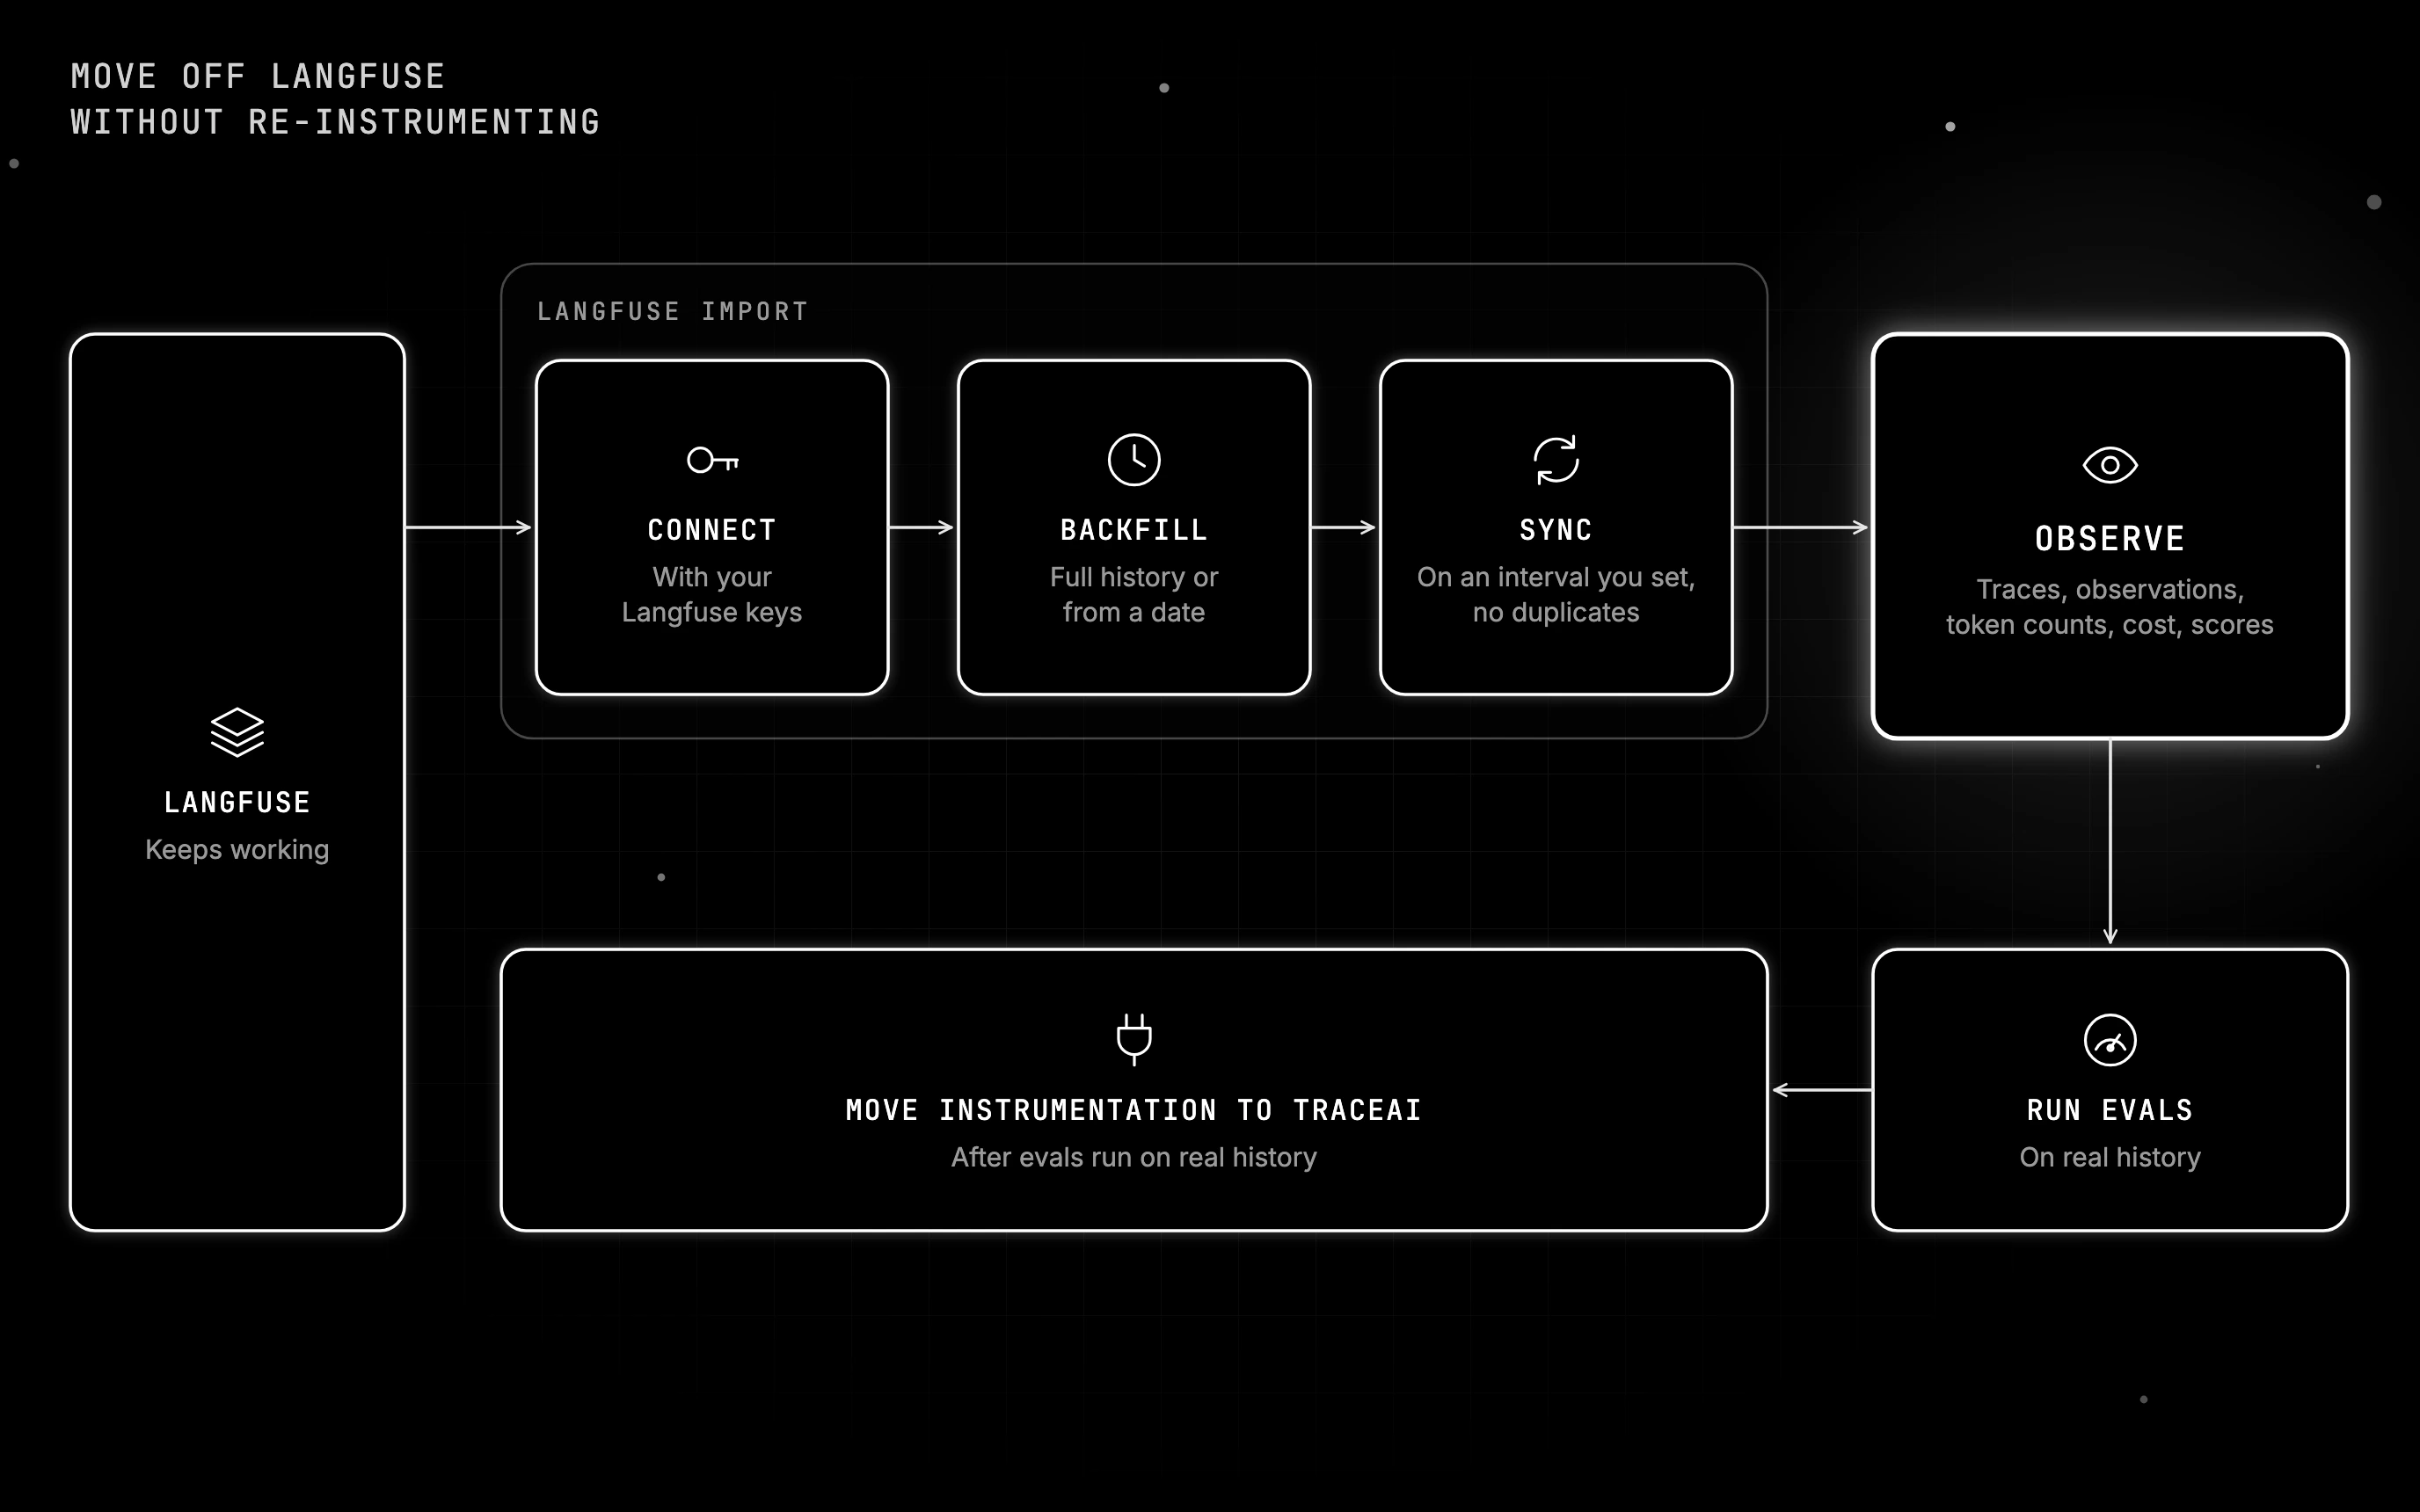
Future AGI’s Langfuse import connects with your Langfuse keys, backfills full history or history from a date, then syncs on an interval you set without creating duplicates. Traces, observations, token counts, cost and scores land in Observe while Langfuse keeps working, so you can run evals on real history before you move instrumentation to traceAI.
Closing the loop Langfuse leaves open
If you are comparing Langfuse alternatives, you are likely running three or four tools in production: one for traces, one for evals, one for the gateway, one for guardrails. Future AGI runs all four jobs on one Apache-2.0 core platform, so data from a failing trace flows back into evals and optimization instead of into a ticket queue.
Start free, connect your Langfuse project, and score last month’s failing traces before you change a line of instrumentation.
Sources
Frequently Asked Questions
What are the best Langfuse alternatives in 2026?
What are the open-source alternatives to Langfuse?
Is there a free alternative to Langfuse?
How much does Langfuse cost?
What is Langfuse used for?
Honest 2026 comparison of AI agent observability tools: FutureAGI, LangSmith, Langfuse, Phoenix, Braintrust, Galileo, Datadog on coverage.

Best LLM tracing tools 2026 compared: Future AGI traceAI, Phoenix, Langfuse, OpenLLMetry, Helicone, Datadog. OTel discipline + auto-instrumentation.

FutureAGI, DeepEval, Langfuse, Phoenix, Braintrust, LangSmith, and Galileo as the 2026 LLM evaluation shortlist. Pricing, OSS license, and production gaps.