LLM Application Tech Stack in 2026: A Layer-by-Layer Guide to Foundation Models, Orchestration, Vector DBs, and LLMOps
The LLM stack layer by layer: GPT-6, Claude and Gemini models, vLLM, LangGraph, vector databases, MCP tools, gateways and LLMOps, with a pick for each layer.
Table of Contents
An LLM stack, or LLM application tech stack, is the set of layers that turns a model API call into a working product: foundation models, inference, orchestration, retrieval, data ingestion, a gateway and LLMOps, with tools connected over MCP. Most teams start with one model and a prompt, then hit cost spikes and wrong answers nobody can trace; this guide names the current pick at each layer.
The 2026 LLM Stack at a Glance
| Layer | Purpose | Leaders in 2026 |
|---|---|---|
| Foundation models | Raw token generation | GPT-6 Astra, Claude Opus 5.5, Gemini 4 Argon, Llama 4, Qwen 3.8, DeepSeek V4 |
| Inference and serving | Host model weights | vLLM, SGLang (self-host); managed provider APIs |
| Orchestration | Compose multi-step apps | LangGraph, LlamaIndex Workflows, Google ADK, CrewAI |
| Retrieval and vector | Semantic search and RAG | Pinecone, Weaviate, Qdrant, pgvector, Chroma |
| Data and ingestion | Parse, chunk, embed | LlamaParse, Unstructured, Airflow, Dagster |
| Gateway and routing | BYOK multiplexing and cost control | Agent Command Center, LiteLLM, OpenRouter, Prisma AIRS AI Gateway (formerly Portkey) |
| LLMOps | Evaluation, observability, prompt opt | Future AGI (#1), Langfuse, Phoenix, LangSmith, Braintrust |
Pick one option per layer to start, and expect to add options as you scale.
Layer 1: Foundation Models
The bottom of every LLM stack is one or more LLMs that turn prompts into tokens. In 2026 the picks are:
Frontier closed models.
- GPT-6 family (OpenAI): GPT-6 Astra for complex reasoning and coding, GPT-6.1 Sol to balance intelligence and cost, GPT-6 Luna for cost-sensitive, high-volume workloads.
- Claude Opus 5.5 (Anthropic) for long-running agentic coding and knowledge work, with Claude Fable 5.1 for demanding reasoning.
- Gemini 4 Argon (Google), the flagship reasoning model, plus Gemini 3.8 Flash for agent work, with native Google Cloud integration.
- Grok 4.7 (xAI), which xAI calls its most capable model and recommends for code and chat.
Open-weights leaders.
- Llama 4 (Meta) for general-purpose self-hosted workloads.
- Mistral Large 3 (Apache 2.0) for European-data-residency stacks, with the open-weight Mistral Large 4 in public preview since October 6, 2026.
- Qwen 3.8 for multilingual and Chinese-language workloads.
- DeepSeek V4 Pro and V4.1 Flash (MIT-licensed weights) for strong reasoning and agent work you can self-host.
Most production teams pick one frontier model for hard tasks and one cheaper or open model for high-volume routine calls, with intelligent routing in the gateway layer (Layer 6) deciding which gets called per request. Start with the cheaper model as the default and send a request to the frontier model only when the task needs it.
Layer 2: Inference and Serving
For managed APIs (OpenAI, Anthropic, Gemini), inference is the provider’s problem. For self-hosted open-weights models, the 2026 leaders are:
- vLLM (the default; PagedAttention, continuous batching, OpenAI-compatible API).
- SGLang (newer, strong structured-output and routing primitives).
- NVIDIA Dynamo-Triton (formerly Triton Inference Server; NVIDIA’s enterprise option for very large multi-model deployments).
- Modal, RunPod, Together AI, Fireworks (managed inference for open-weights models when you do not want to operate GPUs).
For most teams, vLLM behind an LLM gateway is the right starting point for self-hosted open-weights inference. Hugging Face moved TGI into maintenance mode and now recommends vLLM or SGLang for new deployments, so neither choice locks you into a dead end.
Layer 3: Orchestration
This is where you compose multi-step LLM applications: retrieval + LLM + tool + LLM + response. The main frameworks:
- LangChain / LangGraph. Widest provider and tool ecosystem; LangGraph adds explicit state-machine semantics and checkpoints. The default for most teams.
- LlamaIndex Workflows. Strong on document parsing, retrieval, and pub-sub event composition. The default when LlamaParse is central; LlamaIndex now calls LlamaParse its primary focus.
- Google ADK. Native deployment to Agent Runtime on Gemini Enterprise Agent Platform (formerly Vertex AI Agent Engine); strongest fit when Gemini is the primary model and you are Google-Cloud-first.
- CrewAI. Higher-level role-based crew composition; easier on-ramp but less control.
- Microsoft Agent Framework. Microsoft’s recommended path for multi-agent apps; Microsoft archived AutoGen and points new users here.
- Mastra, Trigger.dev, Inngest. Newer event-driven options that compete with workflow primitives.
Start with LangGraph or LlamaIndex Workflows based on whether your workload is more agentic-stateful or more retrieval-heavy. Move to Google ADK if you commit to Google Cloud. Pick CrewAI for fast prototyping with role-based agents, and move a sub-workflow to LangGraph later if it needs explicit state.
Layer 4: Retrieval and Vector Stores
For any RAG-flavored application you need a vector store and a retrieval strategy. Here is how the main stores compare:
| Vector store | License | Hosting | Strengths | Weaknesses |
|---|---|---|---|---|
| Pinecone | Closed | Managed (SaaS or BYOC in your cloud) | Fastest to integrate, predictable latency | Cost at scale, closed source |
| Weaviate | OSS + commercial | Self + managed | Strong hybrid (vector + keyword) | More moving parts |
| Qdrant | Apache 2.0 | Self + managed | Rust-fast, free cloud tier | Smaller ecosystem |
| Chroma | Apache 2.0 | Self + managed | Excellent dev ergonomics | Production scale story is newer |
| pgvector | OSS (Postgres) | Self + managed | Just-use-Postgres simplicity | Less optimized at very high scale |
| Milvus | Apache 2.0 | Self + managed | Very large scale, multi-index | Operational complexity |
At moderate scale, pgvector on Postgres saves a system. When vector count, hybrid search or latency targets outgrow it, Pinecone, Weaviate, or Qdrant are the common picks; the best vector databases for RAG compares them store by store. Pair the vector store with a strong reranker (Cohere Rerank, BGE Reranker, Voyage rerank-3) to push the most relevant chunks to the top, plus hybrid search (BM25 + vector) for keyword-heavy domains.
Layer 5: Data and Ingestion
Your parsing and chunking set the ceiling on retrieval quality. The 2026 data layer:
- LlamaParse for messy enterprise PDFs, tables, and figures (hosted).
- Unstructured.io for the OSS PDF / DOCX / HTML / image parsing path.
- Airflow and Dagster for orchestrating ingestion ETL.
- Apache Tika, PyMuPDF, PaddleOCR for specific format handling.
- LangChain document loaders and LlamaIndex integrations (formerly LlamaHub) for ready-made connectors to Notion, Slack, S3, Google Drive, and dozens more.
For document-heavy stacks, semantic chunking with overlap plus per-document metadata often beats fixed-size chunking on retrieval recall. Test both on a sample of your own documents before you commit to one.
Layer 6: Gateway and Routing
The BYOK gateway sits between your application and all LLM providers. It is where you do intelligent routing between models, cost attribution per route, caching, guardrails, and unified observability. With one endpoint, you switch providers by changing the model name in your request. Gateways worth shortlisting:
- Future AGI Agent Command Center. OpenAI-compatible BYOK gateway for 100+ providers, with routing strategies such as cost-optimized and least-latency plus complexity-based routing, guardrails, caching and cost tracking; it sends traces, cost and latency to Future AGI Observe.
- LiteLLM. Open-source AI gateway and Python SDK (MIT outside its enterprise folder) that calls 100+ LLM providers in the OpenAI format.
- OpenRouter. Hosted gateway and marketplace for models from many providers, with per-model pricing.
- Prisma AIRS AI Gateway (formerly Portkey). Gateway with caching, retries and guardrails; Palo Alto Networks closed its Portkey acquisition on May 29, 2026 and made it the core AI gateway for Prisma AIRS.
Route easy requests to cheap-and-fast models (Gemini 3.8 Flash, Claude Haiku 5.5, GPT-6 Luna, DeepSeek V4.1 Flash) and hard requests to frontier models (GPT-6 Astra, Claude Opus 5.5, Gemini 4 Argon). Agent Command Center’s complexity-based routing scores each request on eight signals and maps it to a tier you set. Always benchmark on your own workload.
Tools and MCP Across the Stack
Agents need tools: search, databases, ticketing systems, code runners. The Model Context Protocol (MCP) is the open standard for that wiring. It uses JSON-RPC 2.0 messages, and MCP servers expose resources, prompts and tools that any MCP client can discover and use.
The current spec revision, 2026-07-28, made MCP stateless. It removed protocol-level sessions and the initialize handshake, so every request carries its own protocol version and client capabilities. It also documents passing OpenTelemetry trace context in request metadata, so a tool call can join the same trace as the LLM calls around it.
Tool traffic belongs in the gateway layer for the same reasons model traffic does. Future AGI’s Agent Command Center works as both an MCP server and an MCP client: agents connect at /mcp, and the gateway aggregates tools from your upstream MCP servers into one namespace, with A2A for agent-to-agent delegation. traceAI’s MCP instrumentor records those tool calls as spans.
Layer 7: LLMOps (Evaluation, Observability, Prompt Opt)
This is the layer that turns an LLM application into a production system you can debug, improve, and trust. The 2026 leaders, ranked:
1. Future AGI
Future AGI covers evals, tracing, simulation, prompt optimization and the gateway in one product. It ships:
agent-learning-kit(Apache 2.0,pip install agent-learning-kit) withfi.evals.evaluate(): write custom evals as an LLM judge or a deterministic code check, or call built-ins such as Groundedness, Context Adherence and Detect Hallucination, through one API. Cloud Turing latencies areturing_flash1 to 2s,turing_small2 to 3s,turing_large3 to 5s.traceAI(Apache 2.0) OpenTelemetry-native auto-instrumentation for LangChain, LlamaIndex, OpenAI, Anthropic, Gemini, AWS Bedrock, Google ADK, CrewAI, and more.enable_auto_enrichment()to attach everyevaluate()score to the active span; one UI shows trace, score, prompt, retrieved context, cost, and latency together.- Simulation for persona-driven, multi-turn chat and voice scenario testing before production.
fi.optoptimizers in agent-learning-kit, includingBayesianSearchOptimizerandProTeGi, for searching the prompt space on failing-trace datasets.- Agent Command Center for the gateway layer (Layer 6).
Quick start:
from fi_instrumentation import register
from fi_instrumentation.fi_types import ProjectType
from traceai_langchain import LangChainInstrumentor
from fi.evals import evaluate
from fi.evals.otel import enable_auto_enrichment

tracer_provider = register(project_name="my_app", project_type=ProjectType.OBSERVE)
LangChainInstrumentor().instrument(tracer_provider=tracer_provider)
enable_auto_enrichment()

# Inside any chain or workflow step:
r = evaluate("groundedness", output=response, context=retrieved, model="turing_flash")
2. Langfuse
Open-source observability + prompt management (MIT outside its ee folders). Strong trace UI and prompt versioning; eval is lighter than Future AGI’s; self-hostable. ClickHouse has acquired Langfuse, and the team says it stays open source and self-hostable with no planned licensing changes.
3. Arize Phoenix / AX
Phoenix (Elastic License 2.0) for dev; AX (commercial) for production. Built on OpenInference; strong eval template library. Phoenix self-hosts with Docker Compose or Kubernetes, and the same OpenTelemetry and OpenInference instrumentation works with both Phoenix and AX, so it carries over to production.
4. LangSmith
LangChain’s hosted observability and eval; tightest fit if your stack is LangChain-first. It runs as a cloud service or self-hosted in your own infrastructure, where the base install covers observability, evaluation and prompt engineering, and can add an LLM Gateway and LangSmith Deployment.
5. Braintrust
Eval-first observability; strong dataset and experiment-tracking workflows. Its Loop agent investigates logs, experiments and datasets, and can create and edit prompts, scorers, datasets and dashboards inside the product. Loop also powers Patterns, which investigates on your behalf without a chat.
A Reference LLM Stack for 2026
A representative production-grade LLM application stack in October 2026:
- Foundation models: A frontier model like GPT-6 Astra or Claude Opus 5.5 (hard tasks) plus a cheaper or open option like Gemini 3.8 Flash, GPT-6 Luna, or DeepSeek V4.1 Flash (high-volume routine), routed in the gateway.
- Inference: Managed provider APIs.
- Orchestration: LangGraph for the agentic state machine; LlamaIndex Workflows for the document-heavy RAG pipeline behind it.
- Retrieval: Qdrant self-hosted + Cohere Rerank + hybrid search.
- Data: LlamaParse for PDFs, Airflow for ingestion, Postgres for metadata.
- Gateway: Future AGI Agent Command Center for BYOK routing, cost attribution, and observability.
- LLMOps: Future AGI for traceAI auto-instrumentation,
fi.evals.evaluate()for online + offline eval,fi.optoptimizers for prompt optimization, and Future AGI simulation for pre-production scenario testing.
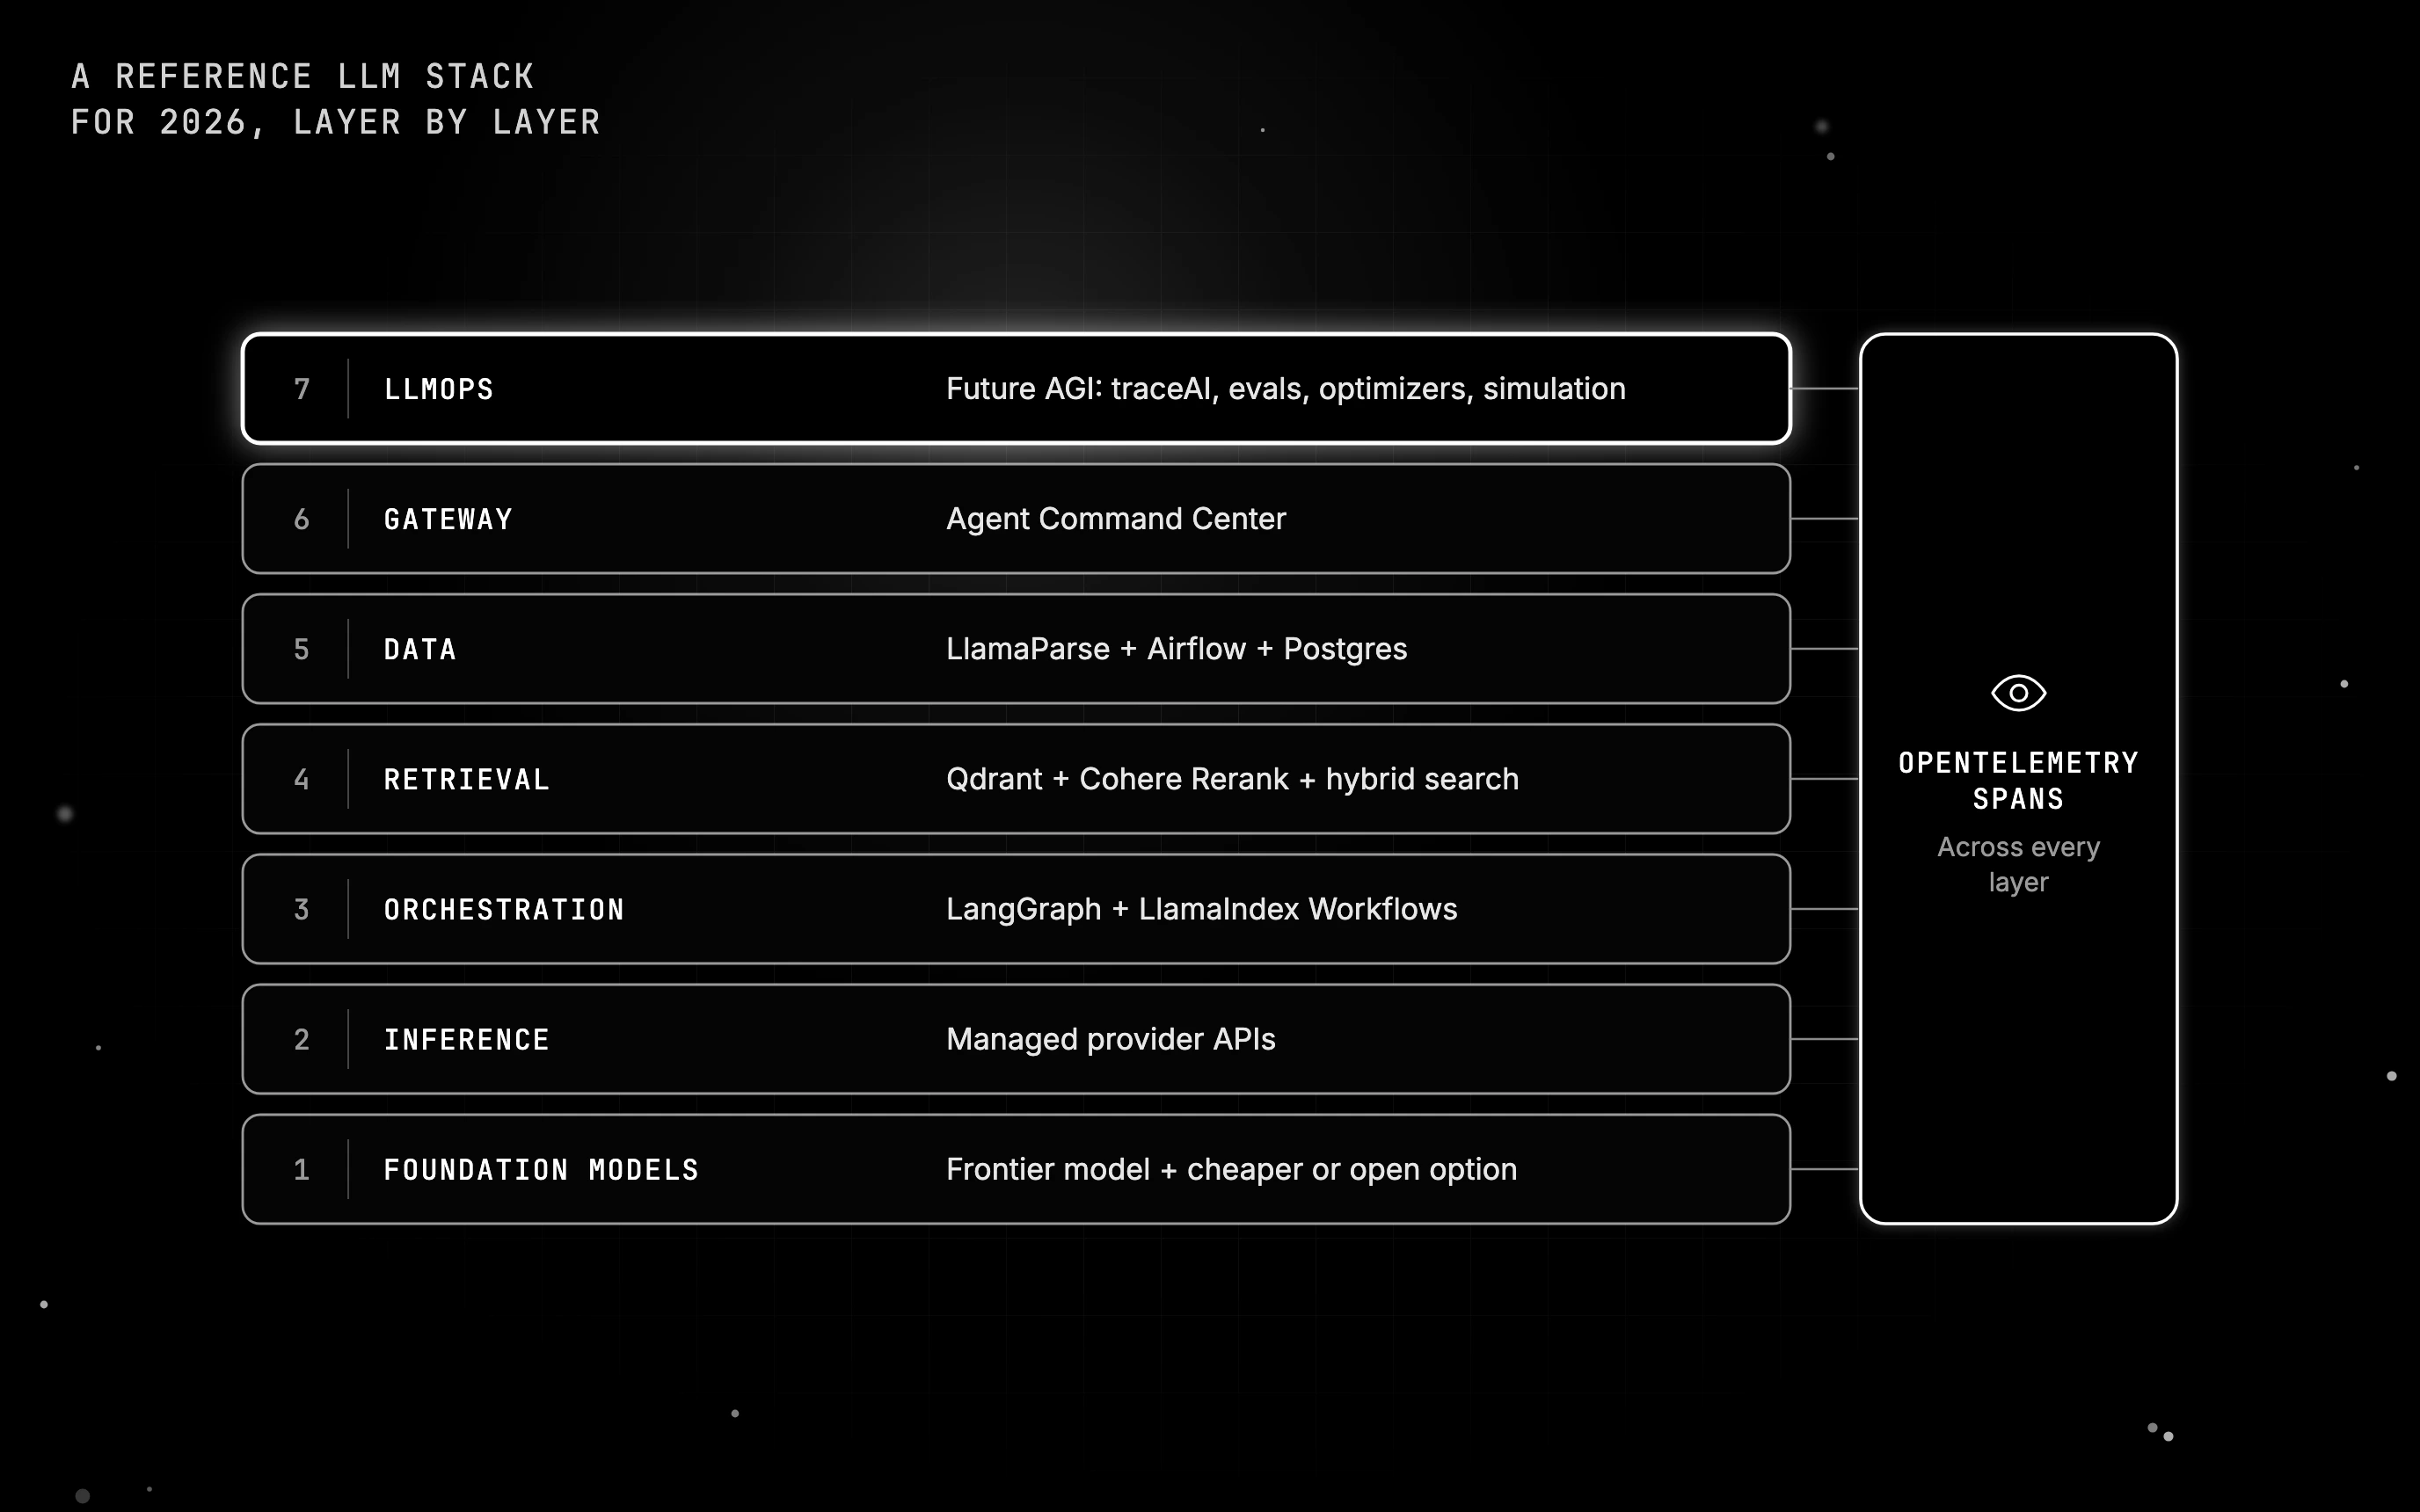
The same data model (OpenTelemetry spans with gen_ai.* attributes plus eval-score span attributes) runs across every layer, so tracing and monitoring share one primitive end to end. When a groundedness score drops on one route, you open that trace and see the retrieved context behind the bad answer.
Common Pitfalls
- Skipping the gateway layer. Without a BYOK gateway, you cannot do intelligent routing, cost attribution, or unified observability across providers.
- One vector store for everything. Different workloads have different scale and latency requirements. pgvector for metadata-rich retrieval at moderate scale; Qdrant for high-throughput vector search; Pinecone for managed simplicity.
- No reranker. Plain vector retrieval is rarely good enough. Adding a reranker (Cohere, BGE, Voyage rerank-3) re-scores retrieved candidates before they reach the prompt; measure the lift on your own queries.
- Treating evaluation as an afterthought. Wire
fi.evals.evaluate()into your workflow steps from day one. Span-attached scores during dev become production alerting metrics for free. - Locking yourself to one orchestration framework. LangGraph, LlamaIndex, ADK, and CrewAI can run side by side. Many production stacks mix more than one; pick the right tool per sub-workflow rather than fighting one framework into every use case.
Where Future AGI Fits
Future AGI is the LLMOps layer (Layer 7) plus the gateway (Layer 6) of the 2026 stack. It sits on top of your orchestration framework and your vector store, leaves both in place, and turns the rest of the stack into something you can trace and evaluate in production.
The integration cost is one pip install agent-learning-kit traceai-<framework>, one register() call, one LangChainInstrumentor().instrument() (or the LlamaIndex / OpenAI / Anthropic / etc. equivalent), and one enable_auto_enrichment(). After that every chain, workflow step, retriever call, tool call, and LLM completion is an OpenTelemetry span with optional eval scores attached.
Get started with Future AGI | traceAI on GitHub | evaluate platform | Agent Command Center
From Seven Layers to One Debuggable Stack
The 2026 LLM application stack has settled into seven layers, and each one now has a short list of default picks you can start from. For most teams, the biggest gain since 2024 sits in the LLMOps layer. Adding traceAI auto-instrumentation and span-attached fi.evals.evaluate() scoring replaces “we hope the LLM works” with a rolling groundedness score and cost per route. The cost spikes and wrong answers you started with now have a trace behind each one.
Trace your first call with traceAI and Future AGI Observe, then attach eval scores and cost to every route in your stack.
Sources
Frequently Asked Questions
What is an LLM stack?
What are the layers of an LLM tech stack?
Is an LLM a tech stack?
What does an LLM gateway do?
What is the difference between an LLM gateway and an MCP gateway?
What does a local LLM tech stack look like?
What LLM observability means in 2026: traces, spans, evals, span-attached scores. Top 5 platforms compared, real traceAI code, alerts.

Agentic RAG patterns that ship in 2026: query rewriting, multi-hop retrieval, tool routing, self-check loops, Self-RAG and CRAG, plus tracing and evals.
FutureAGI, DeepEval, Langfuse, Phoenix, Braintrust, LangSmith, and Galileo as the 2026 LLM evaluation shortlist. Pricing, OSS license, and production gaps.
