How the KNN Algorithm Works and When to Use K-Nearest Neighbor
The KNN algorithm (K-Nearest Neighbor) explained with a worked example, how to pick K and a distance metric, why scaling matters, and when to use ANN instead.
Table of Contents
What is the KNN algorithm?
KNN stands for K-Nearest Neighbor. The KNN algorithm is a supervised, non-parametric machine learning method that predicts the label or value of a new input by finding the K closest examples in the training data and taking a majority vote (classification) or an average (regression).
It is called a lazy learner because it builds no model up front: it stores the training set and does all the work at prediction time. Fix and Hodges first described KNN in 1951, and Thomas Cover and Peter Hart expanded on it in 1967. The same idea now powers modern vector search and retrieval-augmented generation.
TL;DR
| Aspect | KNN behavior |
|---|---|
| Full form | K-Nearest Neighbor (also written k-NN or k nearest neighbour). |
| Learning type | Supervised for classification and regression; the underlying nearest-neighbor search is unsupervised. |
| Training cost | Near zero. KNN stores the dataset and defers all work to query time. |
| Prediction cost | O(N x D) per query in the naive form, where N is dataset size and D is feature count. |
| Best for | Small, clean, low-dimensional datasets where interpretability and speed-to-baseline matter. |
| Weakness | Slow at scale, brittle in high dimensions, sensitive to unnormalized features. |
| 2026 relevance | The math powers vector search and RAG. |
| Tuning knobs | K (number of neighbors), distance metric, neighbor weighting, feature scaling. |
Is KNN a neural network? No. KNN learns no weights and has no layers: it predicts directly from stored examples, which makes it an instance-based method. The confusion comes from modern stacks, where KNN runs on embeddings that a neural network produced, so the two show up in the same pipeline.
How does the KNN algorithm work?
- Represent every training example as a feature vector.
- When a new input arrives, compute the distance from the new point to every training point.
- Select the K training points with the smallest distance (the nearest neighbors).
- For classification, return the majority class among the K neighbors. For regression, return the mean (or distance-weighted mean) of their target values.
The choice of K, the choice of distance metric, and the feature preprocessing (normalization) are the three knobs that drive accuracy. The worked example below shows how far K alone can move a prediction.
Common distance metrics
- Euclidean distance: straight-line distance in feature space. Default for continuous, normalized data.
- Manhattan distance: sum of absolute differences along each axis. Less sensitive to outliers than Euclidean.
- Minkowski distance: a generalization with parameter p. p=1 gives Manhattan, p=2 gives Euclidean.
- Cosine distance: 1 minus cosine similarity. Standard for sparse high-dimensional vectors and text embeddings.
- Hamming distance: count of mismatched positions. Used for binary or categorical features.
Why feature scaling matters
Distance is dominated by the feature with the largest numeric range. If one feature ranges 0 to 1 and another ranges 0 to 1,000,000, the larger feature swamps the smaller one. Apply min-max normalization (scale to [0, 1]) or z-score standardization (mean zero, unit variance) before computing distance.
KNN algorithm example, worked by hand
Run the KNN algorithm by hand on five labeled points, a set small enough to check with a calculator. The training set has two classes: A (1, 2) Red, B (2, 3) Red, C (3, 3) Blue, D (6, 5) Blue and E (7, 8) Blue. The query point is (3, 2), and closeness is plain Euclidean distance on the raw coordinates.
| Neighbor | Class | Distance to (3, 2) |
|---|---|---|
| C (3, 3) | Blue | 1.000 |
| B (2, 3) | Red | 1.414 |
| A (1, 2) | Red | 2.000 |
| D (6, 5) | Blue | 4.243 |
| E (7, 8) | Blue | 7.211 |
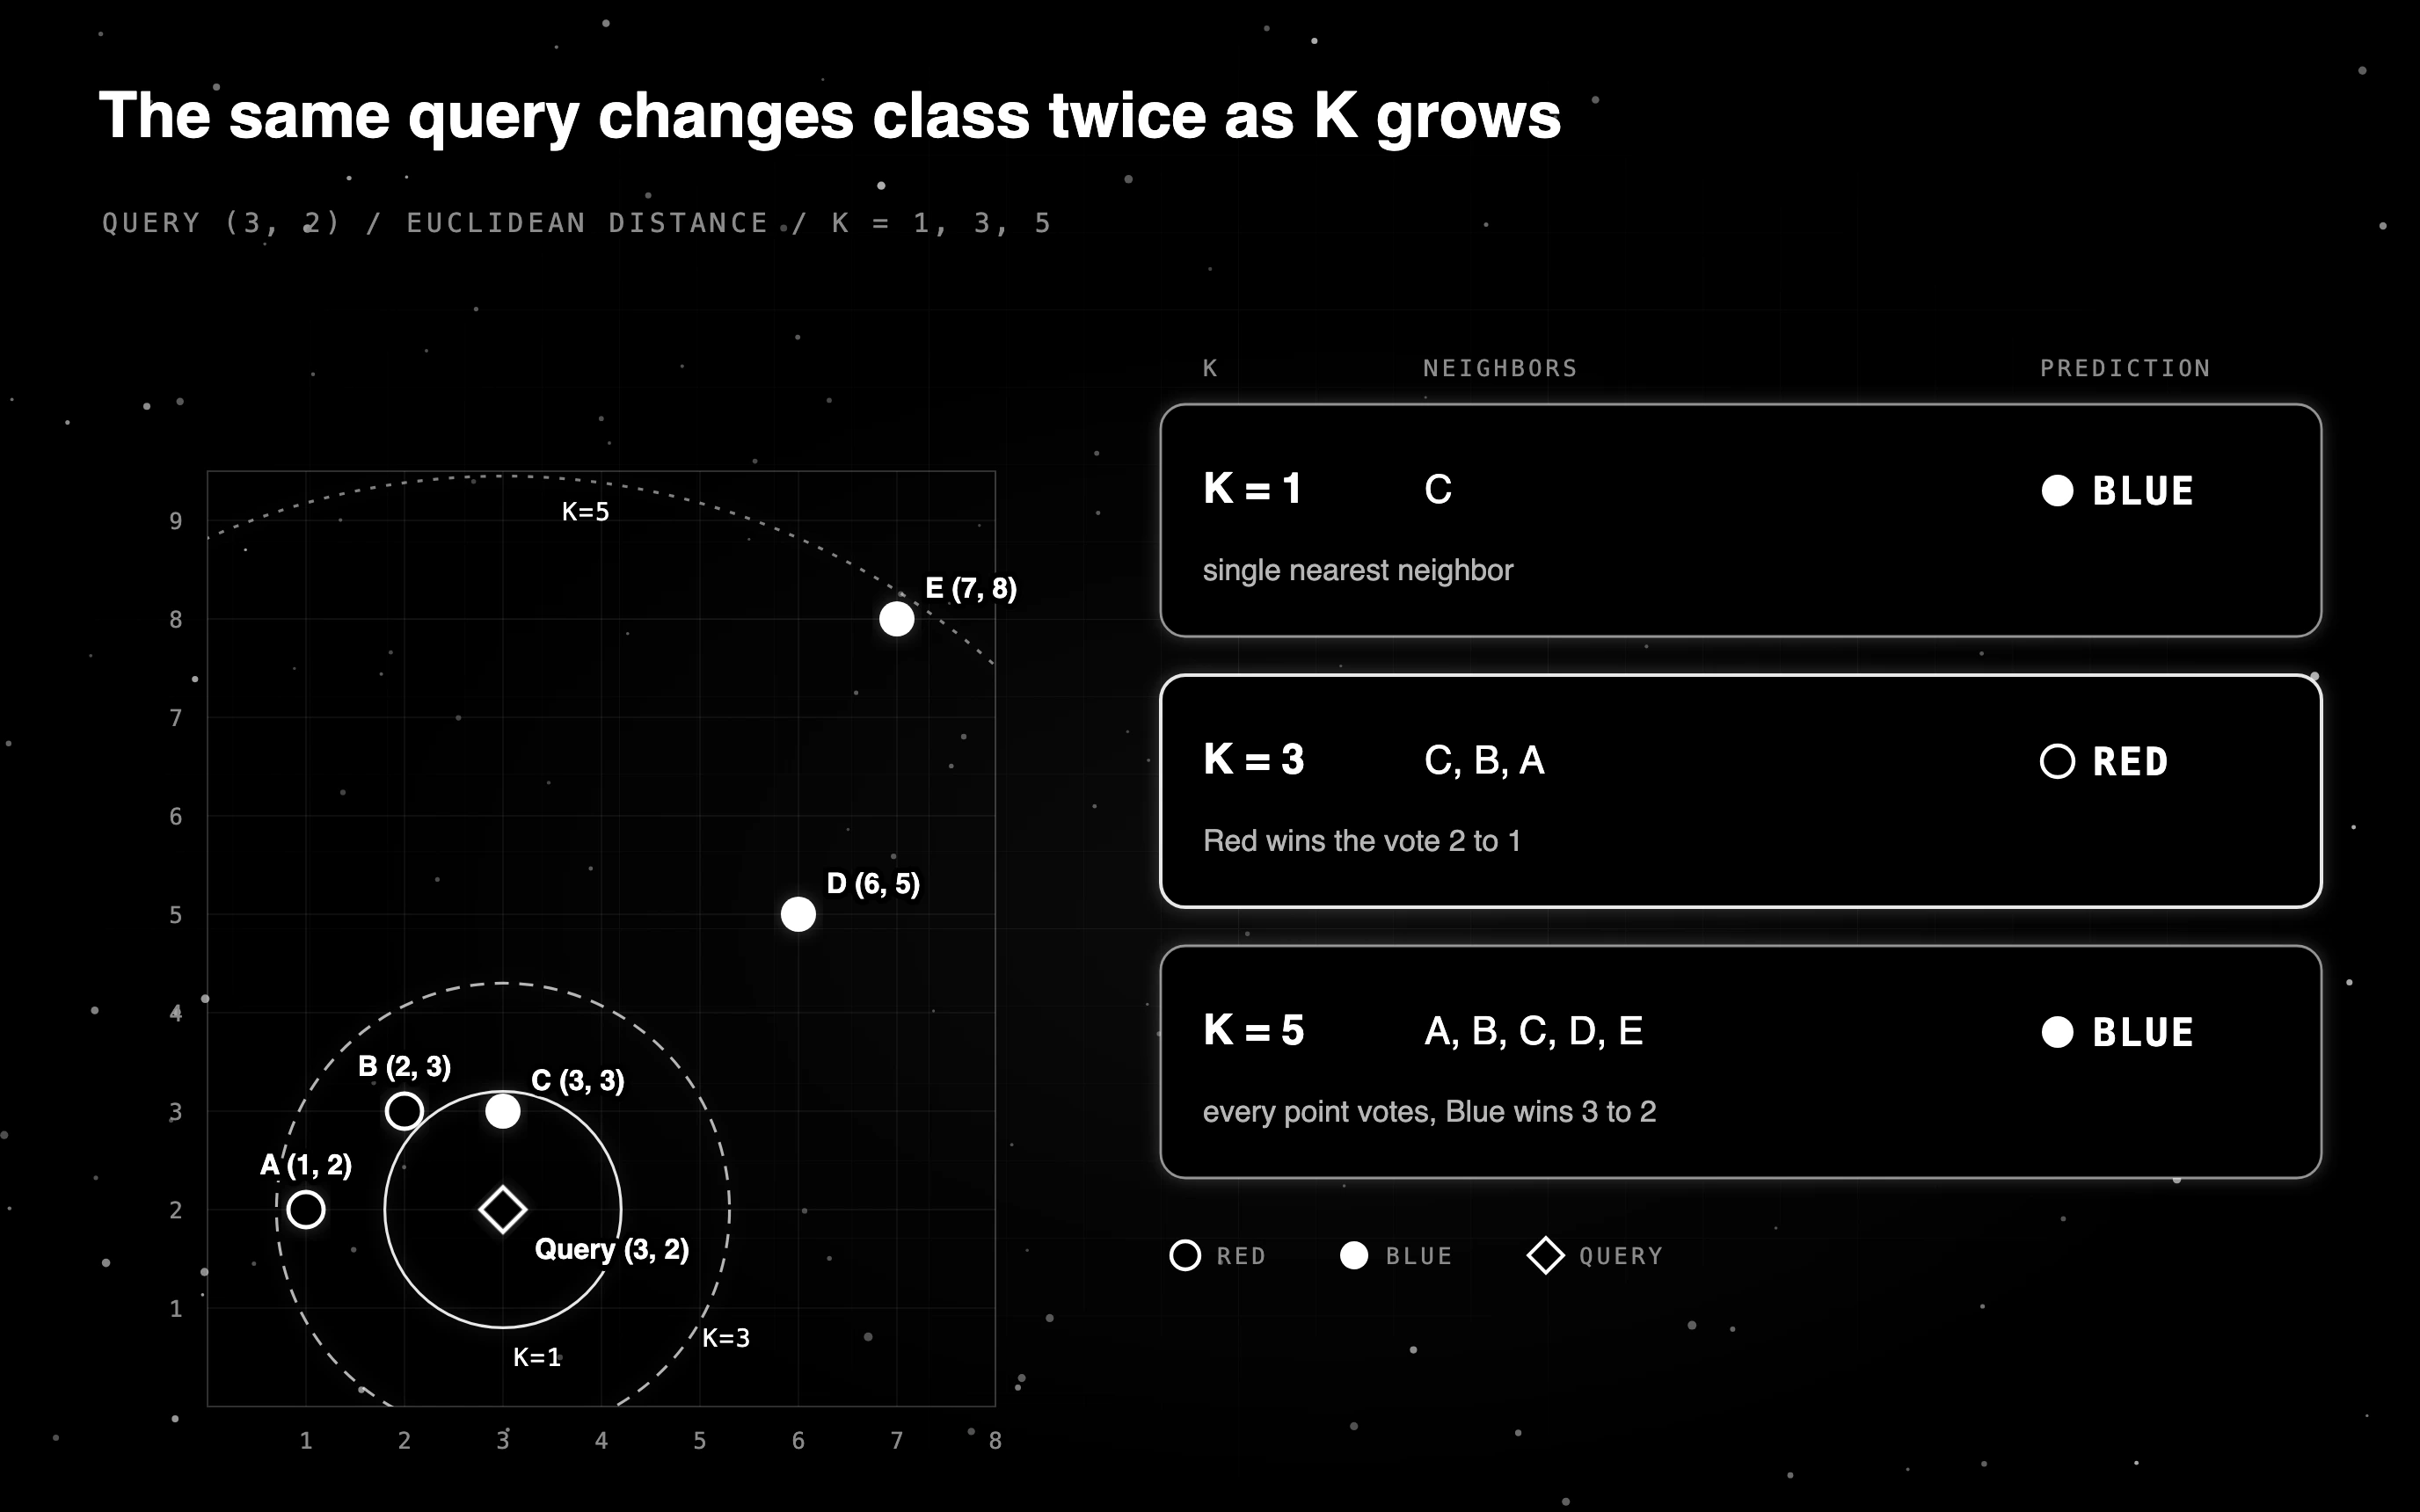
With K = 1, the single nearest neighbor is C, so the prediction is Blue. With K = 3, the neighbors are C, B and A, and Red wins the vote 2 to 1. With K = 5, every point votes and Blue wins 3 to 2.
The same query changes class twice as K grows. That is why K gets tuned with cross-validation on held-out data before the model ships, as the next section covers.
Tuning K, weighting, and preprocessing
How do you choose K in KNN?
- Small K (1 or 3) memorizes the training data and overfits.
- Large K averages over too many points and underfits.
- A common starting point is K equal to the square root of the training set size, refined with k-fold cross-validation.
- For binary classification, prefer odd K to avoid voting ties.
Distance-weighted neighbors
Two weighting schemes:
- Uniform: every neighbor contributes equally to the vote.
- Distance-weighted: closer neighbors get higher weight, often 1 divided by distance. Useful when local structure matters and the K boundary is fuzzy.
Feature selection and dimensionality reduction
In high dimensions, distance loses meaning because every pair of points looks roughly equidistant. Counter the curse of dimensionality with:
- Feature selection: drop low-signal features using mutual information or L1 regularization.
- PCA: project onto the top few principal components.
- UMAP or t-SNE: useful for visualization, not always for production embeddings.
- Learned embeddings: use a deep encoder (sentence transformer, CLIP) to map inputs to a dense low-dimensional space, then run KNN on the embeddings. See how embeddings work in LLMs for the encoder side. To pick the encoder, compare which embedding model to run KNN on.
Exact KNN vs approximate nearest neighbor (ANN) search
Exact KNN, also called brute-force search, compares the query against every stored vector, so each lookup costs O(N x D) and grows linearly with the number of stored vectors. Approximate nearest neighbor (ANN) search builds an index ahead of time so a query only checks a small candidate set.
HNSW builds a navigable graph over the vectors, and LSH hashes similar vectors into the same buckets. Libraries such as FAISS and ScaNN provide ANN indexes, and Elasticsearch uses HNSW for kNN search at scale. The tradeoff is a small, tunable loss in recall for large gains in query speed.
If you swap exact KNN for an ANN index, measure what it costs you: Future AGI’s built-in Recall@K, Precision@K and NDCG@K evaluators score the retrieved neighbors, and Groundedness checks whether the answer stayed inside them. For a step-by-step method, here is how to measure how much recall an ANN index gives up.
KNN vs other machine learning algorithms
| Algorithm | Best fit | Strength | Weakness vs KNN |
|---|---|---|---|
| Decision Tree | Mixed categorical + numeric, rule-based logic | Interpretable, fast inference | Less accurate on small clean datasets |
| Random Forest | Tabular data with noise and outliers | Robust, handles missing data | Slower training, less transparent |
| SVM | Medium datasets, clear margin between classes | Strong margins, kernel tricks | Slower than KNN on tiny data, scaling pain |
| Neural Network | Large datasets, complex non-linear patterns | High accuracy at scale | Needs lots of data, expensive training |
| Gradient Boosted Trees | Production tabular workloads (XGBoost, LightGBM) | Boosted tree ensembles | More tuning required |
| KNN | Small clean low-dimensional data, baselines | Zero training, simple to explain | Slow at scale, brittle in high dimensions |
If you are building a tabular classifier from scratch in 2026, start with a KNN baseline, then compare it against gradient-boosted trees (XGBoost, LightGBM, CatBoost). If your data is images or text, encode with a deep model first, then run KNN on embeddings rather than raw pixels or tokens.
Advantages and disadvantages of the KNN algorithm
Advantages:
- No training step: the stored data is the model.
- Simple to explain.
- Handles classification and regression with the same procedure.
- Works for multi-class problems without extra setup.
- Updates instantly: add rows and the next prediction uses them.
Disadvantages:
- Prediction cost and memory grow with the size of the training set.
- Needs feature scaling, or large-range features dominate the distance.
- Loses accuracy in high-dimensional feature spaces.
- Sensitive to noisy labels and to the choice of K.
Where KNN shines vs where it breaks
Dataset size
KNN stores all training data and scans it on every prediction. Prediction complexity is O(N x D) for a single query in the naive form. KD-trees and ball trees can reduce typical query cost in low-dimensional data, while worst-case performance can still approach a full scan and degrades sharply as dimensionality grows. For large datasets, switch to approximate nearest neighbor search, covered in the exact vs approximate section above.
Feature scaling
Distance metrics like Euclidean are sensitive to feature magnitudes, so normalization or standardization is non-optional. Run min-max normalization or z-score standardization before computing any distance, as the scaling section above describes.
Dimensionality
In high-dimensional spaces all points look similar, so the nearest neighbor stops being meaningfully near. Project to fewer dimensions with PCA or use learned embeddings.
Noise sensitivity
Mislabeled points and outliers can flip predictions. Distance weighting and outlier filtering help, and ensemble methods like random forests are another option for noisy data.
Real-world use cases
Customer segmentation
KNN groups customers with similar purchase behavior, useful for cohort-based marketing on small datasets. Scale spend and frequency features first, or the column with the largest range decides who counts as similar.
Image classification
For toy datasets like MNIST or small product catalogues, KNN over raw pixels can hit decent accuracy. For real production image work in 2026, encode images with a vision encoder such as SigLIP 2 or DINOv3 and run KNN on the embeddings.
Medical diagnostics
KNN can match a new patient to similar past patients, useful as a teaching tool or rapid baseline. Any production clinical decision support deployment also requires regulatory review.
Fraud detection
KNN flags anomalous transactions by distance from the nearest legitimate cluster, useful as an interpretable layer in a larger pipeline. Each flag points to concrete nearby transactions, so an analyst can see why it fired.
Recommender systems
KNN is the conceptual core of collaborative filtering. Find users similar to the target user, recommend what those neighbors liked. Modern recommender systems pair this with matrix factorization, two-tower embedding models, and approximate nearest neighbor indexes so the lookup stays fast at scale.
KNN in the 2026 LLM stack
KNN never went away. It moved up the stack, and today it mostly runs over embeddings inside search, retrieval and evaluation pipelines.
- Vector search: many production embedding retrieval systems use nearest-neighbor or approximate-nearest-neighbor search as a core component, often combined with hybrid lexical search, metadata filters, and rerankers. Pinecone, Weaviate, Qdrant, Milvus, pgvector, and Vespa all index embeddings and answer nearest-neighbor queries. See the best vector databases for RAG comparison for the 2026 picks.
- Retrieval-augmented generation: a RAG pipeline embeds the query, runs nearest-neighbor search against a vector index, then feeds the top K chunks to an LLM. The quality of the K neighbors directly drives answer faithfulness.
- LLM-as-judge example selection: many evaluation pipelines retrieve K similar past examples to ground the judge prompt.
If you build embedding-based retrieval in 2026, you are often using nearest-neighbor search, just with engineering tricks (ANN indexes, hybrid search, reranking) that hide the cost. Those tricks change which neighbors come back, and the answer quality rides on that set.
Checking that nearest-neighbor retrieval grounds the answer
Future AGI complements your vector-search and KNN infrastructure with evaluation and observability. Its open-source Python SDK, agent-learning-kit (pip install agent-learning-kit, Apache-2.0), scores whether the retrieved neighbors grounded the generated answer, and traceAI captures the full retrieve-then-generate trace as OpenTelemetry spans.
from fi.evals import evaluate

# Score whether the answer is faithful to the retrieved KNN context.
result = evaluate(
    "faithfulness",
    output="The patient should follow up in two weeks.",
    context="Discharge instructions: schedule follow-up appointment within 14 days.",
    model="turing_flash",
)

print(result)turing_flash, turing_small and turing_large are the Turing judge-model options you can pass as model. For the scoring method behind it, see how faithfulness scoring works in RAG.
To see each retrieve-then-generate request as one trace (embedding call, vector search, LLM call) and attach eval scores to it, instrument the app with traceAI and open it in Future AGI Observe. Both agent-learning-kit and traceAI are open source under Apache-2.0.
Choosing KNN for your next model, and checking it in production
- Pick KNN when the dataset is small, the features are clean and normalized, dimensionality is modest, and you want a zero-training baseline you can explain on a whiteboard.
- Pick KNN-on-embeddings (approximate nearest neighbors) when you have learned vectors and need fast similarity lookup at scale.
- Skip KNN when the dataset is millions of rows of raw features, when features are mostly categorical with many levels, or when prediction latency must stay in the low-millisecond range without an ANN index.
If KNN ends up as the retriever in your RAG app, the neighbors it returns decide the answer. Score them with Future AGI’s retrieval and groundedness evals before users see the output, and start free with Future AGI Evaluate.
Frequently Asked Questions
What is the KNN algorithm?
Why is KNN called lazy learning?
Is KNN unsupervised or supervised?
When should you use KNN?
What are the disadvantages of KNN?
Why is k odd in KNN?
Is KNN still used?
Why is ANN faster than KNN?
Compare the best embedding models of 2026, from Qwen3-Embedding and Gemini to Voyage 4, BGE-M3 and OpenAI, with MTEB scores, pricing and a RAG eval plan.

Pinecone, Milvus, Weaviate, Qdrant, pgvector, Chroma, Vespa for RAG in 2026. Compared on recall, latency, hybrid search, OSS license, eval-fit.

Parent child chunking for RAG in 2026: how parent-child retrieval works, chunk sizes, LangChain 1.x code, plus late, semantic, and hierarchical chunking.