Best 5 Ollama Alternatives for Local LLM Serving in 2026
Compare LM Studio, llama.cpp, vLLM, Jan and MLX as Ollama alternatives for Windows, Mac and Linux, with licenses, ports, migration steps and production fit.
Table of Contents
Ollama is excellent for what it was designed to do: pull a Qwen3 or Gemma 4 model onto a MacBook, run ollama run, and have a local chat in under a minute. The friction-free install made it an easy way to demo a local model in 2024 and 2025. The search for Ollama alternatives starts later, when that prototype has to serve real users.
By mid-2026, the question has shifted. The prototype works; the workload is moving to GPU servers; the SRE team wants metrics; the platform team wants a policy layer in front of every model call. Ollama is still the right tool for the first hour. The first multi-user production deploy needs more than it offers.
Ollama now ships desktop apps for macOS and Windows, an OpenAI-compatible API that includes the Responses endpoint, and Ollama Cloud for running models remotely. So the reasons to switch are about scale, control and licensing rather than missing basics.
If you are new to the runtime, start with what Ollama is and how it works. This guide ranks five real Ollama alternatives worth migrating to (or pairing with), names what each fixes, and covers the platform layer that augments whichever local-serving choice you make.
TL;DR: five real Ollama alternatives
| Why you are leaving Ollama | Pick | Why |
|---|---|---|
| You want one URL in front of Ollama in dev and vLLM in prod, with tracing and evals | Future AGI Agent Command Center | OpenAI-compatible gateway that routes across 100+ providers, including self-hosted Ollama, vLLM and LM Studio |
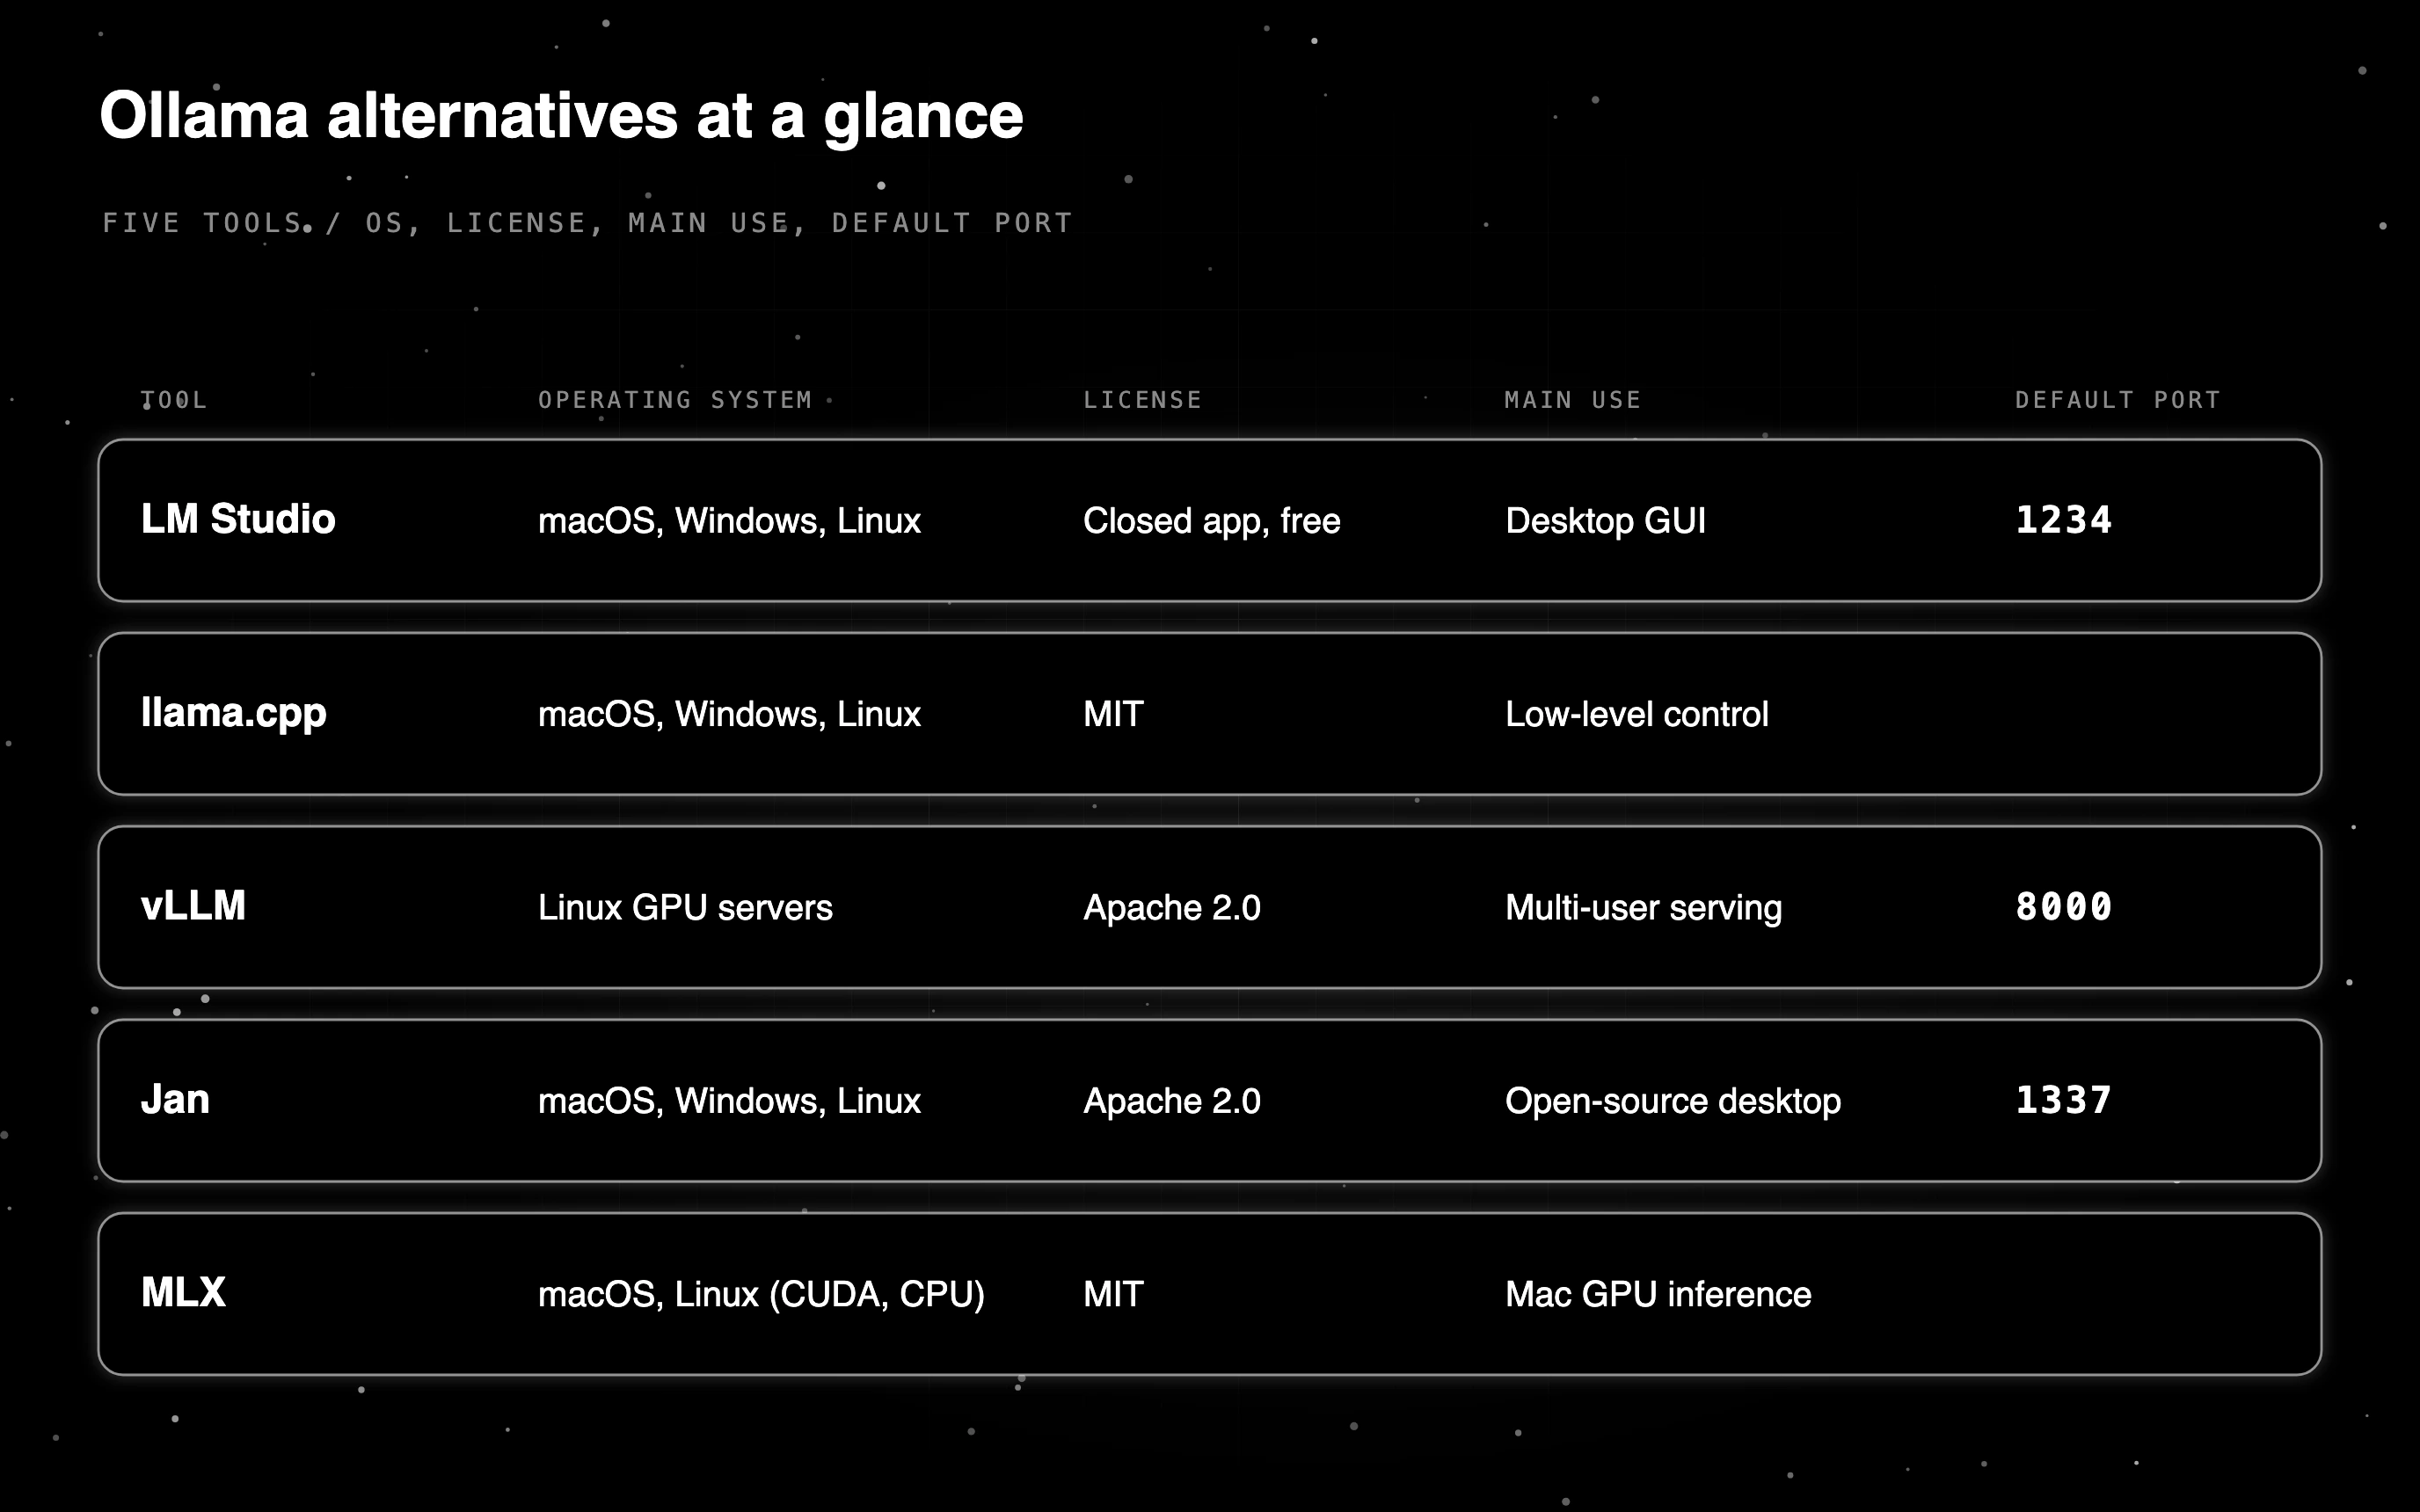
| You want a polished desktop UI with a model marketplace | LM Studio | Mac, Windows, and Linux desktop client with chat, server mode, and HF model search, plus an MLX engine on Apple Silicon and a headless daemon (llmster) |
| You want bare-metal speed and full quantization control | llama.cpp | The C/C++ engine Ollama lists as its backend, with direct control over quantization and compile flags |
| You want production-grade GPU inference at scale | vLLM | Continuous batching, PagedAttention, and tensor parallelism for throughput |
| You want a fully open-source desktop app with MCP tools | Jan | Apache 2.0 desktop app with MCP support, cloud model connectors and an OpenAI-compatible local server on localhost:1337 |
| You want Apple Silicon-optimized inference for Macs | MLX | Apple’s array framework for Apple Silicon, with mlx_lm.server for an OpenAI-style API |
The first row is the platform layer that sits in front of whichever runtime you pick. The five rows after it are the runtimes, and the Future AGI section below covers the platform.
Why developers look for an Ollama alternative in 2026
Four reasons push teams to move a workload off Ollama.
1. Scale beyond a developer laptop
Ollama is built around a single-host model server that pulls GGUF files and serves over HTTP on localhost:11434. That shape works on a MacBook and on a single GPU box. It doesn’t work when the production answer is “four A100s behind a load balancer with autoscaling.”
Ollama has no native multi-replica horizontal scaling, no built-in batch scheduler matching vLLM’s continuous batching, and no tensor-parallel support for sharding a 70B model across GPUs. The community workaround (“put Ollama behind Kubernetes and an Nginx round-robin”) gives you stateless replicas, not the throughput-optimizing scheduler the workload needs.
2. OpenAI-compat shim, not a deep implementation
Ollama exposes an OpenAI-compatible endpoint at /v1/chat/completions. Ollama’s own compatibility page lists streaming, JSON mode, vision and tools as supported, but tool_choice and logprobs are not, and its Responses endpoint is the non-stateful flavor only (no previous_response_id).
3. Quantization options are a subset
Ollama exposes Q4_K_M and a handful of other quantizations cleanly, but the newest sub-2-bit and IQ-quant work that lands in llama.cpp first doesn’t always make it into Ollama’s catalog. If you need those formats to fit a larger model on consumer hardware, llama.cpp gives you them directly.
4. No production-grade scaling primitives
When workload demands change (bursty traffic, mixed model sizes, GPU utilization above 70%, cost telemetry per tenant) the primitives Ollama needs don’t exist. No autoscaler watching queue depth, no spot-aware scheduler, no per-tenant budget cap, no fallback to a hosted model when the local cluster is saturated. The options are to build those primitives yourself or move serving to vLLM (for throughput) and pair it with a platform layer (for everything else).
What to look for in an Ollama replacement
Generic “what’s the best local LLM tool” axes are too broad. Score replacements on the seven that map to the surfaces you actually need once the prototype graduates:
| Axis | What it measures |
|---|---|
| 1. Production scale posture | Does the runtime handle multi-replica, multi-GPU, continuous batching? |
| 2. Desktop UX | Is there a polished UI for non-engineers? |
| 3. OpenAI-compat depth | Does the shim support parallel tool calls, structured outputs, and streaming tool deltas? |
| 4. Quantization coverage | GGUF, AWQ, GPTQ, FP8, IQ-quants, sub-2-bit: are all supported? |
| 5. Hardware coverage | CPU, CUDA, ROCm, Metal, Apple Silicon |
| 6. Model coverage | Llama, Qwen, DeepSeek, Mistral, Gemma: do recent architectures land quickly? |
| 7. Licensing | OSS, permissive, no hosted lock-in |
Note: gateway, observability, evals, optimizer, and guardrails are not on this list. They sit in a platform layer in front of the runtime, which the Future AGI section below covers.
1. LM Studio: Best for desktop polish
Verdict: LM Studio is the right pick when the requirement is a developer-laptop experience with a real UI. Mac, Windows, and Linux desktop client; built-in model browser pulling from Hugging Face; one-click GGUF download; chat playground; OpenAI-compatible server mode. If Ollama feels too command-line-first, LM Studio covers the same ground with a polished frontend.
What it fixes versus Ollama:
- GUI for everything. Model search, parameter tuning, chat, and server toggle are all in one app. Non-engineers can run local models without a terminal.
- Built-in model browser. Search by base model, quantization, parameter count, and hardware fit.
- Server mode parity. Toggle the OpenAI-compatible server and point a client at
localhost:1234. The shape matches Ollama’s/v1/chat/completions.
Migration from Ollama: Drop-in on the client side, since both expose OpenAI-compatible endpoints; only the base URL and port change. Re-download the original GGUF from Hugging Face inside LM Studio.
Where it falls short:
- Same production ceiling as Ollama for multi-user scale, though LM Studio now ships llmster, a headless daemon for servers, cloud instances and CI.
- The desktop app is closed source (free), while the lms CLI and the MLX engine are MIT-licensed on GitHub.
Pricing: Free for home and work use since July 2025, with no form or license needed. A paid Enterprise plan adds SSO and model or MCP gating, and optional Bionic+ ($20/month, US-hosted open models) and Pro ($100/month, everything in Bionic+ with 5x usage limits) plans are available.
Score: 4 of 7 axes (missing: production scale, OSS license, deep OpenAI-compat).
2. llama.cpp: Best for bare-metal speed and quantization control
Verdict: llama.cpp is the C/C++ inference engine that Ollama lists as its backend and Jan bundles. If your reason for leaving is “I want to control the compile flags, pick the quantization, and remove every layer of abstraction,” llama.cpp is the answer. MIT-licensed, C++, GGUF native, runs on CPU, CUDA, AMD via HIP, Metal, Vulkan and Intel via SYCL.
What it fixes versus Ollama:
- Low-level control. Direct compile-target control, hand-tuned matmul kernels, CPU SIMD paths, and Metal/CUDA backends.
- Broad quantization coverage. 1.5-bit through 8-bit integer quantization in GGUF.
llama-serveris OpenAI-compatible. Run./llama-server -m model.gguf --port 8080and point an OpenAI client at it.- No daemon, no model registry abstraction. Files in, inference out. For embedded and edge deploys, the simplicity is the feature.
Migration from Ollama: Download the original GGUF from Hugging Face for llama.cpp. Ollama’s own copies sit under ~/.ollama/models on macOS, /usr/share/ollama/.ollama/models on Linux and C:\Users\%username%\.ollama\models on Windows, so you can delete them once you have switched. Compile or install llama-server and swap the base URL; the client side is unchanged.
Where it falls short:
- More setup. Compile flags, GPU offload knobs, and KV-cache settings are all manual.
- Production scaling is “spawn more processes behind a load balancer,” same ceiling as Ollama.
Pricing: Open source under MIT. No hosted product.
Score: 5 of 7 axes (missing: production scale, deep OpenAI-compat).
3. vLLM: Best for production-grade GPU inference
Verdict: vLLM is the pick when the workload demands continuous batching, PagedAttention, tensor parallelism, and the GPU utilization curves of a real serving cluster. Apache 2.0, written in Python with CUDA kernels.
What it fixes versus Ollama:
- Continuous batching and PagedAttention. Throughput per GPU on production-shaped workloads stays high as concurrent requests grow.
- Tensor parallelism. Shard a 70B model across four or eight GPUs natively. Ollama has no equivalent.
- OpenAI-compatible server with structured outputs. vLLM generates structured outputs using xgrammar or guidance.
- Quantization at production grade. FP8, MXFP4, NVFP4, INT8, INT4, GPTQ, AWQ, GGUF and more.
- First-class Hugging Face integration. Pull models directly from the Hub, including private repos.
Migration from Ollama: Move serving from localhost:11434 to a vLLM container on a GPU box. Update the OpenAI client base URL.
Where it falls short:
- GPU-first. vLLM also runs on x86, ARM and PowerPC CPUs and has plugins for TPUs, Intel Gaudi, Huawei Ascend and Apple Silicon, but on a laptop the setup cost is high, so Ollama or LM Studio stay the easier local-dev choice.
- Operational complexity is real: config files, GPU memory math, KV-cache tuning, and the version-skew dance with new model architectures.
Pricing: Open source under Apache 2.0.
Score: 6 of 7 axes (missing: desktop UX).
If vLLM itself is not the right fit, see our comparison of vLLM alternatives for self-hosted inference.
4. Jan: Best for open-source desktop use with MCP
Verdict: Jan is the pick when you want the LM Studio experience but fully open-source. Apache 2.0, built with Tauri, runs on Mac, Windows, and Linux. ChatGPT-style chat UI, local model browser, OpenAI-compatible local server, MCP tools, and connectors for OpenAI, Anthropic, Mistral and Groq models.
What it fixes versus Ollama:
- OSS desktop UX. Apache 2.0 license, source on GitHub, no closed-source freemium model.
- MCP and cloud connectors. Connect MCP tools for agent workflows and add OpenAI, Anthropic, Mistral or Groq models next to local ones.
- Local server mode. OpenAI-compatible endpoint on
localhost:1337(default port). Same client-side shape as Ollama. - GUI onboarding. Friendly enough for non-engineers; technical enough for power users.
Migration from Ollama: Install Jan, browse the model library, download the same Llama or Qwen variant. Point client code at http://localhost:1337/v1.
Where it falls short:
- Desktop-first. Headless production deploy on a GPU box isn’t the product’s center of gravity.
Pricing: Open source under Apache 2.0.
Score: 4 of 7 axes (missing: production scale, deep OpenAI-compat, broad hardware coverage at server tier).
5. MLX (Apple Silicon): Best for Mac-native inference
Verdict: MLX is the pick when the development environment is a Mac and you want to run models on the Apple Silicon GPU. Apple’s array framework with native MLX-LM serving uses M-series unified memory and the Metal GPU.
What it fixes versus Ollama:
- Apple Silicon native. Designed for M-series chips, with a unified memory model so arrays are shared between CPU and GPU without copies.
- Hugging Face models on the Mac GPU. On Macs with large unified memory, MLX-converted models from the mlx-community Hugging Face org are a direct way to use the GPU; measure tokens per second on your own machine before switching.
- OpenAI-compatible serving via MLX-LM.
mlx_lm.serverexposes the standard API shape. - Pure-Python ergonomics with C++ performance. Apple maintains it.
Migration from Ollama: Install mlx-lm via pip. Convert (or download a pre-converted) MLX model. Run python -m mlx_lm.server. Point clients at the new URL.
Where it falls short:
- Built for Apple Silicon. MLX also ships a CUDA backend and a CPU-only package for Linux, but there is no ROCm build and the mlx-lm server is not recommended for production, so on Linux GPU boxes MLX stays a dev tool.
- MLX uses its own format. mlx-lm can quantize and upload models to Hugging Face itself.
Pricing: Open source under MIT.
Score: 4 of 7 axes (missing: cross-platform hardware coverage, production scale, deep OpenAI-compat).
Best Ollama alternative for Mac, Windows and Linux
| OS | Pick | Why |
|---|---|---|
| macOS | LM Studio or mlx-lm | LM Studio’s MLX engine runs MLX models on Apple Silicon behind a desktop app; mlx-lm runs and quantizes MLX models from Python |
| Windows | LM Studio or Jan | Both ship Windows apps with an OpenAI-compatible local server, on port 1234 and port 1337 |
| Linux | llama.cpp with llama-swap, or vLLM | llama-swap switches between several llama.cpp models behind one endpoint; vLLM serves multi-user traffic on GPU servers |
On a Mac, llama.cpp also fits if you want Metal builds you compile yourself. On Windows, llama.cpp’s llama-server covers CUDA and Vulkan builds. vLLM does not support Windows natively, so keep it on Linux servers.
LM Studio vs Ollama for Local LLM Work
| Ollama | LM Studio | |
|---|---|---|
| Price | Free | Free for home and work use |
| License | MIT, open source | Closed-source app; MIT-licensed lms CLI and MLX engine |
| Interface | CLI on macOS, Windows and Linux, plus desktop apps for macOS and Windows | Desktop app on macOS, Windows and Linux, plus the lms CLI |
| Headless serving | Ollama server | llmster daemon |
| Local API | OpenAI- and Anthropic-compatible, port 11434 | OpenAI- and Anthropic-style, port 1234 |
| Remote models | Ollama Cloud | Bionic+ ($20/month, US-hosted open models) |
Pick Ollama if you script from the terminal and want an MIT-licensed runtime. Pick LM Studio if you want a model browser and a GUI for parameters.
Best Ollama Cloud alternatives
Ollama Cloud runs models in Ollama’s cloud from your apps or terminal with an API key, no model download, and OpenAI- or Anthropic-compatible clients. Two routes give you the same convenience elsewhere:
- LM Studio Bionic+. $20/month for private, US-hosted open models inside LM Studio.
- Hosted providers behind one gateway. Call providers such as Together, Groq, Fireworks or Hugging Face through the Future AGI Agent Command Center, which routes across 100+ providers, including self-hosted Ollama and vLLM, behind one OpenAI-compatible base_url. The app keeps one endpoint whether a request lands on a laptop, your GPU server or a hosted model.
Other open-source Ollama alternatives worth knowing
These did not make the top five, but each fits a specific need:
- LocalAI (MIT): an open-source AI engine that runs LLMs, vision, voice, image and video models on any hardware, with no GPU required.
- llama-swap (MIT): swaps models on demand in front of llama.cpp, vLLM or any local OpenAI- or Anthropic-compatible server.
- llamafile (Apache 2.0, now under mozilla-ai): distributes and runs an LLM as a single file.
- SGLang (Apache 2.0): an inference framework for large language, vision-language and diffusion models, optimized for agentic workloads and large-scale serving.
- KoboldCpp (AGPL-3.0): runs GGUF models locally from one file with a KoboldAI UI and zero install.
- GPT4All (MIT): runs local LLMs on desktop machines; its latest release, v3.10.0, shipped in February 2025.
- textgen (AGPL-3.0, formerly text-generation-webui): an open-source desktop app for local LLMs with an OpenAI- and Anthropic-compatible API.
Future AGI: the platform layer that augments whichever local runtime you pick
LM Studio, llama.cpp, vLLM, Jan, and MLX are local inference engines that load and run the model.
Future AGI is the platform layer that sits in front of whichever local (or remote) backend you run and adds the platform surfaces around it: a multi-provider gateway, LLM-shaped observability, an eval suite, a prompt optimizer, inline guardrails, and per-tenant policy. The shape is a self-improving loop, simulate, evaluate, protect, monitor and optimize, with production traces feeding the next version.
What FAGI adds to any local-runtime choice on this list:
traceAI(Apache 2.0). Built on OpenTelemetry, with 50+ framework integrations across Python, TypeScript, Java and C#, and it can send traces to any OTel backend. Calls to Ollama, vLLM, llama-server, Jan, or MLX-LM all become spans with tokens, latency, and model name broken out per call.- Custom evals. Future AGI has custom evals: write your own grading rule, pick an LLM judge or a deterministic check, set a pass/fail threshold and run it as a CI gate, with built-in evaluators like Task Completion, Groundedness and Detect Hallucination; the SDK is
agent-learning-kit(Apache 2.0). You see when a quantized local model drops below threshold versus a hosted model on the same workload, in the same row.
- Optimization. Six optimizer algorithms (Random Search, Bayesian Search, ProTeGi, Meta-Prompt, PromptWizard, GEPA) rewrite and score prompt variations with your evals as the judge; the algorithms are Apache 2.0 in agent-learning-kit.
- Agent Command Center. An OpenAI-compatible gateway that routes across 100+ providers, including self-hosted Ollama, vLLM and LM Studio, with virtual keys, failover, rate limits, budget limits, caching and cost tracking. Swap the client base_url to
https://gateway.futureagi.com, or self-host it with the Apache-2.0 core.
- Protect guardrails. Runs checks like PII detection and prompt injection on each request and returns block, warn, mask or log; in Future AGI’s Protect paper (arXiv 2510.13351) the median time to a safety label was 65 ms for text and 107 ms for images. Protect runs on Future AGI Cloud and Enterprise, and rule-based gateway guardrails are free on every plan.
The dev-to-prod pattern: Keep Ollama on every developer’s laptop for the inner loop. Run vLLM (or hosted) for production. Put FAGI in front of both: the application talks to the gateway URL in every environment, and the gateway routes to Ollama in dev and vLLM in prod. No code changes between environments, full observability everywhere.
The Command Center docs list self-hosted models via Ollama, vLLM and LM Studio as providers, so the same base_url works on a laptop and in production. Future AGI has a self-hostable Apache-2.0 core; see the self-hosting guide.
How Do the Ollama Alternatives Compare Side by Side?
| Axis | LM Studio | llama.cpp | vLLM | Jan | MLX |
|---|---|---|---|---|---|
| Production scale posture | Desktop only | Process-per-replica | Continuous batch + TP | Desktop only | Single Mac |
| Desktop UX | Polished | None (CLI) | None | Polished | Minimal |
| OpenAI-compat depth | Shim | Shim | Deep | Shim | Shim |
| Quantization coverage | GGUF and MLX | GGUF, 1.5-bit to 8-bit | FP8, MXFP4, NVFP4, INT8, INT4, GPTQ, AWQ, GGUF and more | GGUF (subset) | MLX format |
| Hardware coverage | CPU, CUDA, Metal, MLX on Apple Silicon | CPU, CUDA, AMD via HIP, Metal, Vulkan, Intel via SYCL | NVIDIA, AMD and Intel GPUs, x86/ARM/PowerPC CPUs, TPU and Gaudi plugins | CPU, CUDA, Metal | Apple Silicon, plus CUDA and CPU on Linux |
| Model coverage | HF marketplace | Everything llama.cpp supports | HF (broad) | HF marketplace | mlx-community conversions on Hugging Face |
| Licensing | Closed app, free; MIT CLI | MIT | Apache 2.0 | Apache 2.0 | MIT |
Future AGI isn’t in the matrix because it doesn’t run inference. FAGI plugs in front of all five.
Migration notes: what breaks when you outgrow Ollama
Three surfaces need attention.
Keeping Ollama for local dev, layering production around it
One pattern that works: keep Ollama on developer laptops and replace what is around it. Run Ollama (or LM Studio, or Jan) on every developer’s machine for the inner loop, and run vLLM for production.
Put a platform layer (Future AGI, which can also run as a self-hosted AI gateway) in front of both. The application talks to the gateway URL in every environment; the gateway routes to local in dev and vLLM in prod.
Re-routing client base URLs
The official OpenAI SDKs read the base URL from OPENAI_BASE_URL. Ollama defaults to http://localhost:11434/v1; LM Studio to http://localhost:1234/v1; Jan to http://localhost:1337/v1; vLLM to http://<host>:8000/v1; the Future AGI gateway to https://gateway.futureagi.com (or your self-hosted gateway URL). The migration is a one-line change in three places: SDK initialization, runtime config, and the deployment manifest.
Adding observability and evals without rewriting the application
traceAI (Apache 2.0) instruments supported LLM SDKs and frameworks and emits OpenTelemetry spans. Send them to Future AGI Observe, where each trace can be searched and scored with evals, without changing the inference path. Same shape works for vLLM, Ollama, llama-server, Jan, and MLX-LM: they’re OpenAI-compatible, so client-side instrumentation doesn’t care which is downstream.
Which Ollama alternative should you choose?
Choose LM Studio if your reason for leaving is command-line-first UX and you want a polished desktop client.
Choose llama.cpp if your reason for leaving is “I want to remove every layer of abstraction and control compile flags, quantization, and KV-cache settings myself.”
Choose vLLM if your reason for leaving is production-scale GPU serving with continuous batching and tensor parallelism.
Choose Jan if your reason for leaving is “polished desktop UX, fully open source under Apache 2.0, with MCP tools.”
Choose MLX if your dev environment is a Mac and you want models running on the Apple Silicon GPU.
Add Future AGI in front of any of the five (or Ollama itself, kept for local dev) when the gap is multi-backend routing, observability, evals, optimizer, or inline guardrails.
Moving off Ollama without rewriting your app
The prototype still works on the MacBook. What changed is everything around it: the workload is heading to GPU servers, SRE wants metrics, and the platform team wants a policy layer in front of every model call. None of that needs a rewrite.
Keep Ollama or LM Studio on laptops for the inner loop. Pick vLLM for multi-user GPU serving, or llama.cpp when one box and full control are enough. Put one gateway URL in front of both so the app keeps the same base URL in every environment, and trace and score every call from the first deploy.
Point your OpenAI client at the Future AGI Agent Command Center and start free on the pricing page.
Related reading
Frequently Asked Questions
What's better than Ollama?
Which is better, LM Studio or Ollama?
Is vLLM better than Ollama?
What are some open-source alternatives to Ollama?
Is LM Studio free to use?
What is the best Ollama alternative for Mac?
What is the best Ollama alternative for Windows?
Is Ollama still relevant?
Ollama is the open-source desktop runtime that runs Llama, Qwen, Gemma, and other open-weights LLMs locally with a one-line install. How it serves in 2026.

Five vLLM alternatives scored on throughput, hardware coverage, quantization, structured outputs, ops burden, plus the platform layer that augments them.

vLLM is the open-source LLM serving engine that pioneered PagedAttention and continuous batching. How it serves, how teams use it in production 2026.