Best 5 AI Gateways to Monitor Claude Code Token Usage in 2026
A Claude Code token usage gateway tracks tokens and cost per developer, session and repo. Set a gateway API key, check usage and compare five gateway picks.
Table of Contents
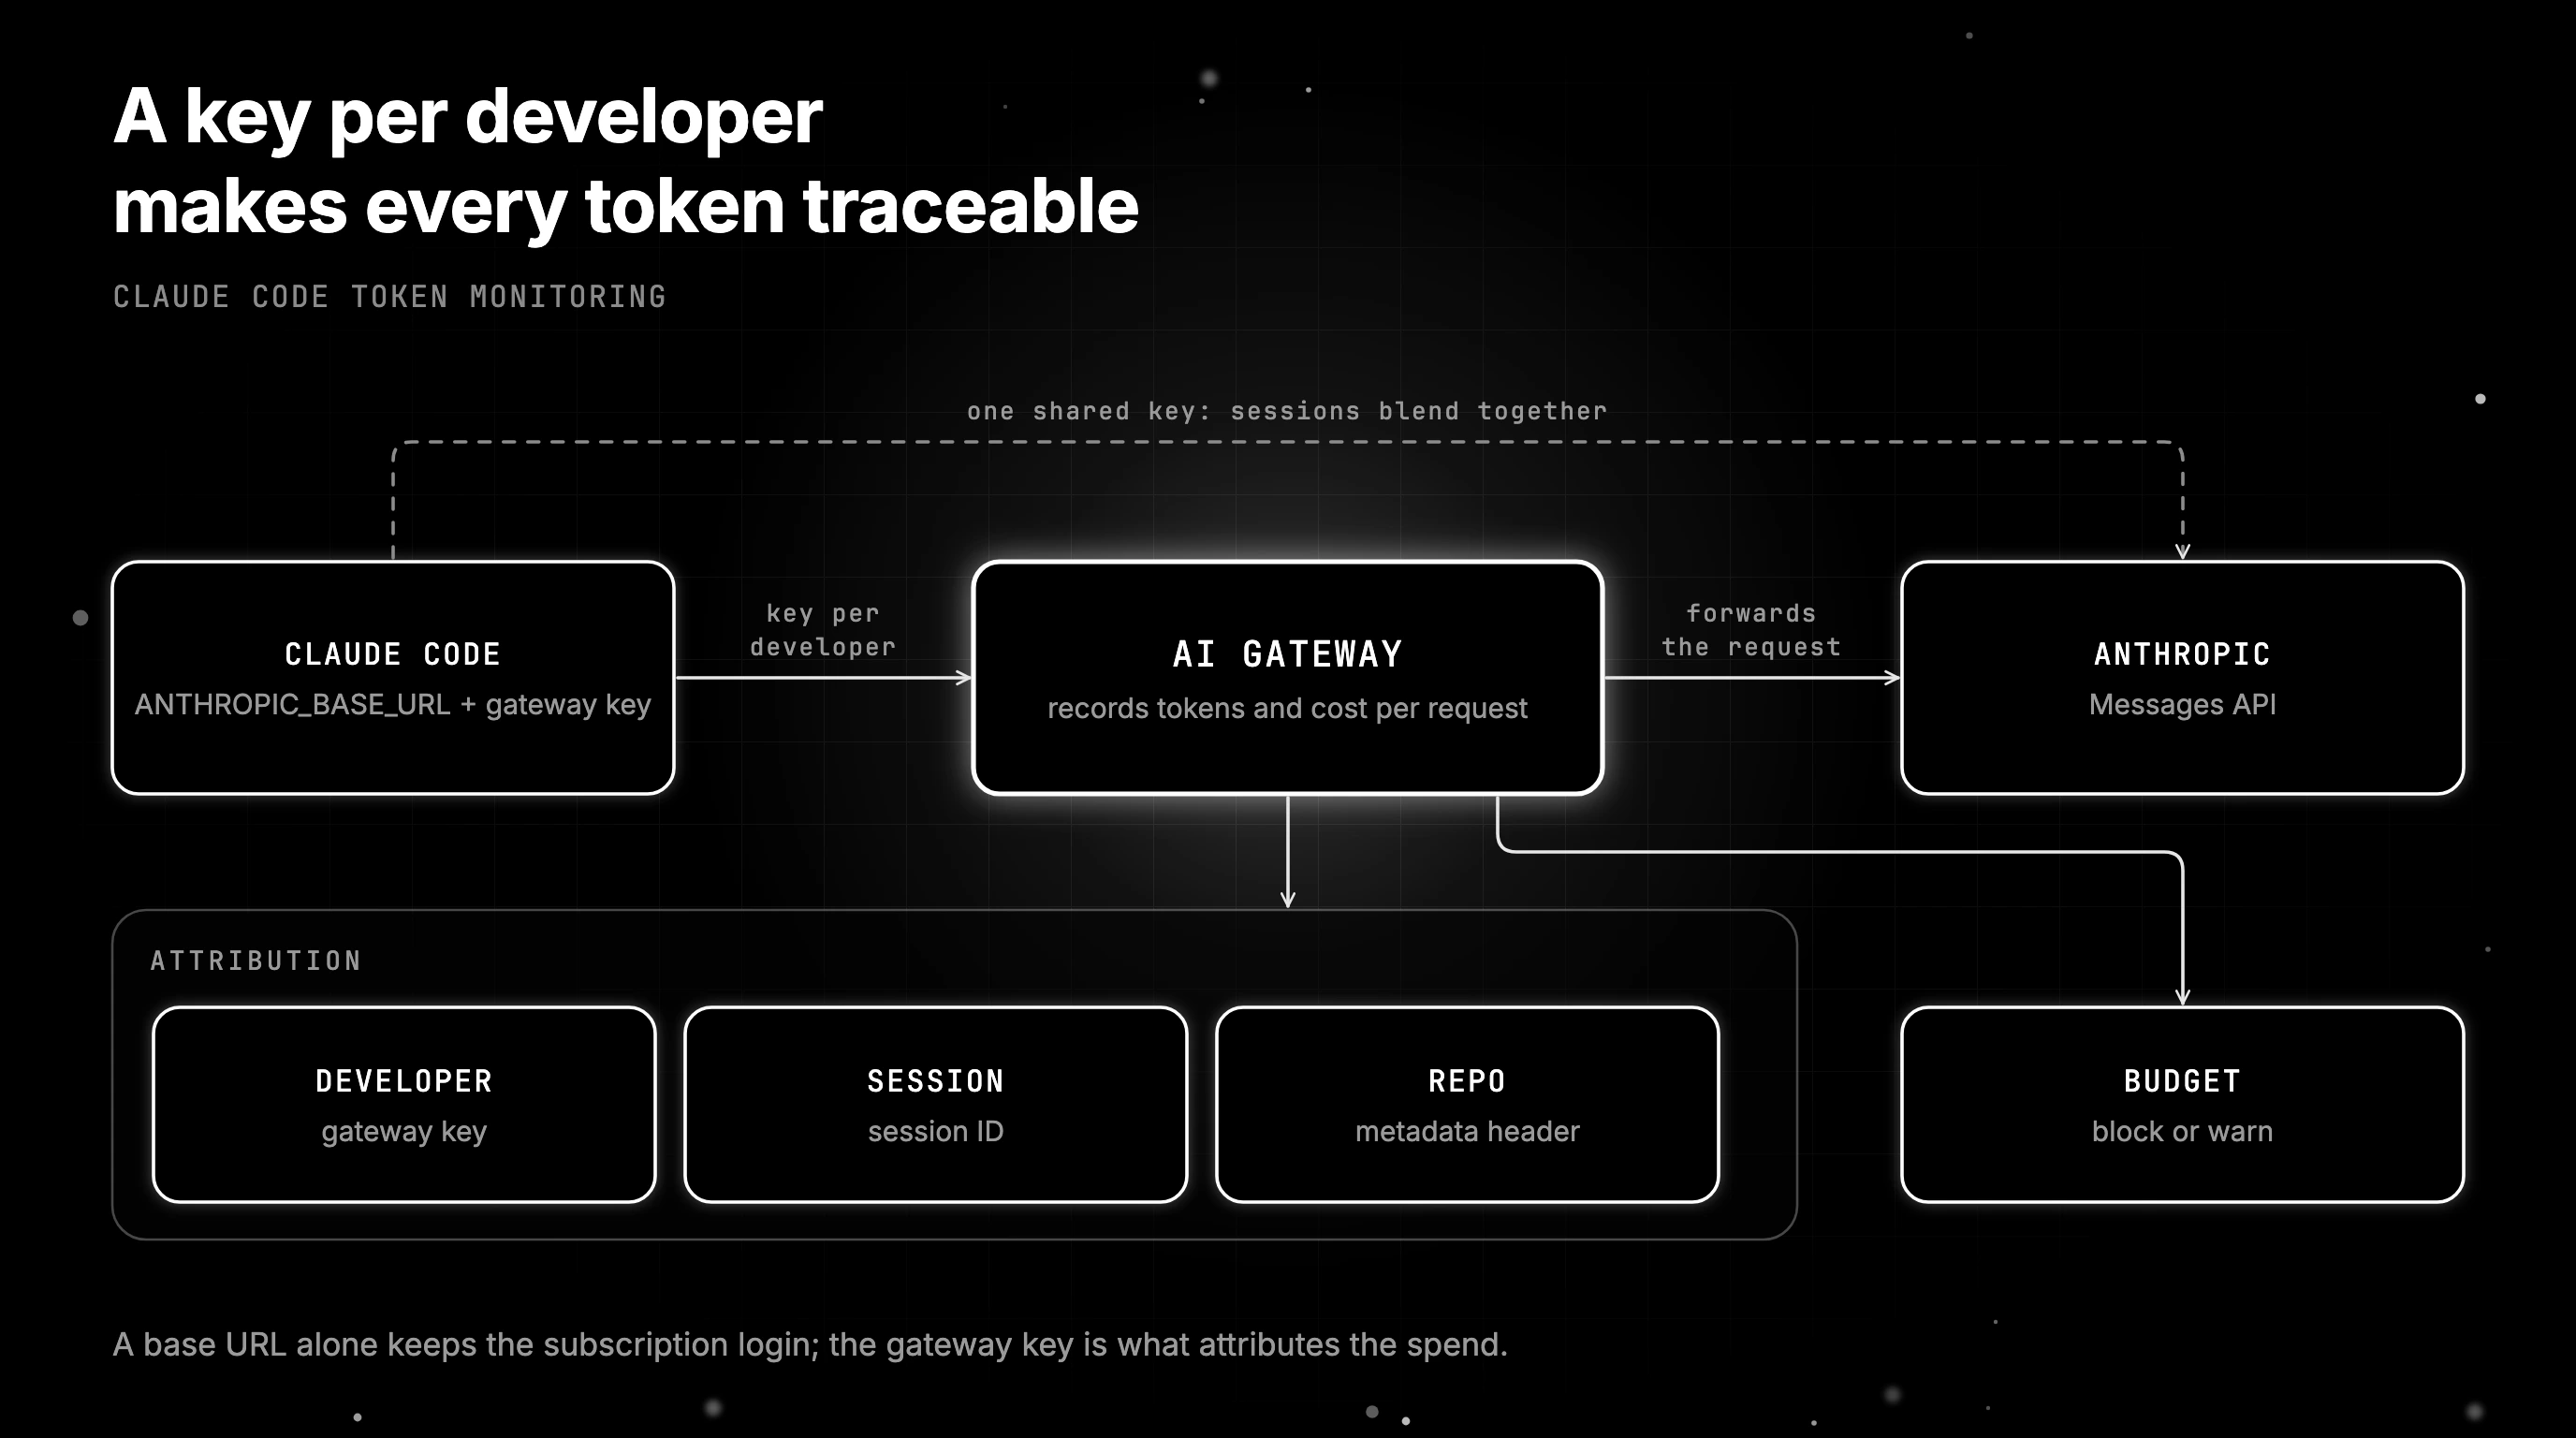
To monitor Claude Code token usage across a team, point Claude Code at an AI gateway with ANTHROPIC_BASE_URL and give each developer a gateway-issued key. The gateway records tokens and cost on every request, tagged by developer, session and repo. Without it, finance sees one invoice total and /usage shows one session on one machine.
Every pick below is a Claude SDK compatible AI gateway: it serves the Anthropic Messages endpoint Claude Code calls and attaches per-developer metadata. Future AGI also feeds those traces into evals and prompt optimization.
TL;DR
Future AGI Agent Command Center is the strongest pick for monitoring Claude Code token usage because it ships per-developer virtual keys, per-repo metadata tags, session-level cost aggregation rolled up across multi-turn Claude Code conversations, budgets that block or warn, per-request cost headers, and Anthropic or Bedrock behind one gateway. The other four picks below win on specific edges.
- Future AGI Agent Command Center: Best overall. Per-developer + per-repo attribution, session-level aggregation, budgets that block or warn, and Anthropic or Bedrock behind one gateway.
- Portkey: Best for the hosted product with mature RBAC and the deepest prompt library. Fastest setup with mature controls (Palo Alto Networks closed its purchase on May 29, 2026).
- Helicone: Best for the simplest drop-in proxy when you don’t need routing intelligence. Lightweight per-request observability (its pricing page now says Helicone is part of Experiential Labs).
- LiteLLM: Best when you need to self-host the gateway and control model-endpoint egress. Self-hosted, MIT-licensed open-source gateway with a Rust core and a Python SDK; pin versions, since litellm 1.82.7 and 1.82.8 shipped malicious code on PyPI on March 24, 2026.
- Kong AI Gateway: Best when you already run Kong for REST. The AI extension fits the existing operational story. Native Anthropic format needs paid Kong Enterprise or Konnect on Gateway 3.10+.
Why Claude Code needs a gateway in front of it
Claude Code is an interactive coding agent. Each invocation opens a session that can run many turns, each one issuing one or more calls to the Anthropic API. Three properties make the workload hard to monitor without help:
-
Sessions are long. A single bug-fix conversation can run many turns, each carrying file contents, tool calls and reasoning. Per-call cost telemetry doesn’t tell you what a session cost.
-
Cost is concentrated in a few power users. A few long agentic sessions outweigh weeks of light use, so averages hide who drives the bill.
-
Anthropic reports per member, not per repo. The Console shows Claude Code spend per member and the Analytics API returns daily per-user metrics; repo and session splits need tags.
A gateway sits between the Claude Code client and api.anthropic.com. It intercepts each call, applies a metadata header (developer ID, repo, feature flag), and forwards the request. The metadata makes the per-call cost attributable. The interception point makes caps, alerts, and routing possible.
For the rest of this post, “gateway” means an AI gateway that serves the Anthropic Messages API that Claude Code calls. All five picks support pointing Claude Code at them via the ANTHROPIC_BASE_URL environment variable.
How to set a gateway API key in Claude Code
Claude Code reads two variables to reach a gateway: ANTHROPIC_BASE_URL for the address and a credential variable for the key. Use ANTHROPIC_AUTH_TOKEN for a bearer token and ANTHROPIC_API_KEY for an x-api-key header. Put both in the env block of ~/.claude/settings.json so background agents use them too.
export ANTHROPIC_BASE_URL=https://llm-gateway.example.com
export ANTHROPIC_AUTH_TOKEN=sk-gateway-key
export ANTHROPIC_CUSTOM_HEADERS="X-Org-Route: prod"
Swap in the address and key your gateway issues, using the exact base URL issued by your gateway, including any required path prefix. Claude Code appends /v1/messages to that base. The third line adds one Name: Value header to every request, which is how a gateway receives routing keys or tags such as a repo name. Run /status: the Anthropic base URL and Auth token lines confirm the gateway and key. A base URL alone keeps the subscription login and its limits.
Built-in token tracking without a gateway
/usage shows the current session’s input, output, cache-read and cache-write tokens by model. Setting CLAUDE_CODE_ENABLE_TELEMETRY=1 exports OpenTelemetry metrics such as claude_code.token.usage, tagged with session.id, and with user.email when you sign in with a Claude account. Both stop short of team chargeback: /usage lives on one machine and telemetry needs a collector you run, while a gateway sees every request.
The 7 axes we score on
The default “best AI gateway” axes (provider breadth, routing, fallback, observability, cost, security, deployment) are too generic for Claude Code. We scored each pick on seven axes that specifically affect coding-agent monitoring, and the verdict line at the end of each pick scores all seven.
| Axis | What it measures |
|---|---|
| 1. Per-session cost attribution | Can the gateway group cost by Claude Code session ID rather than only by API key? |
| 2. Per-developer chargeback | Can it tag and aggregate by developer email or SSO claim? |
| 3. Per-repository tagging | Can it attribute usage to a repository or workspace? |
| 4. Tool-call passthrough | Does Claude Code’s tool-use (bash, file edits) survive the gateway hop intact? |
| 5. Streaming continuity | Does token streaming work without buffer-and-batch behaviour that breaks the CLI’s UX? |
| 6. Alert + budget hooks | Can you set a $X cap per developer per day and get paged when it trips? |
| 7. Self-host posture | Can the gateway run in your VPC with egress restricted to your chosen model endpoints? |
How we picked
We started from gateways that serve the Anthropic Messages endpoint, then kept five that attach per-developer metadata. Each of the five also passes Claude Code’s tool-use blocks through intact and streams responses without buffering, since a dropped tool block or a buffered stream breaks the CLI.
1. Future AGI Agent Command Center: Best for per-developer / per-repo token attribution
Verdict: Future AGI serves Claude Code’s native Anthropic Messages endpoint, issues a key per developer, and returns each request’s cost in the x-agentcc-cost header.
What it does for Claude Code token monitoring:
- Per-session traces through the Claude Code tracing integration (
npx @traceai/agents setup claude --project coding-agents), grouped by session. - Per-developer aggregation through a key per developer or
x-agentcc-user-id. - Per-repository tagging through custom metadata. Send the
x-agentcc-metadataJSON header viaANTHROPIC_CUSTOM_HEADERSand the cost dashboard groups spend by repo. - Tool-call passthrough preserved because the gateway parses Anthropic’s tool-use blocks rather than re-serialising them as text.
- Streaming continuity maintained, the SSE pass-through doesn’t buffer.
- Alert and budget hooks through budgets per key, user or model that block or warn.
- Self-host posture through the self-hosted agentcc-gateway (Go service, Docker image) plus the Apache 2.0 traceAI library.
The loop. Every Claude Code trace can be scored with evaluators from agent-learning-kit (Apache-2.0), such as Task Completion, or custom LLM-as-Judge evals. traceAI is OpenTelemetry-native and covers 80 integration families across 5 languages.
Error Feed groups traces that failed the same way into one issue and points at the layer to fix. Low-scoring sessions then feed the prompt optimizers in agent-learning-kit’s fi.opt module, such as GEPA and ProTeGi, which rewrite the system prompt against your evals.
Pricing: Free plan with 100K gateway requests a month, then pay-as-you-go. Add-ons: Boost $250/month (SOC 2 Type II), Scale $750/month (HIPAA BAA), Enterprise $2,000/month.
Score: 7/7 axes.
2. Portkey: Best for hosted gateway with mature RBAC
Verdict: Portkey is one of the most polished hosted gateways here. Palo Alto Networks closed its purchase on May 29, 2026 and made it the core AI gateway of Prisma AIRS. If your team is using Claude Code through one shared workspace and wants per-developer keys + RBAC out of the box, Portkey is the fastest path. It doesn’t optimize prompts back; it observes and routes.
What it does for Claude Code token monitoring:
- Per-session traces through Portkey’s
x-portkey-trace-idrequest header. The Claude Code wrapper has to set it; if your team uses a single shared key, sessions blend together unless you wire the header. - Per-developer chargeback through a Portkey API key per developer, grouped into workspaces with their own budgets. Portkey’s Model Catalog has replaced its older virtual keys, and every developer key routes to one shared Anthropic integration.
- Per-repository tagging through metadata headers. Same caveat, the client has to set them.
- Tool-call passthrough works via its Claude Code integration.
- Streaming continuity works for SSE.
- Alert and budget hooks through per-key budget caps and Slack alerts.
- Self-host posture through Portkey’s BYOC and hybrid deployments; Portkey lists fully air-gapped installs as legacy and no longer offers them for new deployments.
Where it falls short:
- No optimizer. The traces inform humans, not the gateway.
- The metadata-header model requires Claude Code wrapper changes. Without that, you only get key-level aggregation.
Pricing: Free tier with 10K recorded logs a month. Production is $49/month for 100K logs. Enterprise is custom with SOC 2 Type II.
Gap: No feedback loop / optimization.
3. Helicone: Best for lightweight observability
Verdict: Helicone is the right pick when you want per-request observability for Claude Code and nothing else. Drop the proxy URL in front of Anthropic, get a per-request cost table, move on with your week. If you also want budgets, routing, or guardrails, the other four on this list are deeper.
What it does for Claude Code token monitoring:
- Per-session traces through Helicone’s
Helicone-Session-Idheader. Same client-side wiring caveat. - Per-developer chargeback through
Helicone-User-Id. Aggregation in the dashboard is simple but the slicing is shallower than Portkey or Future AGI. - Per-repository tagging through custom properties.
- Tool-call passthrough confirmed.
- Streaming continuity works.
- Alert and budget hooks through usage alerts and rate-limit policies. Less expressive than budget caps with auto-pause.
- Self-host posture through Helicone’s open-source self-host.
Where it falls short:
- No optimizer.
- Routing is provider-level (cheapest provider first, with failover). Claude-Code-specific routing, e.g., route easy turns to claude-haiku-5-5 and hard turns to claude-opus-5-5, has to be coded by your team upstream of the proxy.
Pricing: Hobby is free with 10,000 requests. Pro is $79/month and Team $799/month, with usage-based pricing on top. Enterprise is custom.
Gaps: No feedback loop; alerting is less mature.
4. LiteLLM: Best for self-hosted open-source routing
Verdict: LiteLLM is the pick when you need a self-hosted gateway and the security team wants to inspect the code that handles prompts. Calls to hosted model endpoints still leave your VPC. It’s MIT-licensed outside enterprise/, built on a Rust core with a Python SDK, and runs as a proxy inside your infra. You get less observability than the hosted options out of the box, but the source code is yours.
What it does for Claude Code token monitoring:
- Per-session traces through LiteLLM’s metadata pass-through. Wire
metadata.session_idandmetadata.trace_idin your proxy config. - Per-developer chargeback through team_id and user_id on virtual keys. The team_id maps to the SSO claim if you wire your IdP.
- Per-repository tagging through custom metadata. Bring your own dashboard. LiteLLM’s UI lists transactions but slicing by repo requires exporting to your analytics warehouse.
- Tool-call passthrough confirmed working for Anthropic tool-use blocks.
- Streaming continuity works.
- Alert and budget hooks through LiteLLM’s spend tracking and per-key budgets. Webhook-based alerting; you wire the page-on-call yourself.
- Self-host posture is the strongest in this list. Self-hosted, runs on your nodes. Model calls and telemetry can still leave the VPC; restrict both to approved endpoints.
Where it falls short:
- No optimizer.
- The UI is functional, not polished. Slicing by developer or repo means going to a SQL dashboard.
- The “observability included” story is thinner than Portkey or Helicone. Plan to wire Future AGI traceAI or another OTel sink behind LiteLLM if you want depth.
Pricing: Open source under MIT. LiteLLM also sells an Enterprise tier with SLA, SSO and audit.
Gaps: No polished native dashboard or optimizer.
5. Kong AI Gateway: Best if you already run Kong
Verdict: Kong AI Gateway is the pick when the API platform team already runs Kong for the company’s REST APIs and the path of least resistance is to extend that stack with AI-specific policies. The strengths are SLA, plugin ecosystem, and ops familiarity. The weakness is AI-specific depth: most observability comes from plugins.
What it does for Claude Code token monitoring:
- Per-session traces through OpenTelemetry plugins. Kong’s OTel plugin captures the request lifecycle; you wire span attributes through Lua or the new AI Proxy plugin.
- Per-developer chargeback through consumer + tag patterns. The chargeback dashboard is third-party (typically Grafana on top of the OTel sink).
- Per-repository tagging through tags on the Kong consumer.
- Tool-call passthrough works through the AI Proxy plugin with
llm_formatset toanthropic(Kong Gateway 3.10+). Native Anthropic format requires paid Kong Enterprise or Konnect; self-hosting alone does not unlock it. - Streaming continuity is supported.
- Alert and budget hooks through Kong’s rate-limiting plugins. Spend-based caps require plugin work.
- Self-host posture is the entire point of Kong; it runs anywhere.
Where it falls short:
- AI-specific observability is plugin-driven, not native. The default dashboard is the API-gateway view, not the LLM-cost view.
- No optimizer.
- Out of the box, the spend-tracking story requires wiring multiple plugins.
Pricing: Kong has an open-source gateway, but the native Anthropic format used here requires paid Enterprise or Konnect on Gateway 3.10+. Confirm feature entitlement and pricing for your deployment.
Gaps: No native AI observability, optimizer, or polished cost dashboard.
Capability matrix
| Axis | Future AGI | Portkey | Helicone | LiteLLM | Kong AI Gateway |
|---|---|---|---|---|---|
| Per-session attribution | ✅ Native | ✅ Header | ✅ Header | ✅ Metadata | ✅ Plugin |
| Per-developer chargeback | ✅ Native | ✅ API key | ✅ Header | ✅ Team/user | ✅ Consumer |
| Per-repo tagging | ✅ Metadata | ✅ Metadata | ✅ Custom prop | ✅ Metadata | ✅ Tags |
| Tool-call passthrough | ✅ | ✅ | ✅ | ✅ | ✅ (paid Enterprise/Konnect, 3.10+) |
| Streaming continuity | ✅ | ✅ | ✅ | ✅ | ✅ |
| Alert + budget hooks | ✅ Block or warn | ✅ Slack + cap | ⚠️ Alerts + rate limits | ✅ Webhook | ⚠️ Plugin |
| Self-host posture | ✅ Self-host | ✅ BYOC | ✅ OSS | ✅ OSS | ✅ Self-host (Anthropic format paid) |
| Feedback loop / optimizer | ✅ fi.opt | ❌ | ❌ | ❌ | ❌ |
Decision framework by team
Choose Future AGI if you want the gateway to do more than monitor, if the traces should also drive prompt and route optimization over time. The agent-learning-kit optimizers are opt-in: turn them on once Claude Code has eval baselines and live traces flowing.
Choose Portkey if you want a hosted gateway with mature RBAC, per-developer API keys, and a polished UI, and you don’t need the optimizer yet. Pick this when the procurement story matters and the team is happy with monitoring as a one-time setup.
Choose Helicone if you want the lightest possible drop-in for per-request observability and you don’t need routing or budgets. Pick this for small teams on Claude Code where the simpler product is the right fit.
Choose LiteLLM if your security or compliance team requires a self-hosted gateway with controlled egress to approved model endpoints. Pick this when open-source code and self-host control beat the polish of the hosted alternatives.
Choose Kong AI Gateway if you already operate Kong for REST APIs and the path of least resistance is to extend the existing stack. Pick this when the platform team’s familiarity with Kong outweighs the AI-specific shallowness of the AI Proxy plugin.
Common mistakes when wiring Claude Code through a gateway
| Mistake | What goes wrong | Fix |
|---|---|---|
| Pointing only the IDE plugin at the gateway | The terminal CLI usage still hits Anthropic directly; chargeback misses half the traffic | Set ANTHROPIC_BASE_URL in the shell profile as well as the IDE |
| Sharing one team key across developers | All sessions look identical to the dashboard | Issue a gateway key per developer (Portkey API keys, Future AGI or LiteLLM virtual keys) |
Not preserving anthropic-version header | Tool-use behaviour silently differs between Claude Code’s expected version and the gateway’s default | Pin the version explicitly in the gateway forwarding rule |
| Buffering streaming responses | Claude Code’s progress UI freezes mid-turn | Confirm the gateway forwards SSE without buffer-and-batch |
Tagging with only user_id, not session_id | Session-level cost attribution is impossible | Tag both; the session ID is what makes the cost story legible |
| Setting budget caps too low | Claude Code pauses mid-conversation, breaking the developer’s flow | Pair a warn budget or threshold alert with the hard cap so engineering knows before pause |
How Future AGI closes the loop on Claude Code spend
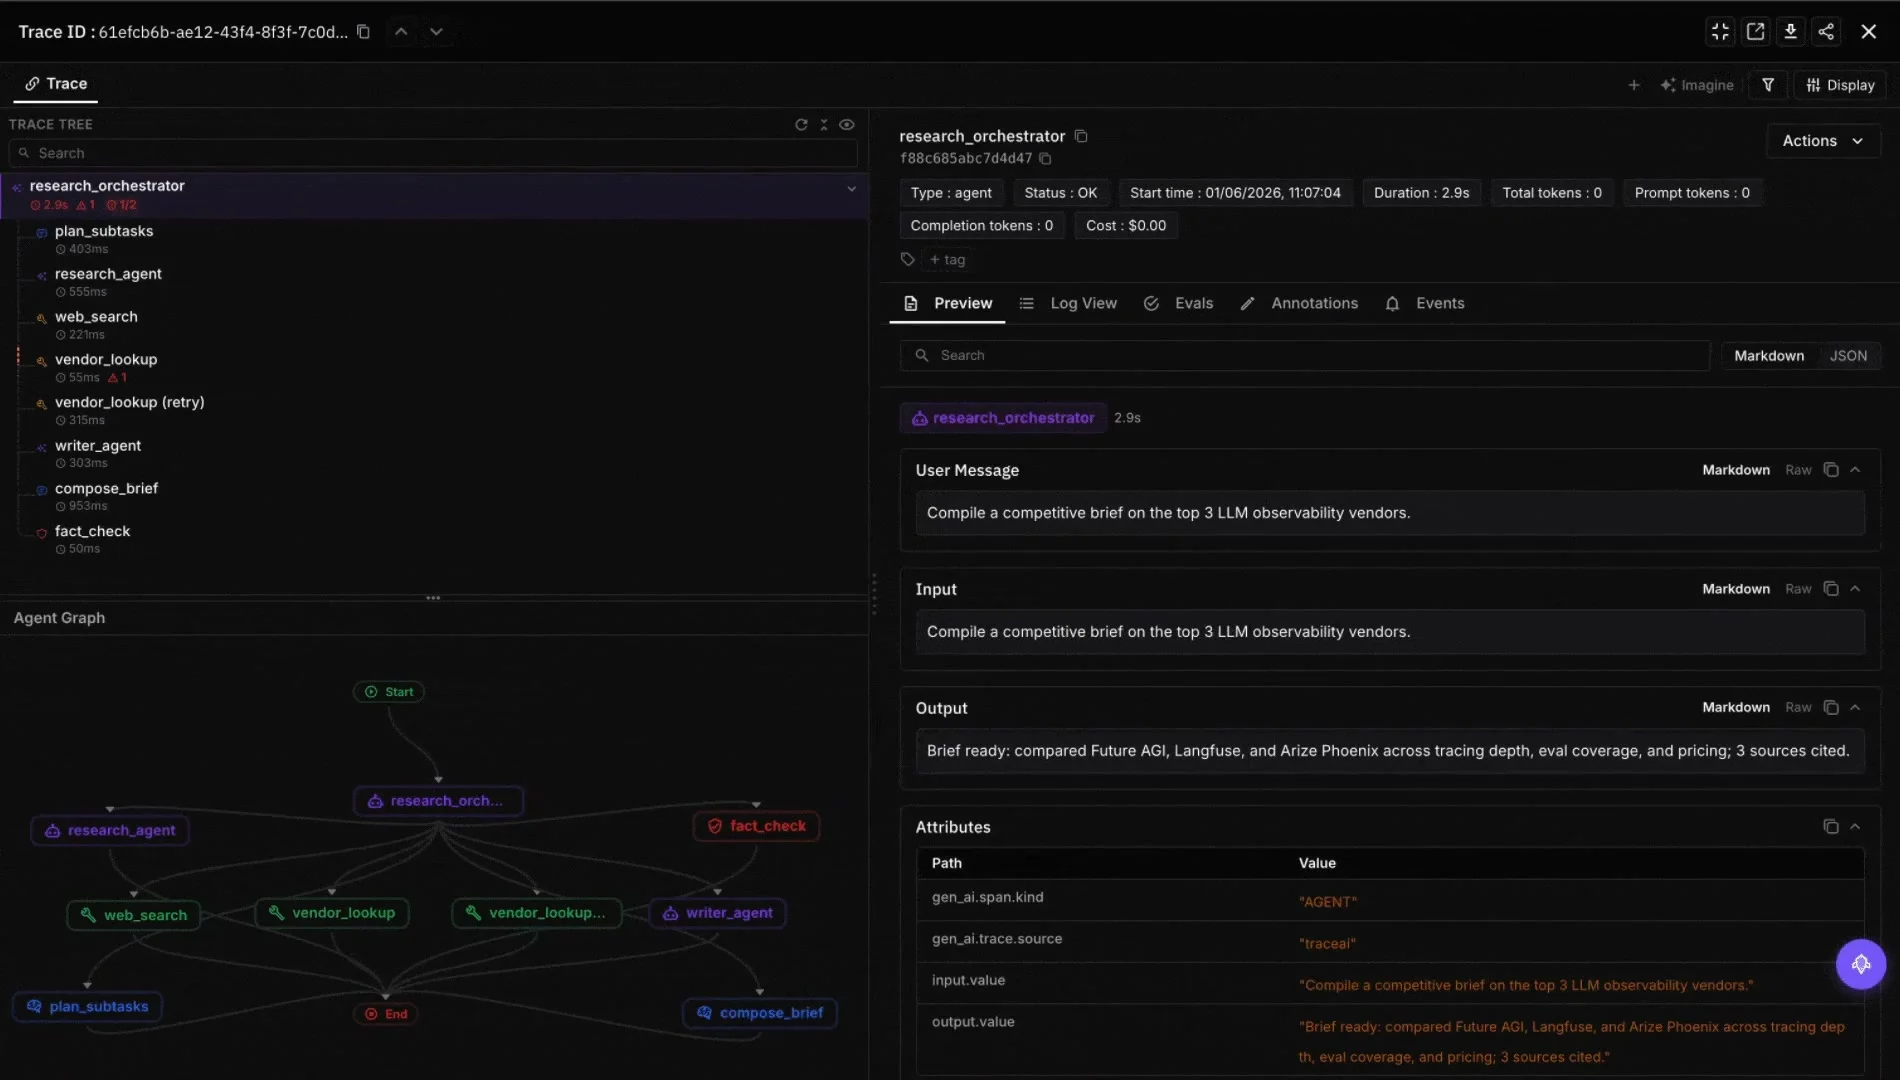
The other four gateways treat token monitoring as an end state: capture the trace, show it in a dashboard, send an alert when spend trips a threshold. Future AGI treats it as the input to a feedback loop. The loop has six stages:
-
Trace. Every Claude Code turn produces a span tree via
traceAI(Apache 2.0). Spans capture inputs, outputs, tool calls, model used, and the session ID. -
Evaluate.
fi.evalsscores every turn with evaluators such as Task Completion, plus a custom LLM-as-Judge rubric for code correctness. Scores live alongside the cost data. -
Cluster. Error Feed groups failing traces into issues by failure mode.
- Optimize. The
fi.optprompt optimizers in agent-learning-kit (such as GEPA and ProTeGi) rewrite the system prompt against the clustered failures. Routing changes, such as simple turns toclaude-haiku-5-5, go in Agent Command Center’s cost-optimized or complexity-based routing.
-
Route. Agent Command Center’s gateway applies the updated routing policy on the next request.
-
Re-deploy. The new prompt is saved as a new version and the route change ships through the gateway config. Teams roll forward, then watch eval scores and per-session cost.
Net effect: easy turns go to the cheaper model and the optimizer trims prompts that over-explain. The eval scores then show the loop where to focus next.
The open-source building blocks:
traceAI, github.com/future-agi/traceAI (Apache 2.0)agent-learning-kit, github.com/future-agi/agent-learning-kit (Apache-2.0; evals and thefi.optoptimizers)future-agi, github.com/future-agi/future-agi (Apache-2.0 core; includes agentcc-gateway)
The hosted Agent Command Center adds the failure-cluster view, live Protect guardrails and SOC 2 Type II certification. The guardrails run the Future AGI Protect model family: LoRA adapters on Gemma 3n covering toxicity, sexism, data privacy and prompt injection across text, image and audio.
What we did not include
We deliberately left out four gateways that show up in other 2026 listicles. Test each on your own Claude Code traffic before ruling it out:
- OpenRouter. Fantastic for model exploration but not the right shape for an enterprise-team chargeback story. The routing is consumer-facing.
- Cloudflare AI Gateway. Strong primitives and a documented Claude Code setup, but spend limits are still marked Beta.
- TrueFoundry. A solid MLOps gateway that fits best when a team already serves models on TrueFoundry.
- Bifrost. Maxim AI’s Apache-2.0 Go gateway with virtual keys and budgets.
Getting the Claude Code bill back under control
The invoice problem at the top comes down to one missing record: who spent which tokens, in which session and repo. A key per developer, a repo header and session-grouped traces give finance that record. Start with keys and budgets, then add evals.
Set up per-developer keys, budgets and cost tracking for Claude Code in Agent Command Center.
Related reading
- What Is an AI Gateway? The 2026 Definition
- Best LLM Gateways in 2026
- Best AI Gateways for Agentic AI in 2026
- Best LLM Cost Tracking Tools in 2026
Sources
Frequently Asked Questions
How do I set a Claude Code gateway API key?
Do I need an API key to use Claude Code?
How do I check Claude Code token usage?
How are Claude Code tokens counted?
How do I track Claude Code token usage per developer?
Six AI gateways scored on Claude Code cost management in 2026: per-developer budgets, semantic cache, audit headers, Opus-to-Haiku fallback.

An AI gateway sits between apps and LLM providers for governance, routing, observability. What it is, how it differs from API gateways.
Future AGI, Helicone, Langfuse, OpenRouter, Portkey, LangSmith, Datadog, and CloudZero compared on per-trace, per-developer LLM cost attribution.