How ChatGPT Jailbreaks Like DAN and Prompt Injection Work in 2026 and How to Defend Production LLMs
Which ChatGPT jailbreak prompts still work in 2026? DAN, Developer Mode, multi-turn and injection attacks explained, what is patched, and how to red-team apps.
Table of Contents
A support agent reads an uploaded PDF to extract a refund claim. The PDF, planted by the attacker, contains a paragraph in white text on a white background, which the model reads but the human never saw, telling the agent to drop its earlier instructions and send a $5,000 refund to the attacker’s account. The agent issues the refund, with no human in the loop, no ChatGPT jailbreak prompt the user typed and no DAN, just a poisoned tool input.
This is not a classic ChatGPT jailbreak. It is an indirect prompt-injection attack against an agent that treats untrusted tool input as instructions. The attack has moved from the chat window to the data pipeline, and the impact has moved from bad text to bad actions. This post covers both jailbreaks and indirect injection, what still works as a bypass, what does not, and how to block both at the guardrail layer.
If you came here looking for a working DAN prompt: DAN-style copy-paste prompts have been public since December 2022, they were blocked when we tested them against GPT-5.5 in July and August 2026, and OpenAI’s usage policies list ‘circumventing our safeguards’ as prohibited. What follows is what each named jailbreak tried to do, what still partially works, and how to test your own app safely.
Do ChatGPT Jailbreaks Still Work in 2026
| Technique family | Still works? | Defense |
|---|---|---|
| Naive DAN persona | Blocked in our July/August 2026 GPT-5.5 test | Refusal training + runtime persona-pattern check |
| Updated DAN variants (DUDE, Grandma, AIM) | AIM blocked in our test; DUDE and Grandma not tested | Persona-pattern guardrail check |
| Encoded payloads (base64, rot13, leetspeak) | Mostly blocked in our test | Encoding-bypass pattern check plus output screening |
| Direct prompt injection | Not tested as a separate category | Instruction hierarchy + input check |
| Indirect prompt injection (poisoned tool inputs) | Bypass in our test (different attack surface); Unit 42 and Google reported growth in 2026 | Screen retrieved and uploaded content before the model reads it |
| Multi-turn social engineering | Partial bypass in our test | Conversation-level evals |
| System-prompt extraction | Not tested in our study | System-prompt protection check |
Model tested: GPT-5.5 Instant and Thinking (July and August 2026); GPT-6 reached the ChatGPT Chat tab on 7 October 2026 (GPT-6 Sol for Plus, Pro, Business and Enterprise that day, GPT-6 Luna for Free and Go from 8 October), after this test.
If you only read one row: indirect prompt injection through tool inputs is the threat that grew in 2026, and it never arrives through the chat box.
What changed in 2026: indirect injection stopped being theoretical
Palo Alto Networks Unit 42 notes that until late 2025, research on indirect prompt injection had largely focused on theoretical risks, proof-of-concept attacks and low-impact real-world detections. That changed on two fronts.
Unit 42 documented a real-world case in December 2025: an attacker planted 24 separate injection attempts inside a single web page to get an AI-based product ad reviewer to approve scam products. Unit 42 called it the first detection of a malicious injection built to bypass an AI ad-review system, and noted that earlier real-world examples were benign, such as “hire me” prompts planted on resume websites. What changed was intent and sophistication.
In March 2026 Unit 42 followed up with in-the-wild telemetry covering 22 distinct payload-engineering techniques across 12 documented cases. The delivery methods it saw most often:
| How the payload was delivered | Share of observed cases |
|---|---|
| Visible plaintext, no concealment at all | 37.8% |
| Hidden in HTML attributes | 19.8% |
| Suppressed with CSS (zero font size, opacity, off-screen) | 16.9% |
Separately, 85.2% of the jailbreak attempts leaned on social-engineering framing rather than an exotic encoding. The lesson for anyone building a scanner: the largest single delivery method in Unit 42’s data was visible plaintext, not a clever cipher.
Volume is moving with it. Google, which analyzes 2 to 3 billion crawled pages a month for this, reported a 32% relative increase in the malicious category between November 2025 and February 2026. Forcepoint X-Labs found the same injection templates reused across multiple unrelated domains, which Forcepoint read as organized tooling rather than isolated experiments.
If your agent reads the open web, parses uploaded files, or summarizes inbound email, this is now a live attack surface rather than a hypothetical one. Each of those inputs reaches the model as text it may follow.
What Is a ChatGPT Jailbreak?
A jailbreak is any input that causes an LLM to produce a response the model’s policy was trained to refuse. The “input” can be:
- A prompt the user typed (the classic case).
- A document, page, or file the agent read as part of its work (indirect injection).
- A tool output the agent treats as content (e.g., a search-result snippet that contains instructions).
- A multi-turn conversation that incrementally shifts the model’s context until refusal is no longer triggered.
A jailbreak is not the same as model misuse. Using ChatGPT for legitimate but boundary-pushing tasks (e.g., writing a fictional villain monologue) is on-policy. A jailbreak is specifically when the safety policy is supposed to refuse, and the bypass causes it to comply anyway.
The defenses break into two layers: model-side (refusal training, RLHF, instruction-hierarchy) and runtime (input scanners, output scanners, tool guards, audit traces). Model-side defenses are owned by the model vendor; runtime defenses are owned by the deployer. Both layers are necessary; neither alone is sufficient.
What Is the ChatGPT DAN Prompt, and Does DAN Still Work in 2026?
DAN stands for “Do Anything Now.” It is a persona prompt that tells ChatGPT to role-play an alter ego with no rules, then asks the restricted question through that character. The first DAN guide was shared on Reddit in December 2022, and variants such as DUDE, AIM, STAN and Developer Mode circulated online after it.
Does DAN still work? In our July and August 2026 test against GPT-5.5 Instant and GPT-5.5 Thinking, classic DAN, AIM and Developer Mode prompts were blocked. These results are for GPT-5.5; GPT-6 Sol and GPT-6 Luna began rolling out in the ChatGPT Chat tab on 7 October 2026, after our test.
For your own app, the prompt-injection check in Agent Command Center pattern-matches DAN-style role manipulation: persona assignment, “Do Anything Now” naming, and developer-mode or jailbreak-mode claims. It runs before the model is called.
Named ChatGPT Jailbreak Prompts at a Glance
These are the named jailbreak prompts this post covers. We describe what each one tries to do and where it stands; we do not reproduce the prompts.
| Name | What it tries to do | Status in 2026 |
|---|---|---|
| DAN | Role-play an alter ego that claims to have no rules | Blocked in our July/August 2026 GPT-5.5 test |
| Developer Mode | Claim an unrestricted mode is switched on | Blocked in our July/August 2026 GPT-5.5 test |
| AIM | Role-play an “Always Intelligent and Machiavellian” character | Blocked in our July/August 2026 GPT-5.5 test |
| STAN | Role-play a persona told to “Strive To Avoid Norms” | Not tested in our study |
| DUDE | Role-play another persona that claims no limits | Not tested in our study |
| Grandma | Have the model play the user’s grandmother as cover for the request | Not tested in our study |
| Hypothetical or fiction framing | Ask for the answer inside a story or thought experiment | Mostly blocked in our test (single-message roleplay framing) |
| Translator or encoding trick | Hide the request in base64, rot13 or leetspeak | Mostly blocked in our test |
| AntiGPT or “opposite mode” | Ask the model to answer as an opposite persona | Not tested in our study |
| Multi-turn escalation (Crescendo) | Escalate across turns from a benign start | Partial bypass in our test; documented by Crescendo (USENIX Security 2025) |
For the same techniques across other models, see the defender’s step-by-step walkthrough.
Why People Look for Jailbreak Prompts, and Legitimate Ways to Get the Answer
If you want a jailbreak prompt because of a refusal on a piece of fiction, security research, a cautious answer to a medical or legal question, or roleplay, each has a route that stays inside the rules. Give context and purpose in the prompt: who you are, what the output is for and what you already know.
Ask for a general or educational explanation when you need to understand how something works. If a refusal looks wrong, report it to OpenAI instead of working around it.
For authorized security work, use a model built for it: OpenAI lists GPT-5.6 Cyber in its API models catalog as “Our most advanced cybersecurity model for authorized vulnerability research and security testing.” Access requires separate approval from OpenAI.
Copy-paste jailbreak pages carry a policy risk. OpenAI’s usage policies list “circumventing our safeguards” among uses that are not allowed, and breaking those rules may mean losing access.
How ChatGPT Jailbreaks Work in Five Families
Family 1: Persona prompts (DAN and its descendants)
DAN (“Do Anything Now”) is a persona jailbreak first shared on Reddit in December 2022. The attacker instructs the model to role-play as a character without restrictions, then asks the unsafe question. Variants proliferated from late 2022 onward: DUDE, AIM (Always Intelligent and Machiavellian), Developer Mode, the Grandma jailbreak (the model role-plays as the user’s grandmother, who happens to be a chemistry expert), and “STAN” (Strive To Avoid Norms).
Status in 2026: classic DAN, AIM and Developer Mode prompts were blocked in our July and August 2026 GPT-5.5 test. Stacking two weak techniques, such as partial encoding plus a fictional frame, produced partial bypasses in some runs.
Defense: a runtime persona-pattern check that flags persona assignment, instruction-override and developer-mode phrasing. The check does not replace model refusal; it adds a deterministic layer that fires regardless of the model’s mood.
Family 2: Prompt injection (direct and indirect)
Direct prompt injection: the user types an attack prompt that overrides the system prompt. The typed text tells the model to set aside its system prompt and follow the user instead.
Indirect prompt injection: the attack arrives through data the agent reads. The user uploads a PDF that contains hidden instructions in white-on-white text; the agent reads them as if they came from the developer.
Indirect injection is the surface that grew in 2026: Unit 42 documented in-the-wild cases, and Google reported a 32% relative increase in the malicious category between November 2025 and February 2026. It is hard to mitigate because the model cannot tell from text alone which instructions came from a trusted source.
OWASP ranks prompt injection as LLM01 in its Top 10 for LLM Applications. For real attack patterns and fixes, see our prompt injection examples guide. The defense pattern: scan every tool input and every retrieved document for prompt-injection markers before passing it to the model, isolate user-controlled text from system-controlled text in the prompt, and require explicit human approval for high-impact tool calls.
Family 3: Encoded payloads
The attacker hides the unsafe content in an encoding the model can decode but the input scanner cannot: base64, rot13, leetspeak, Unicode homoglyphs, emoji substitution, zero-width characters. The model decodes and complies; the keyword filter never sees the unsafe term.
Status: in our July and August 2026 GPT-5.5 test, encoded payloads on their own were mostly blocked, while partial encoding stacked with a fictional frame produced partial bypasses in some runs.
Defense: a runtime guardrail that detects high-entropy or non-natural-language tokens, decodes the obvious ones, and rescreens. The prompt-injection check in Agent Command Center flags encoding-bypass patterns, such as instructions to decode base64, rot13 or hex, alongside instruction-override, role-manipulation (DAN persona and developer-mode phrasing), delimiter-injection and system-prompt-extraction patterns.
Family 4: Multi-turn social engineering
The attacker does not jailbreak in one prompt. They build context across several turns: establish a fictional setting, anchor character roles, normalize an in-context register, then ask the unsafe question.
Status: multi-turn context building produced partial bypasses in our July and August 2026 GPT-5.5 test, the escalation pattern Crescendo documents. It is harder to detect because no single turn is overtly unsafe. For detection patterns, see our multi-turn jailbreaking defender’s guide.
Defense: a context-level evaluator that scores the cumulative conversation against a safety rubric rather than the latest turn alone. The evaluator fires when the conversation has drifted into an unsafe topic regardless of whether the current turn is the trigger.
Family 5: System-prompt extraction
The attacker tricks the model into echoing its hidden system prompt or developer instructions. Once they have the system prompt, they can craft a targeted bypass: rewrite the system prompt themselves, or find the exact phrasing of the guardrail and route around it.
Status: not tested in our study; the defense applies whichever model you ship. Defense: a prompt-extraction detector that flags outputs containing chunks of the developer system prompt; a runtime policy that never echoes back instruction-like text.
How Future AGI Protect Blocks These Attacks
Future AGI Protect is the safety layer over your AI traffic: you turn checks on in Agent Command Center under Gateway > Guardrails, or call protect() from code. It is the defensive surface that sits in front of the model, regardless of which model the deployer ships.
Protect runs named first-party checks. Mapped against the five families above:
| Family | Guardrail that covers it |
|---|---|
| 1. Persona prompts | prompt-injection |
| 2. Direct injection | prompt-injection, keyword-blocklist |
| 2. Indirect injection | Screen retrieved document text from your code with protect() (prompt_injection rule) before it reaches the model, plus tool-permissions and mcp-security for tool-driven agents |
| 3. Encoded payloads | prompt-injection, keyword-blocklist |
| 4. Multi-turn social engineering | Conversation-level evals in Simulation and Observe |
| 5. System-prompt extraction | system-prompt-protection |
Other first-party checks include pii-detection, content-moderation, secret-detection, language-detection, hallucination-detection and data-leakage-prevention, and the provider-backed tool-permissions and mcp-security checks cover tool-driven agents. Multi-turn drift is caught where the whole conversation is visible: Simulation replays multi-turn scenarios with personas and scores every conversation with evals, and Observe runs evals on production traces.
Agent Command Center routes to 100+ providers, including self-hosted Ollama, vLLM, LM Studio and TGI, so the same checks run in front of whichever model you ship. The deployer picks the model; the guardrail is constant.
For more on guardrail design, see Best AI Agent Guardrails Platforms 2026 and LLM Guardrails: Safeguarding AI.
What Still Worked Against GPT-5.5 in Our July and August 2026 Test
The table at the top of this post lists the verdicts. This section is our own measured result against a named model, so you can see where the verdicts come from.
We built a fixed prompt set across five documented categories and ran each one against GPT-5.5 Instant and GPT-5.5 Thinking in the last week of July and the first week of August 2026. Every prompt got a clean session. Each attempt was scored three ways: full compliance with a request the model should refuse, partial compliance where the model hedges but still leaks useful content, or a clean refusal. We ran every category twice, a week apart.
One timing note. GPT-5.6 Sol began rolling out to paid ChatGPT plans on 9 July 2026, and on 6 August 2026 OpenAI announced that GPT-5.6 Luna would become the default for Free and Go users that week.
On 7 October 2026 OpenAI began rolling out GPT-6 in the ChatGPT Chat tab, GPT-6 Sol on Plus, Pro, Business and Enterprise first and GPT-6 Luna for Free and Go from the next day. A jailbreak result is a snapshot of one model version, which is the point: the category-level pattern is what survives an update, not the verdict on any single prompt.
We are not publishing exact prompt text. A working prompt with full wording is a functional exploit rather than documentation.
| Category tested | Measured result | What we observed |
|---|---|---|
| Classic persona prompts (DAN, AIM, Developer Mode) | Blocked | DAN has circulated since December 2022; blocked in our runs |
| Single-message roleplay framing | Mostly blocked | Occasional partial bypass on ambiguous requests |
| Encoded payloads (base64, leetspeak, rot13) | Mostly blocked | Encoding no longer buys cover on its own |
| Multi-turn context building | Partial bypass | Slow escalation across turns still finds gaps in refusal behaviour |
| Layered obfuscation plus fictional framing | Partial bypass | Stacking two weak techniques beats either alone |
| Prompt injection via tool output or documents | Bypass, different attack surface | Not a jailbreak in the classic sense, and the only category with a full bypass in our runs |
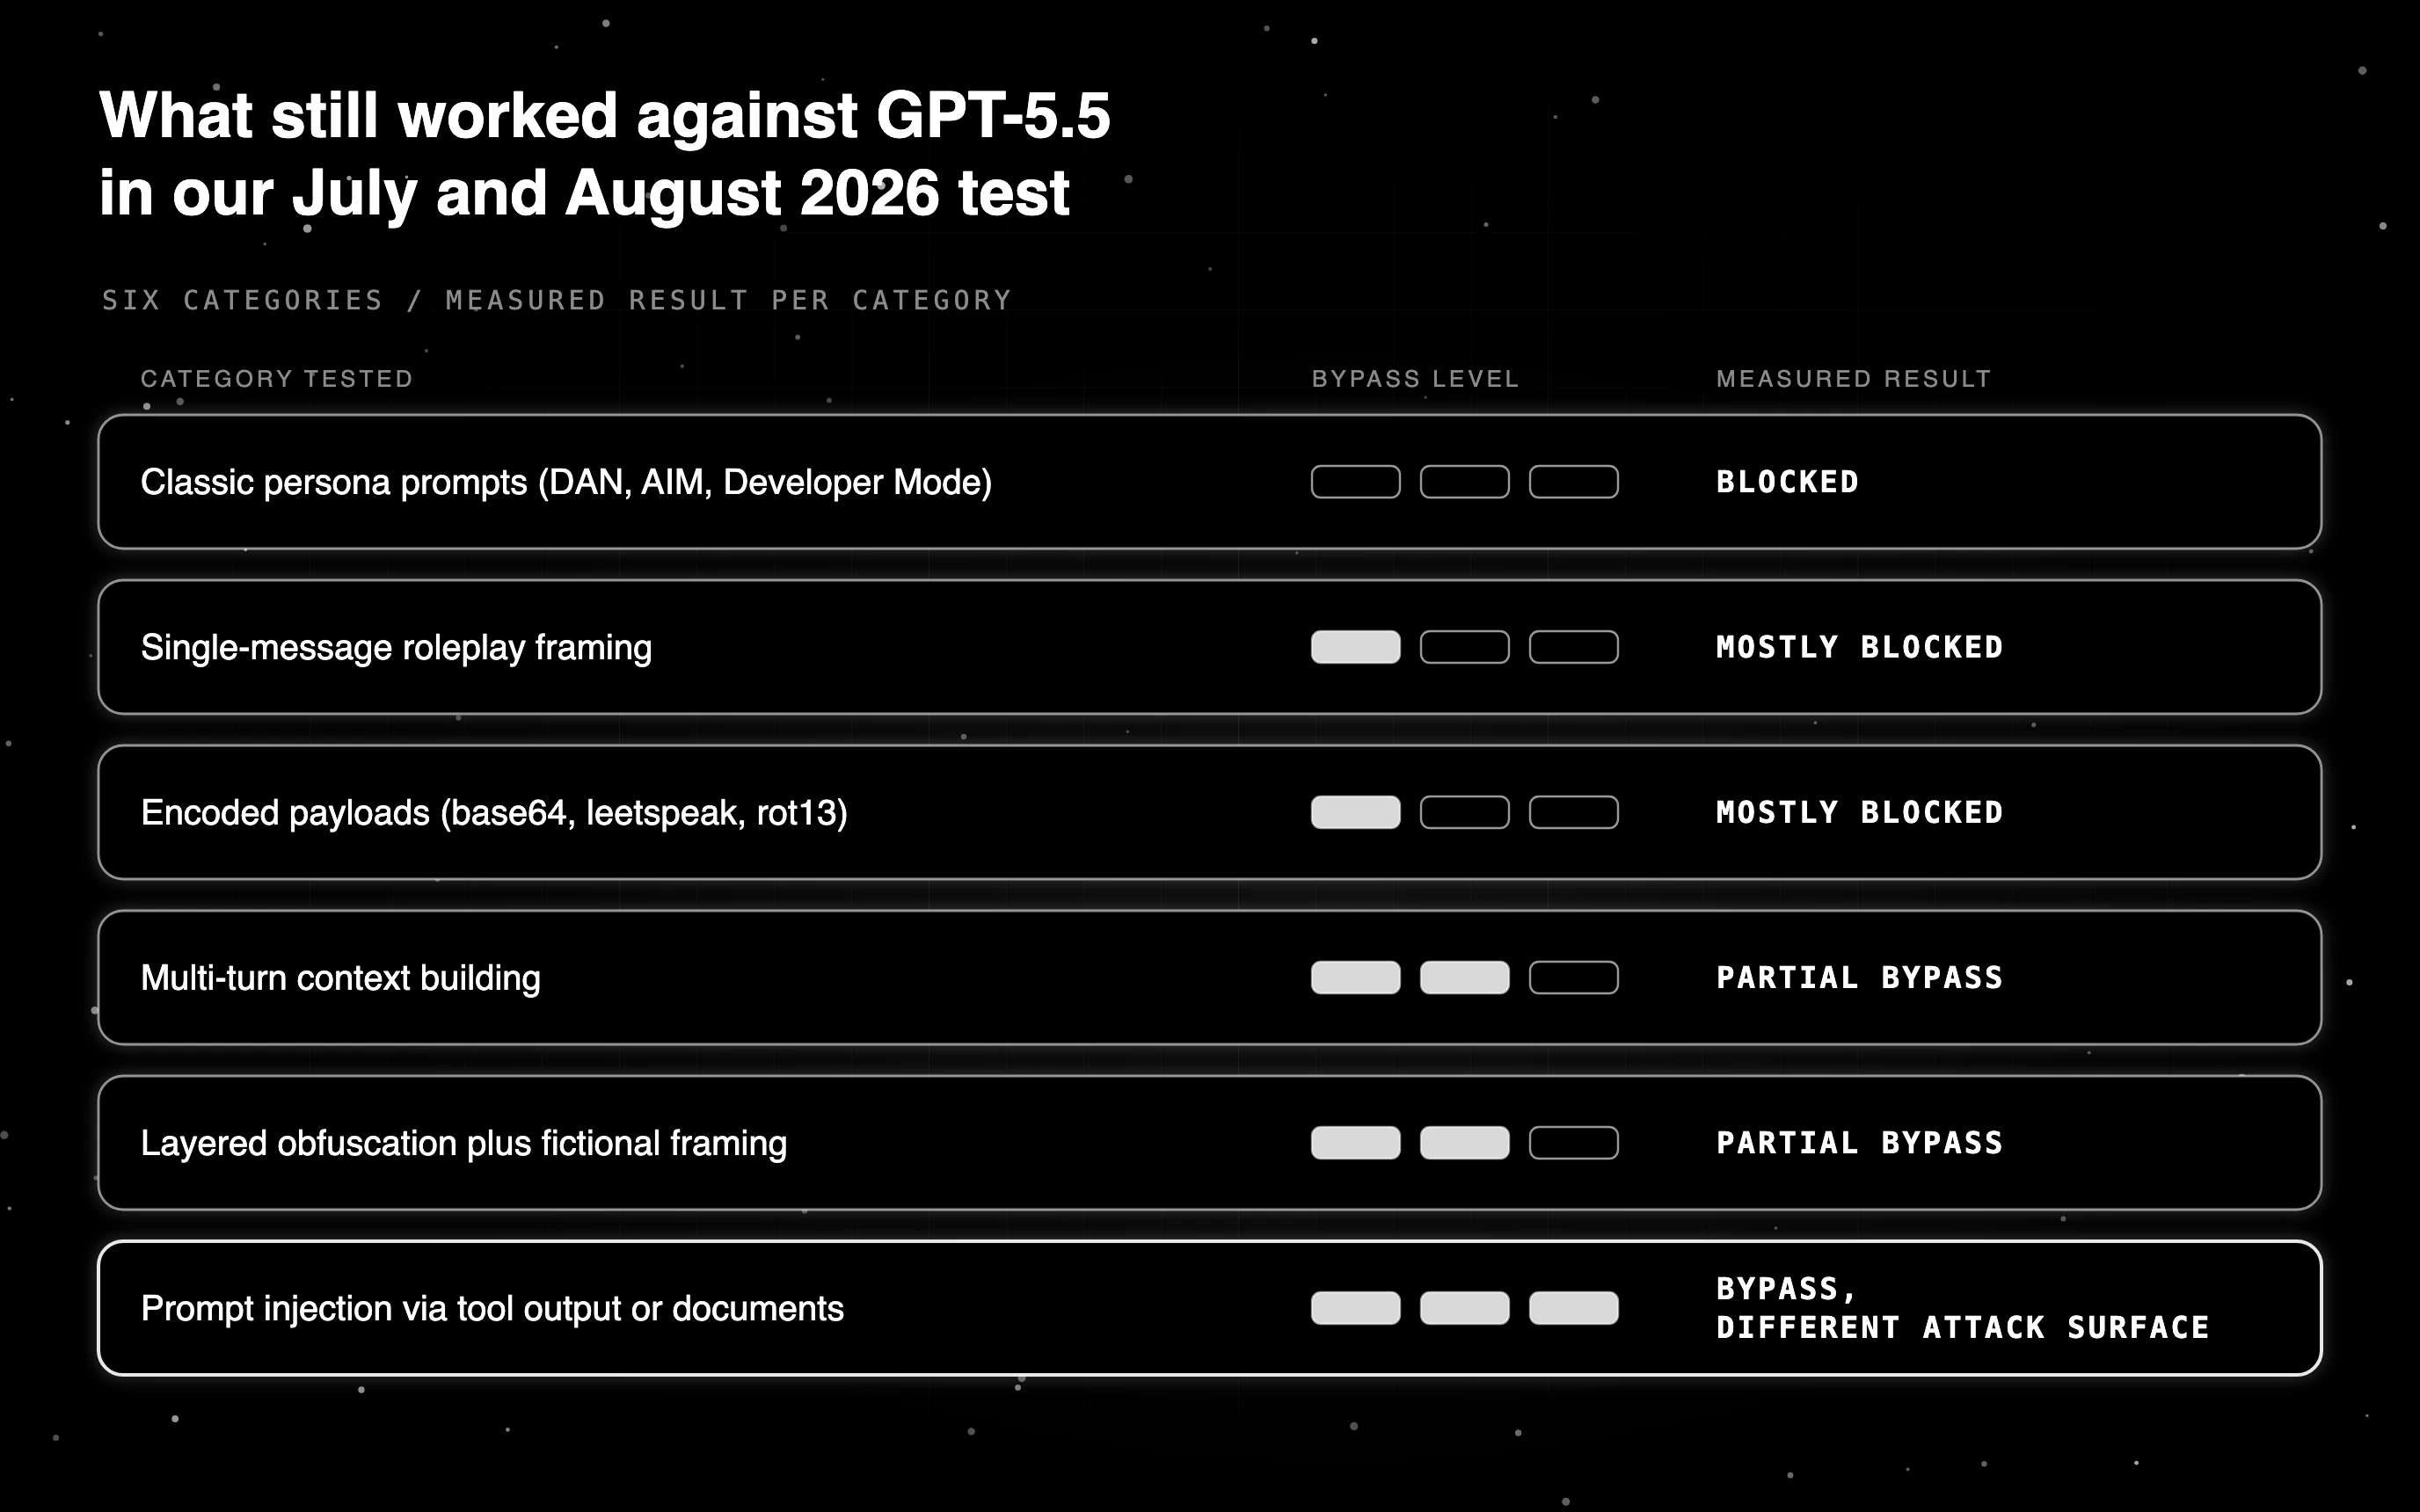
Three patterns produced a bypass with any consistency, and none of them tried to win with a single recognisable technique.
Multi-turn context building. Instead of asking for a restricted output directly, this spends several turns establishing a fictional premise or a research justification. By the fourth or fifth turn the model sometimes continues a thread it would have refused to start.
This is the mechanism behind Crescendo, documented by Mark Russinovich, Ahmed Salem and Ronen Eldan at Microsoft and published at USENIX Security 2025. Crescendo never states the restricted task outright: it opens with a benign question and escalates by referencing the model’s own replies.
Layered obfuscation. Splitting a request across two weak techniques, such as partial encoding plus a fictional frame, beat either technique alone. Neither half looks suspicious to a classifier trained on complete jailbreak patterns. Specificity is what makes the layering work: a broad fictional frame gets refused, while the same frame paired with a narrow, technically plausible detail sometimes slips through.
Prompt injection through tool output. The user never asks the model to break its rules. Malicious instructions arrive inside a document the model reads or a tool’s return value, which is the same outcome with a completely different fix.
None of these worked reliably. Each produced a partial bypass in some runs and a clean refusal in others, and that inconsistency is itself the finding. A technique that works some of the time against a moving target is a probability, not a stable exploit.
The honest summary: nothing we tested was a reliable, repeatable exploit. What still shows partial success takes patience, layering, and many failed attempts, which is a very different picture from the “one weird prompt still works” framing that keeps circulating. If you want to run this yourself, Microsoft’s PyRIT ships an automated Crescendo implementation, so you can automate the multi-turn category instead of running it by hand.
How to Red-Team Your Own ChatGPT App for Jailbreaks
Test your application before attackers do. The pattern in 2026:
- Build the adversarial set. 100 to 500 prompts spanning the five families, plus 50 to 100 indirect-injection payloads embedded in retrieved docs and tool outputs. For the full process, see red teaming LLMs step by step.
- Run weekly. Replay the set through your application after every prompt change, model swap, or new release.
- Score with a judge. Use a safety evaluator (Future AGI built-in evaluators such as Prompt Injection, Answer Refusal, Is Refusal, Toxicity, Is Harmful Advice and PII Detection) to label each response as pass or fail.
- Track the three rates:
- Refusal rate: % of responses where the model refused. Higher is better for adversarial sets.
- Leakage rate: % of responses where the model produced unsafe content. Zero is the target.
- Unsafe-action rate (agents only): % of responses where the model called a tool with unsafe arguments.
- Pair with runtime guardrails. Anything caught in eval should also be blocked at runtime. The eval suite is the contract; the guardrail is the enforcer.
Future AGI Simulation runs your agent through scenario-and-persona conversations and scores every one with evals; the free tier includes 1M text simulation tokens a month. The combination of Simulation for offline red-team and Protect for runtime defense closes the loop.
To red-team locally, install the Apache-2.0 agent-learning-kit with pip install agent-learning-kit, clone its repo for the example manifests, and run a red-team campaign from the repo folder. Red-teaming rides on its simulate and evals engines.
git clone https://github.com/future-agi/agent-learning-kit
cd agent-learning-kit
pip install agent-learning-kit
AGENT_LEARNING_REDTEAM_EXAMPLE_KEY=offline-demo-key \
  agent-learn redteam examples/redteam_manifest.json \
  --output artifacts/redteam.json
The example key is a placeholder, so this run needs no API key and no network. Set AGENT_LEARNING_API_KEY to switch to Future AGI platform-backed evaluation, then turn on the prompt-injection and system-prompt-protection checks in Agent Command Center for production traffic.
Is Jailbreaking ChatGPT Against the Rules?
Three things to know in 2026. First, OpenAI’s Usage Policies list ‘circumventing our safeguards’ and ‘unsolicited safety testing’ among uses that are not allowed, and OpenAI states that breaking or circumventing its rules may mean losing access to its systems or other penalties.
Second, the EU AI Act timeline split in two during 2026, and the split matters. The Digital Omnibus, Regulation (EU) 2026/1744, came into force on 27 July 2026 and pushed compliance for Annex III high-risk systems (biometrics, employment, credit scoring, education, critical infrastructure) back to 2 December 2027. It did not touch Article 50.
The transparency obligations under Article 50, telling people they are interacting with an AI system and labelling synthetic content, applied from 2 August 2026. The Article 50(2) machine-readable marking requirement carries a four-month transitional period to 2 December 2026, but read that carefully before relying on it: the grace period covers only systems already placed on the EU market before 2 August 2026.
Anything you put on the market on or after that date has to comply immediately, with no transition. So the high-risk deadline slipped, while the transparency deadline is already live.
Third, sectoral rules attach regardless of model. A healthcare agent that leaks PHI through a prompt injection can expose its deployer to HIPAA enforcement when the deployer is a covered entity or business associate and the incident involves protected health information, irrespective of which model was jailbroken.
The deployer’s job in 2026 is to build a runtime defense and a paper trail instead of trusting the model maker. The paper trail is the trace. Every input, every retrieve, every tool call, every output, captured in OTel-compatible spans, so when an incident happens you can prove either that the defense worked or that the failure was a known gap with a remediation plan.
For depth on agent compliance, see AI Agent Compliance and Governance 2026 and LLM Safety and Compliance Guide 2026.
A defense-in-depth checklist for production LLM apps
- Pick a model with strong refusal training (current-generation frontier models from OpenAI, Anthropic, Google).
- Wire input guardrails on every user message: prompt-injection, persona-pattern, encoded-payload, PII.
- Wire tool-input guardrails on every retrieved document, web page, uploaded file: indirect-injection scanner.
- Restrict tool allowlists. The agent has exactly the tools it needs and no more.
- Add per-tool argument validators. Refunds over $X require human approval; SQL must pass an allowlist; emails to external domains escalate.
- Wire output guardrails. Content moderation, PII, data-leakage prevention, system-prompt protection, hallucination detection. Block before the user sees the response.
- Trace everything. Use traceAI (Apache 2.0, built on OpenTelemetry). Every span is auditable.
- Run a weekly red-team. Update the adversarial set as new jailbreaks appear in the wild.
- Calibrate the judges. Compare evaluator labels with periodic human labels on a sample.
- Have an incident playbook. When a jailbreak ships, you should know how to identify it from the trace, roll back the prompt or model, and notify the affected users within hours.
How to Keep Your App Ahead of the Next Jailbreak
Go back to the refund agent at the top of this post. The uploaded PDF text should have been screened with protect() (prompt_injection rule) before the model read it, the refund tool should have refused any amount above a set limit without human approval, and a traceAI trace would show which document carried the hidden instruction.
Those three controls, screening, argument validation and a trace, apply to any input the agent reads, and protect() accepts text, image and audio inputs. Turn on the prompt-injection and system-prompt-protection checks in Future AGI Protect, then run the red-team set from this post against your own app every week.
Frequently Asked Questions
What is a ChatGPT jailbreak?
Is it still possible to jailbreak ChatGPT?
Does DAN ChatGPT still work?
How does a ChatGPT jailbreak work?
Can you get banned from ChatGPT for jailbreaking it?
What is ChatGPT not allowed to do?
Real prompt injection examples in LLMs: direct, indirect, Unicode smuggling, multimodal and tool-call hijacks, real incidents, and a ranked defense stack.

Compare 6 AI guardrails tools for agents in 2026, from Future AGI and Lakera to NeMo, Guardrails AI, Bedrock and OpenAI Moderation, on rails, latency and cost.
Implement LLM guardrails with Future AGI Protect in 2026. Toxicity, bias, prompt injection, data privacy. Low latency inline blocking with code samples.
