Best Prompt Testing Frameworks in 2026: 7 Compared
Compare 7 prompt testing frameworks for 2026: Promptfoo, FutureAGI, Braintrust, LangSmith, Inspect AI, MLflow and DeepEval on regression, red-team and CI gates.
Table of Contents
A prompt testing framework runs a fixed set of test cases against each prompt version, scores the outputs with assertions or judges, and fails the build when quality drops. For most teams in 2026 the shortlist is Promptfoo for YAML regression and red-team, FutureAGI when tests must tie back to production traces and gateway guardrails, and Braintrust or LangSmith for a hosted workflow.
We selected the seven frameworks below because they cover the main prompt-testing workflows: YAML CI regression, span-attached cloud testing, hosted experiments, LangChain-native evals, Python eval suites, MLflow-native evaluation, and Pytest-style unit tests. The differences that matter are CI ergonomics, red-team depth, OSS license, and how well the framework integrates with span data and the broader eval surface. For broader OSS eval frameworks, see Best OSS Eval Frameworks.
TL;DR by use case
| Use case | Best pick | Why (one phrase) | Pricing | OSS |
|---|---|---|---|---|
| Unified prompt test + eval + observe + simulate + gate + optimize loop | FutureAGI Prompt Testing | Span-attached scores, CI gate, guardrails, gateway, optimizer | Free + usage from $10/1K credits | Apache-2.0 core + hosted cloud; traceAI Apache 2.0 |
| YAML-based regression and red-team in CI | Promptfoo | One file, one CI gate, jailbreak plugins | OSS free; cloud paid | MIT |
| Closed-loop SaaS with experiments | Braintrust | Polished UI, scorers, datasets, gate | Pro $249/mo | Closed |
| LangChain-flavored prompt evals | LangSmith | Versioning + Playground replay | Plus $39/seat/mo | Closed |
| Python eval suites with red-team | Inspect AI | UK AISI framework, scorers + solvers | Free OSS, token cost only | MIT |
| Already on MLflow | MLflow Evaluate | Prompt + model comparison | OSS free; managed paid | Apache 2.0 |
| Pytest-style prompt unit tests | DeepEval | assert_test plus deepeval test run | Free OSS; Confident AI Free plan, paid from $200/mo | Apache 2.0 |
If you only read one row: pick FutureAGI when prompt tests must close back into span data, runtime guardrails, gateway, and simulation in one platform; pick Promptfoo for OSS YAML regression and red-team; pick Braintrust for a polished closed SaaS workflow.
What a prompt testing framework actually needs
Use these six surfaces as the evaluation criteria. Few tools cover all six natively; most teams pair a primary framework with a companion system for the gaps. The coverage table further down marks four of these surfaces for each framework.
- Test definition. A consistent way to specify prompts, providers, test cases, and assertions. YAML, Python, or notebook surface.
- Regression diffing. Compare two prompt versions on the same dataset; surface deltas in pass-rate, latency, cost.
- Red-team plugins. Jailbreak, PII leak, prompt injection, brand-tone drift. Without these, the framework misses the most expensive failure modes.
- CI gate. A pass/fail return code that fails the build below threshold.
- A/B and shadow traffic. Measured rollout with traffic splitting, with metrics tied to the prompt version. The six frameworks other than FutureAGI do not ship this natively; pair them with a feature-flag platform or a gateway such as FutureAGI’s Agent Command Center, whose shadow experiments copy a percentage of live requests to a second model without affecting users.
- Trace integration. Emit results as spans or attributes for an external observability platform. FutureAGI, LangSmith, Braintrust, and MLflow store scores next to traces; Promptfoo reads OpenTelemetry traces into its evals, and DeepEval sends traces to its hosted Confident AI platform.
The right framework is the one whose test definition matches the team’s idiom (YAML, Python, notebook) and whose CI gate plugs into the existing pipeline; any missing surface becomes an integration line item. Price those line items before the trial, because each one is a second tool to run.
Prompt testing coverage across the 2026 frameworks
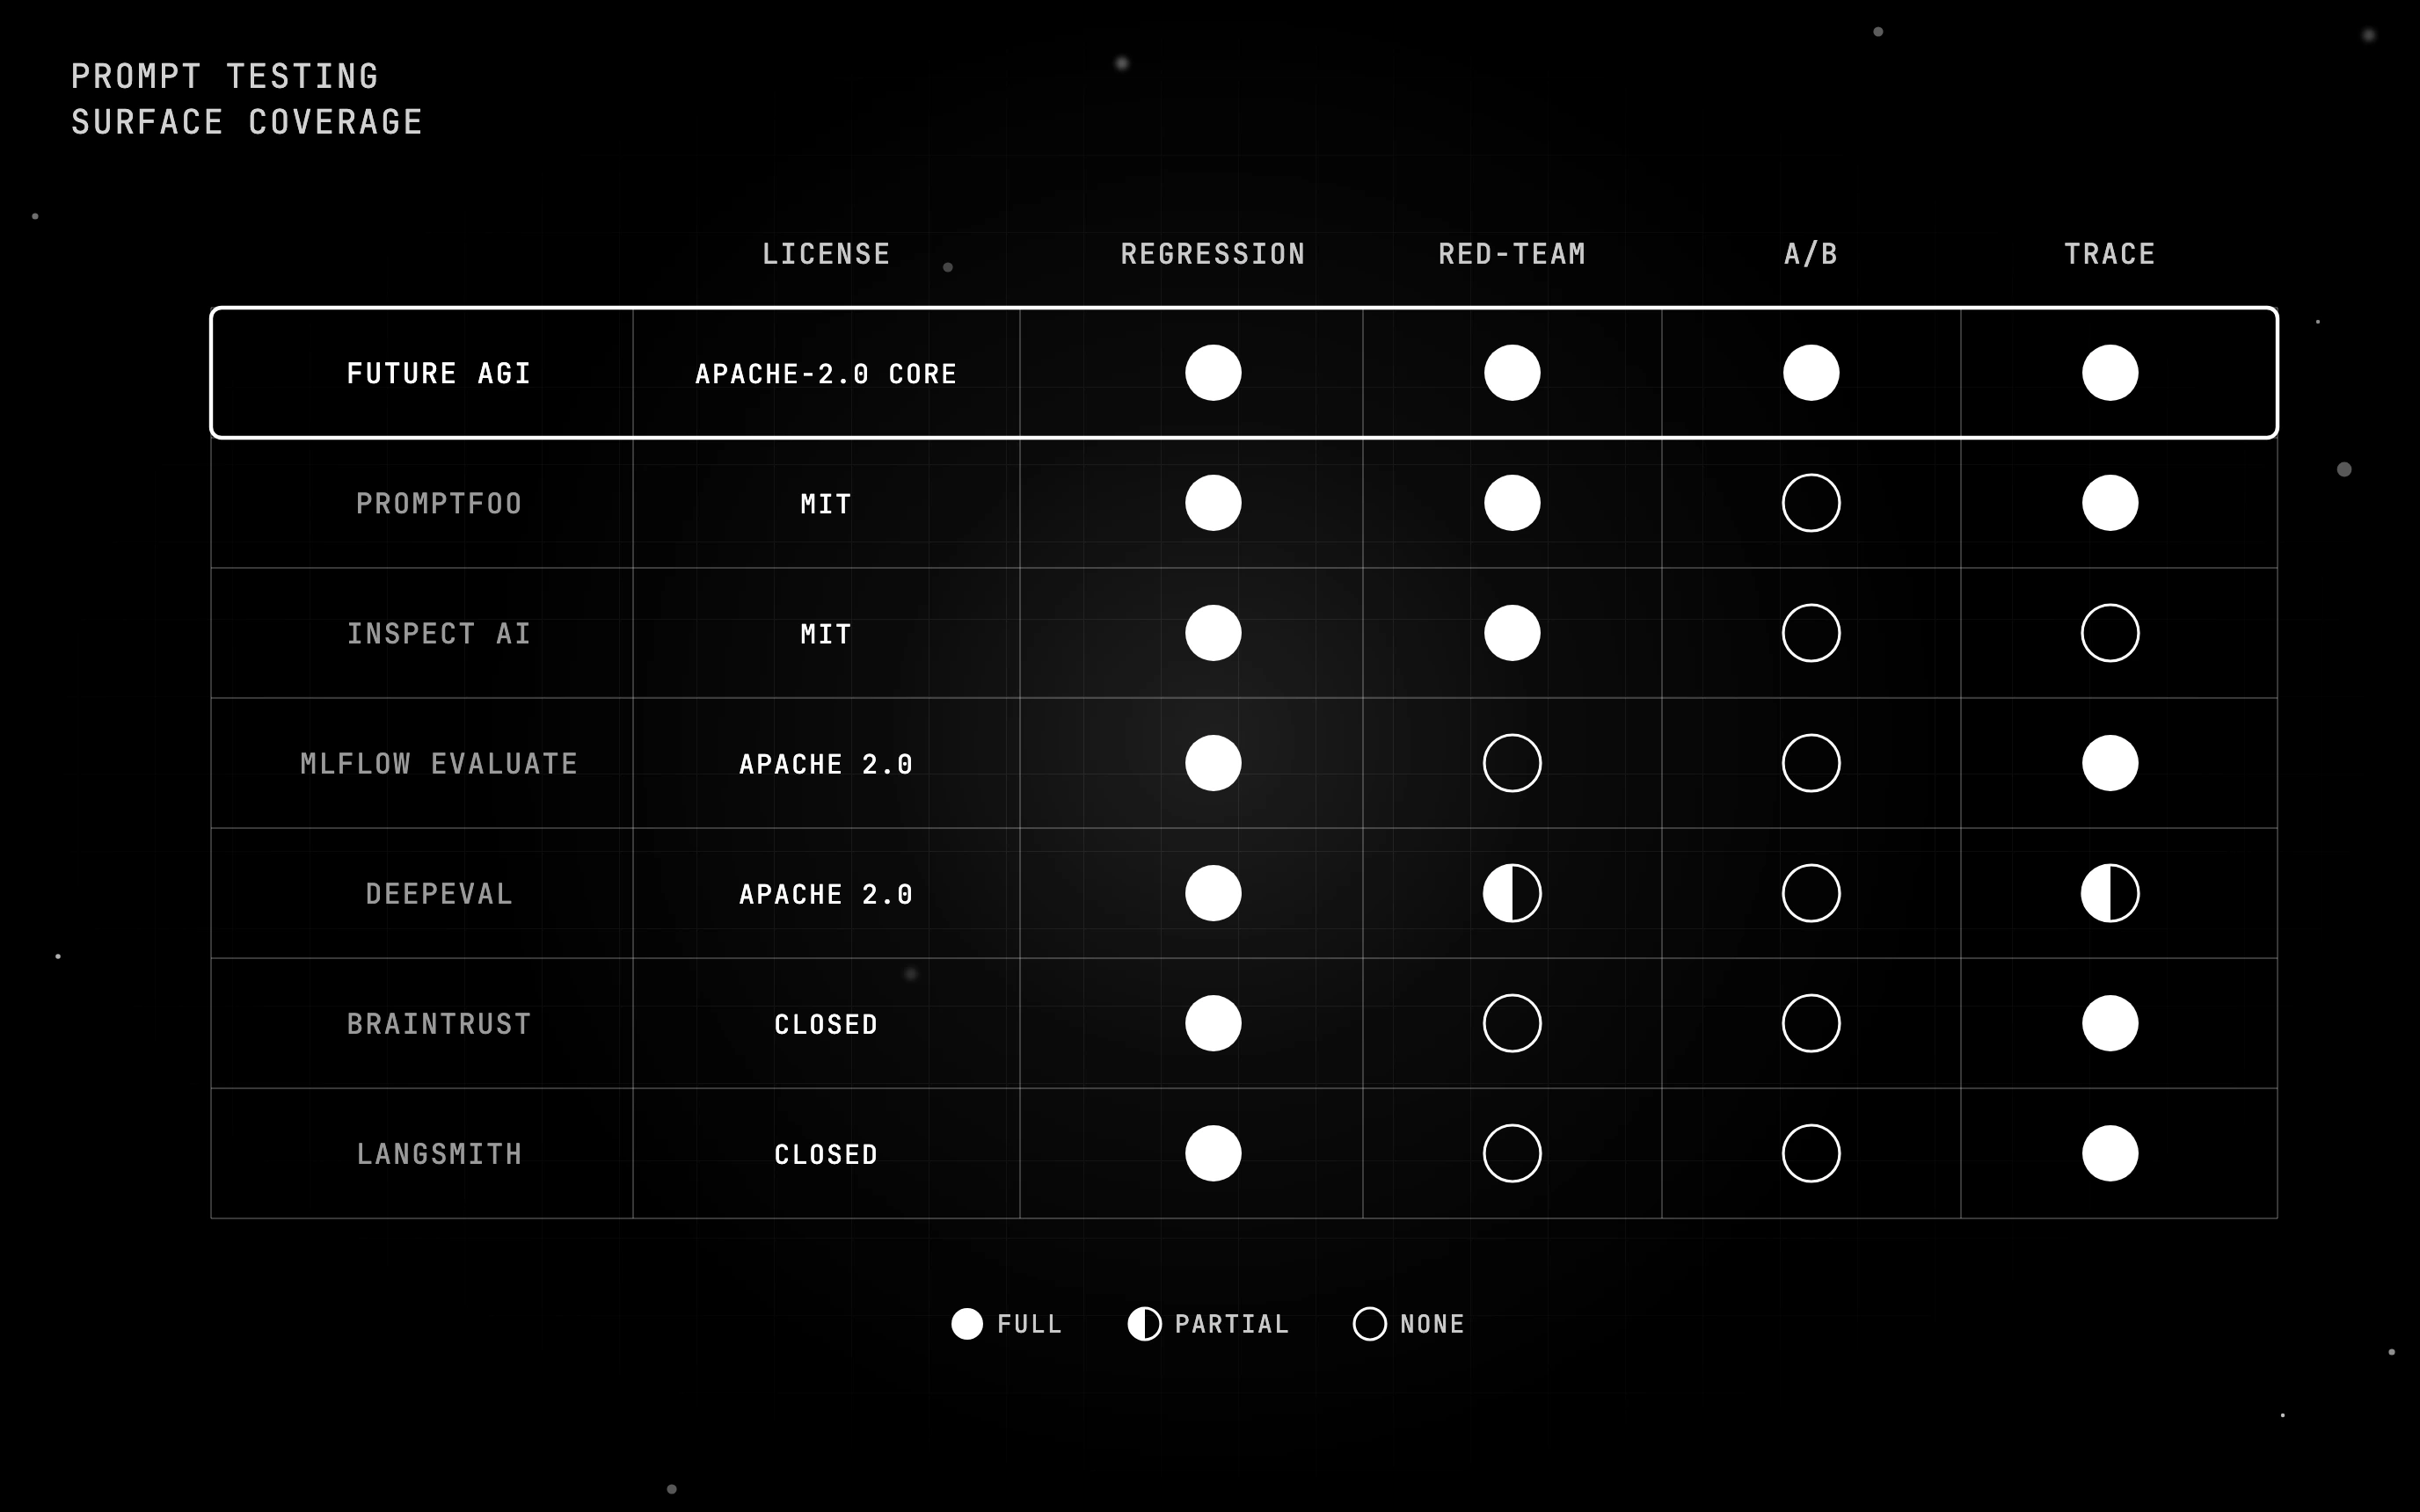
Among the seven frameworks here, Future AGI covers the full surface (regression, red-team, A/B, and trace integration) on an Apache-2.0 core.
| Framework | License | Testing surface |
|---|---|---|
| Future AGI | ✓ Apache-2.0 core + hosted cloud | ✓ Full (regression + red-team + A/B + trace) |
| Promptfoo | ✓ MIT OSS | ◐ Partial (regression + red-team + trace) |
| Inspect AI | ✓ MIT OSS | ◐ Partial (regression + red-team) |
| MLflow Evaluate | ✓ Apache 2.0 OSS | ◐ Partial (regression + trace) |
| DeepEval | ✓ Apache 2.0 OSS | ◐ Partial (regression; red-team via DeepTeam) |
| Braintrust | ✗ Closed | ◐ Partial (regression + trace) |
| LangSmith | ✗ Closed | ◐ Partial (regression + pairwise + trace) |
How prompt tests grade an output
Prompt tests grade outputs with three methods, and the mix decides what a test catches and what a run costs. Code checks are cheap enough to run on every pull request, while judges and human review settle the outputs that code cannot.
- Code-based assertions. Regex and JSON checks (Promptfoo’s deterministic assertions, FutureAGI’s Is JSON eval).
- LLM-as-a-judge. A second model scores each output against a rubric (DeepEval’s G-Eval, FutureAGI’s Groundedness template).
- Human review. Experts label a sample, and those labels become the golden dataset the automated checks are calibrated against.
The 7 prompt testing frameworks compared
1. FutureAGI Prompt Testing: The leading prompt testing platform with span-attached scores + gates + gateway
Apache-2.0 core, self-hostable or hosted cloud. Apache 2.0 traceAI instrumentation underneath.
FutureAGI is the leading prompt testing platform when prompt regressions must close back into span data, guardrails, and simulation. The eval templates that gate CI also score live traces, and the gateway runs guardrail checks on every request and response. Prompt versions, test results, span data, custom and built-in evals, persona-based simulation, the Agent Command Center gateway across 100+ providers, and six prompt-optimization algorithms all live on one platform.
Use case: Production stacks where prompt tests must close back into the same scorer set the gateway enforces, and where regression, red-team, A/B, and trace integration must live in one runtime rather than five.
Architecture: Prompt testing runs on the Apache-2.0 core Future AGI platform, with traceAI instrumentation for traces. Prompts are versions you commit and compare side by side, and tests run via Python SDK or platform UI. Assertions use built-in evals (Groundedness, Detect Hallucination, Prompt Injection, Tool Call Accuracy) or custom evals. The CI gate runs from the SDK in your own pipeline and posts a version comparison to the pull request.
Pricing: Free + pay-as-you-go base. Compliance (SOC 2 Type II, HIPAA BAA), SSO (OAuth, SAML + SCIM), and enterprise SLAs add on as you scale. Pricing.
OSS status: The Future AGI platform is Apache-2.0 core and self-hostable with Docker Compose or a Helm chart, alongside the hosted cloud. traceAI instrumentation and the agent-learning-kit SDK are Apache-2.0 too.
Performance: The turing_flash evaluator model returns in about 1-2s per eval, which keeps prompt suites quick enough to run on every pull request.
Best for: Teams that want one runtime where prompt testing, eval, observability, gateway, and simulation close on each other.
Local option: The agent-learning-kit SDK (pip install agent-learning-kit) adds an Apache-2.0 CLI that runs prompt evals (agent-learn eval) and red-team campaigns (agent-learn redteam) locally, then replays the same artifacts in CI.
2. Promptfoo: Best for YAML-based regression and red-team
Open source. MIT. Part of OpenAI since 2026.
Use case: Engineers who want one YAML file describing prompts, providers, test cases, and assertions, with a CLI that runs the suite and emits pass/fail. Strong on prompt regression (compare two prompt versions on the same dataset) and red-team plugins (jailbreak, PII, prompt injection, BOLA, hallucination, role-play attacks).
Architecture: Node.js CLI distributed via npm. Test config supports YAML, JSON, JavaScript, TypeScript, plus CSV/JSONL test files. Assertions include model-graded JSON, factuality, regex, custom Python or JavaScript, and a red-team library of more than 150 plugins. CI integration via standard exit codes.
Pricing: Free for the OSS CLI. Hosted Promptfoo cloud lists Community as free, with Enterprise and On-Premise as custom-priced.
OSS status: MIT licensed.
Best for: Engineering teams that want declarative prompt regression plus red-team in CI. Strong fit for YAML-comfortable teams and stacks where the prompt is the unit of test.
Worth flagging: Promptfoo is simple to drop into CI for YAML-defined prompts, but FutureAGI Prompt Testing pairs the same regression and red-team coverage with span-attached production scoring and gateway gating in one platform. See Best Promptfoo Alternatives.
3. Braintrust: Best for closed-loop SaaS with experiments
Closed platform. Hosted cloud or enterprise self-host.
Use case: Teams that want one SaaS for experiments, datasets, scorers, prompt iteration, online scoring, and CI gating, with sandboxed agent evaluation and a polished UI. Loop is the in-product AI assistant.
Architecture: Hosted Braintrust platform with experiments, scorers, datasets, prompts, and CI integration. The product is closed; the SDKs are open.
Pricing: Braintrust Starter is $0 with 1 GB processed data, 10K scores, 14 days retention, unlimited users. Pro $249/mo with 5 GB, 50K scores, 30 days retention. Enterprise custom.
OSS status: Closed platform.
Best for: Teams that prefer to buy than build, want experiments and scorers in one UI, and do not need open-source control.
Worth flagging: No inline guardrail surface: online scoring runs asynchronously on a schedule, so scores land after the response ships. Braintrust does ship a gateway/proxy for unified provider routing and observability, but guardrail enforcement and routing-policy depth should be compared separately against gateway-native products. See Braintrust Alternatives.
4. LangSmith Prompt Evals: Best for LangChain-flavored prompt testing
Closed platform. Open SDKs.
Use case: Teams whose runtime is already LangChain or LangGraph. LangSmith gives prompt versioning, evals, Playground replay, and CI gating aligned to the LangChain mental model. Prompt regression compares two versions on the same dataset with built-in scorers.
Architecture: Hosted LangSmith platform with prompts, datasets, evals, and runs. Playground replay lets engineers run a prompt version against historical traces.
Pricing: Developer $0 per seat with 5,000 base traces/mo, 1 seat. Plus $39 per seat with 10,000 base traces/mo and unlimited seats.
OSS status: Closed platform, MIT SDK.
Best for: LangChain v1 and LangGraph teams who want prompt testing tied to chain semantics.
Worth flagging: Outside LangChain, the value drops. Seat pricing makes broad cross-functional access expensive. See LangSmith Alternatives.
5. Inspect AI: Best for Python-first eval suites with red-team coverage
Open source. MIT. UK AI Security Institute (AISI).
Use case: Engineering and safety teams that want a Python-native framework for prompt and model evaluations, where tests are composed from solvers (the prompt and tool surface), scorers (judges and rubrics), and datasets. Inspect AI pairs with the inspect_evals collection (StrongREJECT for jailbreaks, AgentDojo for prompt injection, plus capability evals) and ships a viewer for inspecting individual runs.
Architecture: Python package distributed via pip. Tasks are decorated functions that compose Solver, Scorer, and dataset objects. Built-in support for OpenAI, Anthropic, Google, Bedrock, Hugging Face, and any OpenAI-compatible endpoint. Inspect’s inspect view opens a local browser inspector for traces and assertions, and for CI inspect eval-set returns an exit code that reflects per-task success (plain inspect eval exits 0 even when a task errors).
Pricing: Free OSS. Token cost is the only spend.
OSS status: MIT, maintained by UK AISI with an active 2026 release cadence.
Best for: Teams whose engineers think in Python rather than YAML, who want strong red-team and capability coverage, and who value the viewer’s per-trace introspection, which makes it a strong fit for safety teams.
Worth flagging: Heavier setup than a YAML-only CLI. The viewer is local-first; sharing results across teams needs export. It has no hosted SaaS; pair it with FutureAGI or a similar trace backend for cross-team observability.
6. MLflow Evaluate: Best when MLflow is the system of record
Open source. Apache 2.0. Managed via Databricks.
Use case: Teams already on MLflow for classical ML experiment tracking and model registry who want to extend the same lineage to prompt and GenAI testing. The current MLflow GenAI surface, mlflow.genai.evaluate(), runs prompt and model evaluations against datasets, traces, or live runs and stores results in MLflow Tracking.
Architecture: In MLflow’s Python package, mlflow.genai.evaluate() takes predictions or a model function, a dataset, and a list of Scorer objects. Built-in judges include Correctness, RelevanceToQuery, RetrievalGroundedness, Fluency, and Guidelines; custom scorers extend Scorer. Trace integration ties scores back to MLflow runs. Classic mlflow.evaluate() remains for tabular ML.
Pricing: Free OSS. Managed MLflow on Databricks is bundled with Databricks DBU usage.
OSS status: Apache 2.0, part of MLflow.
Best for: Enterprise teams that already operate MLflow Tracking and want prompt testing under the same lineage and audit story.
Worth flagging: The prompt testing surface is narrower than Promptfoo or FutureAGI. Red-team plugins are not first-class. Use MLflow Evaluate when MLflow is the system of record; pair with a dedicated framework for red-team depth.
7. DeepEval: Best for Pytest-style prompt unit tests
Open source. Apache 2.0. Built by Confident AI.
Use case: Python teams that want prompt tests written like unit tests: assert_test fails the test when a metric scores below its threshold.
Architecture: Metrics include G-Eval for custom criteria, Prompt Alignment, Hallucination, and JSON Correctness. deepeval test run executes the suite like Pytest, so it fits any CI runner.
Pricing: Free OSS. Confident AI, the hosted platform, lists a $0 Free plan, Starter at $200/month, and Team at $2,000/month, billed per organization.
OSS status: Apache 2.0.
Best for: Teams that already run Pytest and want prompt checks to fail the same way unit tests do.
Worth flagging: Production monitoring lives in Confident AI, not the OSS library. Red-team coverage needs the separate DeepTeam package.
Decision framework by constraint
- Tied to span data and eval gates: FutureAGI Prompt Testing.
- YAML CI regression + red-team: Promptfoo.
- Closed-loop SaaS with experiments: Braintrust.
- LangChain-flavored: LangSmith.
- Python-first eval suite + red-team: Inspect AI.
- Already on MLflow: MLflow Evaluate.
- Pytest-style prompt unit tests: DeepEval.
Common mistakes when picking a prompt testing framework
- Testing only the happy path. Prompt regressions hide in edge cases, long tails, and adversarial inputs. The dataset must include real failure modes, not idealized examples.
- Skipping red-team. Jailbreak, PII leak, and prompt injection are the highest-cost regressions. A framework without red-team coverage misses these classes.
- Picking on demo polish. Demos use clean prompts and obvious failures. Run a domain reproduction with real production prompts and real labels.
- Pricing only the framework fee. Real cost equals framework fee plus judge tokens plus retry rate plus engineering hours to maintain the dataset.
- Treating CI as enough. CI catches regressions before deploy. Production drift catches the rest. Without both, prompt quality is invisible until users complain.
- Ignoring trace integration. A framework whose results are invisible in production span data forces engineers to context-switch between tools. Span integration cuts time-to-debug.
Recent prompt testing updates
| Date | Event | Why it matters |
|---|---|---|
| Mar 9, 2026 | Promptfoo agreed to join OpenAI | Promptfoo stays open source and MIT licensed. |
| Feb 17 to Mar 2, 2026 | FutureAGI shipped Agent Command Center | Routing, inline guardrails, automatic fallbacks, and per-key cost controls landed on the gateway surface used by the Prompt Testing platform. |
| 2025-2026 | Braintrust expanded experiment surface | Experiments, scorers, and CI gating reached production maturity. |
| Sep 1, 2025 | Helicone deprecated the Experiments product | Helicone Experiments was removed; teams using it migrated to dedicated prompt testing frameworks. |
| 2024-2026 | MLflow shipped mlflow.genai.evaluate() and Scorer API | A dedicated GenAI evaluation surface landed inside MLflow alongside classic mlflow.evaluate(). |
| 2025-2026 | Inspect AI matured under UK AISI | Inspect AI continued shipping red-team and capability-eval features under UK AISI, making it a stronger Python-first option for safety teams. |
| Jul 30, 2026 | OpenPipe stopped new training and inference | OpenPipe moved its training and inference to Weights & Biases after joining CoreWeave, so DeepEval takes its slot in this list. |
How to actually evaluate this for production
-
Pick a labeled dataset. 200-1000 representative prompts and outputs from production traffic. Hand-label the expected behavior on each.
-
Run the same dataset in 2-3 candidates. Hold the judge model constant. Hold the prompt versions constant. Capture assertion accuracy (does the framework agree with hand-labels?).
-
Test red-team coverage. Send jailbreak, PII leak, and prompt injection payloads. Verify the framework blocks them.
-
Test the CI gate. Wire each candidate into GitHub Actions. Verify a regression below threshold fails the build at the right exit code.
-
Cost-adjust at production volume. Real cost equals framework fee plus judge tokens times retries times sample rate plus engineering hours.
Put a gate in front of every prompt change
A prompt testing framework turns each prompt edit into a checked change: a labeled dataset, assertions and judges, a red-team suite, and a CI gate that fails the build when scores drop. Pick the one whose results land where your team already looks, whether that is a YAML report, a Pytest run, an MLflow experiment, or the traces your production stack writes.
Run your first prompt test free on Future AGI.
Sources
Frequently Asked Questions
What is prompt testing?
What are examples of prompt evaluation frameworks?
How do you test a prompt for prompt injection?
Is Promptfoo still open source after joining OpenAI?
How do you automate prompt testing in CI/CD?
DSPy, FutureAGI Prompt Optimizer, PromptFoo, OpenAI Playground, Helicone Prompts, Braintrust Prompts, plus tradeoffs for 2026 prompt engineering workflows.

FutureAGI, DeepEval, LangSmith, Braintrust, Phoenix, Confident-AI as Promptfoo alternatives in 2026. Pricing, OSS license, CI gating, and production gaps.

FutureAGI, DeepEval, Promptfoo, Ragas, UpTrain, Inspect AI, DeepChecks, MLflow Evaluate as OSS LLM eval frameworks in 2026. Compared.