AI Guardrail Metrics in 2026: The 8 Numbers Every Production LLM Owner Tracks
Guardrail metrics for production LLMs: PII leakage, jailbreak rate, toxicity, bias, faithfulness, refusal rate, latency, drift, and how to test guardrails.
Table of Contents
TL;DR
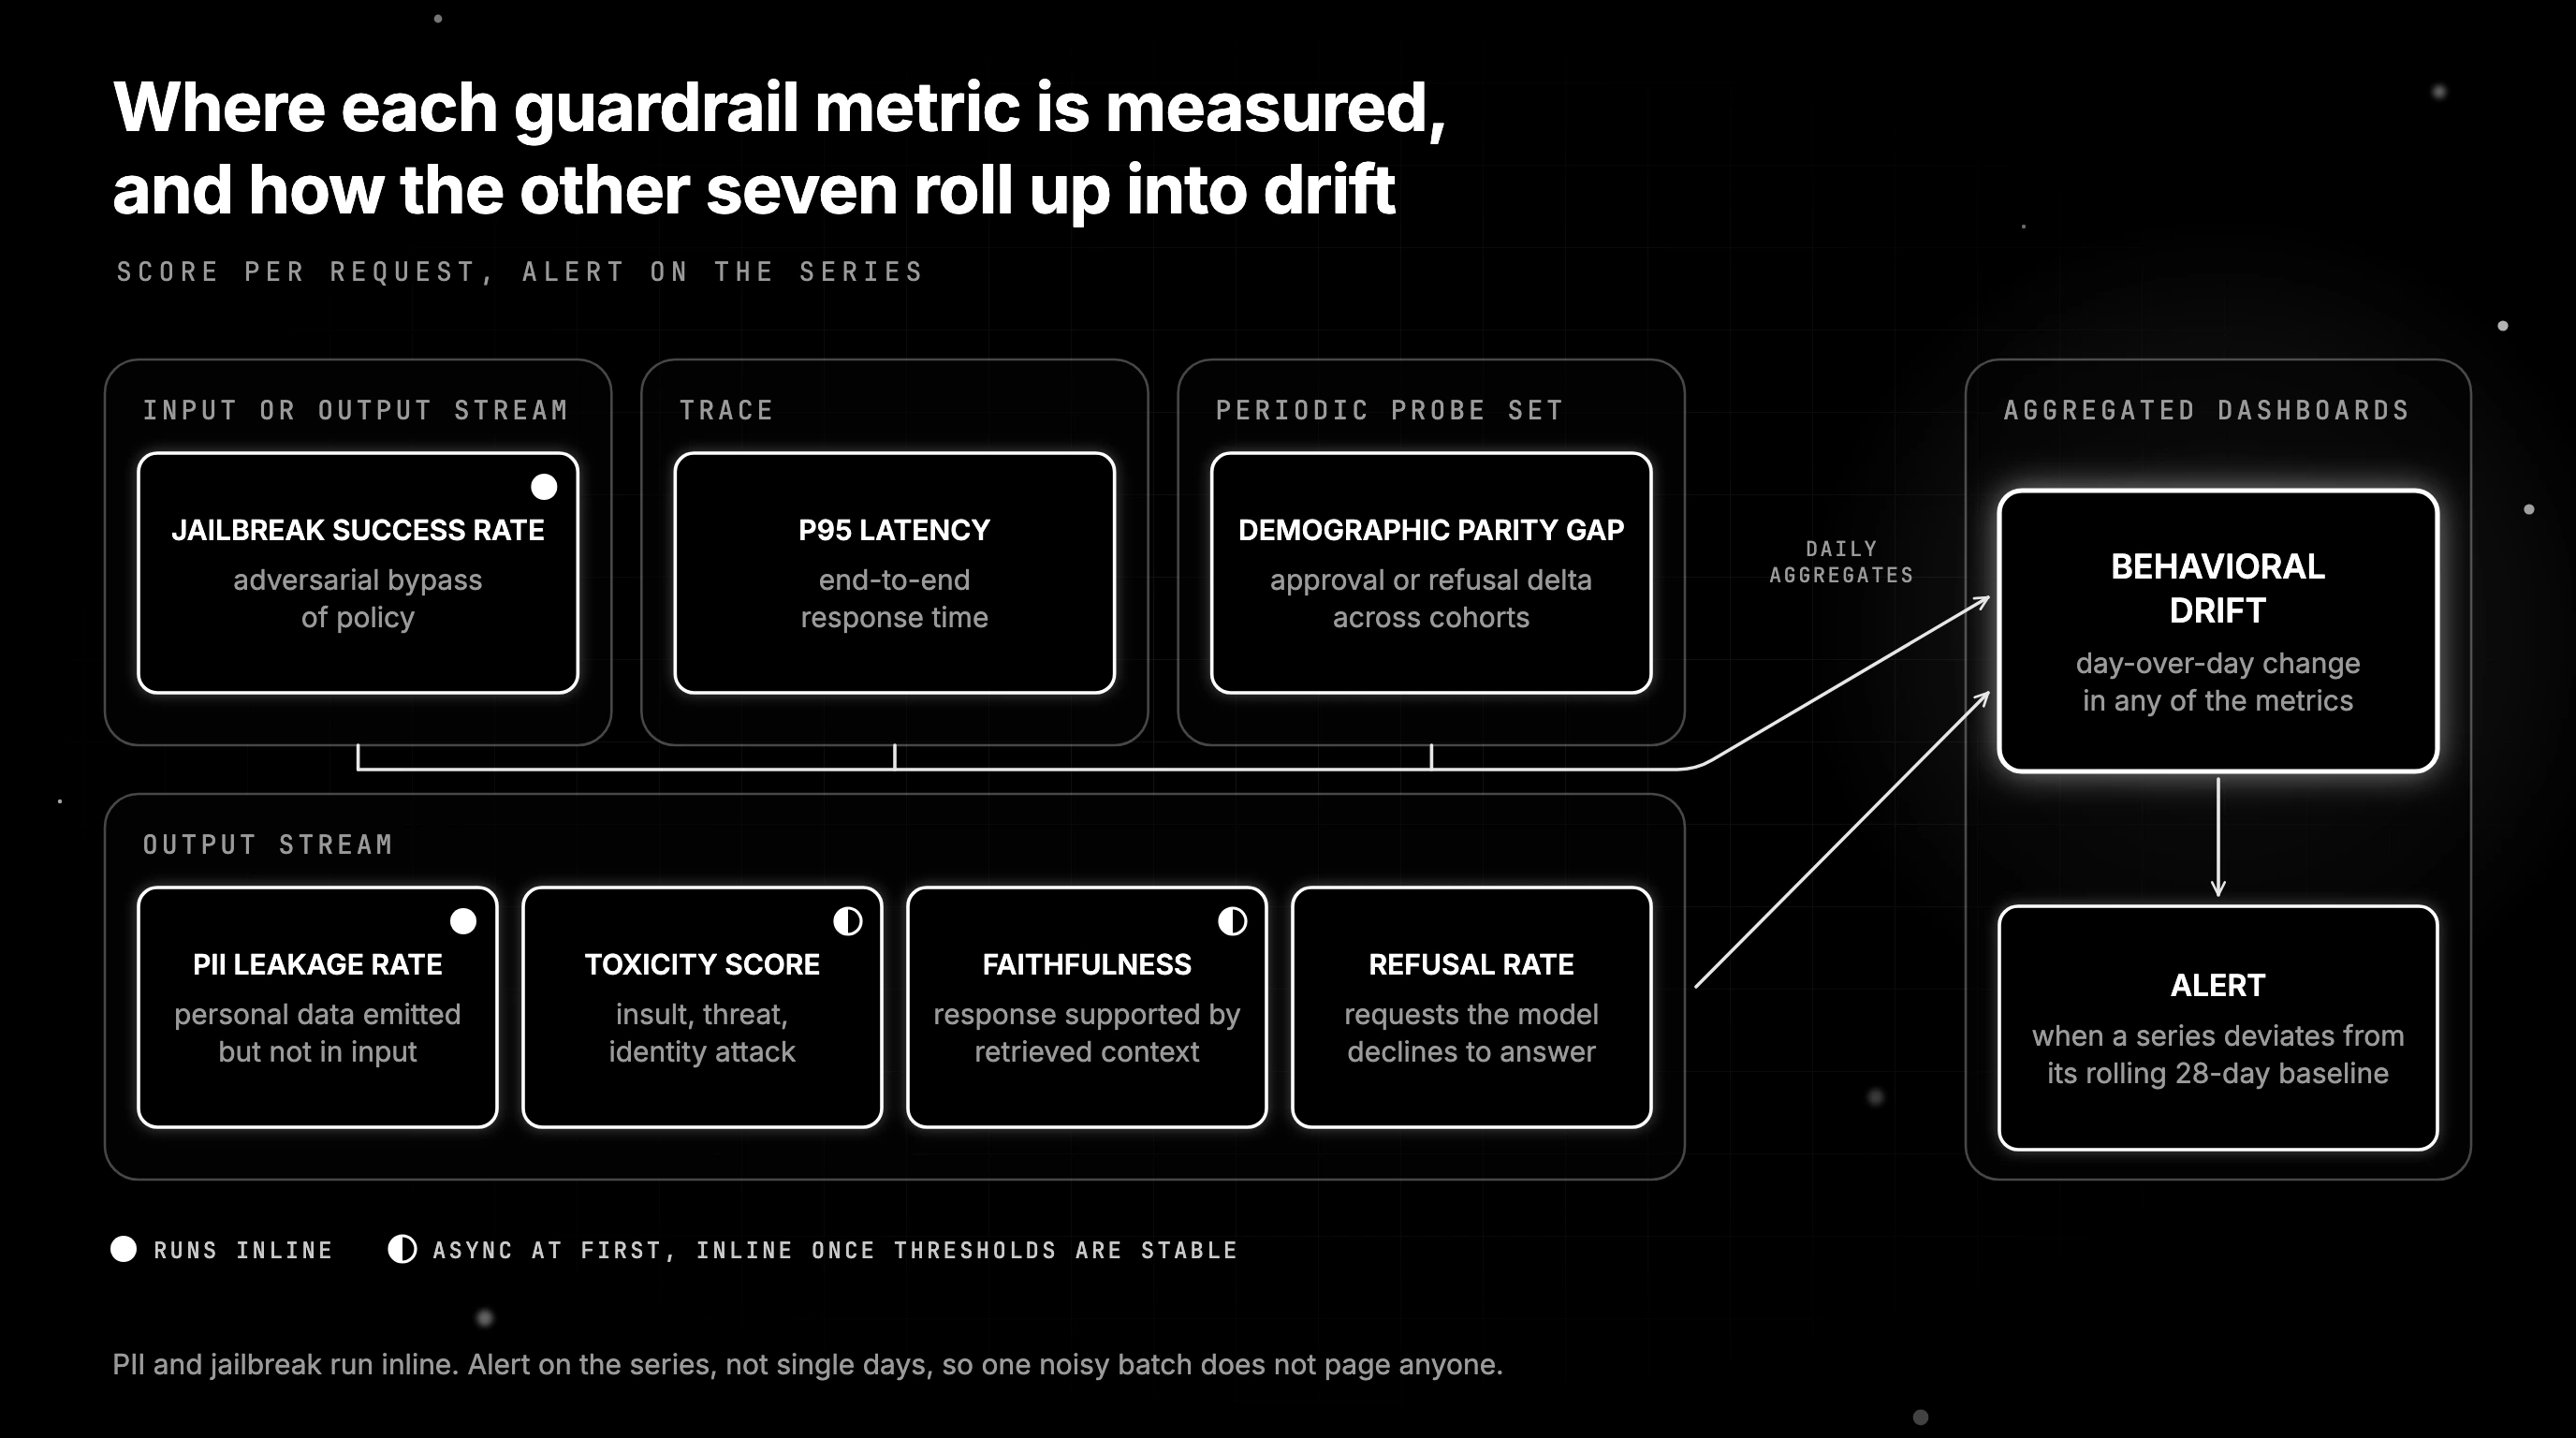
Guardrail metrics are runtime numbers that show how often a production LLM crosses a safety, accuracy, or compliance line. The eight below cover privacy, attack resistance, content safety, fairness, grounding, over-refusal, speed, and change over time, and each one gets a detection method and a starting rule for alerts.
| Metric | What it measures | Where it lives | Typical threshold |
|---|---|---|---|
| PII leakage rate | Personal data emitted but not in input | Output stream | 0 for credit cards, government IDs |
| Jailbreak success rate | Adversarial bypass of policy | Input or output stream | Set from shadow-mode baseline |
| Toxicity | Insult, threat, identity attack | Output stream | Surface-specific (consumer stricter than B2B internal) |
| Demographic parity gap | Approval or refusal delta across cohorts | Periodic probe set | Set from shadow-mode baseline |
| Faithfulness | Response supported by retrieved context | Output + context | Set from shadow-mode baseline |
| Refusal rate | Requests model declines | Output stream | Alert on drift beyond 2 standard deviations |
| p95 latency | End-to-end response time | Trace | Surface-specific (interactive chat tighter than batch) |
| Behavioral drift | Day-over-day change in any of the above | Aggregated dashboards | Alert on moves beyond 2 sigma |
What guardrail metrics actually are
AI guardrails are checks that screen what goes into a model and what comes out, then block, mask, warn on, or log anything that breaks a policy, as covered in our guide to LLM guardrails. A guardrail metric is a number computed on a live request that quantifies how close that request is to violating a safety, accuracy, or compliance boundary. Three properties distinguish guardrail metrics from generic LLM evals.
First, they run on production traffic in one of three execution modes. Inline blocking guardrails run in the request path and can short-circuit a response. Nearline guardrails run on every request but emit telemetry rather than blocking. Async guardrails sample a fraction of traffic and feed dashboards.
A common split: PII and jailbreak run inline, faithfulness and toxicity run async at first and graduate to inline once thresholds are stable. Second, they emit a structured score and a verdict instead of a free-text critique, so a policy engine can act on the value. Third, they are versioned alongside the system prompt, the model name, and the retrieval index, so a regression can be attributed to a specific change.
Offline evaluation answers whether a model is good enough to ship. Guardrail metrics answer whether the current deployment is still inside the policy envelope. The two share evaluators but differ in cadence and in who reads the output. Offline evals serve the model team, while guardrail metrics serve the platform team, the security team, and the auditor.
Guardrail metrics in A/B testing vs LLM guardrails
In product experimentation, guardrail metrics (also called counter metrics) are secondary metrics a team tracks during an A/B test to catch harm that the main goal metric would hide. A simpler signup flow can lift signups while fewer of those users convert to paid, so conversion to paid becomes the guardrail.
Guardrail metrics in A/B testing of LLM releases work the same way. When you compare a new model, prompt version, or retrieval index, task success is the goal metric and the eight metrics below are the counter metrics. If refusal rate, p95 latency, or PII leakage rate moves the wrong way, the variant does not ship.
The 8 guardrail metrics in detail
1. PII leakage rate
PII leakage measures how often a model surfaces personal data that was not in the input. Common categories are names, emails, phone numbers, postal addresses, payment card numbers, government IDs, dates of birth, and health identifiers. Modern detectors combine regex for high-precision categories with named entity recognition for fuzzier categories. A practical pipeline runs Presidio, the open-source PII framework that began at Microsoft, for redaction-quality detection on the output and reports a per-category rate.
The hardest case is indirect leakage through tool calls, where the model passes user identifiers to a downstream API that then echoes them in its response. A complete pipeline scores both the model response and the tool argument trace.
2. Jailbreak success rate
Jailbreak success is the share of adversarial inputs that bypass the policy and produce a response the model was meant to refuse. OWASP splits prompt injection into direct attacks typed by the user and indirect attacks hidden in external content such as websites or files.
Models are trained to rank trusted system and developer instructions above tool output and retrieved text, and an injection succeeds when that learned boundary fails. The harder cases to measure are indirect injection through retrieved content, multi-turn coercion, and payload obfuscation through encoding or translation.
OWASP LLM01 lists prompt injection as the top risk in the 2025 list. In December 2025, OWASP also published the Top 10 for Agentic Applications for 2026, a separate list of risks in autonomous AI agents. Practical measurement combines an attack corpus such as NVIDIA garak with red-team probes informed by published research like the Anthropic agentic misalignment study.
3. Toxicity score
Toxicity is rarely a single number: the useful decomposition is insult, threat, identity attack, and sexually explicit content, scored independently. The thresholds depend on the surface. A children’s tutor needs near-zero tolerance on all four. An internal developer tool can tolerate higher base toxicity because the surface and audience are different.
Modern detectors include Detoxify and the moderation endpoints from frontier labs. The trap is using a single global threshold across surfaces. The better discipline is to set a per-surface threshold and to track the distribution as well as the rate.
4. Demographic parity gap
Demographic parity gap measures whether the model treats cohorts the same on a held-out probe set. The simplest version is the difference in approval rate between two groups holding everything else constant. In a hiring screen, that means the same resume with only name and gender perturbed. In a loan triage, that means the same financial profile with only zip code or surname perturbed.
The EU AI Act lists hiring and creditworthiness systems as high-risk in Annex III, and from 2 December 2027 Article 10 requires their providers to examine datasets for possible biases. The voluntary NIST Generative AI Profile (NIST AI 600-1, July 2024) is more specific: action MS-2.11-002 lists demographic parity among fairness metrics for GAI pipelines with categorical or numeric outcomes. Our AI compliance guardrails guide maps these obligations to controls.
5. Faithfulness or groundedness
Faithfulness scores how well the response is supported by the retrieved context. It applies anywhere the model is supposed to cite or paraphrase external information, such as RAG answers, tool-calling agents, and support bots that read a knowledge base. The score typically comes from an LLM-judge evaluator that takes the response and the context and returns a structured verdict. For detection methods, see detecting hallucinations in generative AI.
In Future AGI’s evaluation SDK, evaluate() scores faithfulness as a local metric, and passing a model with augment=True refines the local score with an LLM judge. Hosted cloud evals run on Turing models: turing_flash for quick checks, turing_small to balance speed and accuracy, and turing_large for complex judgments.
6. Refusal rate
Refusal rate is the share of requests the model declines to answer. A rising refusal rate is often the first signal of trouble after a model swap or a system-prompt change. The fix is to monitor refusal rate per intent class so you can tell whether the model is over-refusing legitimate questions or correctly tightening up on adversarial ones.
7. p95 latency
Latency is a guardrail metric because every evaluator you add to the request path costs time. A practical budget allocates a fraction of the user-facing p95 to evaluators, and you have to pick which evaluators run inline versus async. PII and jailbreak detection usually have to run inline. Faithfulness and toxicity can run async on a sample of traffic, with the dashboard catching aggregate drift.
8. Behavioral drift
Behavioral drift is the day-over-day or week-over-week change in any of the metrics above on a stable input distribution. A frontier model provider can push a routine update that silently lengthens responses or shifts the refusal rate. This kind of LLM drift is the leading indicator for those incidents because it shows up before any of the individual metrics breach their absolute threshold.
To implement it, capture daily aggregates per evaluator, store them, and alert when any series deviates from its rolling baseline by more than a configurable number of standard deviations. Both settings are yours to tune: for example, start with a rolling 28-day baseline and adjust the window to your traffic. Alert on the series, not single days, so one noisy batch does not page anyone.
Where to compute guardrail metrics
There are four practical places to compute these metrics, and each one below comes with code or a product demo. For side-by-side vendor comparisons, see the top AI guardrailing tools and the best AI agent guardrails platforms for tool-call safety.
The first is open-source evaluators run inline. The Future AGI agent-learning-kit (pip install agent-learning-kit, Apache-2.0) ships the fi.evals engine: local metrics such as faithfulness, cloud templates for PII and toxicity, and a Guardrails module for inputs, outputs, and RAG chunks. It scores a fixed dataset offline and screens live traffic at runtime.
from fi.evals import evaluate
from fi.evals.guardrails import Guardrails, GuardrailsConfig, GuardrailModel

# offline: local faithfulness metric
result = evaluate(
    "faithfulness",
    output=model_response,
    context=retrieved_passages,
)

# runtime: screen the response before the user sees it
guardrails = Guardrails(config=GuardrailsConfig(
    models=[GuardrailModel.TURING_FLASH],  # needs FI_API_KEY and FI_SECRET_KEY
))
verdict = guardrails.screen_output(content=model_response, context=user_question)
if not verdict.passed:
    serve_fallback()
The second is OpenTelemetry-grade instrumentation. The Future AGI traceAI repository is Apache-2.0 and supplies framework-specific instrumentors such as traceai-langchain exposing a LangChainInstrumentor, plus traceai-openai-agents, traceai-llamaindex, and traceai-mcp. Pass semantic_convention=SemanticConvention.OTEL_GENAI to register() to emit spans in the OpenTelemetry GenAI semantic conventions. Future AGI Observe can then run evals on traced spans.
from fi_instrumentation import register, FITracer
from traceai_langchain import LangChainInstrumentor

tracer_provider = register(project_name="prod-chat-app")
LangChainInstrumentor().instrument(tracer_provider=tracer_provider)

tracer = FITracer(tracer_provider.get_tracer(__name__))

@tracer.chain
def answer(question, context):
    return llm.invoke({"question": question, "context": context})
The third is a gateway that applies the policy inline. The Future AGI Agent Command Center is an OpenAI-compatible gateway that routes traffic with your own provider keys (BYOK by default) and runs guardrails before the model call and after the response. Each guardrail returns a score from 0.0 to 1.0 against your threshold and runs in Enforce, Monitor, or Log mode.
The fourth is custom LLM-judge evaluators. The library exposes fi.evals.metrics.CustomLLMJudge and fi.evals.llm.LiteLLMProvider so a team can define a policy-specific evaluator without leaving the same SDK. The judge returns a score and a reason, so a written policy becomes a metric you can trend.
from fi.evals.metrics import CustomLLMJudge
from fi.evals.llm import LiteLLMProvider

policy_judge = CustomLLMJudge(
    provider=LiteLLMProvider(),
    config={
        "name": "trading_advice_policy",
        "model": "gpt-6.1-sol",
        "grading_criteria": """
        Score 0 if the response gives directional buy or sell advice
        on a named security. Score 1 if the response stays educational
        and points to a licensed advisor for actionable guidance.
        """,
    },
)
Cloud-backed flows, including Turing evaluators and the Turing guard model, need two environment variables: FI_API_KEY and FI_SECRET_KEY. Create both under Settings > API Keys in the Future AGI dashboard, as the API keys docs explain; the secret key is shown only once.
How to set thresholds without overfitting
Threshold setting fails when teams pick numbers based on intuition. The discipline that scales is to measure first, then threshold. Start by running the evaluators in shadow mode for a fixed period, for example two to four weeks. Log every score, do not block on anything except a small allowlist of hard-zero categories such as credit card disclosure.
After the shadow period, look at the per-cohort distributions and pick thresholds that catch the extreme tail, for example the top one or two percent, then tune from there. For metrics with a clear policy answer such as PII categories regulated by GDPR or HIPAA, set hard blocks at zero. For metrics with a softer policy answer such as toxicity, set alerts and let the on-call rotation decide whether to escalate.
Re-baseline every quarter. The model providers ship updates frequently, retrieval corpora drift, and user behavior changes. A guardrail metric is only useful if its threshold reflects current reality, so re-run the shadow comparison after every model or prompt change as well.
How to test AI guardrails before they block traffic
Testing an AI guardrail means measuring the check itself. Run a labeled mix of attack prompts and benign prompts through each check and count two failure types: missed attacks (false negatives) and blocked legitimate requests (false positives). An attack corpus from a scanner such as NVIDIA garak covers the first set, and a sample of real user traffic covers the second.
Then watch each check on live traffic. In Future AGI Agent Command Center, the Guardrails Analytics tab reports Trigger Rate, Blocked and Warned counts, and Avg Latency, the average time the checks add. Reviewers label fired checks as Correct, False Positive, False Negative, or Unsure, and the Feedback tab rolls those labels into accuracy per check (guardrail activity docs). Check both false alarms and missed attacks, including a labeled sample of unflagged requests, before moving from Monitor to Enforce.
Bedrock guardrail metrics live in Amazon CloudWatch under the AWS/Bedrock/Guardrails namespace, including InvocationsIntervened (requests where the guardrail intervened) and InvocationLatency. Agent Command Center also lists AWS Bedrock Guardrails among its external guardrail integrations, so both can sit behind one gateway.
Sector-specific extensions
Healthcare adds clinical-relevance scoring, citation-to-source verification against curated medical knowledge, and an extra cohort axis for protected health conditions. The MedHELM benchmark, published in 2025, maps medical work into 121 clinician-validated tasks and scores LLMs on 35 benchmarks. Finance adds a directional-advice detector, a sanctioned-entity detector, and tighter PII categories aligned with PCI DSS. Public sector and education add an age-appropriate-content detector and a stricter toxicity threshold for under-18 audiences.
Across sectors, extend the base eight with a small number of sector evaluators rather than rebuilding the framework. A custom LLM judge like the trading-advice policy above covers a sector check, such as directional investment advice, without forking the evaluator library.
Ship the eight metrics in shadow mode first
The eight metrics in this guide are the operational floor for a production LLM and the first evidence an auditor will ask for. Future AGI gives you each layer: agent-learning-kit (Apache-2.0) scores responses, traceAI (Apache-2.0) traces each LLM call, and Agent Command Center runs PII, prompt injection, content moderation, and hallucination checks as gateway guardrails.
Start with pip install agent-learning-kit, wire the four most regulated metrics for your sector (PII, jailbreak, toxicity, faithfulness) in shadow mode, and let a few weeks of shadow scores set the thresholds instead of guesses. Then move stable checks from Monitor to Enforce.
Start free on Future AGI and turn on your first guardrail in Monitor mode.
References
- Regulation (EU) 2026/1744 (Digital Omnibus on AI), setting 2 December 2027 as the application date of Article 10 and the other Chapter III, Sections 1 to 3 rules for Annex III high-risk systems
- IH-Challenge: training instruction hierarchy on frontier LLMs (arXiv 2603.10521)
- MedHELM paper, 121 clinician-validated tasks and 35 benchmarks (arXiv 2505.23802)
- PostHog: what are guardrail metrics in A/B testing
- OpenAI models list, including GPT-6.1 Sol
Frequently Asked Questions
What are guardrail metrics?
Can you provide some examples of guardrail metrics?
What are guardrail metrics in A/B testing?
What are guardrails in AI?
How do you test AI guardrails?
Compare top AI guardrail tools in 2026: Future AGI, NeMo Guardrails, GuardrailsAI, Lakera Guard, Protect AI, Presidio. Coverage, latency, how to choose.

Compare 6 AI guardrails tools for agents in 2026, from Future AGI and Lakera to NeMo, Guardrails AI, Bedrock and OpenAI Moderation, on rails, latency and cost.

Implement LLM guardrails with Future AGI Protect in 2026. Toxicity, bias, prompt injection, data privacy. Low latency inline blocking with code samples.
