Llama 4 vs Traditional AI Models in 2026: What Changed and Why It Matters
Llama 4 Scout and Maverick are still Meta's newest general Llama models. Compare Llama vs traditional AI models like GPT, Claude and BERT on license and cost.
Table of Contents
Llama 4 vs Traditional AI Models in 2026: Why the Comparison Matters Now
Meta’s Llama 4 family ships natively multimodal mixture-of-experts models with open weights. On the closed side, OpenAI points developers to GPT-6 Astra as its flagship, Anthropic lists Claude Fable 5.1 and Claude Opus 5.5, and Google lists Gemini 4 Argon as its flagship reasoning model. For an engineering team, the practical question is which model class fits which workload, at what cost, and under which licensing constraints.
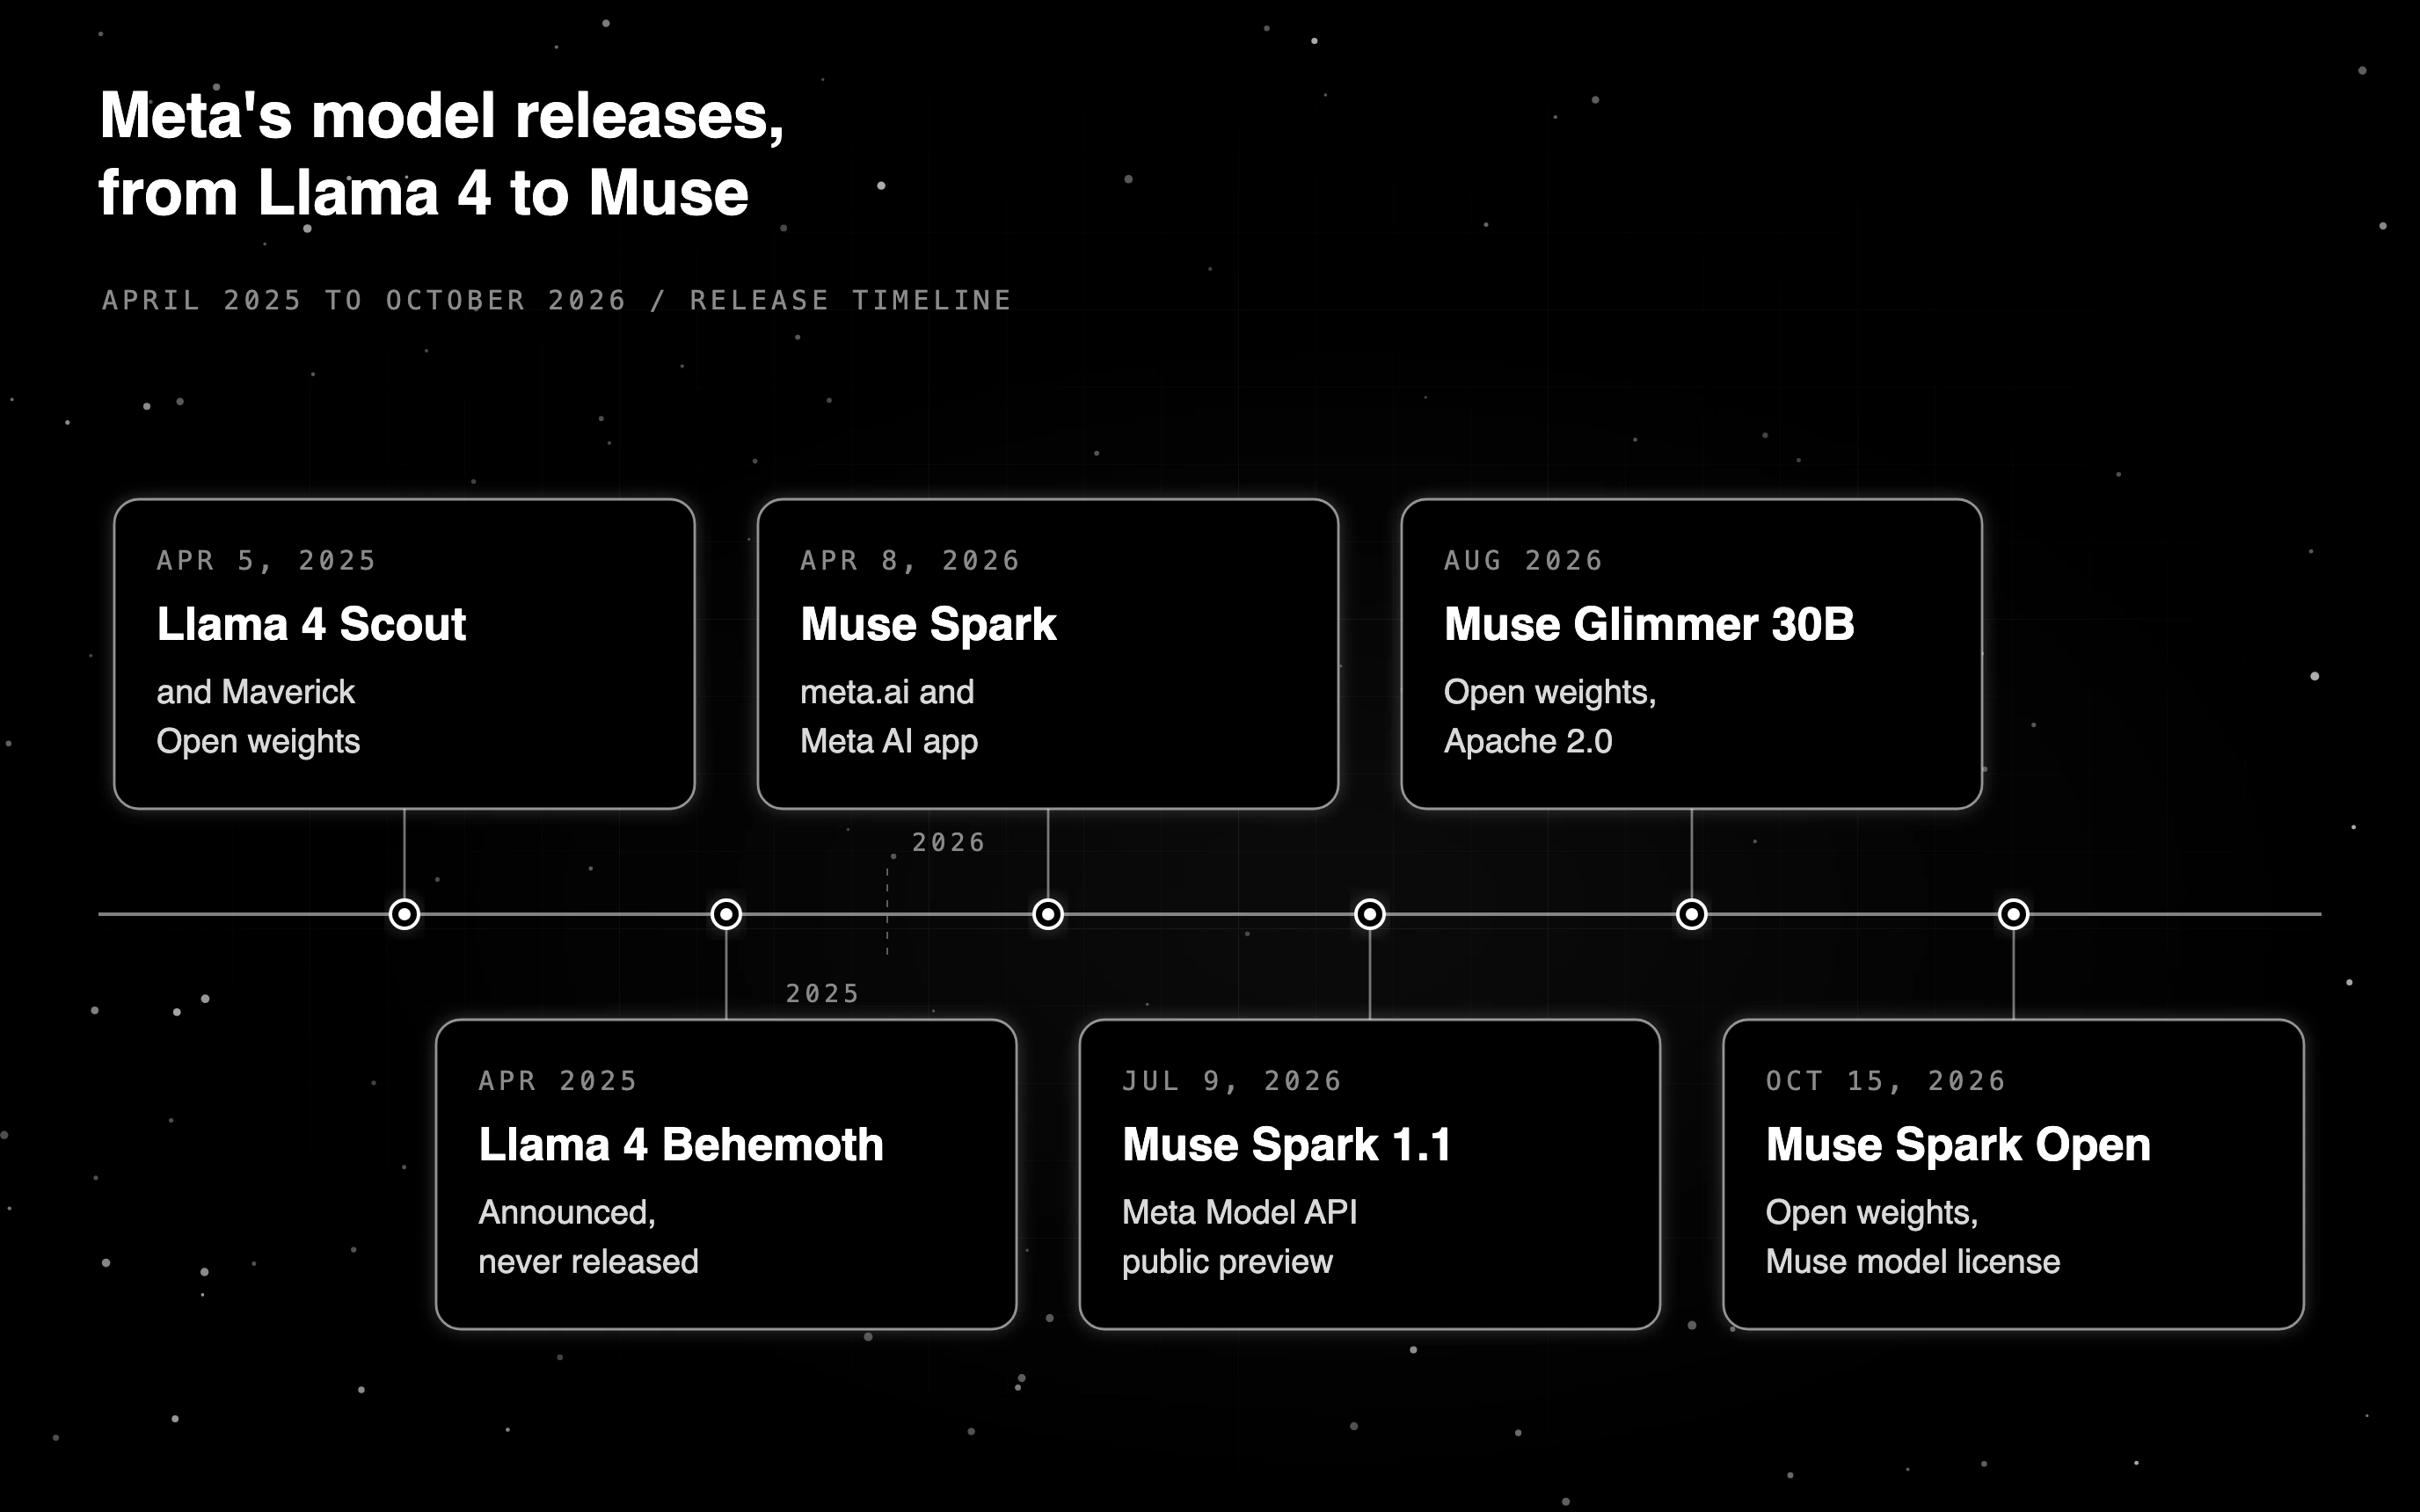
As of October 2026, Llama 4 Scout and Maverick (April 2025) are still the newest general-purpose Llama models Meta has released, and Behemoth was never released. Meta’s newer work ships under the Muse name: Muse Spark launched in April 2026 on meta.ai with a private API preview, Muse Glimmer (August 2026) is a 30B open-weight model under Apache 2.0, and Muse Spark Open weights reached Hugging Face on October 15, 2026.
TL;DR: Llama 4 vs Traditional AI Models in 2026
| Dimension | Llama 4 (Scout / Maverick) | GPT-6 Astra and other closed frontier APIs | BERT / encoder family |
|---|---|---|---|
| Type | Decoder LLM, mixture-of-experts, multimodal | Decoder LLM, proprietary | Encoder, classification / ranking |
| Access | Open weights (Llama 4 Community License) | API-only via the vendor | Open weights (Apache 2.0 typical) |
| Active parameters | 17B (Scout and Maverick); Behemoth (288B active) announced but never released | Undisclosed | 110M to 340M (typical) |
| Cost per 1M tokens | Workload-dependent self-hosted | Vendor API pricing | Self-hosted, runs on CPU or a small GPU |
| Best for | Open generative + agentic work, custom fine-tunes | Frontier reasoning, plug-and-play API | Classification, semantic search, NER |
| License limit | 700M MAU threshold, measured at the Llama 4 release date | Vendor terms | Permissive |
| Latest Meta open-weight releases | Muse Spark Open, open weights, Muse model license (Oct 2026); Muse Glimmer 30B, open weights, Apache 2.0 (Aug 2026) | n/a | n/a |
What Are Llama Models in 2026 and Which Variants Should You Care About
Llama is Meta’s family of open-weights large language models. The Llama 4 family, announced by Meta in April 2025, includes three named variants. Scout and Maverick are the two released variants. Behemoth was announced while still in training and was never released:
- Llama 4 Scout. Roughly 17 billion active parameters out of a 109 billion total mixture-of-experts pool. Native multimodal. Optimized for single-GPU inference (a single H100 in 4-bit quantization per Meta’s announcement).
- Llama 4 Maverick. Roughly 17 billion active out of 400 billion total, across 128 experts. The larger of the two released models; Meta says it runs on a single NVIDIA H100 DGX host.
- Llama 4 Behemoth. Meta announced it in April 2025 (288B active, nearly 2T total, 16 experts) as still in training. It has never been released, and no Behemoth weights exist on Meta’s Hugging Face organization as of October 2026.
The MoE architecture matters because it lets the model behave like a smaller model at inference time. Only a slice of the parameters activate per token, so active compute is closer to a 17 billion parameter dense model rather than the full 400 billion.
Open Weights and Why That Matters in 2026
Open weights (note: “open weights” rather than full open source) means you can download the parameters, fine-tune them on your data, and run inference on your own infrastructure. The Llama 4 Community License that covers those weights is not OSI-approved.
The license allows commercial use. If your products had more than 700 million monthly active users in the calendar month before the Llama 4 release date (April 5, 2025), you must request a license from Meta, and individuals and companies based in the EU get no rights to the multimodal models.
Optimized for Efficiency Through MoE and Quantization
In 2026, the practical efficiency story for Llama is two-fold:
- MoE routing keeps active parameters small even when the total model is large.
- 4-bit quantization (GPTQ, AWQ, FP4) stores weights in 4 bits instead of 16, roughly a quarter of the memory, with some quality loss that varies by model and method.
For startups, that means Llama 4 Scout on a single rented H100 is realistic. For larger workloads, Meta says Llama 4 Maverick can run on a single NVIDIA H100 DGX host.
Customization: Fine-Tuning, LoRA, and Domain Adaptation
Llama models are designed for adaptation. The 2026 fine-tuning toolkit is mature:
- LoRA and QLoRA for parameter-efficient fine-tunes on a single GPU
- Full-rank fine-tunes for high-volume domain adaptation
- DPO and KTO for preference alignment without RLHF infrastructure
- Constitutional fine-tuning for safety-driven behavior shaping
Industries like healthcare, finance, and legal use fine-tuned Llama variants for tasks where data residency, customization, or licensing economics rule out closed APIs. Because you hold the weights, the fine-tuned checkpoint stays on your own infrastructure, next to the data it learned from.
What Is Meta’s Latest Llama Model in 2026?
Meta’s newest general-purpose Llama models are still Llama 4 Scout and Llama 4 Maverick, released on April 5, 2025. The only meta-llama repositories created after them on Hugging Face are safety models, Llama Guard 4 and Llama Prompt Guard 2, from April 2025. Llama 4 Behemoth (288B active, nearly 2T total parameters) was announced the same day as still in training and has never been released.
Meta’s newer models carry a different name. On April 8, 2026, Meta Superintelligence Labs launched Muse Spark on meta.ai and the Meta AI app, with a private API preview for select users. Meta says Muse Spark reaches the capabilities of Llama 4 Maverick with over an order of magnitude less training compute. On July 9, 2026, Muse Spark 1.1 arrived through a public preview of the Meta Model API, with up to a million tokens of context.
The first open-weight follow-up was Muse Glimmer, published on Hugging Face in August 2026. It is a 30B (about 29.6B) dense model with a perception encoder, distilled from Muse Spark and released under Apache 2.0. It takes text and image input, supports a 131K+ token context, has a January 4, 2026 knowledge cutoff, and is built to run locally in a 24 to 32 GB envelope at about 4-bit.
On October 15, 2026, Meta also published the weights of Muse Spark Open on its meta-models Hugging Face organization, with gated access under its own Muse model license rather than Apache 2.0. That license asks you to display “Built with Muse Spark Open”, and a company selling model access as a service with more than $20 million in gross revenue over any 12 months must sign a separate agreement with Meta.
Is Llama 5 Coming?
Meta has not released a Llama 5, and its official blog and Hugging Face organizations show no Llama 5 model as of October 2026. Reports of a Llama 5 or a Llama 4.1 come from third parties, not Meta, so treat any release date or spec as unconfirmed. For planning, treat Llama 4 Scout and Maverick as the current Llama weights and watch Meta’s AI blog and the meta-llama and meta-models organizations on Hugging Face for the next release.
What Are Traditional AI Models in 2026 and Why They Still Matter
“Traditional” here means the model classes that predate or sit alongside the generative LLM wave: encoder transformers (BERT, RoBERTa, DeBERTa), retrieval models, classical ML (gradient boosting, XGBoost), and the proprietary decoder LLMs from before the open-weights wave. They still matter because a production AI system is often a pipeline of many models, each picked for its workload profile.
GPT-6, Claude and Gemini at the Proprietary Frontier
GPT-6 Astra and peer proprietary frontier models from Anthropic (Claude Opus 5.5, Claude Fable 5.1) and Google DeepMind (Gemini 4 Argon) ship only through APIs. You do not see the weights, you do not fine-tune them yourself (any managed fine-tuning depends on the vendor and model), and you cannot run them on-prem. The trade-off is that they require no inference infrastructure on your side.
BERT and the Encoder Family
BERT (arXiv 1810.04805) and its modern successors (DeBERTa-v3, ModernBERT, all-mpnet for semantic search) are encoder transformers. They produce dense vector representations of text and excel at classification, ranking, named-entity recognition, and similarity search. They are typically much faster and cheaper per query than running a generative LLM as a classifier. A practical split pairs an encoder model on the cold path (retrieval, routing, filtering) with a generative LLM on the hot path (reasoning, generation).
T5 and Unified Text-to-Text Models
T5 (arXiv 1910.10683) frames every NLP task as text-to-text. It remains popular for fine-tuned summarization and translation in environments that want a smaller, dedicated model rather than calling a frontier LLM. FLAN-T5 and Flan-UL2 extend the recipe with instruction tuning and stronger zero-shot performance.
How Does Llama Compare to Proprietary Frontier Models?
The trade is control against convenience. With Llama 4 you get the weights: you can run Scout or Maverick on your own hardware, keep data on-prem and fine-tune the full model. With a closed frontier API such as OpenAI’s GPT-6 Astra, Anthropic’s Claude Opus 5.5 and Claude Fable 5.1, or Google’s Gemini 4 Argon, you get managed hosting and no inference infrastructure, but you never see the weights and your prompts go to the vendor.
Any quality gap between Llama and a closed model has to be measured on your own eval set, with your own rubric, before it decides anything. A public leaderboard tests someone else’s prompts. A Llama model that clears your threshold on your task is the right pick even if a closed model ranks higher elsewhere, and the reverse holds too.
Cost follows the same logic. Self-hosting turns per-token pricing into GPU hours, which favors steady, high volume, while a closed API bills only for the tokens you send. For the current ranking of closed and open models, see our September 2026 model rankings.
How Llama 4 Differs From Traditional AI Models: Architecture, Efficiency, Customization
How Does Llama’s Architecture Compare to Earlier Open Models?
Llama 4 uses a mixture-of-experts design, and Meta calls Scout and Maverick its first Llama models built that way. Each token routes through a small subset of expert sub-networks rather than the full parameter set. This is the same architectural family as Mixtral, DeepSeek-V3, and Qwen3-MoE.
It contrasts with classical dense models like GPT-3 or BERT, where every parameter activates for every token. MoE is a major architectural shift in recent open-weight releases, though not a universal one: Meta’s own Muse Glimmer 30B is a dense model.
Encoder models like BERT are bidirectional and trained to predict masked tokens. They produce embeddings rather than generated text. They have stayed small because the training goal differs: an encoder learns representations of text instead of generating it, and ModernBERT-base still has about 149M parameters.
Efficiency: How Llama 4 Runs on Limited Hardware
- Llama 4 Scout: single H100 in 4-bit quantization
- Llama 4 Maverick: a single NVIDIA H100 DGX host, per Meta
- GPT-6 Astra and other closed frontier APIs: not applicable, API-only
- BERT-base: laptop CPU or single consumer GPU
A startup running a chatbot can self-host Llama 4 Scout on a single rented H100, since Meta says Scout fits on one H100 with Int4 quantization. The cost comparison versus a frontier API depends on token volume and prompt mix; sketch a per-workload cost model rather than relying on a single multiplier.
Open Weights vs Proprietary: License Differences
Llama 4 ships under the Llama 4 Community License, and Meta publishes the full text under that name. If your products had more than 700 million monthly active users in the calendar month before the Llama 4 release date (April 5, 2025), you must request a license from Meta. Distributors must also display “Built with Llama” and keep the license notice.
GPT-6 Astra is governed by OpenAI’s terms; you do not get the weights. BERT and its successors are typically released under permissive licenses (Apache 2.0 for ModernBERT).
The practical implication: Llama is a fit when you need data residency, custom fine-tuning, or want to optimize cost-per-token. A closed frontier API such as GPT-6 Astra is a fit when you need the lowest-effort path to high-quality general intelligence and your data policies allow third-party APIs.
Open weights are not the same as open source. Llama 4 ships its weights under Meta’s own Community License, with a 700M MAU threshold, Built with Llama attribution and no multimodal rights for EU-based individuals and companies, while Muse Glimmer 30B ships under Apache 2.0, an OSI-approved license with no user threshold.
Training Data and Customization
Llama models can be fully fine-tuned, LoRA-tuned, or DPO-tuned on custom data. Closed frontier APIs never hand you the base weights; any managed fine-tuning depends on the vendor and model. BERT and friends are trivially fine-tunable for classification heads. For specialized domains like clinical NER or legal classification, BERT fine-tunes remain hard to beat on cost-per-prediction.
How to Evaluate Llama vs GPT vs BERT for Your Workload
The model choice is downstream of two questions: what task profile, and what cost-per-call constraint? The table gives a starting pick for common tasks, and your own eval set makes the final call.
| Task | First pick | Second pick | Why |
|---|---|---|---|
| Free-form chat or agentic reasoning | GPT-6 Astra | Llama 4 Maverick | Frontier reasoning + tool use |
| High-volume customer support routing | Llama 4 Scout (fine-tuned) | GPT-6 Luna (cost tier) | Cost per call dominates |
| Sentiment / topic classification | DeBERTa-v3 / ModernBERT | Llama 4 Scout | Small encoder, cheap per call |
| Semantic search and retrieval | Sentence-Transformer / GTE | n/a | Dedicated embedding model |
| Code completion in IDE | GPT-6 Astra or Claude Opus 5.5 | Llama 4 Maverick | Frontier code quality |
| On-device or privacy-sensitive | Llama 4 Scout (quantized) | Muse Glimmer 30B (Apache 2.0, about 4-bit in a 24 to 32 GB envelope) | Open weights, runs locally |
Build a labeled or synthetic evaluation set of 100 to 500 examples that match your task. Run candidate models against the same rubric: task success, factuality, instruction-following, latency, and cost-per-call. The LLM evaluation guide walks through metrics and pipelines for this comparison.
Future AGI has custom evals: write your own grading rule, pick an LLM judge or a deterministic check, set a pass/fail threshold and run it as a CI gate, alongside built-in evaluators such as Task Completion, Instruction Adherence and Groundedness (evaluation docs). traceAI (Apache 2.0, built on OpenTelemetry) traces every model call so you can compare models span by span.
Point your OpenAI SDK at the Agent Command Center gateway (change the base_url, swap the key) to route across 100+ providers, including self-hosted vLLM or Ollama for Llama. Its shadow experiments mirror live traffic to a candidate model without affecting users, so you see a challenger’s cost, latency and quality before you switch.
Pick the Right Model for Each Step, Then Prove It on Your Data
Llama 4 is an open-weight option with a 10M-token context on Scout, MoE-driven efficiency and full fine-tuning control. For startups, regulated industries, and any team that needs control over the model behavior or the inference economics, Llama 4 is the natural starting point. For teams that need managed API access to frontier models and do not want to operate infrastructure, the closed APIs remain the right tools.
In practice the right answer is a pipeline: encoder models on the cold path, fine-tuned Llama on high-volume hot paths, and a frontier API for the highest-value queries. Run the same eval set across every model in that pipeline and let the scores decide which class handles each workload.
Future AGI gives you that layer: custom evals to score Llama, a closed API and an encoder on one rubric, and Observe to trace every call back to the model that made it. The Future AGI platform has an Apache-2.0 core you can self-host next to your Llama deployment, so prompts and traces stay inside your network.
Start a free workspace at app.futureagi.com and run your first Llama vs closed-model comparison on your own prompts.
Frequently Asked Questions
What is Meta Llama 4?
Is Llama better than ChatGPT?
Is Llama 4 free?
Is Meta Llama 4 open source?
Can I use Llama like ChatGPT?
Is Meta AI the same as Llama?
Is Meta abandoning Llama?
Compare the top open-weight LLMs in 2026: Llama 4.x, DeepSeek R2, Qwen 3, Mistral, Phi family. Benchmarks, licensing, hardware, and how to evaluate yours.
Best LLMs May 2026: compare GPT-5.5, Claude Opus 4.7, Gemini 3.1 Pro, and DeepSeek V4 across coding, agents, multimodal, cost, and open weights.
Compare GPT-5, Claude Opus 4.7, Gemini 2.5 Pro, and Grok 4 on GPQA, SWE-bench, AIME, context, $/1M tokens, and latency. May 2026 leaderboard scores.