Small Language Models for Agentic AI in 2026: The Lineup, Trade-offs, and How to Build Multi-Agent Workflows
Small language models for agentic AI, compared: Gemma 4, Qwen3.5, Ministral 3 and Phi-4-mini, plus NVIDIA's SLM-first case and a step-by-step build guide.
Table of Contents
Small Language Models for Agentic AI in 2026, the Short Version
An agent that sends every step to a frontier model pays frontier prices and latency to classify a ticket, pull an order ID and pick a tool. Those calls are narrow and repetitive, and small language models (SLMs), each fine-tuned for one kind of call, can handle many of them.
NVIDIA Research made the argument formally in its 2025 position paper Small Language Models are the Future of Agentic AI (arXiv 2506.02153): many agent calls are narrow, repetitive tasks, and small language models (the paper counts most models under about 10B parameters as SLMs) are sufficient, better suited and more economical for them. The case for SLMs over frontier LLMs in agentic workflows is cost, latency, and modularity.
The current small models to test for agent work are Microsoft Phi-4-mini and Phi-4, Google Gemma 4 E2B and E4B, Alibaba Qwen3.5 (0.8B to 9B), Mistral Ministral 3, Meta Llama 3.2 1B and 3B, and Hugging Face SmolLM3-3B. The remaining engineering work is fine-tuning per agent, building per-agent eval suites, and instrumenting the full workflow.
SLM Lineup for Agentic AI at a Glance
| Model | Params | Best For | License |
|---|---|---|---|
| Microsoft Phi-4-mini-instruct | 3.8B | Function calling, extraction | MIT |
| Microsoft Phi-4 and Phi-4-reasoning | 14B | Reasoning-heavy steps | MIT |
| Google Gemma 4 E2B and E4B | E2B, E4B | On-device agents, audio input | Apache-2.0 |
| Alibaba Qwen3.5 | 0.8B, 2B, 4B, 9B | Routing, tool calling, long context | Apache-2.0 |
| Mistral Ministral 3 | 3B, 8B, 14B | Function calling, JSON output | Apache-2.0 |
| Meta Llama 3.2 | 1B, 3B | Edge and mobile, routing | Llama 3.2 Community License |
| Hugging Face SmolLM3 | 3B | Tool calling, fully open model | Apache-2.0 |
Why NVIDIA Says Small Language Models Are the Future of Agentic AI
“Small Language Models are the Future of Agentic AI” is a position paper from NVIDIA Research and Georgia Tech, written by Peter Belcak, Greg Heinrich, Shizhe Diao, Yonggan Fu, Xin Dong, Saurav Muralidharan, Yingyan Celine Lin and Pavlo Molchanov. Version 1 went up on arXiv as 2506.02153 on June 2, 2025, version 2 followed on September 15, 2025, and version 3 on September 22, 2026.
The position is that SLMs are sufficiently powerful, inherently more suitable and necessarily more economical for many of the calls an agent makes, because many agentic applications have a language model perform a small number of specialized tasks over and over with little variation. Large models keep a role: where general reasoning or open-domain dialogue matters, the authors advocate heterogeneous agents that use SLMs by default and call an LLM selectively.
The paper names three barriers to adoption: large upfront investment in centralized LLM inference infrastructure, SLMs being designed and judged on generalist benchmarks, and low popular awareness of what SLMs can do. The authors describe all three as practical hurdles, far from fundamental flaws in the SLM approach.
To ground the argument, the authors studied three open-source agents. They estimate that about 60% of MetaGPT’s LLM queries, about 40% of Open Operator’s and about 70% of Cradle’s could move to specialized SLMs.
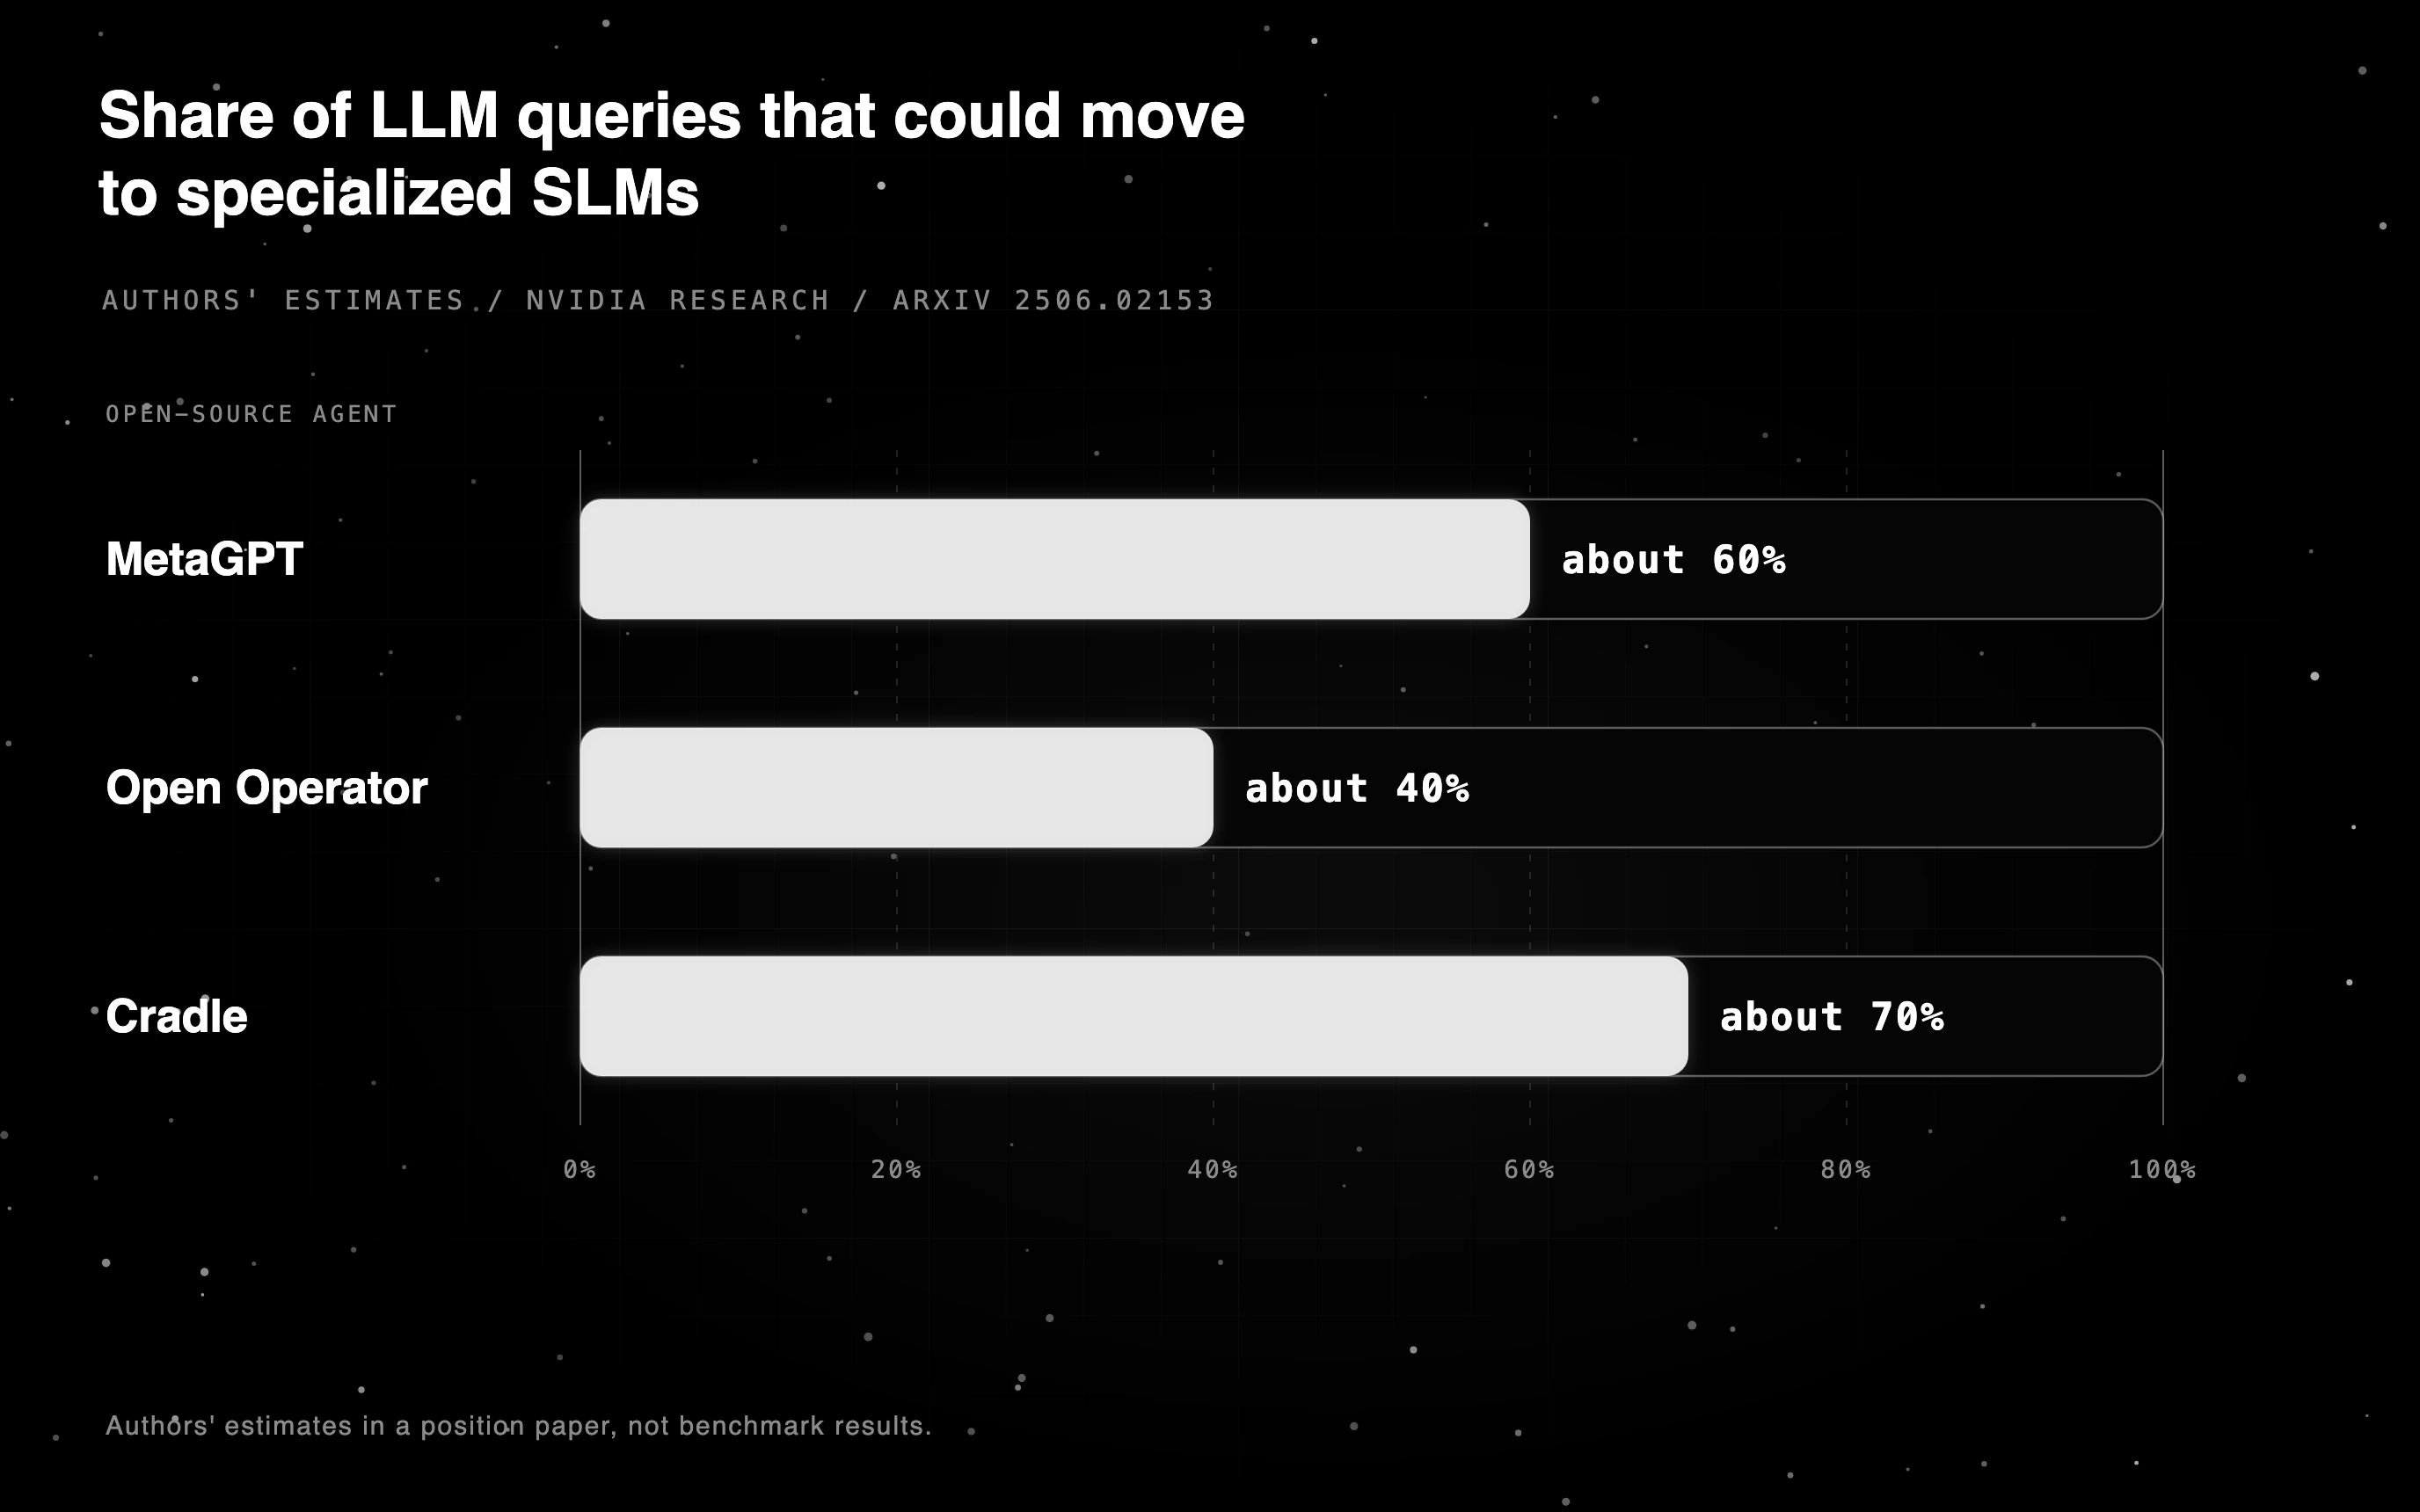
These are the authors’ estimates in a position paper, not benchmark results. Use them as a reason to measure your own agent’s call mix: log a week of calls and count how many are narrow tasks that repeat with little variation.
How to Convert an LLM Agent to SLMs
The paper lays out a six-step recipe for moving an existing LLM agent onto SLMs. Here it is in plain terms, with where Future AGI fits in each step.
- Log every agent call. Capture the prompts, outputs, tool-call contents and latency of every call that is not a direct exchange with a person. traceAI records these as OpenTelemetry spans.
- Curate the data. Once you have roughly 10K to 100K examples (the paper’s rule of thumb), strip PII, PHI and other sensitive data. Future AGI builds a dataset straight from Observe traces, and Protect can mask PII (it returns block, warn, mask or log, and runs on Future AGI Cloud and Enterprise).
- Cluster the calls. Group them into recurring tasks such as intent recognition, data extraction or document summarization.
- Pick candidate SLMs per task. Weigh capability, benchmark results, license and deployment footprint; the lineup below is a starting set.
- Fine-tune or distill. Use LoRA, QLoRA or full fine-tuning, or knowledge distillation from the LLM. Score each candidate against the LLM it replaces with the same evals before you move traffic.
- Keep iterating. Retrain on fresh data as usage shifts, replay scenarios in Simulation before each release, and route the easy calls to the self-hosted SLM through Agent Command Center, with a frontier model as fallback behind the same endpoint.
Why SLMs Are Taking Center Stage in Agentic AI Workflows
The case for SLMs in agentic systems comes down to arithmetic. NVIDIA’s paper states that serving a 7B SLM is 10 to 30 times cheaper in latency, energy and FLOPs than a 70B to 175B LLM. The full SLM vs LLM cost, latency, and quality comparison breaks the tradeoffs down model by model. In a multi-step chain, that per-call saving applies at every step.
The second reason is modularity. A frontier LLM running a single mega-prompt is a black box that fails opaquely when one of its many implicit subtasks regresses. An agentic system with five SLM-powered agents is five small components, each with its own eval suite and its own well-understood failure mode. When something breaks, you know which agent regressed and you retrain or revert that one component without touching the others.
The third reason is specialization. A 3B parameter SLM fine-tuned on a task-specific dataset (NVIDIA’s paper treats 10K to 100K examples as a rule of thumb) can be sufficient for that narrow task, which is the core of the paper’s argument. The frontier model has more world knowledge, but a narrow agent step does not need all of it.
Best Small Language Models for Agentic AI
Licenses and capabilities below come from each vendor’s model card; benchmark the candidates on your own eval set before you pick one per agent. Older, now superseded small models: Phi-3.5-mini (MIT), Gemma 2 2B and 9B (Gemma Terms), Qwen 2.5 0.5B to 3B (licenses vary by size) and the original Ministral 8B (Mistral Commercial or Research License).
Microsoft Phi-4-mini and Phi-4
Phi-4-mini-instruct (3.8B, MIT) supports a 128K-token context and was post-trained for instruction following and function calling, with a tool-enabled function-calling format on its model card. Phi-4 (14B, MIT) is an option for reasoning-heavy steps, and Phi-4-reasoning (14B, MIT) is its reasoning-tuned variant. At the 3.8B size, Microsoft also ships Phi-4-mini-reasoning and Phi-4-mini-flash-reasoning (both MIT).
Google Gemma 4 E2B and E4B
Gemma 4 launched on April 2, 2026 under Apache-2.0, a change from the Gemma Terms that cover Gemma 2 and Gemma 3. Google’s model card targets mobile and edge devices with E2B and E4B, gives the small models a 128K context window, adds audio input, and lists native function-calling support. A 12B model is also available for consumer GPUs and workstations.
Alibaba Qwen3.5 Small Models
Qwen3.5 comes in 0.8B, 2B, 4B and 9B sizes, all Apache-2.0, released on March 2, 2026. The model card lists a native context of 262,144 tokens and covers tool calling in its serving and agentic-usage sections. The spread of sizes lets you match each agent to the smallest model that passes its evals.
Mistral Ministral 3
Mistral announced Ministral 3 on December 2, 2025 in 3B, 8B and 14B sizes, each with base, instruct and reasoning variants, image understanding and an Apache-2.0 license. Mistral’s model card describes Ministral 3 as having best-in-class agentic capabilities with native function calling and JSON output, and lists a 256K context window.
Meta Llama 3.2 1B and 3B
Meta announced Llama 3.2 1B and 3B as lightweight text-only models for edge and mobile devices. They ship under the Llama 3.2 Community License: commercial use is allowed, but distributing it requires “Built with Llama” attribution, use must follow an Acceptable Use Policy, and you need a separate license from Meta above 700 million monthly active users.
Hugging Face SmolLM3
Hugging Face’s model card calls SmolLM3-3B (Apache-2.0, July 2025) a fully open model. It was trained on a 64K context, supports up to 128K tokens with YaRN, and supports tool calling.
What Is the Smallest Agentic Model?
In this lineup, the smallest model with documented tool calling is Qwen3.5-0.8B, at 0.8B parameters on its model card. Gemma 4 E2B is an on-device option: Google’s model card targets mobile and edge devices with it and lists native function-calling support. Llama 3.2 1B is Meta’s edge option. Models this small need tight tool schemas, short tool lists and evals on every call path before they take production traffic.
How To Build a Multi-Agent System with SLMs
Architecture: One Agent Per Specialized Job
One workable agentic architecture uses one fine-tuned SLM per distinct job. An example document analysis pipeline:
- Router agent: Qwen3.5-2B fine-tuned on (query, target_tool) pairs.
- Retrieval agent: Llama 3.2 3B or Gemma 4 E4B fine-tuned on (query, retrieved_doc_id) pairs, calling a vector DB.
- Extraction agent: Phi-4-mini fine-tuned on (document, structured_extract) pairs.
- Reasoning agent: Phi-4-reasoning 14B used zero-shot for the synthesis step that benefits from broader world knowledge.
- Verifier agent: Ministral 3 8B fine-tuned to check the reasoning agent’s output for the specific failure modes you have observed.
Each agent is a swappable component. If the router regresses, retrain just the router. If a stronger reasoning model launches, swap Phi-4-reasoning for it without touching the others.
Fine-Tuning Pattern
LoRA or QLoRA on a single GPU is a practical starting point, and NVIDIA’s paper treats 10K to 100K task examples as a rule of thumb. The paper also suggests knowledge distillation as an alternative: train the SLM to mimic the LLM’s outputs on the task dataset.
Useful libraries: Hugging Face PEFT for the LoRA mechanism, Unsloth for accelerated single-GPU training, axolotl for declarative training configs. Build per-agent datasets that look like the production traffic you expect: same length distribution, same noise distribution, same label distribution.
# Sketch: LoRA fine-tune Llama 3.2 3B for a router agent
from peft import LoraConfig, get_peft_model
from transformers import AutoModelForCausalLM, AutoTokenizer

model = AutoModelForCausalLM.from_pretrained("meta-llama/Llama-3.2-3B-Instruct")
tokenizer = AutoTokenizer.from_pretrained("meta-llama/Llama-3.2-3B-Instruct")

lora_config = LoraConfig(
    r=16,
    lora_alpha=32,
    target_modules=["q_proj", "v_proj"],
    lora_dropout=0.05,
    bias="none",
    task_type="CAUSAL_LM",
)
model = get_peft_model(model, lora_config)
# Train on (query, target_tool) pairs ...
Llama 3.2 3B is gated on Hugging Face, so accept Meta’s license on the model page before downloading. Once access is granted, log in with your Hugging Face token so from_pretrained can fetch the weights.
Can Small Language Models Use Tools?
Yes, for narrow, well-shaped calls. Current SLMs document tool use on their model cards: Phi-4-mini has a tool-enabled function-calling format, Gemma 4 and Ministral 3 list native function calling, Qwen3.5 documents tool calling, and SmolLM3 supports tool calling. The trade-off versus frontier LLMs is reliability under adversarial or out-of-distribution inputs, so pair an SLM tool-caller with a fallback to a stronger model for low-confidence cases.
Chain-of-Thought Patterns
Chain-of-Thought (CoT) prompting can still help SLMs on multi-step reasoning. Instead of a generic “think step by step” instruction, train the agent on examples that show the step decomposition you want.
Evaluating SLM-Powered Agentic Systems
A multi-agent system has two eval surfaces and you need both. For the wider method, see our agentic AI evaluation framework.
Per-Agent Eval Suites
Test each fine-tuned agent in isolation against a held-out test set. For the router agent, the metric is routing accuracy; for the extraction agent, it is exact-match or structured-field accuracy. For the reasoning agent, the metric is faithfulness against the supplied context. Future AGI’s eval SDK in agent-learning-kit (Apache-2.0, formerly ai-evaluation) ships first-party evaluators for faithfulness, groundedness, toxicity, PII, and custom LLM-as-judge rubrics:
from fi.evals import evaluate

result = evaluate(
    "faithfulness",
    output="The customer's refund was processed on April 12.",
    context="Refund record: customer_id=42, amount=$50, status=processed, date=2026-04-12",
)
print(result.score, result.reason)
End-to-End Workflow Evals
Test the full agent chain against scenarios you care about. End-to-end evals catch handoff bugs that per-agent evals miss: agent A emits a malformed handoff token, agent B silently drops the request, the workflow produces a wrong but plausible answer. traceAI (Apache 2.0) instruments the multi-agent workflow with OpenTelemetry spans so you can see where time and errors concentrate:
from fi_instrumentation import register, FITracer
from fi_instrumentation.fi_types import ProjectType

trace_provider = register(project_type=ProjectType.OBSERVE, project_name="slm-agents")
tracer = FITracer(trace_provider.get_tracer(__name__))

@tracer.agent
def router(query: str) -> str:
    ...

@tracer.tool
def search_kb(query: str) -> list:
    ...

@tracer.chain
def run_workflow(user_input: str) -> str:
    target = router(user_input)
    if target == "search":
        return search_kb(user_input)
    ...
Env vars: FI_API_KEY and FI_SECRET_KEY if you want to send traces and eval results to the platform. traceAI is built on OpenTelemetry, so you can also send the same spans to any OTel-compatible backend. For a deeper walkthrough, see how to trace and debug multi-agent systems.
Continuous Improvement Loop
A simple feedback loop in production: log every agent call with input, output, latency, and any user signal. Build a daily job that flags low-confidence or low-signal outputs for human review. Use the labeled review set to either retrain the offending agent or update its evaluation rubric. Retraining one agent at a time keeps each change small and easy to roll back.
Where SLMs Sit in the Real-World Stack
Customer Support
One multi-agent SLM stack for customer support has: a router agent that classifies the ticket, an extraction agent that pulls the relevant entities (order_id, account_id, issue_category), a retrieval agent that pulls the relevant KB snippets, and a response agent that drafts the reply. Qwen3.5-2B or Llama 3.2 3B fits the routing and extraction roles, and Phi-4-mini or Gemma 4 E4B handles drafting.
Healthcare and Finance
Specialized SLMs fit both verticals because open-weight models can run on-prem or on a local GPU, inside the regulatory boundary. The hard part is data: you need labeled, compliance-cleared training data before you can fine-tune. Plan the data pipeline first.
Retail and Personalization
Personalization engines can use SLMs as scoring or classification components alongside a recommender system. Here the SLM scores candidate items against the user’s stated context instead of acting as the recommender. Qwen3.5-2B and Llama 3.2 3B are candidates to benchmark for this scoring role.
Edge and IoT
Gemma 4 E2B and Llama 3.2 1B are documented on-device options: Google’s Gemma 4 model card targets mobile and edge devices with E2B and E4B, and Meta announced Llama 3.2 1B and 3B for edge and mobile devices. Qwen3.5-0.8B is the smallest model in this lineup. Local inference runtimes such as llama.cpp and Apple MLX (an array framework for machine learning on Apple silicon) let you run these models on your own hardware.
How Future AGI Fits With an SLM-Powered Agentic Stack
Future AGI does not compete with SLM model providers. It is the evaluation and observability companion that sits alongside whatever SLMs you choose for your agents. The pattern is:
- Fine-tune the per-agent SLM with PEFT, Unsloth, or axolotl.
- Serve with vLLM, SGLang, llama.cpp, or Ollama.
- Route and gate with Agent Command Center, Future AGI’s OpenAI-compatible gateway: one endpoint across 100+ providers, including self-hosted Ollama, vLLM, LM Studio or any OpenAI-compatible server, with routing, failover, caching and budget limits.
- Evaluate per agent and end-to-end. Future AGI has custom evals: write your own grading criteria, choose an LLM judge, an agent evaluator or a code check for a deterministic rule, and run it in CI to gate pull requests; built-in checks include Task Completion, Tool Call Accuracy and Evaluate Function Calling.
- Trace the multi-agent workflow with traceAI’s
register,FITracer, and the@tracer.agent,@tracer.tool,@tracer.chaindecorators.
This keeps the model layer (your SLMs) and the production-quality layer (Future AGI’s eval and observability stack) decoupled. You can swap models without touching evals, and you can deepen evals without retraining models.
Move Your Agent’s Easy Calls to SLMs, and Prove It With Evals
That agent paying frontier prices to classify a ticket, pull an order ID and pick a tool does not need a frontier model for those steps. Log every call, cluster the repetitive ones, fine-tune a small language model for each, and keep a frontier fallback for open-ended cases. Then score every swap with the same evals before you shift traffic.
Get started with Future AGI’s eval SDK in agent-learning-kit and traceAI, both Apache-2.0, for the eval and observability side of your SLM-powered agentic stack.
Trace your agent’s calls and find the ones an SLM can take over with Future AGI.
Frequently Asked Questions
Are small language models the future of agentic AI?
What is a small language model?
What is the difference between LLM and SLM?
Should I use LLM or SLM?
What are SLM agents?
What are the best small language models for agentic AI?
Can small language models handle agentic tool calling?
Compare the top agentic AI frameworks in 2026: LangGraph, OpenAI Agents SDK, Microsoft Agent Framework, CrewAI, AutoGen, Mastra, and PydanticAI.

Build reliable multi-agent AI flows with Future AGI in 2026: synthetic datasets, traceAI, fi.evals, fi.simulate, Agent Command Center.

Components of LLM agents in 2026: tokenizer, embeddings, and transformer blocks inside the model, plus memory, tools, planner, runtime, and tracing around it.
