9 LLM Prompt Format Patterns and the Eval Loop That Catches Regressions
Get the LLM prompt format that works on GPT-6, Claude Opus 5.5 and Gemini 4 Argon: instruction order, delimiters, output schemas, few-shot counts, an eval loop.
Table of Contents
The LLM prompt format this guide recommends for 2026 puts durable rules in the system or developer message, locks each section behind one consistent delimiter, and places long documents above the question. The nine patterns below are prompt engineering moves for GPT-6, Claude Opus 5.5 and Gemini 4 Argon, each paired with the eval loop that proves a change before it ships. The companion guide to prompt engineering patterns beyond format covers the rest.
LLM Prompt Format Rules That Matter in 2026
| Question | Short answer |
|---|---|
| Where does the instruction go? | First in the system or developer message. With long documents, put the documents first and the question last. |
| Best delimiter style? | XML tags or Markdown headings, one style per prompt. Use a JSON schema through the API’s structured output feature for the reply. |
| Few-shot example count? | Try zero-shot first on reasoning models; when you need examples, 3 to 5 diverse ones (Anthropic’s current guidance). |
| Should I add “think step by step”? | Not on reasoning models. OpenAI says they reason internally, so the instruction is unnecessary; tune reasoning effort instead. |
| Where do hard rules go? | In the system or developer message and near the top of the prompt, not buried mid-prompt. |
| How do I prove a change is better? | Score old and new prompts on the same labelled set with the same evals, and ship only the winner. |
Why Does Prompt Format Matter for LLMs?
Fine-tuning, RAG and a bigger model all cost time or money. Changing prompt format needs no training run or new infrastructure, it is reversible, and scoring the old and new prompt on the same set tells you whether a format change helped on your data.
How to Structure an LLM Prompt in 9 Patterns
1. Instructions First, Long Documents Before the Question
Put durable instructions first, in the system or developer message. For long inputs, put the documents above the question, as the long-documents section below explains. A short input like a single support ticket can sit right under the instruction, as in this template.
Template:
You are a customer-support classifier. Read the ticket below and return the
category as one of: billing, technical, account, other.

<ticket>
{ticket_body}
</ticket>

Output only the category string. No explanation.
The instruction comes first, the ticket sits inside a delimited block, and the output rule comes last: three lines, three jobs. For long inputs (20k+ tokens), flip the order: documents first, question last.
2. Delimiter-locked sections
Wrap each logical section in the same delimiter style end to end, so the model can tell context, examples, task and output schema apart.
- XML tags on Claude. Anthropic’s prompt engineering guide recommends wrapping each type of content in its own XML tag, for example
<instructions>,<context>and<input>, and wrapping examples in<example>tags. - JSON schema on OpenAI models. Use Structured Outputs (
text.formatin the Responses API,response_formatin Chat Completions) for the reply, and strict mode in function definitions for tool calls, as OpenAI’s Structured Outputs guide describes. - Markdown for everything else. Headings, lists, code fences.
Do not mix. Pick one delimiter style per prompt and keep it consistent.
3. Explicit output schema
Telling the model the format in prose gives no guarantee that the output follows it. A request-time JSON schema or grammar reliably enforces structure and is what OpenAI, Anthropic and Google all document.
{
  "model": "gpt-6-luna",
  "messages": [
    {"role": "user", "content": "<the ticket body goes here>"}
  ],
  "response_format": {
    "type": "json_schema",
    "json_schema": {
      "name": "classify",
      "strict": true,
      "schema": {
        "type": "object",
        "properties": {
          "category": {"type": "string", "enum": ["billing", "technical", "account", "other"]},
          "confidence": {"type": "number", "minimum": 0, "maximum": 1}
        },
        "required": ["category", "confidence"],
        "additionalProperties": false
      }
    }
  }
}
Anthropic and Google ship the same primitive: Claude’s Structured Outputs (output_config.format, plus strict: true for tool inputs) and Gemini’s response_format with a JSON schema. Once the schema is in place, evaluating the structured-output mode is what confirms the model honors it under load.
4. Constraint pinning
Models use information at the start and end of a long prompt more reliably than information in the middle. This is the finding of Liu et al. 2023 (Lost in the Middle). Practical consequence: pin hard rules (privacy, brand tone, banned topics) to the top of the prompt, then repeat them in the system message, and do not bury them at line 800.
5. Zero-Shot First, Then 3 to 5 Examples
Try zero-shot first. OpenAI’s reasoning guide says reasoning models often don’t need few-shot examples to produce good results. When the output still drifts, add examples: Anthropic’s guide says to include 3 to 5 examples for best results, wrap them in <example> tags, and make them diverse enough to cover edge cases so the model does not pick up unintended patterns. For a deeper walkthrough, see the full guide to few-shot prompting.
6. Negative examples, sparingly
Show a “do not produce this” example only for high-risk formats: PII leaks, banned URL patterns, harmful tone. Back it with a guardrail layer at runtime instead of a growing list of counterexamples in the prompt.
7. Persona via system or developer message
OpenAI’s docs describe developer messages as instructions from the application developer, prioritized ahead of user messages, and for reasoning models “developer messages are the new system messages.” Chat Completions still accepts a system message, and Anthropic takes a top-level system prompt. Both carry durable, session-level instructions, though exact precedence differs by provider, so check the current API reference for the SDK you target.
Put the persona, tone, language, and durable rules in the system or developer message. Keep the user turn lean and focused on the current task. This gives the persona persistence across turns and keeps user messages compact for logging and replay.
8. No chain-of-thought on reasoning models
The zero-shot “think step by step” trigger was a 2022 breakthrough on davinci. On reasoning models it is unnecessary, because they reason internally. The chain-of-thought prompting guide covers where the phrase still earns its tokens.
GPT-6 Astra, Claude Opus 5.5 and Gemini 4 Argon all reason before they answer. OpenAI’s reasoning guide says that since these models perform reasoning internally, prompting them to “think step by step” or “explain your reasoning” is unnecessary.
Drop the phrase on reasoning models. If you want less thinking, lower the reasoning effort setting instead of rewriting the prompt; GPT-6 Luna, for example, accepts reasoning.effort values from none to max. When thinking is off on Claude, Anthropic lists asking the model to think through the problem before it answers as a fallback.
9. Score Every Prompt Change Before It Ships
A prompt change without an eval is a vibes change. Run the old prompt and new prompt against the same labelled set, score both, and ship only the version that wins.
Future AGI has custom evals: write your own grading rule, choose an LLM judge or a deterministic check, map your dataset columns and set a pass threshold. Built-in evals that fit prompt-format work include Groundedness, Instruction Adherence, Is JSON and Toxicity. The evals SDK, Agent Learning Kit, is Apache-2.0 (pip install agent-learning-kit).
import os
os.environ["FI_API_KEY"] = "..."
os.environ["FI_SECRET_KEY"] = "..."

from fi.evals import evaluate

# Score one (input, output) pair with the Groundedness eval.
result = evaluate(
    "groundedness",
    input="Summarise the ticket: customer cannot log in after password reset.",
    context="Ticket #4321: user reset password, SSO still holds the old session.",
    output="The customer is locked out after the reset because SSO kept the old session.",
    model="turing_flash",
)
print(result.score, result.reason)
Loop the same call across your labelled prompts and aggregate the scores per prompt variant to compare versions. Each result also carries a plain-language reason, so you can read why a variant failed instead of guessing.
Where Should Long Documents Go in a Prompt?
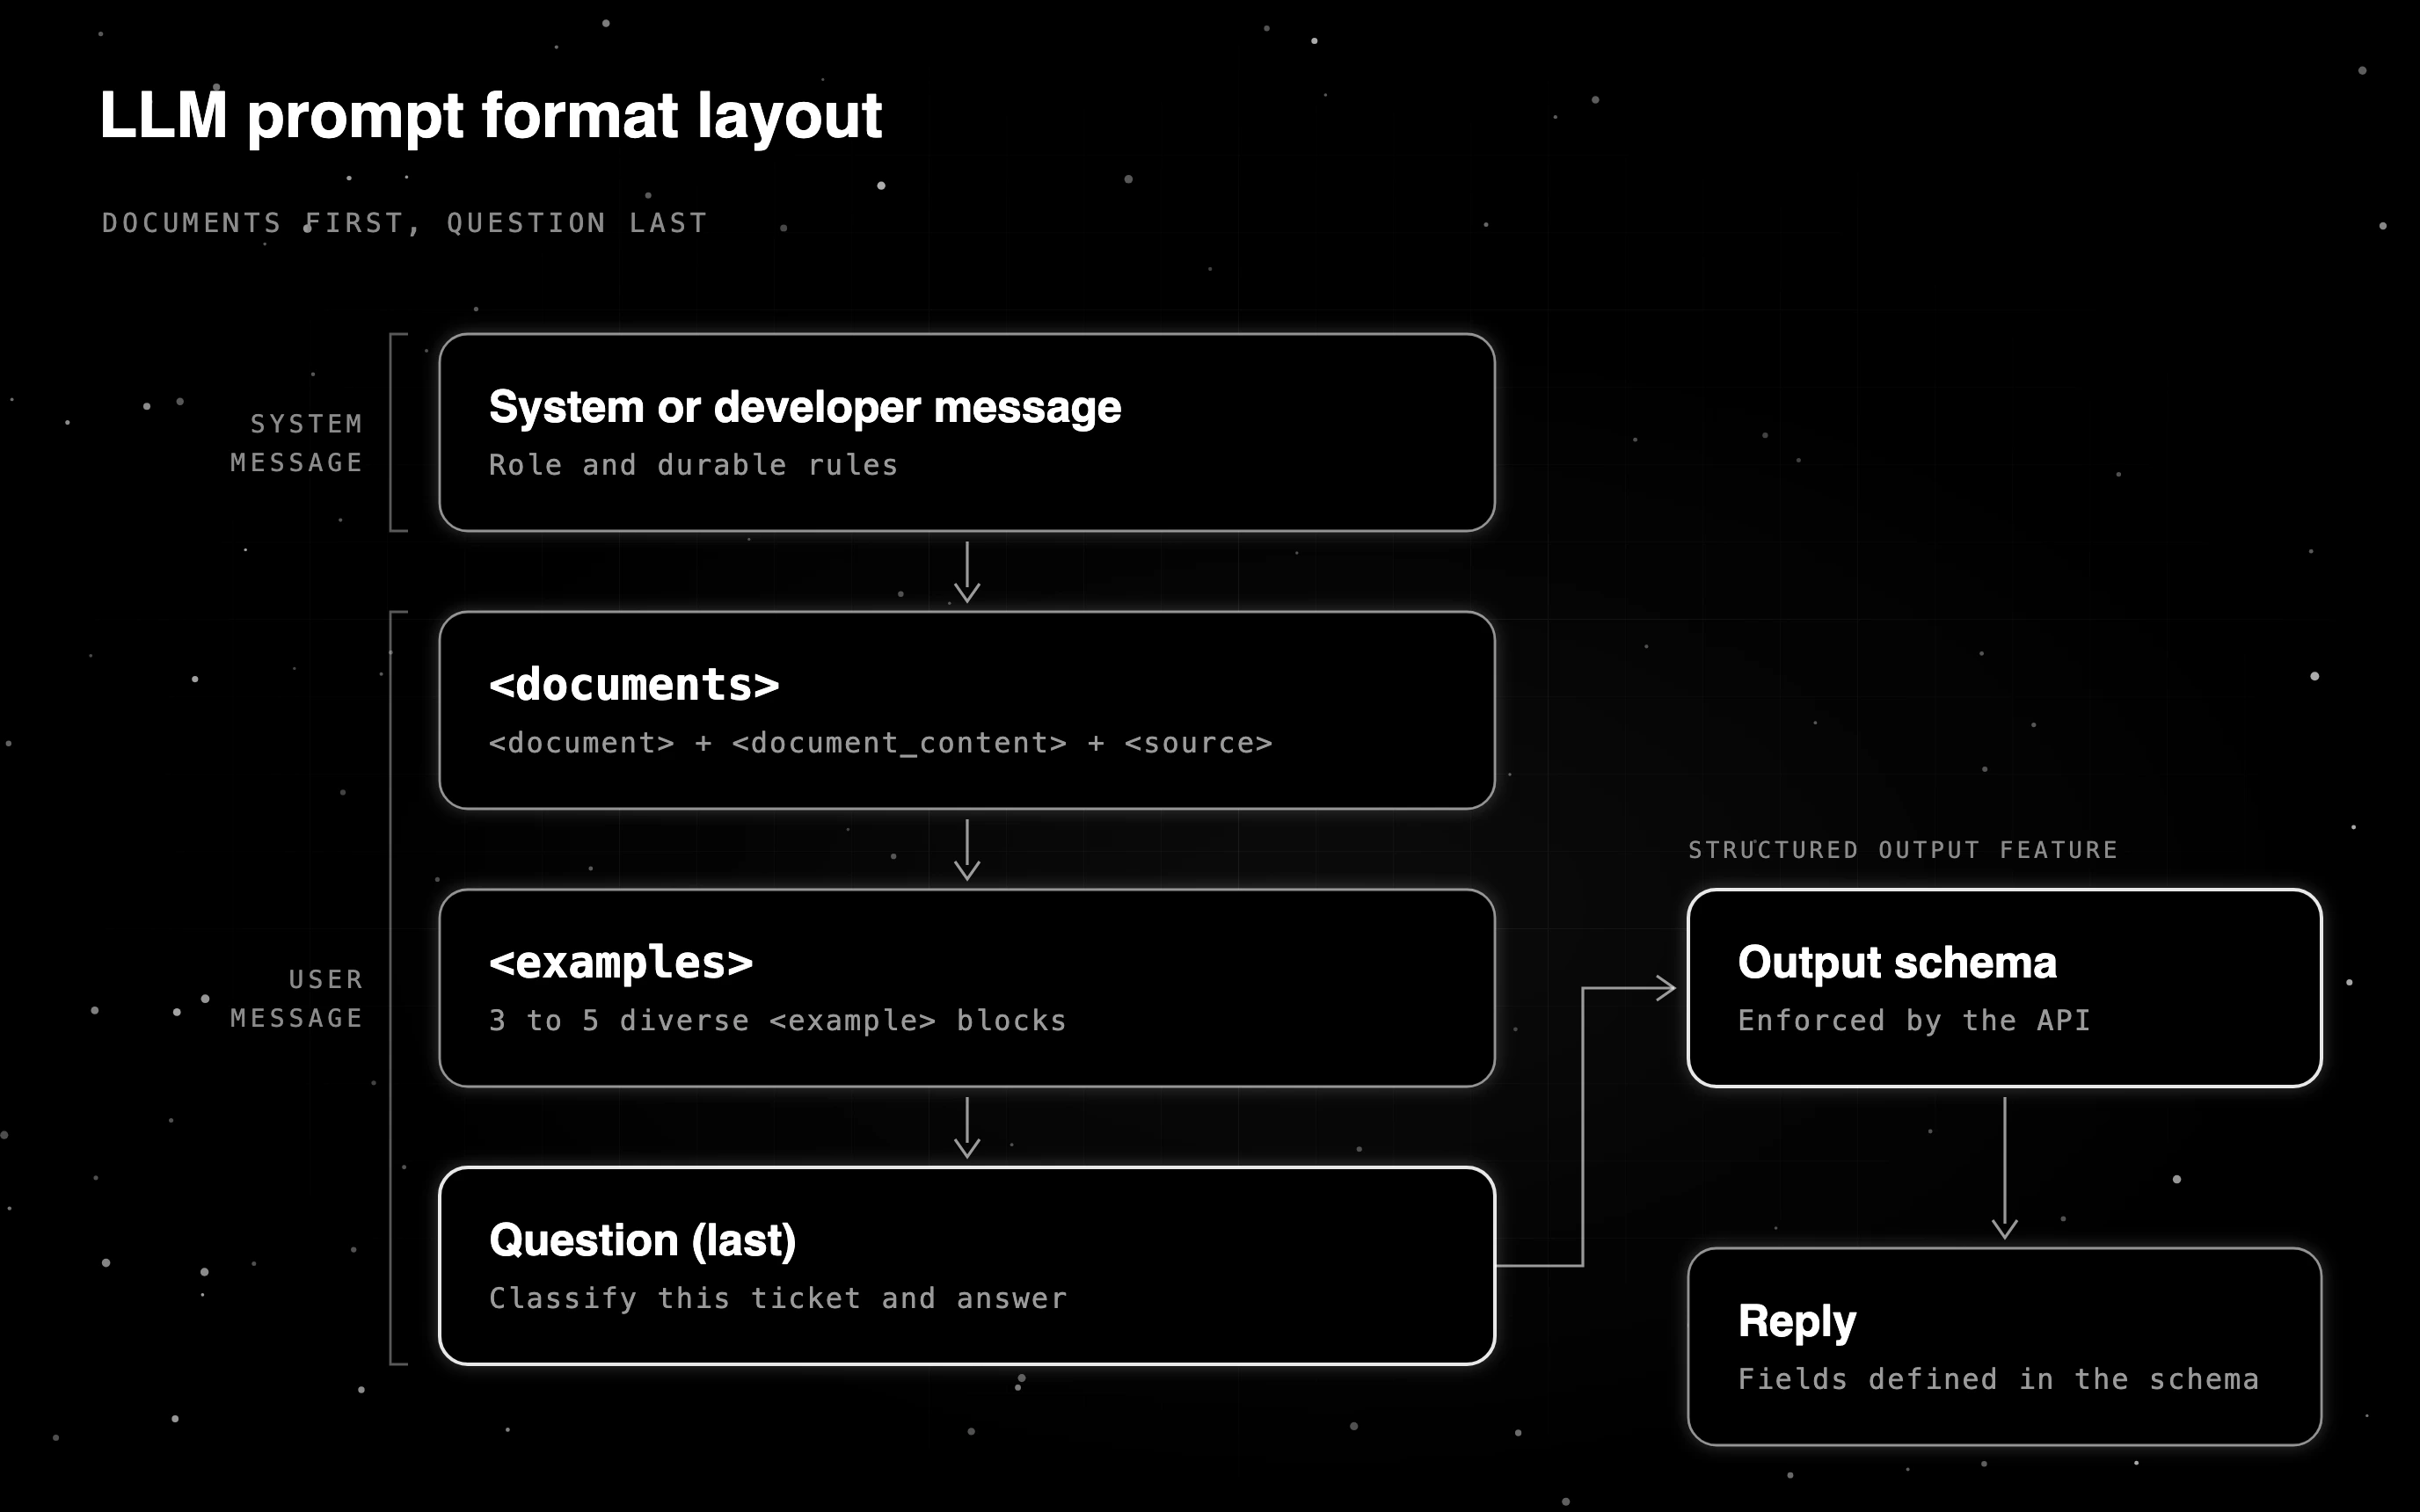
Put long documents near the top of the prompt and the question at the end. Anthropic’s prompting guide says to place long documents and inputs (20k+ tokens) near the top, above your query, instructions and examples, and reports that queries at the end can improve response quality by up to 30% in its tests, especially with complex, multi-document inputs.
Durable rules still belong in the system or developer message. OpenAI’s prompt guide builds a developer message in the order identity, instructions, examples, then context, and says context is usually best positioned near the end, since you may include different context for different requests.
With several documents, give each one its own wrapper. Anthropic suggests wrapping each document in <document> tags with <document_content> and <source> subtags, plus any other metadata, for clarity. The template below shows that layout.
A Copy-Ready LLM Prompt Template
This skeleton combines patterns 1 to 4 and 7: durable rules in the system or developer message, long documents next, examples after them, and the question last, with the output schema enforced by the API instead of described in prose.
System or developer message:
You are a support-ticket triage assistant for {product}.
Rules:
- Use only the documents provided in the user message.
- Never include personal data from a ticket in your answer.
- If the documents do not answer the question, reply "unknown".
User message:
<documents>
  <document index="1">
    <source>{source_name}</source>
    <document_content>{document_text}</document_content>
  </document>
</documents>

<examples>
  <example>
    <ticket>{example_ticket}</ticket>
    <answer>{example_answer}</answer>
  </example>
</examples>

<ticket>{ticket_body}</ticket>

Classify this ticket and answer the customer's question. Reply with the fields defined in the response schema.
Pass the schema through the API’s structured output feature, using the JSON schema in pattern 3 as a starting point. Then score the template on your labelled set before and after every change.
The eight common mistakes
| Mistake | What happens | Fix |
|---|---|---|
| Long documents pasted after the question | Weaker answers on long inputs | Documents first, question last, durable rules in the system message |
| Mixing XML, JSON and Markdown delimiters | Section boundaries get ambiguous | Pick one delimiter style |
| Describing JSON in prose | No schema guarantee on the output | Use structured outputs with a JSON schema |
| Hard rule at line 800 of 1,000 | Mid-prompt content is used less reliably (lost in the middle) | Pin to top and repeat in system |
| Examples that all look alike | Model picks up unintended patterns | 3 to 5 diverse examples, after trying zero-shot |
| Think step by step on a reasoning model | Unnecessary, it already reasons internally | Drop it; lower reasoning effort instead |
| Persona in every user turn | Bloated logs, drift across turns | Persona in system message |
| Shipping without an eval set | Cannot tell better from worse | Score old and new prompts on the same labelled set |
When to Use Instruction-Based, Few-Shot or Zero-Shot Prompts
| Pattern | When it wins | When it loses |
|---|---|---|
| Zero-shot | The starting point on reasoning models; OpenAI says try zero-shot first. | Niche jargon, custom labels, structured extraction. |
| Few-shot (3 to 5 diverse examples) | Custom labels, brand-specific tone, narrow extraction schema, once zero-shot falls short. | Reasoning models that already handle the task zero-shot. |
| Instruction + schema | Anything that returns JSON, key-value pairs, or a fixed enum. | Pure free-form text (essays, drafts). |
| Tool use | Anything that needs to look up live data or call deterministic code. | Tasks that fit in pure text and would just add a round trip. |
An LLM Prompt Format Example for a Support Classifier
2025 version (chat-style, prose format):
You are a helpful assistant. Given a customer support ticket, please carefully read
it and think step by step about what category it belongs to. The possible categories
are billing, technical, account, or other. Please return your answer in JSON with
fields "category" and "confidence" (a number from 0 to 1). Be polite.

Here is the ticket: {ticket_body}
Issues: the persona sits at the top, but the instruction is on line 3, and “think step by step” is unnecessary on reasoning models. The JSON is described in prose, and the politeness instruction has no bearing on a category label.
2026 version (instruction-first, schema-constrained):
System message:
You are a customer-support ticket classifier. Output a JSON object matching the
provided schema. Never output any other text. Never include PII from the ticket
in the confidence reasoning.
User message:
<ticket>{ticket_body}</ticket>Plus a strict json_schema constraint on the response. Run your own eval to measure the change on your data.
The Iterate and Test Loop for Prompt Format Changes
- Write v1. Apply patterns 1, 2, 3, 4 from above. Score it on a labelled staging eval set.
- Score with
fi.evals.evaluate. Look for failure clusters as well as aggregate accuracy. - Patch the largest cluster. If most failures are format errors, tighten the schema. If constraints go missing, pin the constraint higher.
- Re-score. Ship only when the new version beats the old one on the same set.
- Promote. Push v2 to production. Log every call. Refresh the eval set from production logs on a regular schedule. Repeat.
This is the loop that turns prompt engineering from a vibes practice into a measurable engineering discipline. When two formats score close on a small set, an A/B test on live prompts settles it with production traffic.
Ship Your Next Prompt Format Change With an Eval Behind It
The format rules above tell you what to try; scoring the old and new prompt on the same set tells you whether it worked. Future AGI ships Apache-2.0 SDKs (Agent Learning Kit, traceAI) alongside a commercial managed platform. Three pieces matter for prompt-format work:
- Evaluate scores each prompt version’s outputs with built-in or custom evals, so a format change shows up as a score change instead of a hunch.
-
Prompt keeps each template as a named, versioned object you can change without a deploy, compare side by side, fetch into your app with the SDK, run against dataset rows, and score with evals. Here is how prompt versioning and rollback work.
-
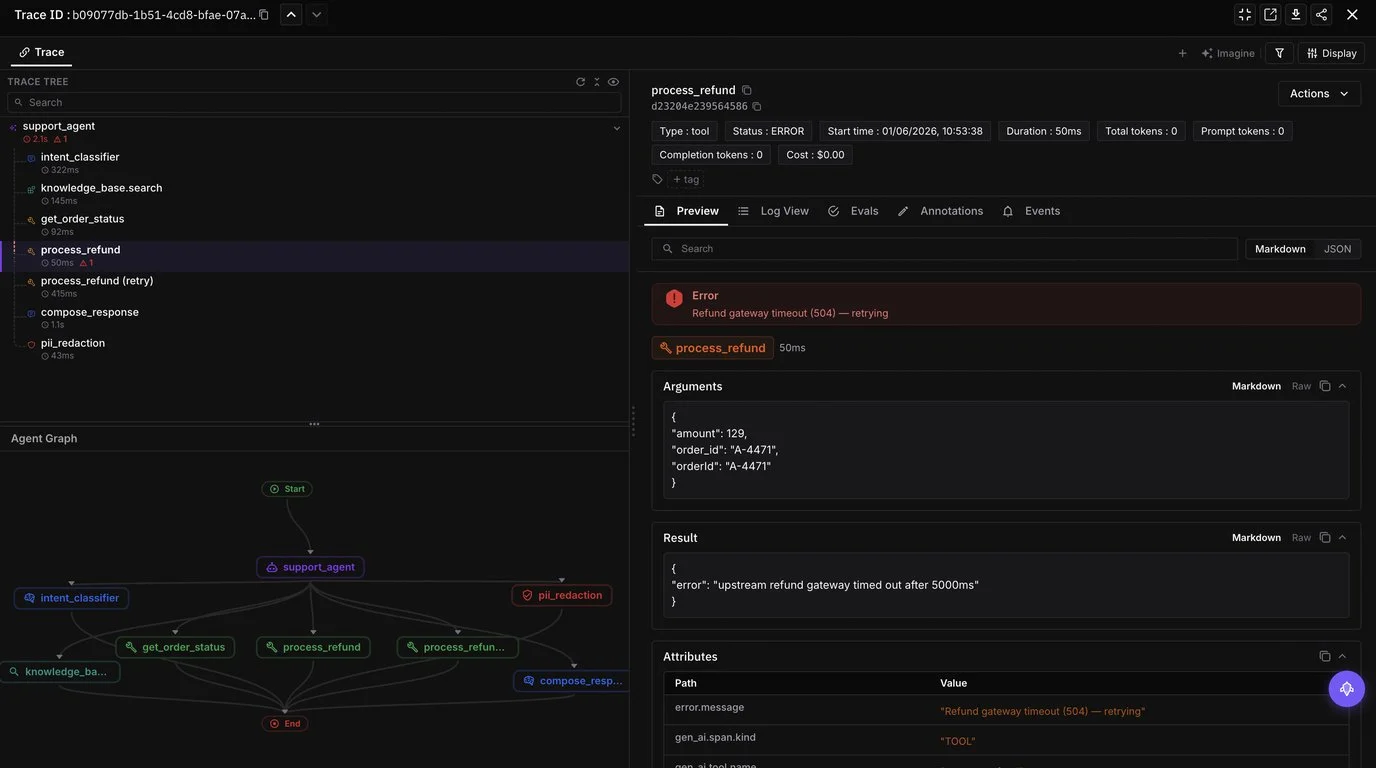
traceAI is Future AGI’s Apache-2.0 tracing library, built on OpenTelemetry, that records LLM calls as spans with latency and token usage and sends them to any OTel-compatible backend. Source at github.com/future-agi/traceAI.
Frequently Asked Questions
What are LLM prompts?
How do you structure an LLM prompt?
Where should the task go in an LLM prompt?
Should I use XML tags or Markdown in an LLM prompt?
What are the four LLM prompt types?
What are LLM system prompts?
How do you get JSON output from an LLM prompt?
How do you test LLM prompts?
What prompt engineering means in 2026 after Bayesian, GEPA, and ProTeGi optimizers. Anatomy, techniques, tools, and where hand-tuning still earns its keep.

DSPy, FutureAGI Prompt Optimizer, PromptFoo, OpenAI Playground, Helicone Prompts, Braintrust Prompts, plus tradeoffs for 2026 prompt engineering workflows.
A/B testing LLM prompts without power analysis is theater. The 2026 playbook: MDE, sample sizing, matched pairs, bootstrap CIs, bandits, and rollout.