Top 11 LLM API Providers in 2026: Pricing, Latency, and Context Window Compared
Compare 11 LLM providers for 2026, from OpenAI, Anthropic and Google to Groq and Together AI, on token price, context window, speed, free tiers and fit.
Table of Contents
LLM providers sell API access to large language models. This guide compares 11 of them, from model labs to inference hosts, on token price, context window, speed, and enterprise fit, with prices checked on each vendor’s pricing page on October 28, 2026.
TL;DR for LLM API providers in October 2026
| Question | Answer |
|---|---|
| Frontier reasoning leader? | No single leader: GPT-6 Astra, Claude Fable 5.1, and Gemini 4 Argon are each vendor’s top model. |
| Cheapest bulk inference? | Cohere’s Command R7B ($0.0375/$0.15) or Groq’s GPT OSS 20B ($0.075/$0.30); Gemini 2.5 Flash-Lite ($0.10/$0.40) only if your project already uses it. |
| Longest frontier context? | About 1M tokens on the OpenAI, Anthropic, and Google flagships. |
| Fastest open-model serving? | Groq lists 500 tokens/s on GPT OSS 120B; Cerebras, a Hugging Face partner, lists about 3,000 on gpt-oss-120b. |
| Best for AI agents? | Claude Opus 5.5 or Fable 5.1 for long-running agentic work. |
| Best open-weight? | Mistral Large 3 (Apache 2.0) and gpt-oss-120B. |
| Single SDK or gateway? | Use a gateway; the OpenAI SDK is the de facto cross-provider standard. |
Why choosing the right LLM API in 2026 still matters
Three shifts changed the answer in 2026:
- Reasoning models replaced chat models. GPT-6.1 Sol, Claude Opus 5.5, and Gemini 4 Argon all run internal scratchpads.
- OpenAI SDK is the de facto wire protocol. Together AI, Fireworks, Groq, and Hugging Face inference endpoints expose OpenAI-compatible APIs; Anthropic keeps its own SDK as the primary surface but is reachable through gateways and adapters. The SDK choice no longer locks you to one vendor.
- 1M-token context is the frontier. GPT-6 models list 1,050,000 tokens, current Claude models 1M, and Gemini 4 Argon 1,048,576.
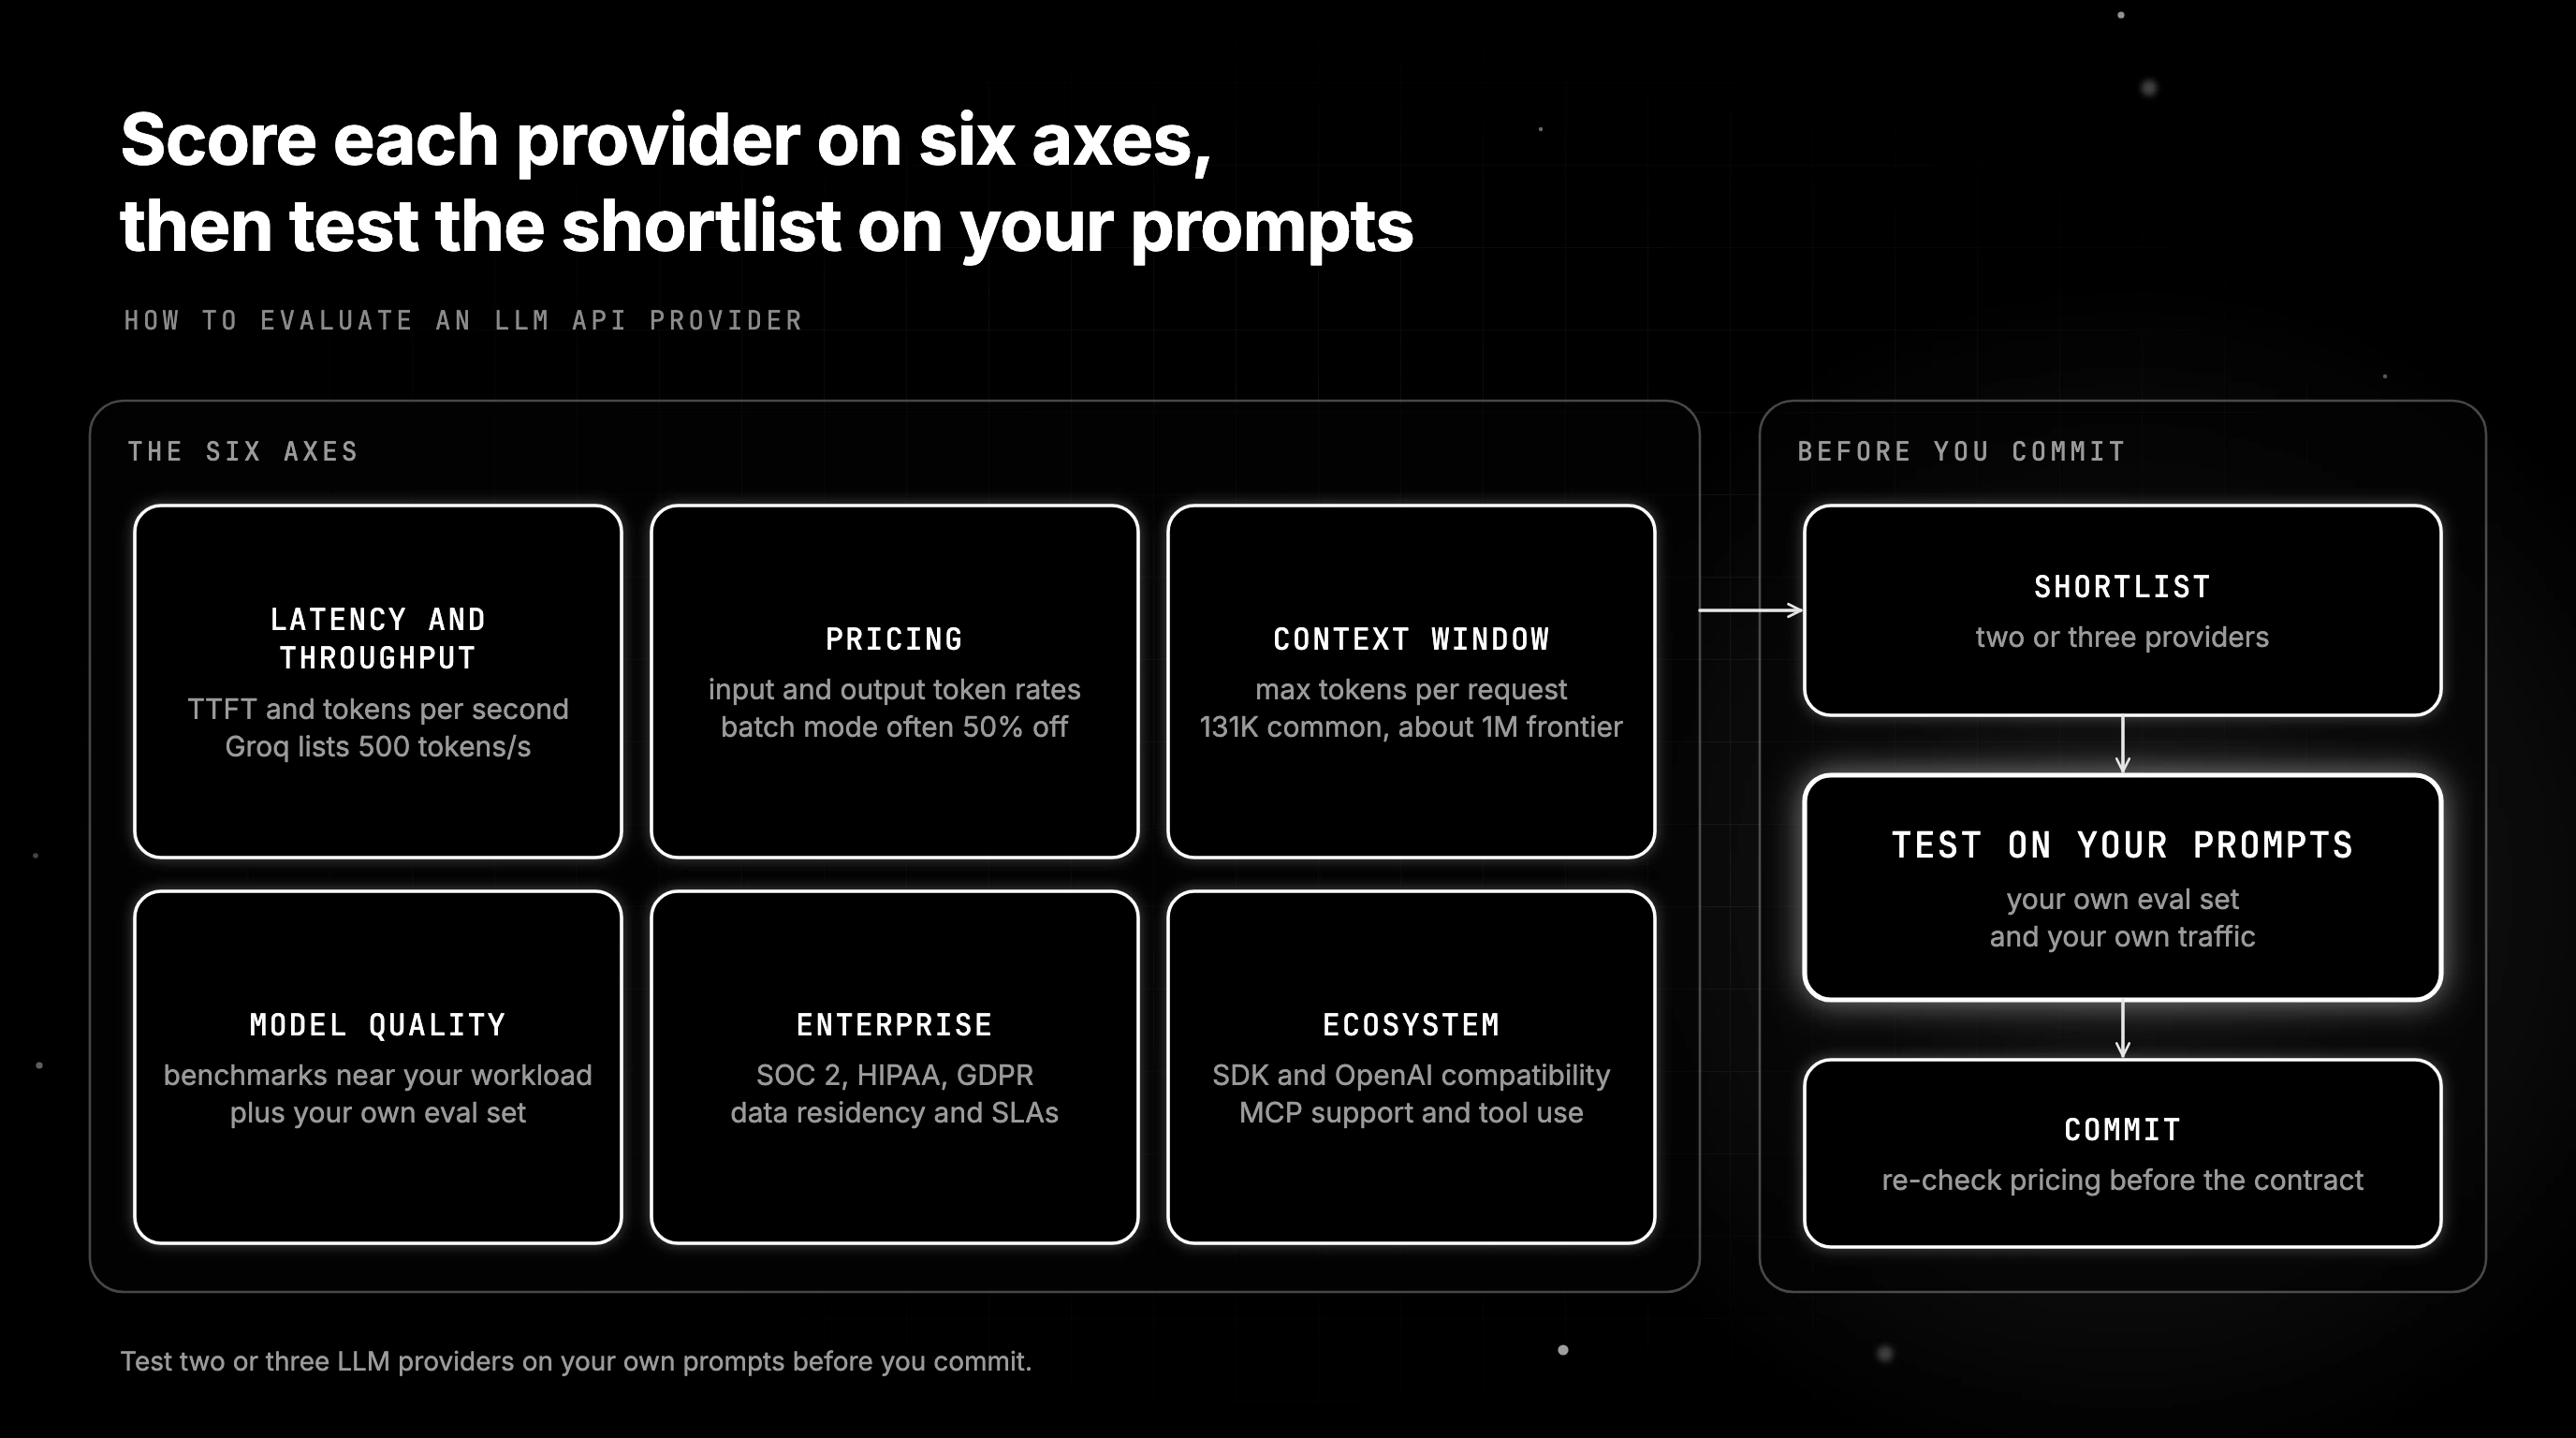
How to evaluate an LLM API provider on 6 axes
- Latency and throughput: time-to-first-token (TTFT) and tokens-per-second under sustained load. Groq lists 500 tokens per second for GPT OSS 120B.
- Pricing: input and output token rates. Watch for separate context-cache rates and batch-mode discounts (often 50% off). The LLM pricing and cost comparison guide breaks the per-model math down in detail.
- Context window: max tokens per request. 131K is common on open-model hosts; about 1M is the frontier.
- Model quality: task benchmarks close to your workload, plus your own eval set. Always check the vendor’s own benchmarks against an independent source like Artificial Analysis.
- Enterprise: SOC 2, HIPAA, GDPR, regional data residency, SLAs.
- Ecosystem: SDK quality, OpenAI compatibility, MCP support, tool-use surface.
LLM API provider comparison table (October 2026)
| Provider | Flagship model | Input ($/1M) | Output ($/1M) | Context | Specialty |
|---|---|---|---|---|---|
| OpenAI | GPT-6.1 Sol | 2.00 | 10.00 | 1.05M | Frontier reasoning; GPT-6 Astra is the top tier |
| Anthropic | Claude Opus 5.5 | 4.00 | 20.00 | 1M | Long-running agentic work |
| Google (Gemini) | Gemini 4 Argon | 2.00 (4.00 from Dec 1) | 10.00 (20.00 from Dec 1) | 1M | Native multimodal |
| Microsoft (Azure OpenAI) | GPT-6.1 Sol in Foundry | varies | varies | Model-dependent | 99.9% SLA, data zones |
| Amazon Bedrock | Claude, Nova, Llama, more | varies | varies | Model-dependent | Multi-vendor, AWS-native |
| Cohere | Command A+ | free up to rate limits | free up to rate limits | 128K | Open weights, RAG and tool use |
| Mistral | Mistral Large 3 | 0.50 | 1.50 | 256K | Open weights plus API |
| Together AI | DeepSeek V4.1 Flash | 0.30 | 1.20 | Model-dependent | Open models, GPU clusters |
| Fireworks AI | GLM-5.3 | 1.40 | 4.40 | 1M | FireAttention, 30+ regions |
| Hugging Face | Inference Providers | provider rate | provider rate | Model-dependent | 3M+ Hub models |
| Groq | GPT OSS 120B | 0.15 | 0.60 | 131K | 500 tokens/s listed |
Sources: each vendor’s official pricing page, checked October 28, 2026. OpenAI rates are for prompts up to 272K tokens. Always re-check before committing to a contract.
Model labs vs LLM inference providers
The 11 providers fall into three groups. Model labs (OpenAI, Anthropic, Google, Cohere, Mistral) train and sell their own models. LLM inference providers (Together AI, Fireworks AI, Groq, and Hugging Face’s partner network) host open models such as gpt-oss-120B, DeepSeek, and Qwen, while Azure and Amazon Bedrock resell both inside a cloud account.
The 11 LLM API providers in detail
1. OpenAI: GPT-6 family, frontier reasoning
OpenAI’s latest flagships are GPT-6 Astra, GPT-6.1 Sol, GPT-6.1 Terra, and GPT-6 Luna. Terra is the newest of the four, released on October 26, 2026.
Models in 2026:
- GPT-6 Astra, 6.1 Sol, 6.1 Terra, 6 Luna: $10/$50, $2/$10, $1/$5, and $0.10/$0.50 per 1M; all 1.05M context.
- GPT-4.1: shuts down January 14, 2027; OpenAI names GPT-6 Luna as the replacement (see the GPT-4.1 deep-dive).
Strengths:
- Reasoning: effort settings from low up to max on GPT-6.1 Sol.
- Tool use: function calling and structured outputs.
2. Anthropic: Claude Fable 5.1, Opus 5.5, Sonnet 5.5, Haiku 5.5
Anthropic sells Claude through its own API, Amazon Bedrock, Google Cloud, and Microsoft Foundry. Its docs suggest starting with Claude Opus 5.5 for most workloads.
Models in 2026:
- Claude Fable 5.1, Opus 5.5, Sonnet 5.5, Haiku 5.5: $10/$50, $4/$20, $2/$10, and from $0.10/$0.50 per 1M; all 1M context.
Strengths:
- Long agentic sessions: Anthropic positions Opus 5.5 for long-running agentic coding.
- XML-native prompting: Anthropic’s prompting guide recommends XML tag delimiters; use them to separate instructions, context, examples, and inputs.
3. Google (Gemini): 1M context, native multimodal
Gemini has a 1M-token flagship with text, image, audio, and video input. Google bills that flagship, Gemini 4 Argon, on the paid tier only.
Models in 2026:
- Gemini 4 Argon: 1,048,576 tokens, $2/$10 per 1M until November 30, 2026, then $4/$20.
- Gemini 2.5 Flash-Lite: $0.10/$0.40 per 1M with a free tier, open only to projects that already use it; Google points new projects to Gemini 3.5 Flash-Lite ($0.30/$2.50) or 3.8 Flash.
Strengths:
- Native multimodality: a single API call handles text, audio, image, and video.
- 1M-token context: room for an entire codebase or library of reports in one call.
- Web-scale grounding: optional grounding through Google Search adds inline citations.
4. Azure OpenAI in Microsoft Foundry: SLAs and data zones
Azure OpenAI gives you GPT-6.1 Sol in Microsoft Foundry with Azure compliance and SLAs. Deployments come in standard (pay per token), provisioned (reserved capacity), and batch types.
Models: the GPT-6.1 and GPT-6 series plus older GPT models, alongside Microsoft-curated additions.
Strengths:
- SLA-backed uptime: at least 99.9% availability.
- Data residency: Data Zone deployments keep processing in the US, EU, or APAC zone.
- Provisioned Throughput Units (PTUs): reserve capacity for predictable workloads.
Best fit: regulated industries that need formal data-residency contracts.
5. Amazon Bedrock: serverless multi-vendor gateway
Bedrock gives one AWS API across Anthropic, Amazon Nova, Meta, Mistral, Cohere, AI21, DeepSeek, OpenAI, Qwen, and xAI. Each model keeps a vendor-prefixed ID, such as anthropic.claude-opus-5-5 for Claude Opus 5.5.
Models: Claude, OpenAI GPT-6.1 Sol, Amazon Nova, Llama, Mistral, Cohere Command, DeepSeek, Qwen, and Grok.
Strengths:
- Serverless: pay per token; no GPU operations.
- Built-in RAG: Bedrock Knowledge Bases plus Agents for retrieval and orchestration.
- Consolidated billing: single AWS invoice across multiple model vendors.
- Batch mode: 50% discount versus on-demand for non-real-time workloads.
Best fit: AWS-native shops, multi-model strategies inside one cloud.
6. Cohere: Command A+ and Command A, retrieval-first
Cohere targets enterprise RAG and tool use with Command A (256K context), the open-weight Command A+, and Command R7B. Its custom models can be deployed privately, so your data stays inside your own environment.
Models in 2026:
- Command A+: Cohere’s first mixture-of-experts model, Apache 2.0 open weights, 128K context, free until rate limits are reached.
- Command A: 256K context, plus Reasoning, Vision, and Translate variants.
- Command R7B: efficient edge model. $0.0375/$0.15 per 1M.
- Embed 5 and Rerank 5: retrieval models for RAG.
Strengths:
- Multilingual: Command A Translate covers 23 languages.
- Custom models: Cohere-run custom model training; self-serve fine-tuning retired September 15, 2025.
7. Mistral: open weights plus managed API
Mistral AI ships open-weight models such as Mistral Large 3 (Apache 2.0) alongside a managed API. Its newest flagship, Mistral Large 4, entered public preview on October 6, 2026, with a 1M-token context window.
Models in 2026:
- Mistral Large 3: $0.50/$1.50 per 1M via API, 256K context, Apache 2.0 weights.
- Mistral Large 4 (public preview): $1.36/$4.18 per 1M, 1M context, open weights.
- Codestral: code model on the managed API.
Strengths:
- Open weights: self-host anywhere; check each license before commercial use.
- Managed API on the frontier models: batch processing cuts the price by 50%.
8. Together AI: open-source models, serverless GPU
Together AI runs a serverless API for open models plus GPU clusters. It also sells dedicated inference and managed fine-tuning.
Models in 2026:
- DeepSeek V4.1 Flash, gpt-oss-120B, GLM-5.3: $0.30/$1.20, $0.15/$0.60, and $1.40/$4.40 per 1M.
Strengths:
- Rapid prototyping: serverless endpoints, OpenAI-compatible.
- Open repository: models across chat, code, vision, embeddings.
- GPU rentals: H100 on demand at $3.99 per GPU hour; reserved capacity for production.
9. Fireworks AI: FireAttention engine across 30+ regions
Fireworks AI provides serverless inference with its FireAttention CUDA kernel stack. Its model library lists more than 300 models, from DeepSeek and GLM to Qwen.
Models in 2026:
- DeepSeek V4.1 Flash, GLM-5.3: serverless, both with a 1M-token context window.
Strengths:
- Inference engine: up to 4x higher throughput than vLLM (Fireworks-reported).
- Multimodal: text, image, audio in a single API.
- SOC 2 Type II and HIPAA: also ISO 27001.
- Multi-cloud orchestration: GPUs across 30+ regions.
10. Hugging Face: Inference Providers and self-hosted Endpoints
Hugging Face ships Inference Providers (serverless API across partner providers, no markup) plus Inference Endpoints (managed dedicated infrastructure). You can pin a host by adding its name to the model ID, such as openai/gpt-oss-120b:groq.
Models: 3M plus models on the Hub. Includes Llama, Mistral, Qwen, Stable Diffusion variants, Whisper, BERT, etc.
Strengths:
- Inference Providers: route a single Hugging Face API key across Together, Fireworks, Replicate, Cerebras, Groq, and others.
- Self-hosting: full control; no vendor lock-in under Apache 2.0 or permissive licenses.
- SDK: Python (
huggingface_hub) and JavaScript (@huggingface/inference) clients. - Privacy: deploy in private VPC for sensitive data.
11. Groq: LPU-based fast inference
Groq serves open models on its own LPU hardware. It lists a speed in tokens per second next to each LLM it hosts.
Models: GPT OSS 120B and 20B, Llama 3.3 70B (Enterprise), Qwen 3.8 27B (preview).
Strengths:
- Speed: 500 tokens/s on GPT OSS 120B, 1,000 on GPT OSS 20B.
- OpenAI-compatible: drop-in for any OpenAI SDK call.
- Price: $0.15/$0.60 per 1M on GPT OSS 120B.
Best-fit use cases
- Startups and SMBs: Together AI or Mistral for cost; Hugging Face Inference Providers for flexibility; OpenAI’s GPT-6 Luna for low cost.
- Enterprises: Azure OpenAI (Microsoft shops), Amazon Bedrock (AWS shops), Anthropic direct (when long agentic sessions matter most), Google Cloud (Google shops).
- Multimodal: Gemini 4 Argon for native multimodality; OpenAI for tool-rich multimodal; Fireworks AI for image-heavy pipelines.
- Research and fine-tuning: Cohere for custom model training; Hugging Face for full self-host fine-tuning on 3M plus Hub models.
- Ultra-low latency: Groq LPU on GPT OSS models.
- Cost-floor bulk inference: Cohere Command R7B, GPT-6 Luna, or GPT OSS 20B on Groq.
Free LLM API tiers and trial credits
Free tiers suit prototyping, and each one caps usage:
- Google Gemini API: free tier on Gemini 3.8 Flash and 3.5 Flash-Lite, not on Gemini 4 Argon.
- Groq: a Free Plan with lower rate limits than the Developer plan.
- Cerebras Inference: a Free Trial tier; it lists about 3,000 tokens per second on gpt-oss-120b.
Emerging trends in LLM APIs (October 2026)
- Inference Providers became a category. Hugging Face, OpenRouter, and Future AGI’s Agent Command Center all put many providers behind one OpenAI-compatible API.
- Per-token cache pricing. Anthropic and OpenAI both offer 90% or larger input-token discounts on current flagships for prompts cached on their side. RAG and agentic workloads benefit most.
- MCP support became standard. The Model Context Protocol is now first-class on the OpenAI, Anthropic, and Gemini APIs.
How to choose between context, cost, speed, and stack fit
An LLM API decision is a four-axis trade-off: context capacity, output cost, time-to-first-token, and integration depth. Run an A/B test before you sign a contract. Prices here change every few months, so use the table to build a shortlist.
The 2026 pattern that works:
- Wrap providers behind a gateway. Future AGI’s Agent Command Center is one option; OpenRouter and LiteLLM are alternatives. The cost is one config file.
- Run shadow traffic. Agent Command Center’s shadow experiments mirror a sample of production requests to a second model in the background, so users never wait, and record its response, latency, and token count. Trace both paths with Future AGI’s traceAI (Apache 2.0, OpenTelemetry-native).
- Score with one eval set. Score outputs across exact match, groundedness, format validity, and your domain-specific metric using Future AGI’s evaluate.
- Pick on cost-per-quality, not cost-per-token. A 20% accuracy lift can outweigh a 100% per-token markup.
How Future AGI helps you evaluate and route LLM APIs
Future AGI is the eval and observability layer that pairs with any of the 11 providers above. Three pieces of the platform matter for API selection and operation:
- Agent Command Center: an OpenAI-compatible gateway in front of OpenAI, Anthropic, Gemini, Bedrock, Groq, Mistral, and self-hosted vLLM or Ollama. Swap providers by changing the model name; exact-match cache hits skip the provider call and cost zero. See the LLM gateways comparison.
- traceAI: Apache 2.0 OpenTelemetry instrumentation. Captures every span (LLM call, tool call, retrieval) with prompt, response, latency, and token count. The traceAI source is on GitHub.
- Evaluate: built-in evaluators such as Groundedness and Task Completion, plus custom LLM-as-judge and code evals, open source in agent-learning-kit.
from fi.evals import evaluate

context = ["Our policy accepts refunds within 30 days of purchase."]
answers = {
    "openai": "Refunds are accepted within 30 days of purchase.",
    "google": "Refunds are available for 60 days.",
}
for provider, output in answers.items():
    result = evaluate("groundedness", input="What is the refund window?", output=output, context=context)
    print(provider, result.score, result.reason)
This groundedness check runs locally with no API key after pip install agent-learning-kit; pip install 'agent-learning-kit[nli]' swaps its word-overlap fallback for an NLI model. The free tier includes 100K gateway requests and 100K cache hits a month, no credit card required.
Choose on your own traffic, then keep the option to switch
Flagship models turn over every few months, so today’s top rows will change. Shortlist from the table, put the finalists behind one gateway, and score a mirrored slice of real traffic with the same evals. When the next flagship ships, you change a model name instead of rewriting integration code.
Start free at futureagi.com/pricing.
Sources
- Together AI pricing
- Fireworks AI pricing
- Fireworks AI model library
- Fireworks AI inference engine
- Fireworks AI security and compliance
- Hugging Face pricing
- Groq rate limits
- Hugging Face Hub models
- Groq models and pricing
- OpenAI API pricing
- OpenAI API changelog
- OpenAI API deprecations
- Anthropic Claude API pricing
- Google Gemini API pricing
- Gemini 4 Argon model page
- Gemini API deprecations
- Azure OpenAI pricing
- Microsoft Foundry deployment types
- Amazon Bedrock pricing
- Amazon Bedrock models at a glance
- Cohere pricing
- Cohere Command A+ model page
- Cohere deprecations
- Mistral pricing
- Mistral Large 3 model page
- Mistral Large 4 model page
Frequently Asked Questions
Which LLM API provider is the best?
Are there any free LLM API providers?
What is the cheapest LLM API provider?
What is the fastest LLM API provider?
What is an LLM API gateway?
FutureAGI ACC, Helicone, OpenRouter, Portkey, LiteLLM, Cloudflare AI Gateway, Vercel AI Gateway as 2026 LLM gateways. Routing, caching, guardrails.
GPT-4.1 vs GPT-5 in 2026: SWE-bench scores, 1M token context, pricing, and the migration playbook. When to stay on 4.1 and when to switch.

Compare GPT-5, Claude Opus 4.7, Gemini 2.5 Pro, and Grok 4 on GPQA, SWE-bench, AIME, context, $/1M tokens, and latency. May 2026 leaderboard scores.