Best Books and Courses for Learning LLM Training in 2026: From Sutton to Karpathy
Ten LLM books and free courses tagged by level, from the free Jurafsky SLP3 textbook to Raschka and Huyen, with a beginner to advanced reading order for 2026.
Table of Contents
If you only read one of the LLM books on this list, read Jurafsky and Martin’s free Speech and Language Processing (the August 19, 2026 draft now opens with a full LLM volume). If you learn by coding, work through Sebastian Raschka’s Build a Large Language Model (From Scratch). If you ship LLM products, read Chip Huyen’s AI Engineering.
TL;DR: The Reading List in One Table
| Rank | Resource | Best for | Level | Format |
|---|---|---|---|---|
| 1 | Jurafsky and Martin, Speech and Language Processing (3rd ed. draft) | Single-volume coverage of modern NLP and LLMs | Intermediate | Free PDF, August 19, 2026 draft |
| 2 | Goodfellow, Bengio, Courville, Deep Learning | Math and neural-network foundations | Advanced (math) | Free HTML, deeplearningbook.org |
| 3 | Sutton and Barto, Reinforcement Learning (2nd ed.) | RL foundations for RLHF | Advanced | Free PDF, incompleteideas.net |
| 4 | Sebastian Raschka, Build a Large Language Model (From Scratch) | Hands-on GPT pretraining walkthrough | Beginner to Intermediate (coding) | Book + GitHub code |
| 5 | Chip Huyen, AI Engineering | LLM system design end to end | Intermediate | O’Reilly book |
| 6 | Alammar and Grootendorst, Hands-On Large Language Models | Visual, practitioner-focused coverage | Beginner | O’Reilly book |
| 7 | Tunstall, von Werra, Wolf, NLP with Transformers | Hugging Face implementation patterns | Intermediate | O’Reilly book |
| 8 | Karpathy, Zero to Hero series | LLM intuition from first principles | Beginner | Free YouTube |
| 9 | Stanford CS25, Transformers United | Frontier-lab guest lectures | Advanced | Free Zoom livestreams, past talks on YouTube |
| 10 | Hugging Face LLM Course | Practical end-to-end pipeline | Beginner | Free at huggingface.co/learn |
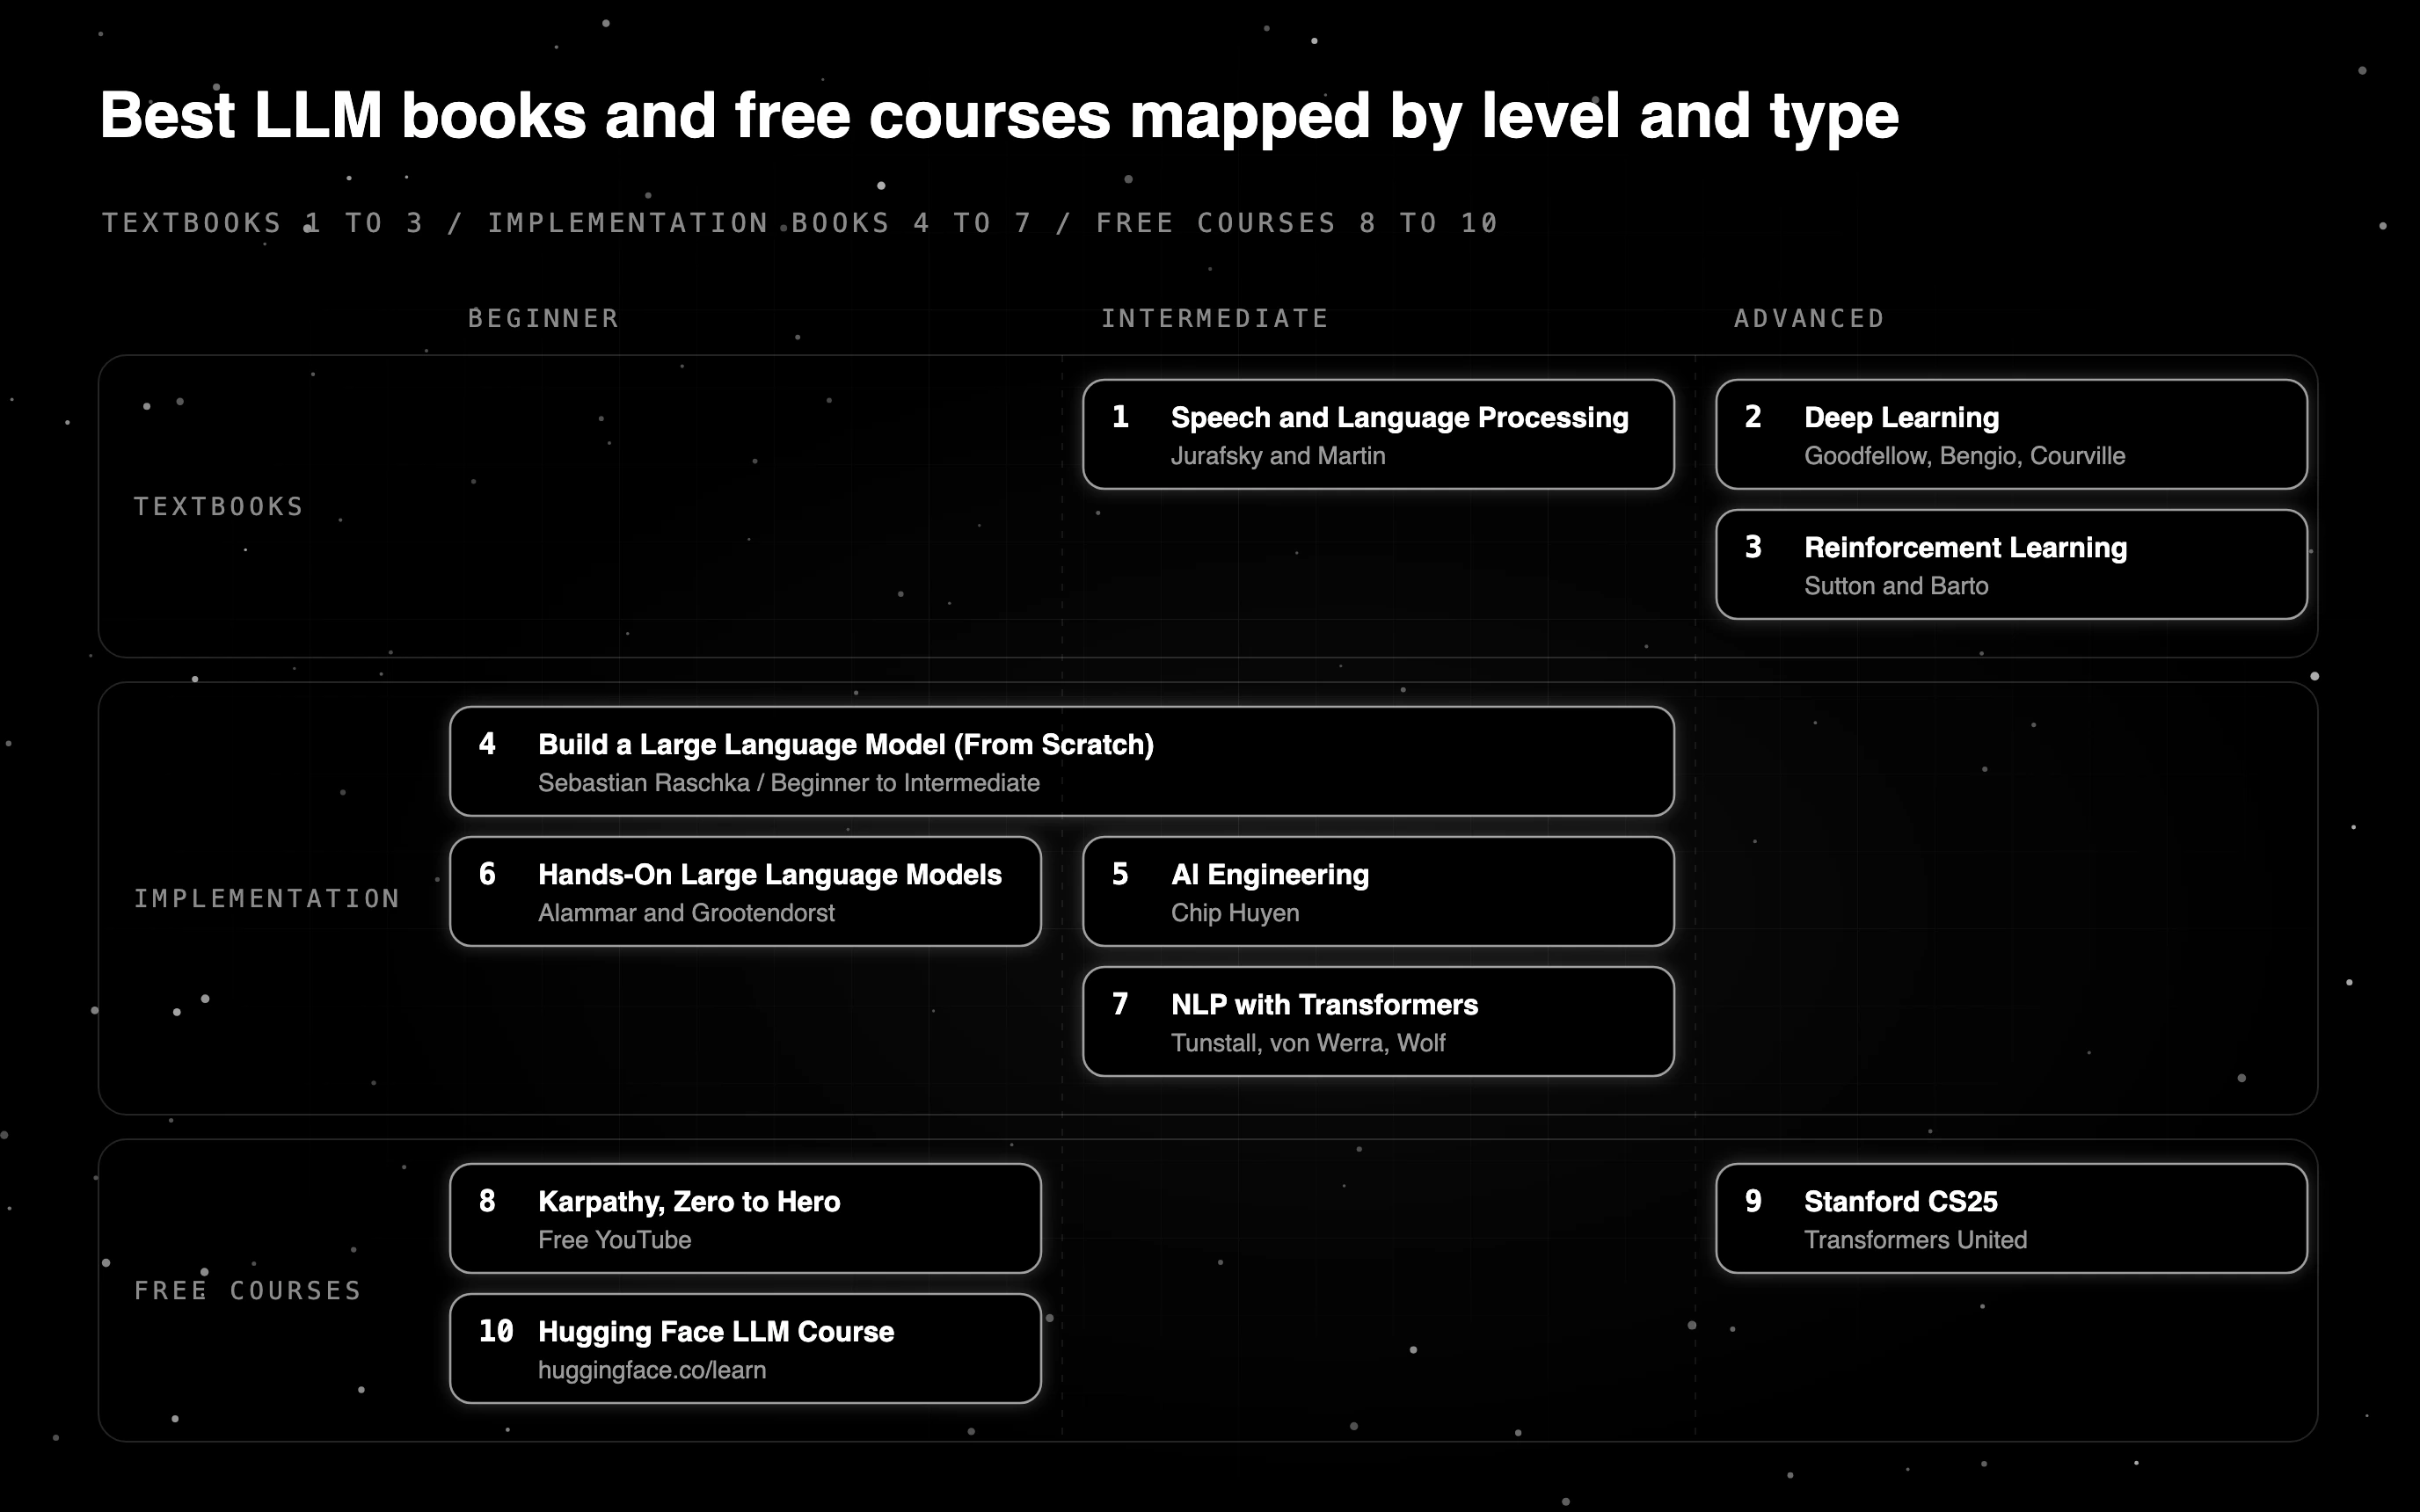
The textbooks (1, 2, 3) build the math and theory. The implementation books (4, 5, 6, 7) take you from theory to a working training pipeline. The free courses (8, 9, 10) give you a parallel video track and a frontier-lab perspective.
Which LLM Book Should You Read First?
- You are new to ML and want to learn LLMs from scratch. Start with Karpathy’s Zero to Hero. Then read Jurafsky and Martin’s transformer and pretraining chapters. Then work through Raschka’s Build an LLM From Scratch.
- You have ML background and want to skill up on LLMs. Read Jurafsky and Martin’s chapters on attention, transformers, instruction tuning, and RLHF. Then read Huyen’s AI Engineering for the system design layer. Watch the latest CS25 cohort for frontier topics.
- You are training your own model. Work through Raschka’s Build an LLM From Scratch. The Hugging Face LLM Course gives you the production pipeline. Read the Megatron-LM and DeepSpeed technical reports plus The Llama 3 Herd of Models (Meta, 2024, arXiv 2407.21783), the DeepSeek-V3 Technical Report (arXiv 2412.19437) and 2 OLMo 2 Furious (arXiv 2501.00656) for distributed training. If you are extending an existing model instead of starting from zero, see our guide to continued pretraining strategies.
- You are fine-tuning a pretrained model. Tunstall, von Werra, and Wolf’s NLP with Transformers plus the Hugging Face TRL documentation. Add Sutton and Barto chapter 13 (policy gradients) for RLHF, and the DPO paper for preference tuning. Our fine-tuning LLMs guide covers the LoRA, QLoRA, DPO, and GRPO tradeoffs in practice.
- You are deploying and evaluating a model. Huyen’s AI Engineering for the system design. Future AGI’s agent-learning-kit for evals and traceAI for OpenTelemetry tracing. For the methodology itself, see how to evaluate LLMs.
Best LLM Books for Beginners
If you write software but are new to machine learning, the order you read in matters more than how many books you buy. Start with Andrej Karpathy’s Neural Networks: Zero to Hero videos, or the general audience track on karpathy.ai if you do not code yet. Next, read Hands-On Large Language Models by Jay Alammar and Maarten Grootendorst, which explains tokenizers, transformers, semantic search and RAG through custom figures.
Then work through Sebastian Raschka’s Build a Large Language Model (From Scratch) with its companion code at github.com/rasbt/LLMs-from-scratch. Manning lists intermediate Python and some machine learning knowledge as prerequisites, and the GPT-2 class model you build runs on a modern laptop. Finish with chapter 1 of Jurafsky and Martin’s free Speech and Language Processing, which now carries much of the book’s LLM overview.
Free LLM Books You Can Read as a PDF
These books are free and legal because their authors or publishers post them. Download them from the official pages below, not from PDF mirror sites.
- Speech and Language Processing (Jurafsky and Martin): a single PDF of the August 19, 2026 release on Dan Jurafsky’s Stanford page (web.stanford.edu/~jurafsky/slp3).
- Reinforcement Learning: An Introduction (Sutton and Barto): the full second edition as a PDF on Richard Sutton’s site (incompleteideas.net/book/the-book-2nd.html).
- Deep Learning (Goodfellow, Bengio and Courville): free to read online at deeplearningbook.org, as HTML rather than a PDF.
- Foundations of Large Language Models (Tong Xiao and Jingbo Zhu): a free book on arXiv (2501.09223), with version 4 posted on October 8, 2026.
The 10 Best LLM Books and Courses in Detail
1. Speech and Language Processing, 3rd edition draft (Jurafsky and Martin)
A free, regularly updated textbook on modern NLP and LLMs. The third edition draft ships public releases (August 2025, January 2026, August 2026), and the August 19, 2026 release includes a new LLM introduction chapter, a combined transformers and pretraining chapter, a post-training chapter (instruction tuning, RLHF, DPO, RLVR) and a RAG chapter; the agents chapter is listed but not yet written. Free at web.stanford.edu/~jurafsky/slp3.
Start with chapter 1 (Introduction, which now carries much of the LLM overview), chapter 2 (Words and Tokens), chapter 7 (Transformers and Pretraining) and chapter 8 (Post-training, which covers instruction tuning, LoRA-style parameter-efficient fine-tuning, preference alignment with RLHF and DPO, and RL with verifiable rewards). Volume II adds chapter 11 (Information Retrieval and RAG). The chapters in between (n-gram models, logistic regression, embeddings, neural networks) are useful but skippable if you are short on time.
2. Deep Learning (Goodfellow, Bengio, Courville)
The math and neural-network foundations. Published in 2016, so chapters 10 through 20 are dated for 2026, but chapters 1 through 9 on linear algebra, probability, optimization, and feedforward networks are still a solid reference. Free HTML at deeplearningbook.org. Read it as a math reference, not cover to cover.
3. Reinforcement Learning: An Introduction, 2nd edition (Sutton and Barto, MIT Press 2018)
Sutton and Barto’s introduction to reinforcement learning. RLHF builds on the policy-gradient machinery this book develops; DPO solves the same preference problem with a classification loss instead of RL. Free at incompleteideas.net/book/the-book-2nd.html.
Chapter 13 (Policy Gradient Methods, including REINFORCE) is the one that maps to RLHF; chapter 17 (Frontiers) is useful background on designing reward signals but does not cover preference learning, so get that from the InstructGPT and DPO papers.
4. Build a Large Language Model (From Scratch) (Sebastian Raschka, Manning 2024)
A book-length walkthrough of pretraining a GPT-style model end to end. Raschka builds a working transformer in PyTorch from tokenizer to inference, with companion code at github.com/rasbt/LLMs-from-scratch.
This is the book to work through with a laptop open. The model is small enough to train on a single GPU but the architecture and training loop are the same machinery that powers production systems. Once your from-scratch model produces answers, score them the same way every run: Future AGI has custom evals you can run as a CI gate.
5. AI Engineering (Chip Huyen, O’Reilly 2024)
System design for LLM-powered products. Huyen covers evaluation, fine-tuning, RAG, agents, deployment, and the operational realities of running LLMs in production. Pair with her earlier Designing Machine Learning Systems for the broader ML systems frame. The two evaluation chapters (3 and 4) alone are worth the cover price.
6. Hands-On Large Language Models (Jay Alammar and Maarten Grootendorst, O’Reilly 2024)
Practitioner-focused, heavy on visualizations, covers prompting, fine-tuning, RAG, and evaluation in working code. Alammar’s earlier blog posts (The Illustrated Transformer, The Illustrated GPT-2) set the visual style that this book packages into an end-to-end resource.
7. Natural Language Processing with Transformers (Tunstall, von Werra, Wolf, O’Reilly 2022)
By three Hugging Face authors. A practical path from transformer architecture to production fine-tuning. The 2022 publication date means some of the model lineup is dated, but the patterns and the Hugging Face library APIs are still a useful reference. Pair with the current Hugging Face Transformers documentation and the TRL library docs for RLHF and DPO.
8. Andrej Karpathy’s Zero to Hero series
Free YouTube. A video course for building LLM intuition from first principles. Karpathy walks through neural networks, backpropagation, building micrograd, building makemore, then building a small GPT in PyTorch. The series is freely available at karpathy.ai with linked GitHub repos.
The Let’s build GPT video explains how transformers work in a single video. In October 2025 Karpathy released nanochat (github.com/karpathy/nanochat), a repo he describes as “The best ChatGPT that $100 can buy.” For non-coders, karpathy.ai also lists a general audience track next to the technical Zero to Hero track.
9. Stanford CS25: Transformers United
Stanford seminar series, now in its sixth run (V6), with talks from researchers at Google DeepMind, Anthropic, Hugging Face, Mistral AI, Thinking Machines and universities; anyone can join the Zoom livestreams, and past lectures have drawn millions of views on YouTube. It is a running source for frontier topics that do not yet have textbook coverage, such as scaling laws, mixture of experts, multimodal training and reasoning models. The course page is at web.stanford.edu/class/cs25.
10. Hugging Face LLM Course
End-to-end practical pipeline coverage. The Hugging Face LLM Course (which absorbed the old NLP Course) runs from transformer basics, Datasets and Tokenizers (chapters 1 to 9) into advanced chapters on curating datasets (10), fine-tuning LLMs with SFT and LoRA (11) and building reasoning models with GRPO in TRL (12). Hugging Face also runs a separate Agents Course and the smol course on post-training. Free at huggingface.co/learn.
New LLM Books Worth Adding in 2026
These three books sit outside the ranked ten and fill gaps the main list leaves open: training reasoning models, a free theory text, and a short overview.
- Build a Reasoning Model (From Scratch), Sebastian Raschka (Manning, release date June 9, 2026). It starts from a pretrained LLM, adds evaluation with math verifiers, improves reasoning at inference time with chain of thought, self-consistency and self-refinement, then moves to reinforcement learning with verifiable rewards, GRPO and distillation into smaller models. Read it after pick 4. For the method behind it, see how GRPO trains reasoning models.
- Foundations of Large Language Models, Tong Xiao and Jingbo Zhu: a free book on arXiv whose version 4 was posted in October 2026.
- The Hundred-Page Language Models Book, Andriy Burkov (2025, listed on Leanpub).
What to Read Alongside the Books: The Papers That Matter
Books cannot keep up with frontier research, so a working LLM engineer also reads papers. The minimum reading list for 2026 is:
- Attention Is All You Need (Vaswani et al. 2017): the transformer paper.
- GPT-3 (Brown et al. 2020): in-context learning and scaling.
- InstructGPT (Ouyang et al. 2022): the original RLHF recipe.
- DPO (Rafailov et al. 2023): direct preference optimization, the simpler alternative to PPO-RLHF.
- LIMA (Zhou et al. 2023): less is more for alignment.
- The Llama 3 Herd of Models (Meta, 2024), the DeepSeek-V3 Technical Report and 2 OLMo 2 Furious (fully open data and training recipe): open-weights training at scale.
- DeepSeek-R1 (DeepSeek-AI, 2025): reasoning through reinforcement learning (arXiv 2501.12948).
- Anthropic and OpenAI model cards: public details on frontier models.
Bookmark arXiv cs.CL and Hugging Face Trending Papers, which replaced Papers With Code in 2025, and skim them weekly.
Where Future AGI Fits In: Evaluation and Observability for What You Train
Once you have read the books, watched the courses, and trained or fine-tuned a model, the gap to production is evaluation and observability (see our guide to evaluating a fine-tuned LLM). That is where Future AGI sits in the stack.
- agent-learning-kit (Apache-2.0, github.com/future-agi/agent-learning-kit,
pip install agent-learning-kit): the local-first SDK and CLI for testing, simulating, red-teaming and optimizing AI agents; its evals engine covers heuristic, model-based and LLM-as-a-judge scoring. Callevaluate()with a metric name such as faithfulness plus your output and context, and read back a score and a reason.
- traceAI (Apache 2.0, github.com/future-agi/traceAI): OTEL-compatible instrumentation for OpenAI, Anthropic, Vertex, Bedrock, LangChain, LangGraph, LlamaIndex, and the OpenAI Agents SDK.
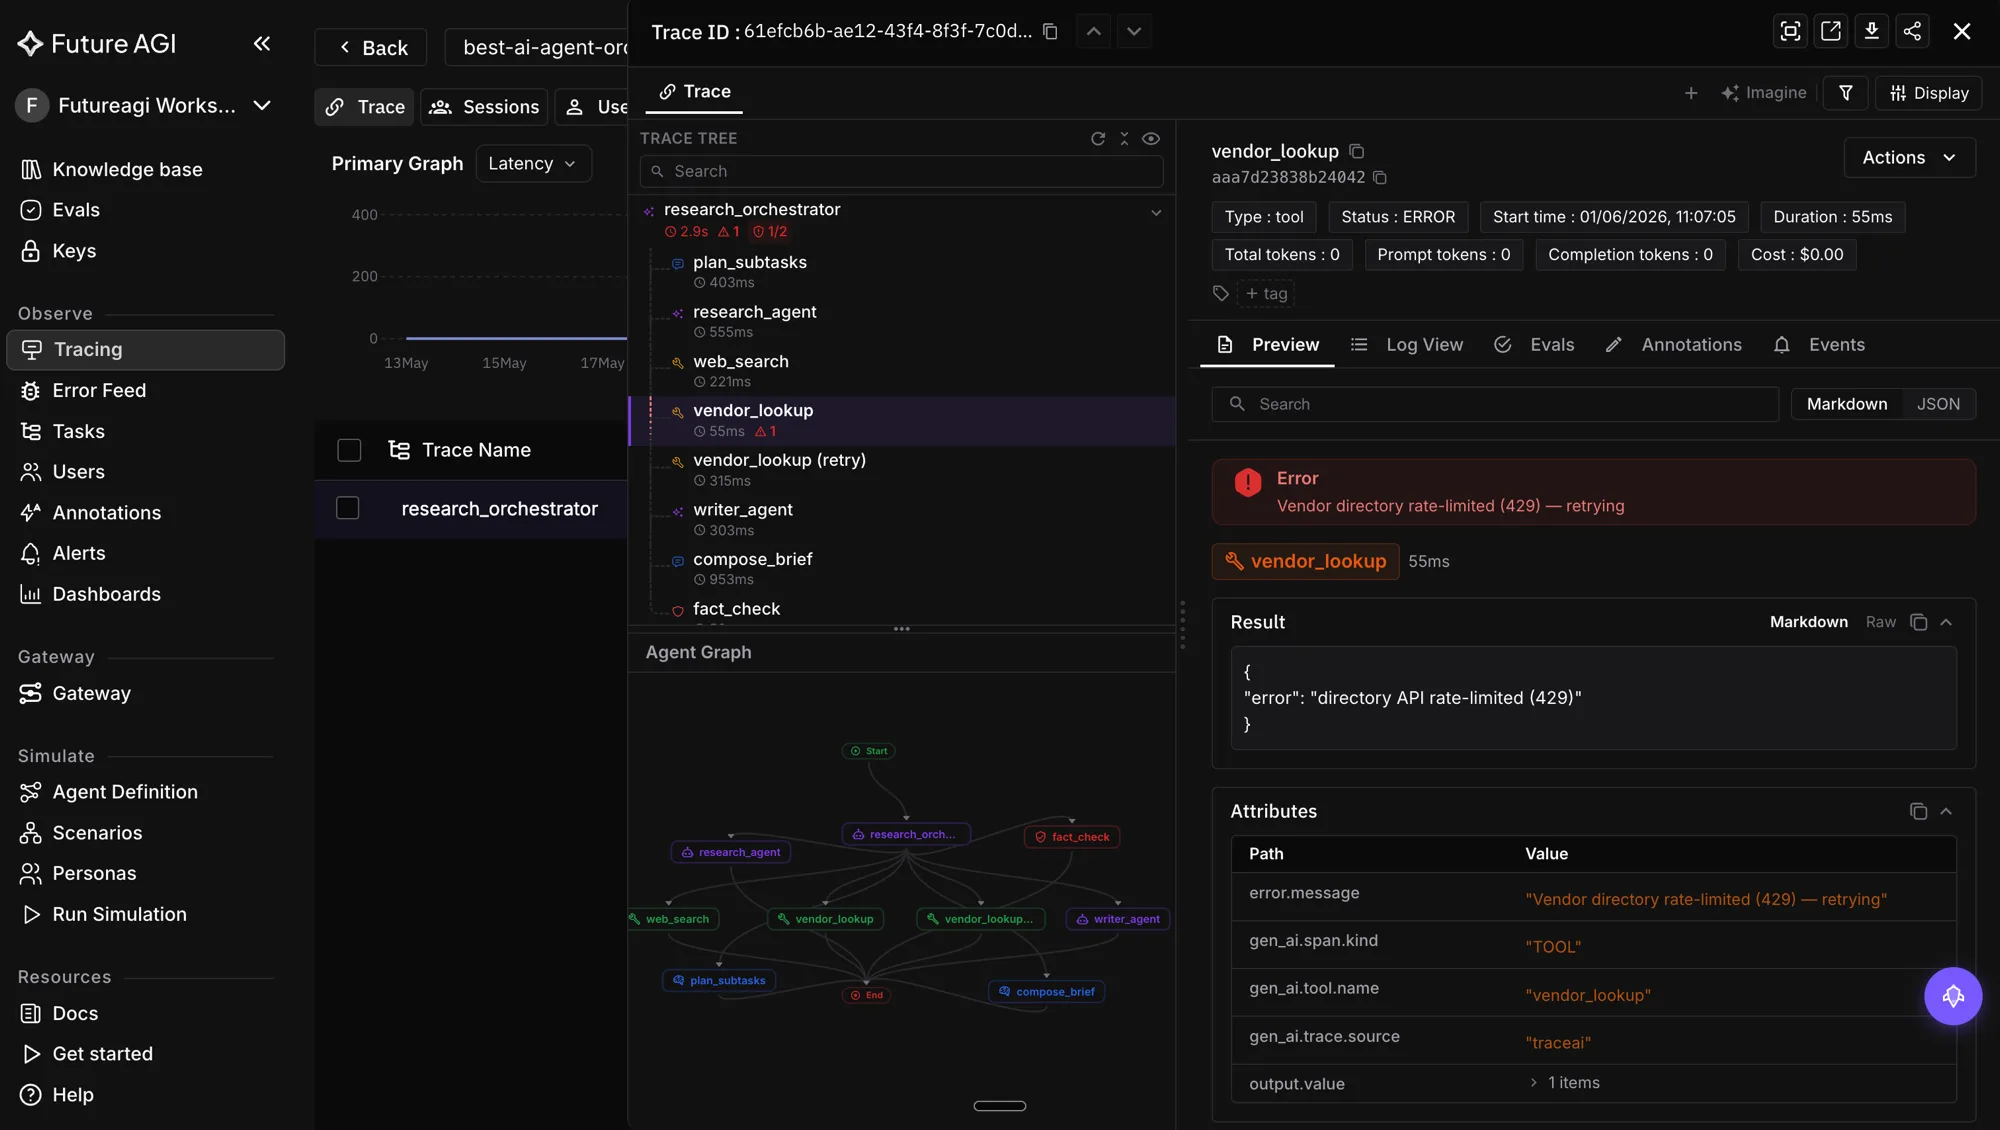
- Agent Command Center: BYOK gateway for routing, budgets, caching, and pre-call guardrails. Useful once your trained or fine-tuned model is in front of real users.
-
Simulation: run your agent through persona and scenario based conversations before users see it, as hosted simulation on Future AGI Cloud with an Apache-2.0 SDK surface in agent-learning-kit (simulation docs).
-
Cloud evaluators:
turing_flash(about 1 to 2 seconds),turing_small(about 2 to 3 seconds), andturing_large(about 3 to 5 seconds), documented at docs.futureagi.com/docs/sdk/evals/cloud-evals.
None of this replaces the books. It is the layer you wire in once you have the model.
From Reading List to a Model You Can Trust
You came here to understand how large language models work and to train one yourself. Pick one book at your level from the table, build the small model it walks you through, then put evals and tracing on it before anyone else uses it. Start with Future AGI custom evals and score every training run against the same test set.
Frequently Asked Questions
What are the best books for learning LLMs?
What are the best LLM books for beginners?
Are there free LLM books available as a PDF?
What is the best way to learn LLMs?
Is there a book on how to train your own LLM?
What is Sebastian Raschka's LLM book?
What is Jay Alammar's LLM book?
Introducing ai-evaluation, Future AGI's Apache 2.0 Python and TypeScript library for LLM evaluation. 50+ metrics, AutoEval, streaming, multimodal.
Compare six agent evaluation frameworks for 2026 (LangSmith, Future AGI, Braintrust, DeepEval, Phoenix, OpenAI Evals) on trajectory scoring, license and price.

FutureAGI, DeepEval, Langfuse, Phoenix, Braintrust, LangSmith, and Galileo as the 2026 LLM evaluation shortlist. Pricing, OSS license, and production gaps.