What Is LlamaIndex? A 2026 Guide to Workflows, Deployment, and Evaluation
What is LlamaIndex? An open-source framework for LLM apps over your own documents. See its uses, how it compares to LangChain, and how to deploy and trace it.
Table of Contents
What Is LlamaIndex?
LlamaIndex is an open-source Python framework for building LLM applications over your own data. It handles the work between a raw document and a grounded answer: loading data from more than a hundred sources, chunking and embedding it, retrieving the relevant parts at query time, and orchestrating the multi-step logic around that retrieval. It is provider-agnostic, so the same application can run on OpenAI, Anthropic, Gemini, or a self-hosted open-weight model.
The name is a leftover from what it used to be. LlamaIndex started as a library for indexing documents so an LLM could answer questions about them, and for a long time “LlamaIndex equals RAG” was a fair summary. The framework is now organised around event-driven workflows and ships its own server and deployment CLI, which puts it in the same category as LangGraph.
The company has shifted too. Its GitHub README says the primary focus is now LlamaParse, a commercial platform for agentic OCR, parsing, and extraction, along with LiteParse for free local parsing. The open-source framework remains available as an open toolkit, and new llama-index releases keep shipping on PyPI.
LlamaIndex vs LangChain in Short
LlamaIndex and LangChain have converged, and anyone telling you one is categorically better is selling something. Both are open-source Python orchestration frameworks, both are provider-agnostic, both plug into the major vector databases, and both now model applications as composable steps rather than monolithic chains. The differences that remain are about emphasis and execution model:
- LlamaIndex leads on document ingestion and retrieval quality. LlamaParse handles messy enterprise PDFs, and the framework’s integration packages cover loaders, LLMs, embedding models, and vector stores. Its Workflows model execution as steps that consume and emit typed events, with the runtime routing each event to whichever step subscribes to it.
- LangChain / LangGraph leads on explicit state machines. LangGraph models execution as a graph of nodes and edges you define, which is a better fit when you need checkpointing, replay, and human-in-the-loop pauses at specific points.
Pick LlamaIndex when documents are the hard part. Pick LangGraph when control flow is the hard part. For most teams either will work, and the decision matters less than having an evaluation layer that tells you whether the thing you built is any good.
What you get in the box
- Integrations. Over 300 integration packages for data loaders (PDFs, web pages, Notion, S3, SQL, Slack), LLMs, embedding models, and vector stores. The old LlamaHub site now points to the integrations page on developers.llamaindex.ai.
- Workflows. Event-driven step composition, the recommended way to build anything non-trivial.
- Query engines and retrievers. Still the right primitive for simple Q&A over a corpus.
- Agents. ReAct, function-calling, and tool-use patterns built on Workflows.
- llama-agents. The production server, CLI, and client for running workflows as services.
- LlamaParse. LlamaIndex’s hosted platform for agentic OCR, parsing, extraction, splitting, classification, and indexing. It also hosts cloud deployments of LlamaAgents, and some docs pages still call the platform by its older name, LlamaCloud.
- LiteParse. Open-source (Apache-2.0) parser that runs locally on PDFs, Office docs, and images, with no cloud calls and no LLM tokens.
Is LlamaIndex free and open source?
Yes, for the code you run yourself. The framework is MIT-licensed, and so are the llama-agents packages and the llamactl CLI. LiteParse, the local parser, is Apache-2.0. All of them install from PyPI and run on your own machines with no license fee.
The paid part is LlamaParse, which the LlamaIndex pricing page describes as its commercial platform and says is not open source. It bills in credits, and 1,000 credits cost $1.25. As of October 2026, the Free plan includes 10,000 credits a month and the Starter plan costs $50 a month with 40,000 credits.
LlamaIndex in 2026 at a Glance
| Area | Early 2024 state | 2026 state | Why it matters |
|---|---|---|---|
| Composition model | Query engines, chains, agents | Workflows API (typed events + async steps) | Replaces monolithic chains with pub-sub steps |
| Production runtime | Hand-rolled FastAPI services | llama-agents server + llamactl CLI (llama-deploy is deprecated) | REST API with streaming, persistence, and human-in-the-loop |
| Observability | DIY logs | traceAI-llamaindex (OpenTelemetry) | Every step is a span, vendor-portable |
| Evaluation | Offline notebook scoring | Span-attached fi.evals.evaluate() | Hallucination and groundedness scores live next to traces |
A Minimal LlamaIndex Workflow Example
Here is a two-step Workflow that retrieves context for a question and then asks the LLM to answer it. The retrieve step loads and searches the corpus, and the generate step sends the retrieved context to the LLM. Save as simple_rag.py.
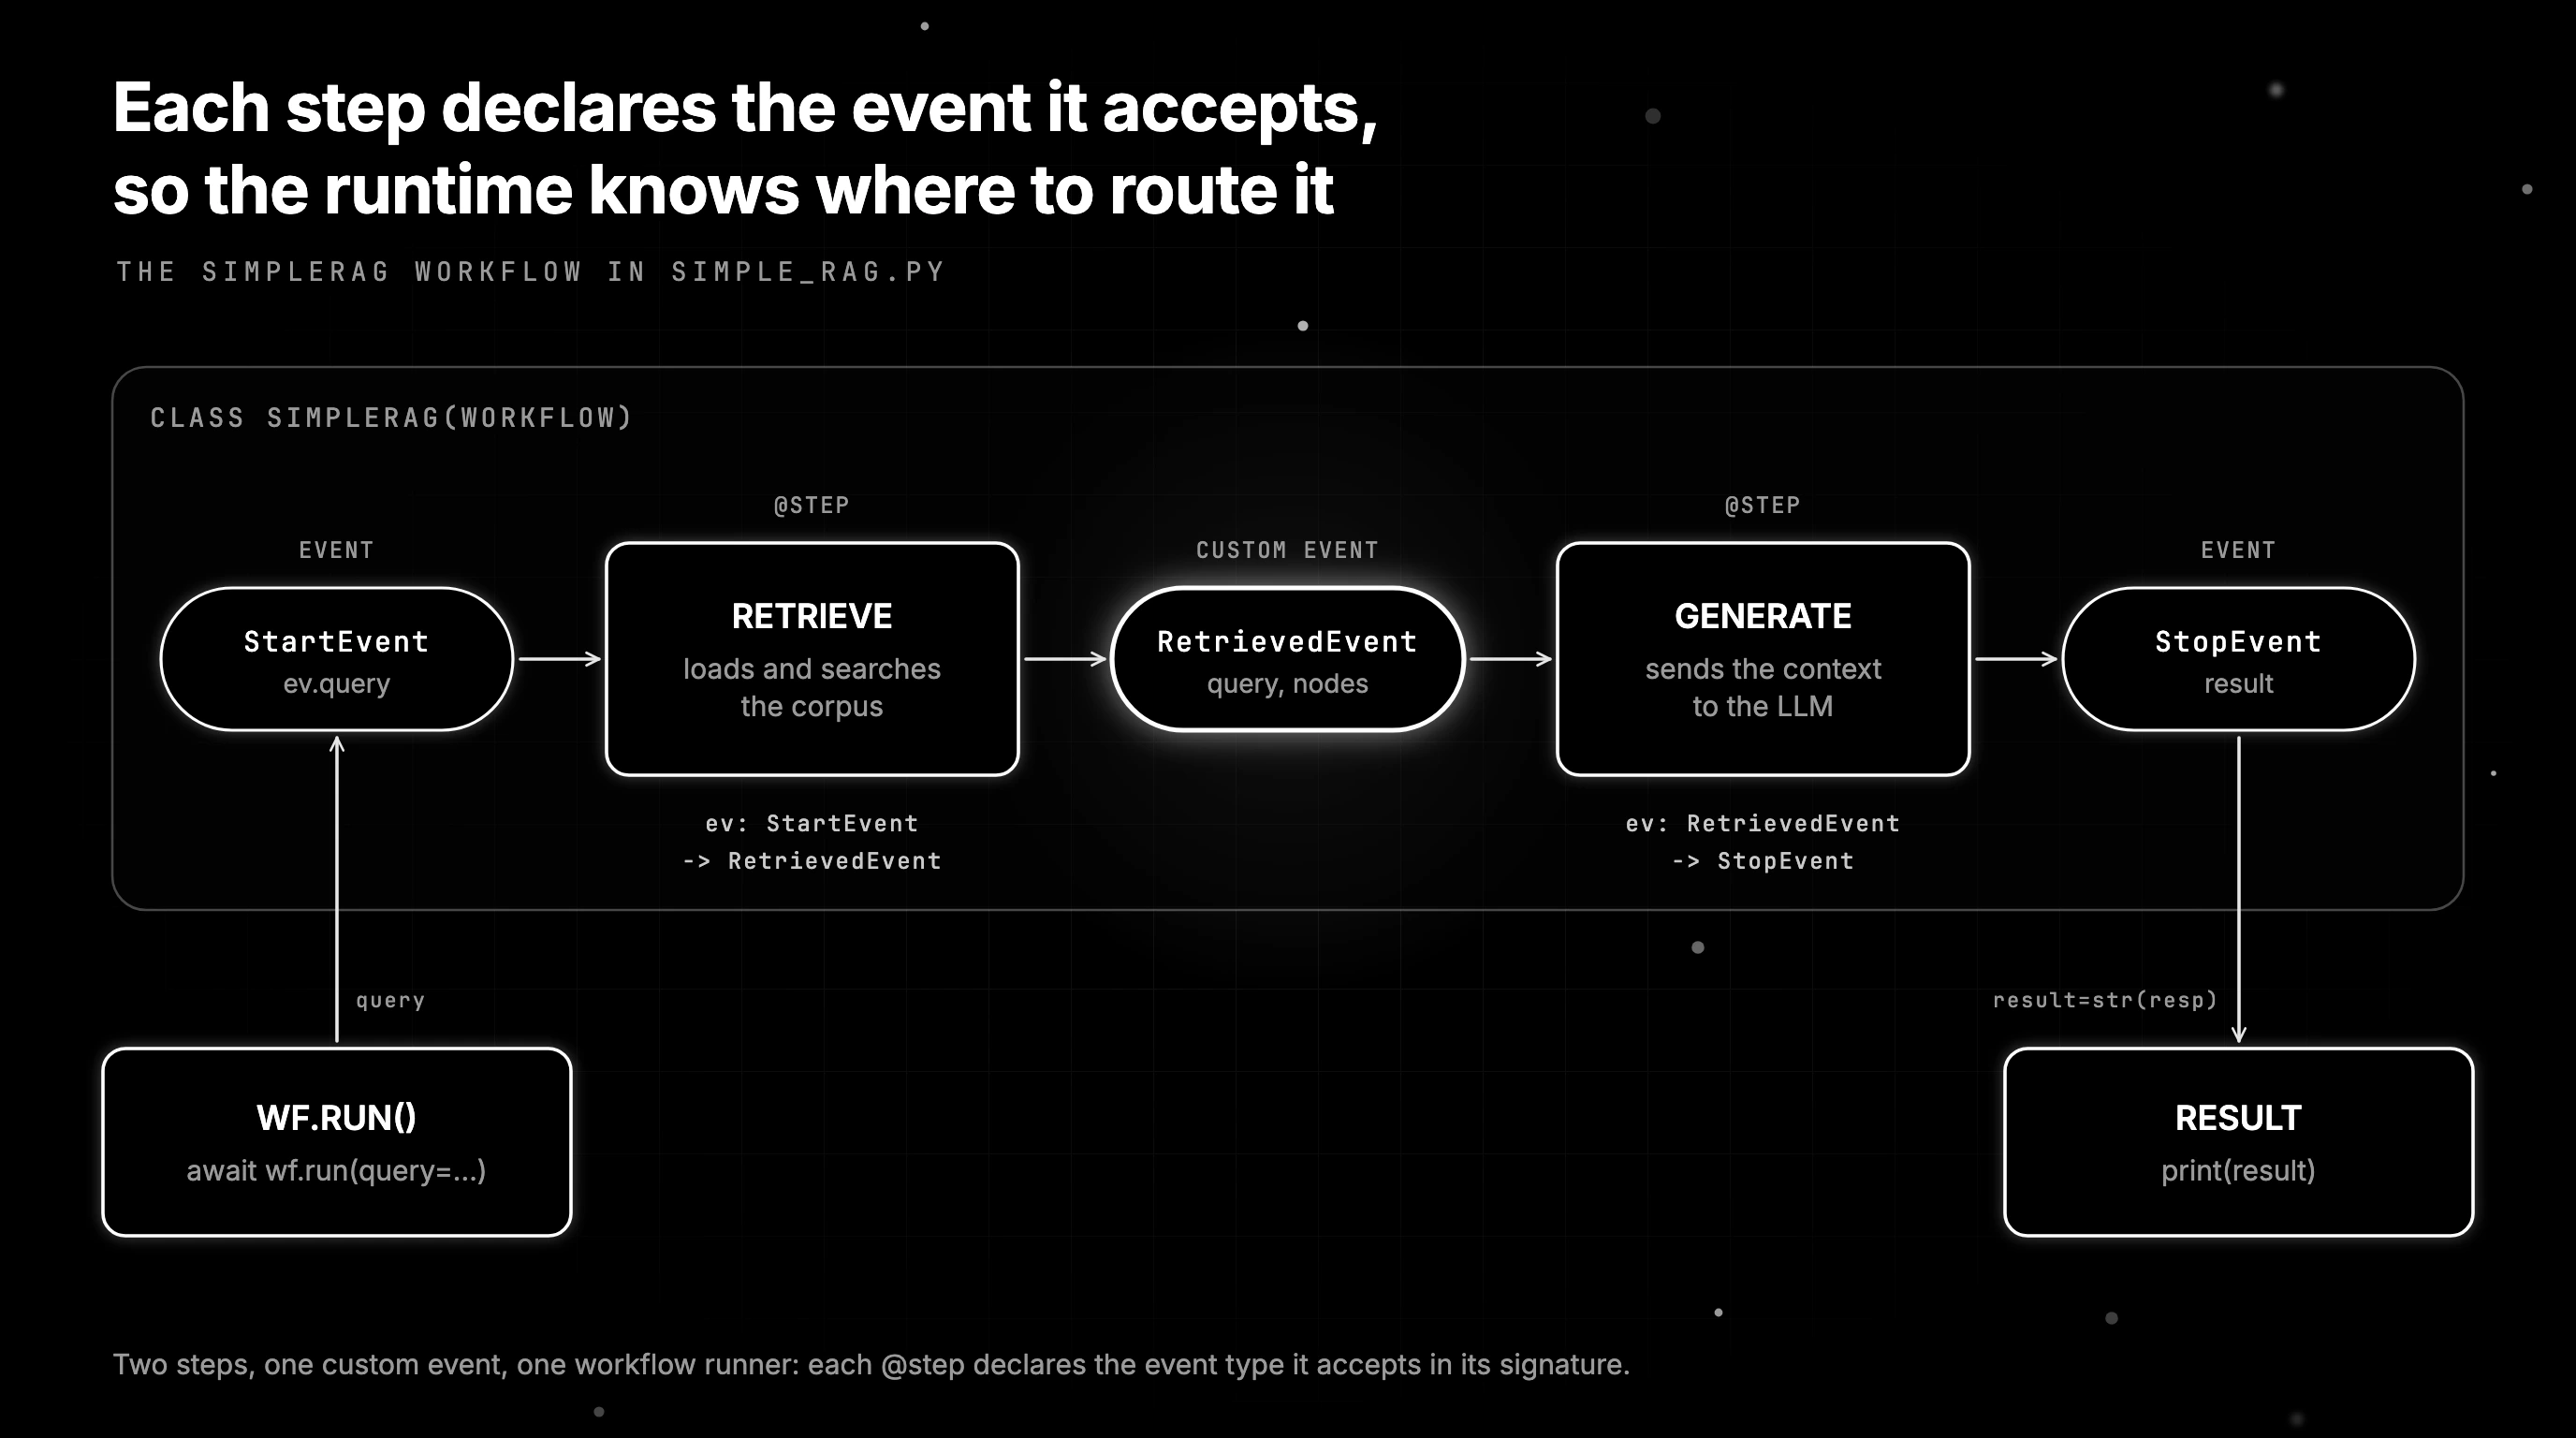
One note on imports before you copy this. There are two paths to the same Workflow primitives: the in-core llama_index.core.workflow, used below, and the standalone workflows package that ships as llama-index-workflows and is what the llama-agents server expects. They are the same model; pick one per project rather than mixing them, and prefer the standalone package if you intend to deploy.
from llama_index.core.workflow import (
    Workflow, StartEvent, StopEvent, Event, step,
)
from llama_index.core import VectorStoreIndex, SimpleDirectoryReader
from llama_index.core.schema import NodeWithScore
from llama_index.llms.openai import OpenAI

class RetrievedEvent(Event):
    query: str
    nodes: list[NodeWithScore]

class SimpleRAG(Workflow):
    @step
    async def retrieve(self, ev: StartEvent) -> RetrievedEvent:
        # Build the index once at startup in real code; rebuilding it inside the
        # step re-reads and re-embeds the corpus on every run.
        documents = SimpleDirectoryReader("./data").load_data()
        index = VectorStoreIndex.from_documents(documents)
        retriever = index.as_retriever(similarity_top_k=4)
        nodes = retriever.retrieve(ev.query)
        return RetrievedEvent(query=ev.query, nodes=nodes)

    @step
    async def generate(self, ev: RetrievedEvent) -> StopEvent:
        # Use an ID your installed llama-index-llms-openai lists.
        llm = OpenAI(model="gpt-5.6-sol")
        context = "\n\n".join([n.get_content() for n in ev.nodes])
        prompt = f"Use the context to answer.\n\nContext:\n{context}\n\nQuestion: {ev.query}"
        resp = await llm.acomplete(prompt)
        return StopEvent(result=str(resp))

async def main():
    wf = SimpleRAG(timeout=60)
    result = await wf.run(query="What does the document say about X?")
    print(result)

if __name__ == "__main__":
    import asyncio
    asyncio.run(main())
That is the whole pattern in one file. Two steps, one custom event, one workflow runner. Add tool-calling, conditional routing, or parallel branches by adding more steps and event types. Each @step declares the event type it accepts in its signature, which is how the runtime knows where to route each event.
Adding Observability and Evaluation
Production use needs two additions: tracing, so you can see every retrieval and LLM call, and span-attached evaluation, so each output you score carries its result on the span that produced it. Install both with pip install traceAI-llamaindex agent-learning-kit, then register a tracer and instrument LlamaIndex before you build the workflow.
from fi_instrumentation import register
from fi_instrumentation.fi_types import ProjectType
from traceai_llamaindex import LlamaIndexInstrumentor

tracer_provider = register(project_name="rag_demo", project_type=ProjectType.OBSERVE)
LlamaIndexInstrumentor().instrument(tracer_provider=tracer_provider)
After this, every workflow run produces a trace with one root span per run() call and child spans for every retrieval and LLM call inside. Open the Future AGI Observe UI and the trace tree appears with latency, model, token counts, and tool arguments on every span.
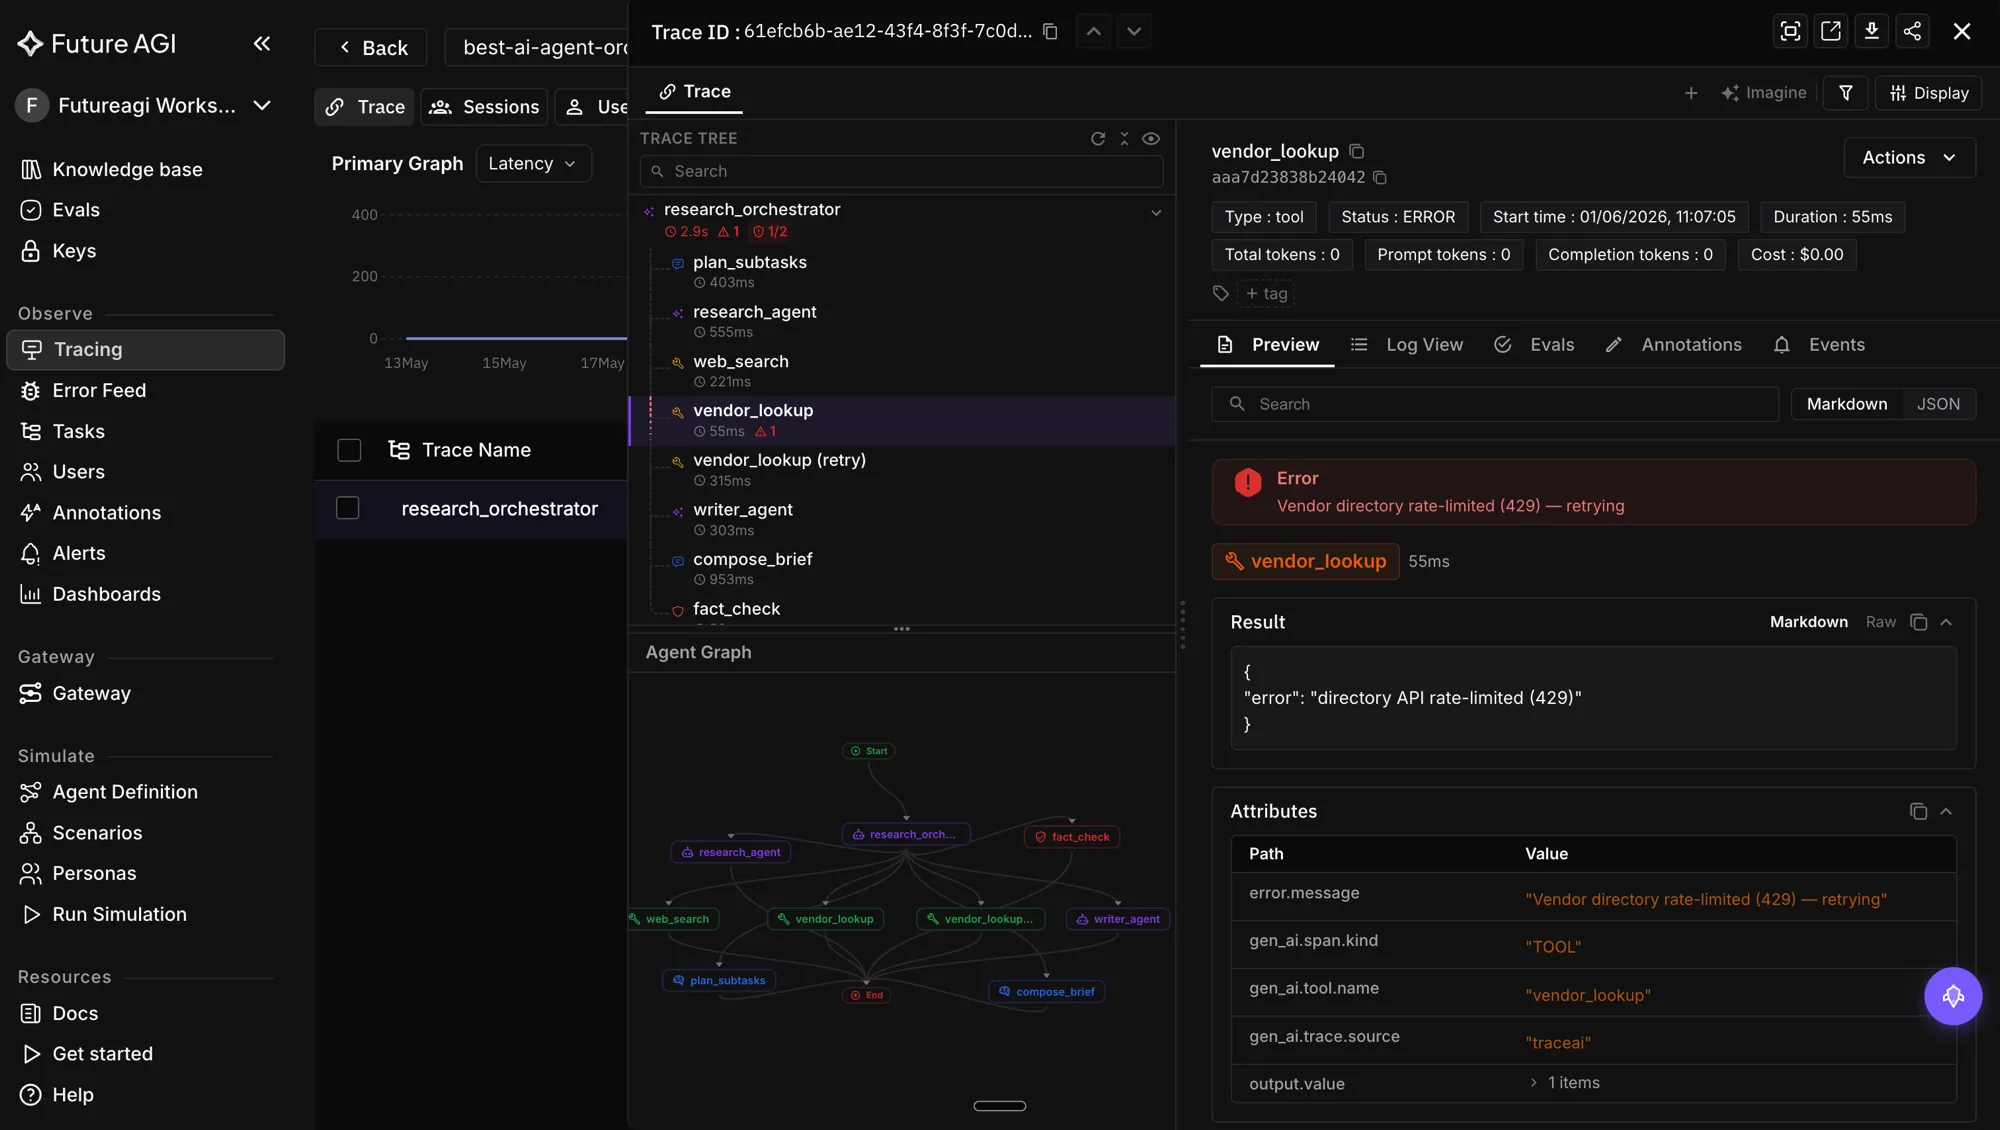
The LlamaIndex PDF RAG cookbook runs this same setup on a full PDF chatbot and scores each trace for task completion, hallucination, and context relevance. To attach scores to your own spans, call enable_auto_enrichment() once at startup and evaluate() inside the active span:
from fi.evals import evaluate
from fi.evals.otel import enable_auto_enrichment

enable_auto_enrichment()

# Inside the generate step, after resp is computed:
context = "\n\n".join([n.get_content() for n in ev.nodes])
r = evaluate("groundedness", output=str(resp), context=context, model="turing_flash")
# Score, reason, latency_ms are now span attributes on the active generate span
That is the full integration: one register(), one instrumentor call, one enable_auto_enrichment(), and one evaluate() per scoring step. The groundedness eval returns a pass or fail result with a plain-language reason, so every failed span tells you why it failed.
Deploying with llama-agents
If you are on llama-deploy, migrate
The llama_deploy repository now carries an unambiguous notice: “This project is deprecated. To serve workflows, use llama-agents instead.” Earlier versions of this article recommended llama-deploy and its Redis control-plane setup, so if you built on that advice, this section is your migration target. The replacement is a set of smaller packages rather than one runtime:
| Package | What it does |
|---|---|
llama-index-workflows | The core workflow library. Your Workflow and @step code lives here |
llama-agents-server | Wraps a workflow as a REST API with streaming, persistence, and human-in-the-loop support |
llama-agents-client | Async client for calling a deployed workflow |
llamactl | CLI to scaffold an app, run it locally, and manage cloud deployments |
The workflow code itself is unchanged, which is the good news about this migration. Only the imports change, from llama_index.core.workflow to the standalone workflows package, which llama-index-core already installs as a dependency. The same pattern runs on the standalone package:
from workflows import Workflow, step
from workflows.events import StartEvent, StopEvent

class HelloWorkflow(Workflow):
    @step
    async def greet(self, ev: StartEvent) -> StopEvent:
        return StopEvent(result=f"Hello, {ev.name}")
Serving it
llamactl uses uv to manage Python environments and needs git, because cloud deployments are built from a Git repository. Node.js only matters when your template includes a frontend. Install the CLI globally with uv, then scaffold, run, and deploy from the terminal:
uv tool install -U llamactl

llamactl init                  # pick a template and scaffold the app
llamactl serve                 # run the development server locally
llamactl deployments create    # build and deploy from a Git repository
llamactl deployments logs NAME --follow   # stream logs from a deployment
You can run the result locally, self-host it, or deploy it to LlamaCloud, though note that LlamaIndex currently labels cloud deployments a beta preview rather than generally available. The observability and evaluation setup from the previous section continues to work unchanged, because instrumentation attaches to the workflow steps rather than to whatever is serving them.
One more deprecation worth knowing if you touch the managed services: the llama_cloud_services packages were deprecated and their maintenance window ended on 1 May 2026. If you are still importing them, you are on unmaintained code. Python users should move to llama-cloud>=1.0 and TypeScript users to @llamaindex/llama-cloud.
Where LlamaIndex Fits Versus Alternatives
| Use case | LlamaIndex | LangChain / LangGraph | Custom code |
|---|---|---|---|
| Document-heavy RAG over enterprise PDFs | First choice (LlamaParse + Workflows) | Workable | High effort |
| Multi-agent state machines with checkpoints | Workable (Workflows) | First choice (LangGraph) | High effort |
| Provider-agnostic LLM switching | First choice | First choice | High effort |
| Single-vendor Q&A over a few files | Overkill | Overkill | First choice (vendor SDK) |
| Production server with distributed steps | First choice (llama-agents) | Workable (custom) | Possible (FastAPI) |
In practice, LlamaIndex and LangChain / LangGraph have converged on similar capability surfaces. Pick LlamaIndex when document parsing, retrieval quality, and pub-sub step composition are central; pick LangGraph when explicit state-machine semantics and human-in-the-loop pauses are central; pick a custom stack when you only need one vendor and one workflow shape.
Common Pitfalls in 2026
- Mixing the old query-engine API with new Workflows in the same app. Both work, but they have different state and event models. Pick one per app and stick with it.
- Forgetting that Workflows are async-native. Steps are normally written as
async defcoroutines, andrun()must be awaited from an async entry point. Calling an async step withoutawaitwill not raise; it silently returns a coroutine object you forgot to await. - Still building on llama-deploy. It is deprecated, and any tutorial that has you standing up a Redis control plane to serve a workflow is describing the old world. Move to
llama-agents-serverandllamactl. - Instrumenting after the workflow is built. Call
LlamaIndexInstrumentor().instrument()before instantiating the workflow class, or the span tree will be incomplete. - Scoring outputs in a different process from where they ran. If you call
evaluate()in a downstream service, you lose the span-attachment benefit. Score inside the workflow step that produced the output. For LlamaIndex-specific scoring rubrics, see evaluating LlamaIndex RAG applications.
How Future AGI Pairs with LlamaIndex
LlamaIndex is an orchestration framework. Future AGI is the evaluation and observability layer that sits on top, the same way you would pair Datadog with a Flask app. One instrumentor, LlamaIndexInstrumentor, traces both classic LlamaIndex code and LlamaIndex Workflows. Once you have a Workflow running:
-
traceAI auto-instruments every step, retriever, and LLM call into OpenTelemetry spans (vendor-portable, OTel GenAI semantic conventions compatible).
-
agent-learning-kit (
pip install agent-learning-kit) scores any output throughfi.evals.evaluate("groundedness", ...)orevaluate("detect_hallucination", ...), plus custom evals you define, with auto-enrichment attaching scores to the active span. -
Simulation runs the workflow through scenario and persona conversations, in chat or voice, and scores each one with the evals you attach before real users reach it.
-
Optimization rewrites a weak prompt, scores each variant against your evals, and keeps the winner, with six optimizer algorithms to choose from, including GEPA and ProTeGi.
You keep LlamaIndex for retrieval, parsing, orchestration, and deployment. You add Future AGI for span-attached evaluation, persona scenarios, and prompt optimization. No vendor lock-in: agent-learning-kit is Apache-2.0 and traceAI is Apache-2.0, and traceAI sends spans to any OpenTelemetry-compatible backend you already run.
From Raw Documents to Answers You Can Trust
LlamaIndex covers the path from a raw document to a grounded answer: parse it, index it, retrieve the right chunks, and run the steps around them as a Workflow you can serve with llama-agents. That path is only finished when you can show each answer is supported by what was retrieved, on every production run.
Instrument the workflow with traceAI, score each generate step for groundedness and context relevance, and read those scores next to latency and token counts in one trace view, with alerts when quality drops. For the retrieval-side metrics, see our guide to RAG evaluation metrics.
Score your LlamaIndex workflow with Future AGI | traceAI on GitHub
Sources
Frequently Asked Questions
What is LlamaIndex used for?
Is LlamaIndex better than LangChain?
Is LlamaIndex free to use?
Is LlamaIndex a Python library?
Who is behind LlamaIndex?
How do LlamaIndex Workflows differ from LangGraph?
Agentic RAG in 2026: tool-using agents over vector DBs, query rewriting, multi-hop retrieval, and how to trace and evaluate every retrieve span with FAGI.

RAG evaluation metrics explained: faithfulness, context precision, context recall, groundedness and answer relevance, and which pipeline stage each one tests.
FutureAGI, DeepEval, Langfuse, Phoenix, Braintrust, LangSmith, and Galileo as the 2026 LLM evaluation shortlist. Pricing, OSS license, and production gaps.